Counting Primes
Posted by John Baez

Since the probability that a number is prime is roughly , the number of primes is close to
Indeed, if is the number of primes , the recently proved quasi-Riemann hypothesis implies
for some constants and . If the Riemann hypothesis is true, any will do.
But here’s what I want to talk about today. For all where can actually be counted, . But in 1914, Littlewood shocked the world by sketching a proof that changes sign infinitely often!
I want to explain how that eventually led to a graph that shows an explicit region where exceeds .
Littlewood’s proof didn’t say when first exceeds . He gave his student Stanley Skewes the task of figuring that out.
In 1933, Skewes gave an enormous upper bound for where this first happens, assuming the Riemann hypothesis:
This is called Skewes’ number. Hardy called it “the largest number which has ever served any definite purpose in mathematics”. In 1955, still working on his advisor’s assignment, Skewes gave an even larger upper bound not assuming the Riemann hypothesis:
This disgustingly large quantity is called the second Skewes number.
I first read about Skewes’ number as a kid in The Guinness Book of World Records. It always intrigued me, but I never tried to understand the math involved, because I figured it would be too hard. This article is my attempt to finally make some progress.
In 1966, Lehman found a trick that lowered Skewes’ bound to about . In 1987, te Riele brought it down to a mere .
In 2000, Bays and Hudson went further. They proved that there are at least integers near with . Their paper includes many fascinating graphs—but the printing is of very poor quality, unpleasant to look at. I think the world deserves better pictures of their amazing result, so yesterday I decided to redo their work with the help of AI.
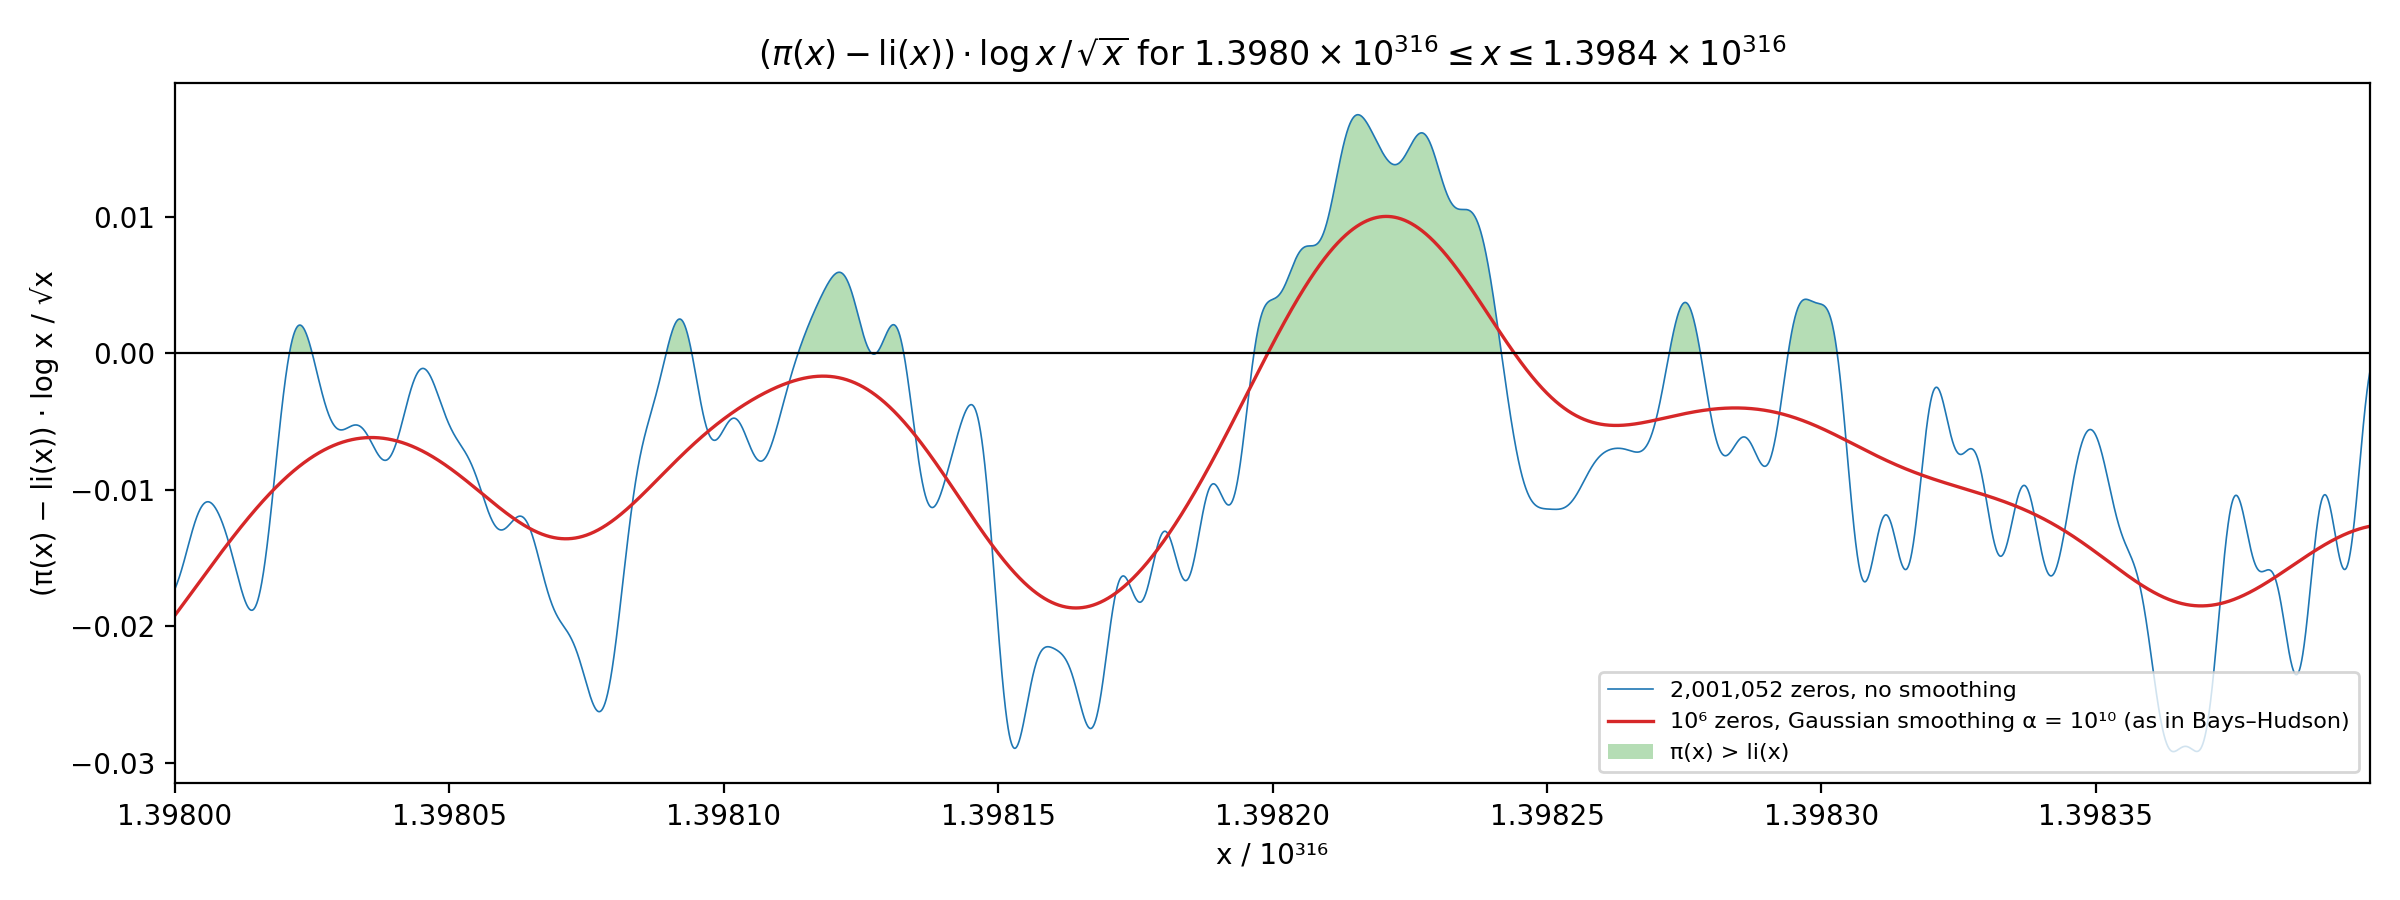
To draw these graphs we need to use Riemann’s explicit formula for as a sum over zeros of the Riemann zeta function. My calculations use twice as many zeros as Bays and Hudson had access to, but the computation now takes only a couple of seconds on a laptop. Here is my version of their Figure 2b:
Bays and Hudson’s proof does not depend on the Riemann hypothesis, nor do the later proofs mentioned below. Their graphs are another matter—and the same is true for the graphs here. It’s hard to get a really precise approximation to for huge numbers without using the Riemann hypothesis, since our best formula for it is a sum over zeros of the Riemann zeta function, and even a single zero off the critical line could have a big effect. However, a smoothed version of is much less sensitive to this problem.
The red curves in my graphs are smoothed. Since they go above zero for integers near , and they go sufficiently high, Bays and Hudson were able to prove that for some near this number. On the other hand, the blue curve is not deliberately smoothed. Its calculation assumes the Riemann hypothesis, and could change substantially if that was wrong! There could also be other problems, as I’ll explain. But it’s probably close to correct if the Riemann hypothesis holds.
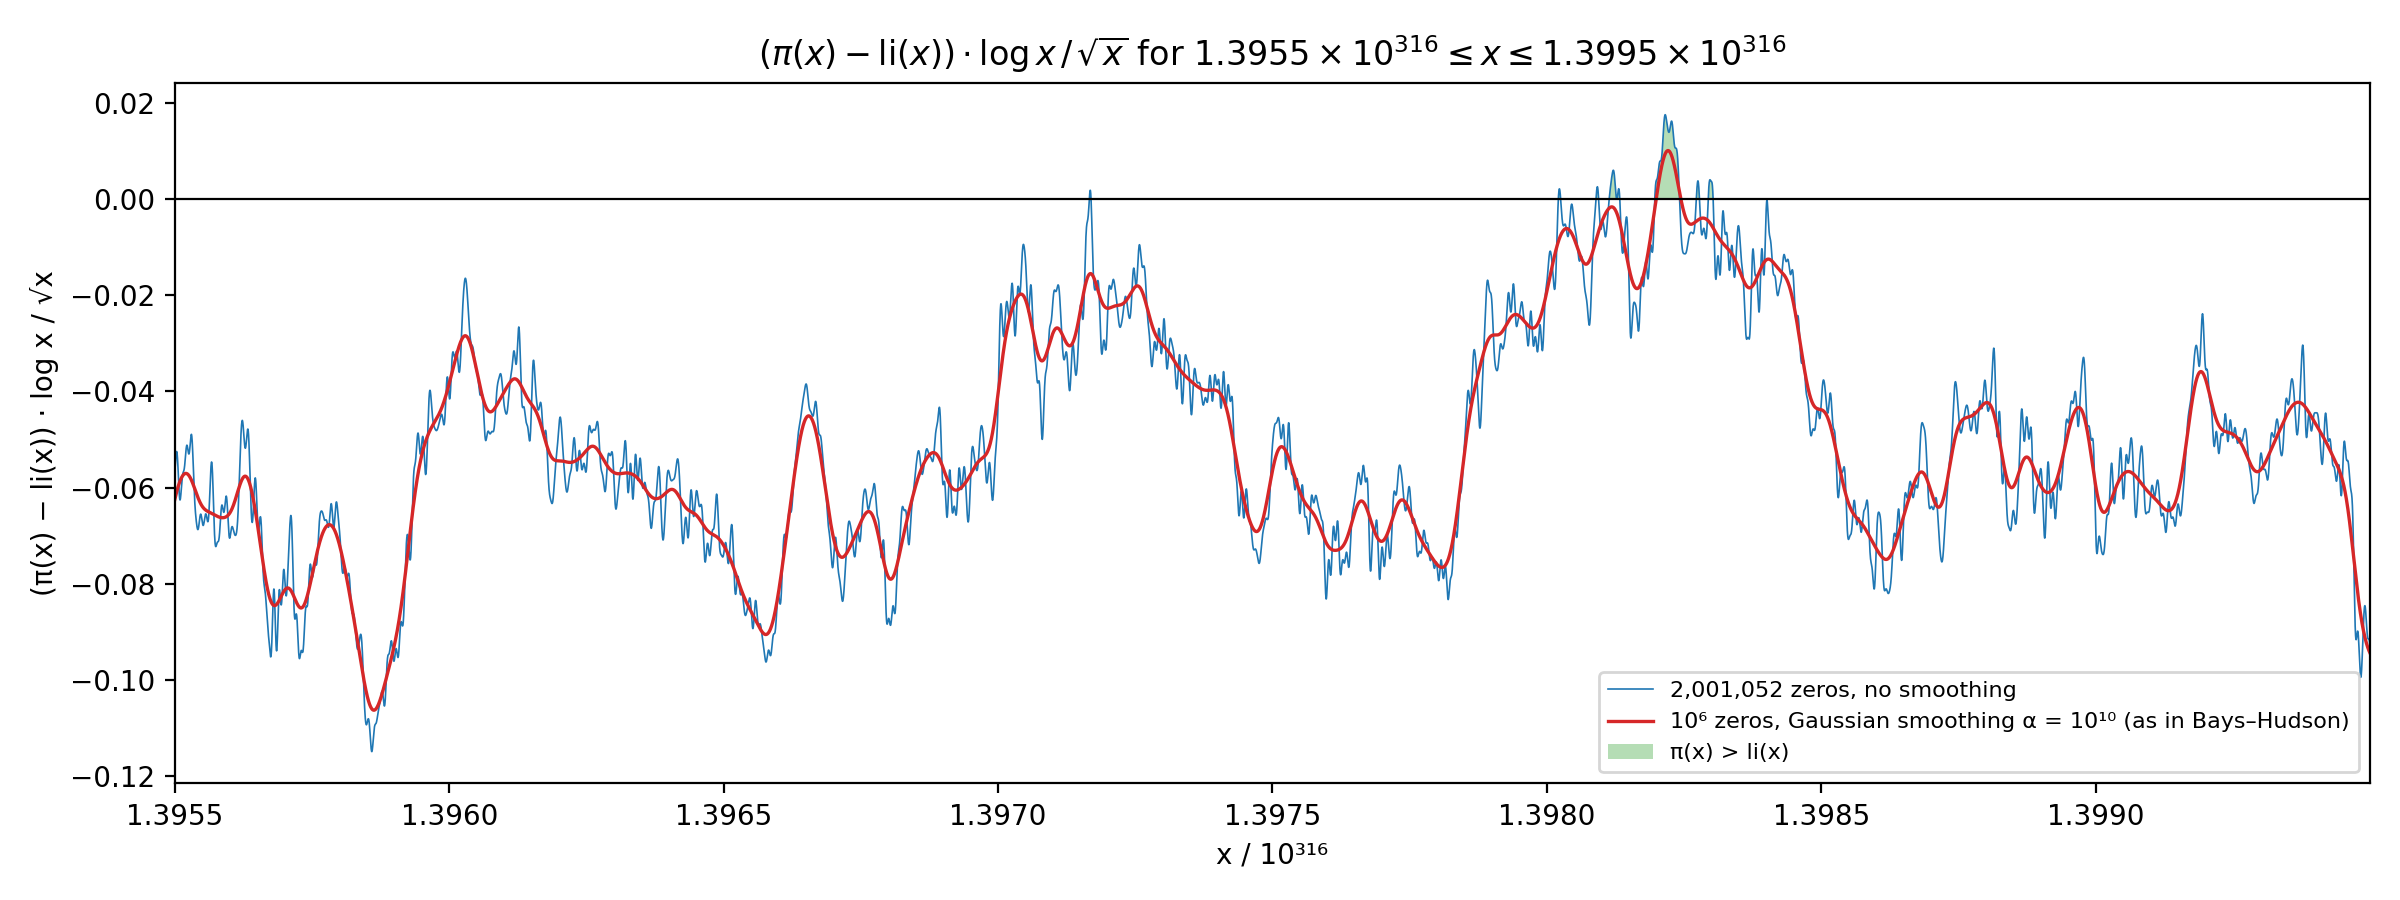
Intriguingly, also becomes positive for some slightly smaller numbers, in a region around . Patrick Demichel spotted this region, Saouter and Demichel proved it exists in 2010, and Saouter, Trudgian and Demichel pinned it down more sharply in 2015. Here is a wider view that also includes their region. See the sharp spike in the blue curve?
What is plotted
Nobody can compute exactly for numbers so large as . What we can compute is an approximation coming from Riemann’s explicit formula, which expresses as a sum over the nontrivial zeros of the zeta function. Assume the Riemann hypothesis, so is real. Write and measure in units of :
The symbol hides several approximations of quite different kinds; the section “What is rigorous and what is not” explains exactly what it means. The term
comes from the squares of primes: counts primes, but the explicit formula naturally counts prime powers, and correcting for squares gives this term. This term is why is usually negative, by about . Higher powers of primes give extra corrections that are negligible when is huge.
More interesting is the sum over zeros: each zero contributes an oscillation in with frequency and amplitude roughly . These oscillations are the key: becomes positive only when enough of these oscillations get in phase and add up to a positive number bigger than 1! Or more precisely, bigger than
On the graphs, means , and the vertical axis is in units of , which is about near . Each graph shows two curves:
- Blue: the sum over the first 2,001,052 zeros, with no smoothing. This approximates point by point. Leaving out the higher zeros causes an error of roughly in these units, assuming the omitted terms behave like random noise.
- Red: the choice Bays and Hudson made. It uses the first zeros, each damped by a factor with . This is a Gaussian average of over a width of about in , which is the quantity Lehman’s trick from 1966 controls rigorously.
Data and computation
The graphs here were made with a short Python program, skewes_window.py, using the NumPy, mpmath, Matplotlib and FINUFFT libraries.
The Riemann zeta zeros come from a table computed by Andrew Odlyzko: the first 2,001,052 zeros, accurate to within . Back in 2000, Bays and Hudson needed a personal favor from Odlyzko to get a million zeros. Today the same table is a free download, and it is even packaged on PyPI as passagemath-database-odlyzko-zeta.
Each point on any curve in the graphs here is a sum of one or two million sine waves. Summing directly at 8000 points would take about operations. Instead the program uses a nonuniform fast Fourier transform from the FINUFFT library, which finishes in about a second on one core. Two precautions matter: the program never forms itself, only , and it computes each phase modulo carefully, because reaches about .
Three graphs
Narrow window, -. This graph shows our estimate of for between and .
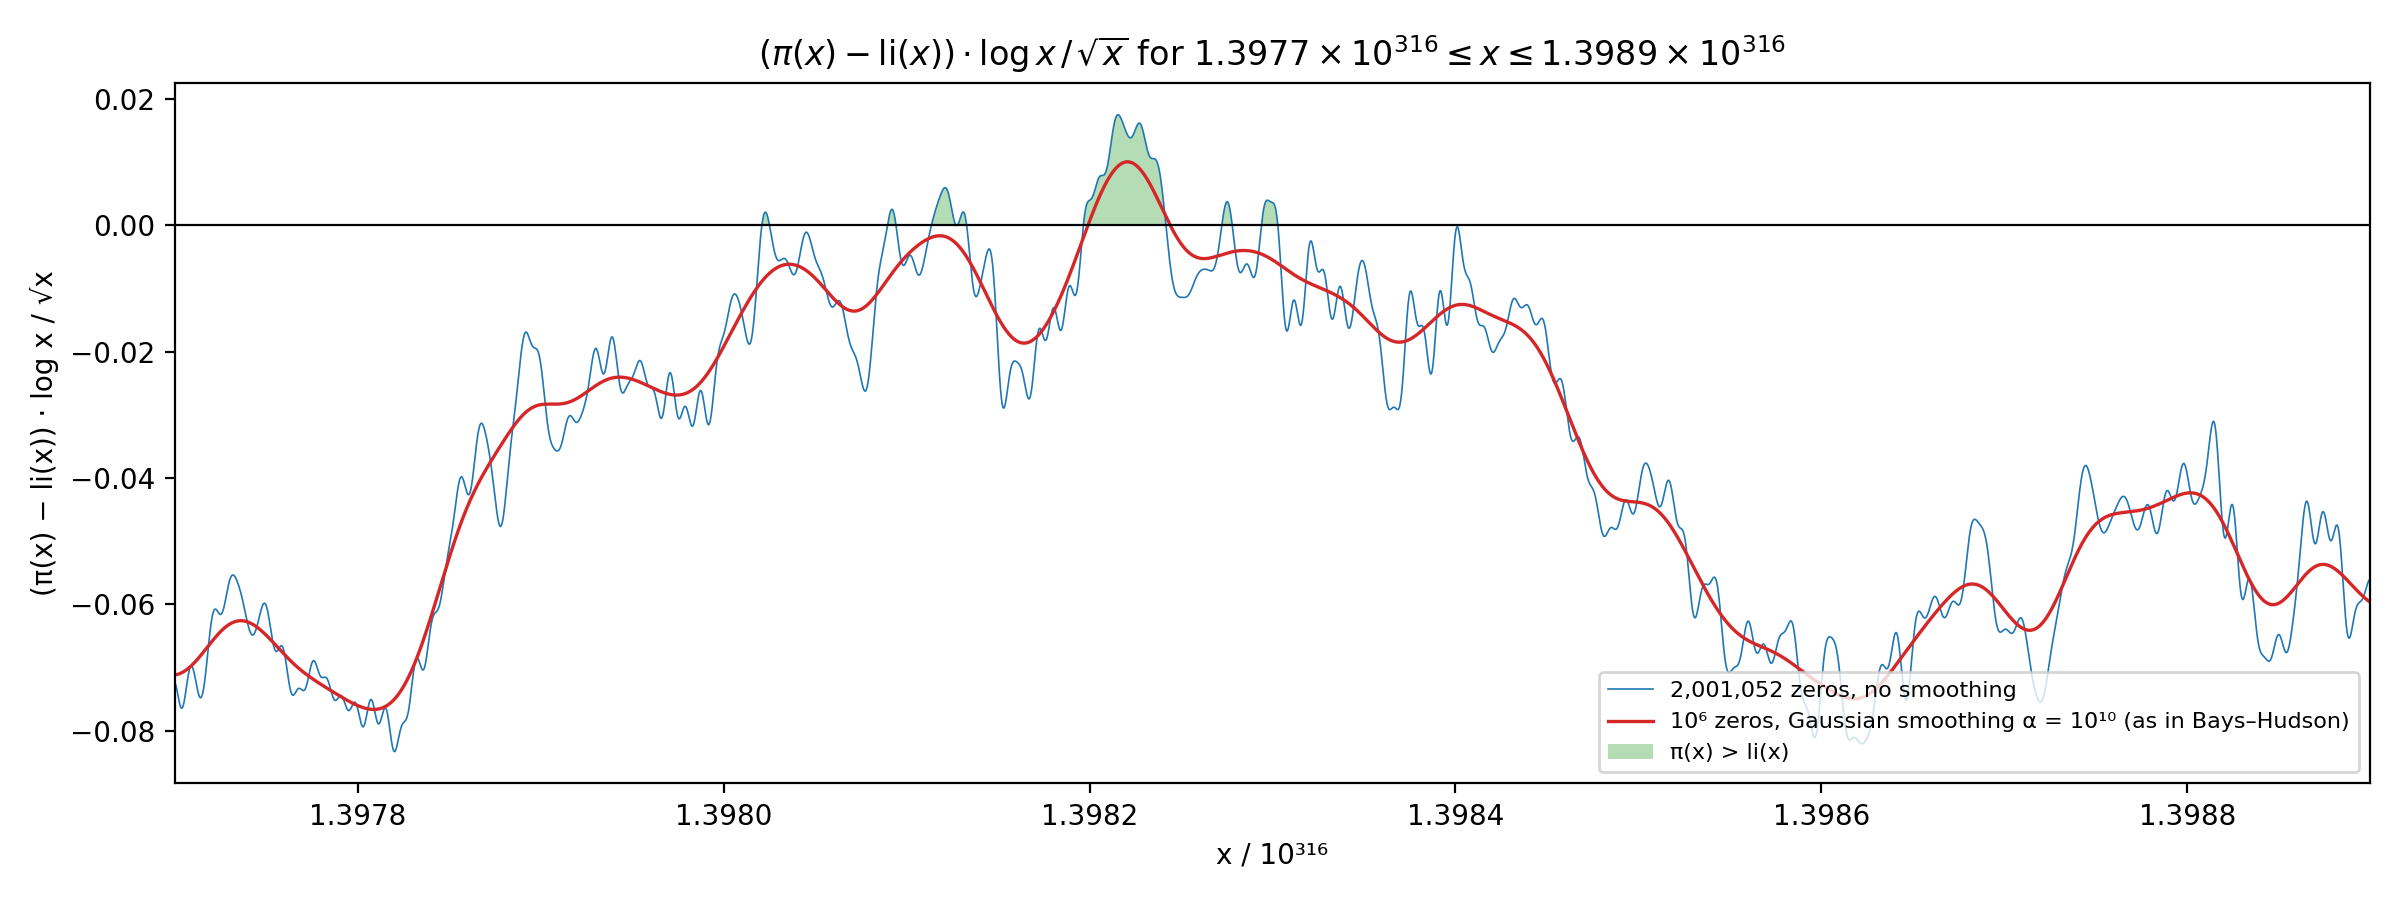
This is the same range as Figure 2b in Bays and Hudson’s paper. The region they proved positive is the green hump near . usually hovers around , but throughout this window the low zeros happen to be nearly in phase, lifting it close to zero. Even so it is a narrow escape: the blue curve rises only about 0.017 above zero. The red curve peaks at about , which is what lets Lehman’s theorem prove that somewhere in this region. Two smaller bumps of the blue curve, near 1.3981 and 1.3983, barely cross zero; they are about as big as the truncation error, so they could be artifacts.
Narrower window, -.
This is just a piece of the previous graph, to make the green hump more visible.
Wider view, -. This zooms out to show what lies just to the left.
The thin spike at about is a second positive region, found after Bays and Hudson. Saouter and Demichel proved there in 2010, and Saouter, Trudgian and Demichel later narrowed it to an interval centered at . In this graph the blue curve rises only about 0.0018 above zero at that spike. That is no larger than the error from using only two million zeros, so this graph alone could not prove the spike is positive. Their proof used about zeros. The red curve, smoothed too heavily to see so narrow a spike, stays below zero there.
What is rigorous and what is not
The red curve could be given rigorous error bars; the blue curve cannot, and itself, point by point, is out of reach near .
Where the formula comes from. The starting point is Riemann’s explicit formula for his prime-power counting function . For it says
where the sum over zeros converges only conditionally and must be taken in order of increasing . Proofs are in the books of Edwards and Ingham. Möbius inversion gives , so
Expanding and , multiplying by , and pairing each zero with its complex conjugate gives the formula for . Apart from the correction and the Gaussian damping, this is the function in Table 1 of Bays and Hudson.
What the means. Three separate approximations are involved, and they are very different in character.
- Dropped smaller terms. These come from and higher roots, the constants, and the zero sum belonging to . Assuming the Riemann hypothesis, they are smaller than the terms kept by factors like , which is about near . Rigorous bounds for them are routine.
- Truncated asymptotic expansions. The first omitted prime-square term is about . The error in expanding each is of order , negligible even when summed over all zeros. This step too can be made rigorous with explicit remainder bounds.
- Stopping the sum at the 2,001,052nd zero. This is the step that could cause trouble. The best known rigorous bounds for truncating Riemann’s explicit formula at zeros of height give an error of order . Making that smaller than would need of roughly , around here, while the 2,001,052nd zero only has height .
What can we do about the problem in item 3? Assuming the Riemann hypothesis, is an almost periodic function of , which is the setting Rubinstein and Sarnak use. A Parseval identity for such functions should then give the long-run mean square of the omitted tail as about . That is a statement about averages over very long stretches of . It does not bound the error at any particular point, or even the average error across our window. But we can say is the typical error at each point of the blue curve if the omitted terms in the sum over zeta zeros act like random noise. This is just a heuristic, though it’s been checked at . So the blue curve is just a good guess, not something proved.
The smoothed curve. Every positive region found so far was proved using a theorem of Lehman (1966), stated as Theorem 1 in Bays and Hudson’s paper. Instead of trying to pin down at a single point, Lehman’s theorem handles a weighted average of it: the average of against a Gaussian bump of width centred at some point . The theorem says this average equals minus a sum over the zeros, with each zero damped by a factor , plus an error term with explicit bounds that hold for every . The red curve is essentially this damped sum, plotted as a function of . The key point is that an average can only be positive if the function being averaged is positive somewhere. So if the damped sum is above zero by more than the largest possible error at some , then for some with near . Bays and Hudson proved their result this way, and later authors used refined versions of the same theorem.
The smoothing is what gives this approach its teeth. The damping makes the contribution of the omitted zeros decay like , so stopping at height costs almost nothing. With these parameters the total error is a few thousandths. So one could draw an upper and a lower curve that provably bracket the smoothed function. Wherever the lower curve is above zero, somewhere nearby.
This holds without assuming the Riemann hypothesis. Lehman’s theorem needs the Riemann hypothesis only up to a finite height, which has been verified: Platt and Trudgian have now checked it up to height . Any hypothetical zeros off the critical line beyond that height are covered by an extra error term, which the Gaussian smoothing makes harmless. For Bays and Hudson’s parameters this term is smaller than . So the positive regions near and are established unconditionally.
The method is one-sided, though. It can prove that crossings exist, but a negative average says nothing about a narrow positive spike hiding inside it.
Earlier crossings. Bays and Hudson observe (p. 1287) that current knowledge cannot rule out sign changes of over gaps as large as near . For the same reason, nobody can currently rule out a crossing somewhere below . Bays and Hudson thought none is likely. Their Figure 1 marks near-misses around , , , and . Rigorously, it is known only that for all . So between and about the question remains open!
In 2025, Michel and Rivers listed some places in this enormous interval where might get bigger than . If you want to contribute to this fascinating story, and you enjoy heavy-duty computations, you could look at those places. You may need a big table of Riemann zeta zeros.
References
The main papers
- Bays, Carter, and Richard H. Hudson. A new bound for the smallest with . Mathematics of Computation 69, no. 231 (2000): 1285–96. https://doi.org/10.1090/S0025-5718-99-01104-7.
- Lehman, R. Sherman. On the difference . Acta Arithmetica 11 (1966): 397–410.
- te Riele, Herman J. J. On the sign of the difference . Mathematics of Computation 48, no. 177 (1987): 323–28. https://www.ams.org/mcom/1987-48-177/S0025-5718-1987-0866118-6/.
- Saouter, Yannick, and Patrick Demichel. A sharp region where is positive. Mathematics of Computation 79, no. 272 (2010): 2395–2405. https://www.ams.org/journals/mcom/2010-79-272/S0025-5718-10-02351-3. Also available at https://hal.archives-ouvertes.fr/hal-00515378.
- Saouter, Yannick, Timothy Trudgian, and Patrick Demichel. A still sharper region where is positive. Mathematics of Computation 84, no. 295 (2015): 2433–46. https://www.ams.org/journals/mcom/2015-84-295/S0025-5718-2015-02930-5. Also available at https://hal.archives-ouvertes.fr/hal-01174411.
- Stoll, Douglas A., and Patrick Demichel. The impact of complex zeros on for . Mathematics of Computation 80, no. 276 (2011). https://www.ams.org/journals/mcom/2011-80-276/S0025-5718-2011-02477-4.
- Platt, Dave, and Tim Trudgian. The Riemann hypothesis is true up to . Bulletin of the London Mathematical Society (2021). Also available at arXiv:2004.09765.
- Revers, Michael. New bounds in R.S. Lehman’s estimates for the difference . (2025). Available at arXiv:2501.04488.
The explicit formula and its approximations
- Davenport, Harold. Multiplicative Number Theory. 3rd ed. Revised by Hugh L. Montgomery. New York: Springer, 2000. Ch. 17.
- Edwards, H. M. Riemann’s Zeta Function. New York: Academic Press, 1974.
- Ingham, A. E. The Distribution of Prime Numbers. Cambridge: Cambridge University Press, 1932. Reprint, 1990.
- Rubinstein, Michael, and Peter Sarnak. Chebyshev’s bias. Experimental Mathematics 3, no. 3 (1994): 173–97.
Historical background
- Littlewood, J. E. Sur la distribution des nombres premiers. Comptes Rendus de l’Académie des Sciences, Paris 158 (1914): 1869–72.
- Skewes, S. On the difference . Journal of the London Mathematical Society 8, no. 4 (1933): 277–83. https://doi.org/10.1112/jlms/s1-8.4.277.
- Skewes, S. On the difference , II. Proceedings of the London Mathematical Society, 3rd ser., 5, no. 1 (1955): 48–70. https://doi.org/10.1112/plms/s3-5.1.48.
- Skewes’s number. Wikipedia.
Data and software
- Barnett, Alex H., Jeremy F. Magland, and Ludvig af Klinteberg. A parallel nonuniform fast Fourier transform library based on an “exponential of semicircle” kernel. SIAM Journal on Scientific Computing 41, no. 5 (2019): C479–C504. Also available at arXiv:1808.06736.
- Odlyzko, Andrew. Tables of zeros of the Riemann zeta function. https://www-users.cse.umn.edu/~odlyzko/zeta_tables. Also available as https://pypi.org/project/passagemath-database-odlyzko-zeta/.