Planet Musings

October 08, 2026

Terence Tao — What should we tell our students?

[This is a guest post by Álvaro Lozano-Robledo. This blog post was initially written in a different file format and converted using AI. — T.]

TL;DR: Keep calm and carry on studying math.

I would like to give Terry my heartfelt thanks for giving me the opportunity to contribute a post to his blog. After giving much thought to what topic I should write about to maximize impact, I decided to take this opportunity to reach out to the students: particularly to those undergraduate and graduate students who just a few months ago were dreaming of an academic career in mathematics, but their dreams may now seem distant and, for some, apparently impossible to ever become a reality. This post was inspired by a message (quoted below in its entirety, with permission) that I received from a student desperately looking for advice and guidance. This is not the only such message I have received (and I suspect that many of us are receiving many similar requests), but it is perhaps the most heartfelt, and the one that has moved me the most. Please also note the urgency of the message. Students are making decisions now.

Hey Prof, I’ve been watching your videos for a while now as a pure math undergraduate who once wanted to pursue a career in math academia. I know you probably have been getting a lot of questions regarding this matter, but I am just completely at an utter loss regarding my career trajectory, and even further, the meaning of life at this point. (I do realize a lot of people have it much worse than I do). I know you have been making a lot of videos lately with the new LLM progress updates, so I thought you might be the appropriate person to reach out to and get a slightly more structured answer regarding this matter. So, to cut to the chase, what I really want to know is: will math academia be big enough and accessible enough for anyone with sheer passion (despite not being the brightest mind in the field) to pursue a career in, or will it inevitably shrink such that it will only really be accessible to the brightest minds? (I do realize the “brightest minds” that I am mentioning here is not well-defined, and in a sense, I am taking it as a hypothesis that this is someone who is “smarter than me”). My second question is, will AI within 5–10 years surpass humans in being able to do pure math research? I’ve just really been lost for a couple of months now and lost in life completely. I don’t mean to make your day more depressing; sorry if I come off in any way of that sort. I would appreciate any advice.

The advances in LLMs are disrupting almost all aspects of academic research and education in mathematics and, while there are many aspects that concern me, the one single issue that worries me the most is the very real possibility that we are about to lose an entire generation of mathematicians. Many students are asking themselves whether going for a PhD in math is the right career move at this time. Many of them just a year ago were headed to grad school in mathematics, but they are now changing their mind, and think that a different career (as far from math as Law School) may be the best path given the threat that AI may completely alter the academic math landscape in the coming months.

The questions students are worrying about are as follows:

  1. Will AI surpass the mathematical research ability of any human?
  2. Will research mathematicians become `professional prompters’ and interpreters of LLM output?
  3. Will only the `brightest minds’ be able to meaningfully contribute to research mathematics?
  4. Will mathematicians be employable? Will mathematicians be needed?
  5. Should I pursue a PhD in math at this time?

In this essay I will try to address these questions to the best of my ability, but will start with two disclaimers, followed by a brief summary of my own outlook.

Disclaimer 1. My answers may “age like milk,” as YouTube commenters love to quip on older videos. I can live with that, because this post expresses how I and many of us in the community around me feel today. Things can change quickly, though (see Disclaimer 2). I also want to acknowledge my privileged point of view as a tenured professor in mathematics — the situation can look much more troubling from the point of view of the job insecurity of a very early-career mathematician.

Disclaimer 2. No one has the answers at this time. I want to make clear from the start that no one can know with certainty the answers to any of the questions posed above: not any particular Fields medalist, not any given mathematician, not any particularly vociferous AI expert, and not the frontier model companies. And if someone is telling you with extraordinary confidence what the future holds, then I would immediately distrust the motives of their conviction (anecdotically, almost anyone on X.com that predicts the triumph of AI and the demise of the mathematics profession, is either a self-proclaimed “AI expert” or works for an AI startup). No one has a clear picture because development of LLMs has been so fast (and opaque) that it is almost impossible to predict what is to come. A good piece of advice is to ask the same questions to many people, to hear a (hopefully balanced) range of opinions. To that end, I am collecting interviews with mathematicians in what I call the “Human Mathematicians in the Age of AI” video project. I encourage you to listen to the interviews for some fantastic points.

For the record: I do not have the answers either, but I am hopeful and excited for the future. I will explain why below.

Who is controlling the narrative about LLMs in math? Overall, the mathematical community’s reactions to the advances in AI have ranged from confusion to anger — but, mostly, confusion about how to proceed. The most dystopian predictions seem to be driven by the fact that the so-called frontier model companies (and other LLM-powered companies) are controlling the narrative in the best of their interests. Unfortunately, the best corporate outcomes for an LLM company could have potential catastrophic outcomes for the math (and scientific) community.

It is certain that AI companies want us to believe that their products will imminently achieve “super-human intelligence” and that, in particular, they will be able to autonomously solve any mathematical problem a human could solve with or without the aid of an LLM. It is in their best corporate interest that the public is convinced of the (allegedly) “unlimited potential” of their technology, particularly before their companies’ stocks go public (i.e., their upcoming IPOs: Anthropic in November 2026, OpenAI in early 2027, etc). Thus, they have tried to control the narrative by spending a huge amount of (human and computational) resources in order to find solutions to certain well-known mathematical problems. The proofs are then released in announcements that lead the public to believe that their models can already autonomously solve any problem at all, and swiftly at that. However, this is (currently) far from their true capabilities. For instance, they never discuss how many tokens have gone to the trash bin with no payoff in trying (and failing) to solve famous problems. We do know, for example, that OpenAI invested the equivalent of some $15M to solve (err, scoop) the Navier-Stokes problem, but we are unaware of the surely colossal running cost of the failures to resolve other Millennium Prize problems.

My own outlook. Even though I am concerned about the incursions of LLMs into academic mathematics, I am quite hopeful. In fact, I consider this to be the most exciting time in my mathematical career (since the year 2000 say). Truly, this may be the most thrilling moment in mathematics in the modern history of our discipline, and I would be terribly sad to see young people leave academia and miss out on the stunning opportunity to be at the frontlines of the current scientific revolution. And not just sad: I think their absence would have disastrous effects for the field.

Undoubtedly, LLMs are already an incredibly powerful tool. If used correctly, and if we set up sensible academic conduct expectations around the use of LLMs, these tools can accelerate progress in our discipline unlike in any previous era. I fully expect that we, the community, will adapt and adjust to this new period, and we will harness these tools to achieve truly great things that just a few months ago seemed far out of reach. And I fully expect that human mathematicians will be front and center in these wonderful achievements to come. I will add reasons that support my optimism below.

I also want to add at this point that the day-to-day of a mathematician has not changed much so far! My days are still filled with teaching and joyful conversations about math with colleagues and students, doing research on a number of exciting (old and new) projects, and going to stimulating conferences to learn and disseminate our most recent methods and findings, while spending time with colleagues that make the mathematical community so wonderful and vibrant. Daniel Litt mentioned the same sentiment in a recent tweet.

One thing has changed though, I am busier than ever before, because the number of research projects I am involved in has tripled in just a few months. My research horizon has expanded significantly, and I have many more projects available for students to help me with.

Now, to the pressing questions:

“Will AI surpass the mathematical research ability of any human?” This is completely unclear. On one hand, the current trajectory in capabilities is surely significant, and we have already seen many impressive results that have been either proved by LLMs, or their proofs have been made possible thanks to substantial LLM contributions. On the other hand, none of the proofs so far seem to contain “alien ideas,” a move-37, or completely novel arguments or new concepts that were not present in the literature in some form or another. This should not be shocking because the LLMs are built and trained on the entirety of all human contributions to date, so it stands to reason that they would `think’ within the boundaries of our current knowledge and make connections (sometimes surprising and ingenious!) among ideas that are already present in the literature. I am particularly fond of the hypothesis (or toy model, as he called it) put forward by Nestor Guillen in a recent blog post, where he argues that LLMs may work within the confines of the convex hull of ideas that are currently available in the literature.

Take, for example, the disproof of Erdos’ unit-distance conjecture. We can imagine the current set of mathematical ideas as a stellated high-dimensional polytope, and we can place the state-of-the-art ideas on discrete geometry at an outer vertex and our knowledge on algebraic number theory at a different outer vertex. The idea for the proof seems ingenious at first sight because it cleverly mixes strategies from two fields of math at the vertices of the polytope of ideas, but after closer inspection, it’s a proof that was within reach of humans as it just sits within the convex hull of the polytope.

The polytope of ideas

This agrees with what Melanie Matchett-Wood said about the proof of the unit-distance when it was released: “I believe if the level and type of human expertise that is represented on this note had been assembled to find a counterexample to this conjecture a month ago, and those people put in similar amounts of time working on it than they did to reading and thinking about Chat GPT’s solution, the mathematicians would have found a counterexample.”

However, a proof of the Riemann hypothesis, say, may need new ideas that are strictly outside of the convex hull of current mathematical ideas, and it is therefore out of reach for an LLM. Only after a new idea is introduced in a new paper, the polytope of ideas may acquire a new outer vertex. And only then the LLMs, after being retrained to include those ideas, may fill out the set of results up to the new convex hull, which may or may not include yet a full proof of Riemann.

The convex hull of ideas

If this toy model holds up, then we would indeed expect the very fast advances in mathematics that we are currently seeing. As the LLMs take advantage of the stellated nature of the polytope of ideas, they will continue to fill in gaps between outer spikes. But as the LLMs fill in the convex hull with new results, we will see a deceleration in the number of results being shown solely by artificial intelligence. We will need human advances and intuition to generate new ideas that expand our knowledge polytope.

Even if the mathematical capacity of the LLMs (or future AI models) can at some point reach beyond the convex hull of the current set of human ideas, there is a different way that we may reach a limit to the LLM capacity: feasibility and ethical use of resources (this is similar what fellow optimist Kevin Buzzard called the “natural boundary” in a recent blog post). Is any cost (a dollar amount, human cost, ethical cost) acceptable in the pursuit of solving a given problem? Should we spend millions of dollars and an undisclosed amount of natural resources in order to find a solution for Navier-Stokes? As an analogy: we would like to know if there is life on Mars, but in order to do so as soon as possible, we would need an absurd amount of funding and risk the lives of a human crew in the process. Is it worth it? Similarly, we may reach a point where an LLM could solve an important problem for an exorbitant cost (in terms of funding and resources) but it may just not be an acceptable cost for the taxpayer or society to bear. Instead, we will need humans to devise an alternative route (the equivalent of a gravity-assisted robotic mission to Mars) to solve the problem at an acceptable cost, that produces a similar result in terms of mathematical advances and, more importantly, human understanding.

“Will research mathematicians become `professional prompters’ and interpreters of LLM output?” There is no indication that this will be the case. Yes, LLMs have produced proofs of important results somewhat autonomously (according to the frontier model companies — see Disclaimer 2) that some mathematicians have been tasked with interpreting and digesting. But in my own experience, and other research mathematicians who are using LLMs in their research seem to agree, working with an LLM is akin to discussing a problem with a collaborator, and the results heavily depend on how much guidance and intuition the mathematician inputs into the conversation. In other words, the LLMs are more than tools: they can be research collaborators but, as in any collaboration, the experience and the results are greatly improved when all parties contribute to the discussion. Further, mathematicians have no desire to prompt “solve the Riemann hypothesis, make no mistakes” and then interpret the proof. We prefer to be active participants during all the steps in the process of the discovery of a proof, because we are motivated by the `why the result is true,’ more than by the final answer that `the statement is true.’

Also, if we buy into the previous concept of the convex hull of ideas, then at some point in the near future it will be impossible to make progress in mathematics without a human adding a new idea, a new definition, a new concept that creates a new spike in the polytope, and then progress can occur.

“Will only the `brightest minds’ be able to meaningfully contribute to research mathematics?” At any given time in the history of mathematics, there have been mathematicians who are research active, and whose mental capacity for mathematics seems completely super human (e.g., the owner of this blog, among many others). It is natural to surmise that they could solve any problem we could solve, in a fraction of the time it would take us to complete a proof and write it up. However, this has never stopped those of us with a more modest capacity for mathematics from enormously enjoying doing research, and producing results that are far from insignificant. In fact, mathematics has always benefitted from the range of ideas and points of view, from the very concrete to the big bird’s eyeview, from the smaller contributions to the building of entire new theories.

Similarly, I am not threatened by the mathematical capacity of LLMs. For one thing their capacity is currently limited, as pointed above. And for another, even if their capacity becomes far superior, there will always be a need for mathematicians at all levels to guide research in paths that make sense for humans to walk (not run).

The mathematical universe is enormous (as Emily Riehl said), and computing time is finite. There will always be areas of mathematics that are under-explored and where even beginners can break new ground. The LLMs can help in the process, by quickly exploring avenues that may be dead ends, pointing out paths that have already been explored, and shining a light on paths that are likely to be fruitful.

As I mentioned above, I have never been this busy, because the access to LLMs has multiplied the number of areas that I have access to, and my curiosity has expanded well beyond my research area. I now have many more ideas that I can possibly explore on my own, so I am recruiting more student collaborators than ever before, to help me test whether these problems can lead to interesting results. Students can be involved in research earlier than ever before too because the LLMs can help them learn material faster (and deeper!), by virtue of being available 24/7 to answer their questions, instead of my meager one or two available hours per week to meet with them.

“Will mathematicians be needed? Will they be employable?” I find these questions natural but also perplexing. Even in the most dystopian of scenarios where AI becomes super human in all research tasks, what good would a proof (of a theorem in pure mathematics) be if there are no human mathematicians to digest it and understand it? Regardless of the advances in LLMs and AI, there will be mountains of research to be understood by humans, with or without the help of a computer.

In addition, we seem to forget that mathematics departments exist in universities to serve two primary goals: discovery and communication of mathematical knowledge. Virtually every mathematics department emphasizes, in equal parts, our research and educational missions (and many institutions place the educational mission of mathematics at a much higher level than their research mission). Mathematics courses are an integral part of a liberal arts curriculum because learning to think as a mathematician is a highly useful and applicable skill. The fact that we are researchers adds immense value to our educational goals, because students are best served learning from those scientists who are in the frontlines of research. The research opportunities that we provide for undergrads are a very valuable add-on to their curriculum, as it is a different type of training that helps them be employable in the future. And as long as the mathematical way of thinking continues to be a highly valuable skill to be learned by the undergraduate population, there will be a great need for mathematicians to be hired by universities.

The LLMs are making math research more accessible than ever to those who are not even in academia or even mathematicians. This means that undergrads will be able to join actual mathematician-led research projects much more easily, and it may be a new fertile ground for exploration. Not mindless exploration, though, but mathematical exploration where the goal is understanding and for the students to be initiated and trained into a highly technical field (in an ethical way). And, of course, we should prioritize training students in how to communicate the mathematics they learn, as that has always been (and probably will become even more of) a crucial skill.

All of this to say that I cannot conceive that the LLMs will displace mathematicians from their jobs. On the contrary, they might produce jobs since our research productivity may sky rocket. On the other hand, I am more worried about policies and funding issues that are political in nature and have nothing to do with the AI and LLM conversation.

Finally, the most important question of all, that I wanted to address here:

“Should I pursue a PhD in math at this time?” The answer to this question should be personal to each and every student. But, in my opinion, the answer should not have changed from a year ago to today. The most important reason (and perhaps the only reason) to do a PhD in math should be that the candidate is passionate about mathematics and wants to become an expert in a particular topic within our field. If that is the goal, then the presence of LLMs in mathematics is irrelevant, because the goal is achieved when the candidate has gained sufficient knowledge to be an expert on a particular problem. If anything, LLMs may be used as a tool to achieve that goal more efficiently. For one, I am using them every day to finally understand concepts and techniques that I always had questions about, and now I can query an LLM until I am fully satisfied. I am able to search for the explanations and examples that click with me, that click with my own particular way of thinking about mathematics.

To what degree a student wants to use LLMs in a math PhD should be a personal choice but I will say that, as my colleague Jeremy Teitelbaum put it in a recent interview (here is the bit I am referring to, and here is the full interview), students cannot afford not to learn about the current capabilities of LLMs, or any other technology for that matter. If your goal is to become an expert, then you have to be amenable to learning from all experts in the field, and from all sources that may allow you to go deeper into a subject than anyone else before you — and LLMs can be extremely efficient tools to explore literature, for instance.

But once again, the decision to do a PhD should not be based on the current state of the art of technology.

I wanted to do a PhD in mathematics because it seemed like a magnificent challenge. I wanted to do a PhD because I wanted to learn how Andrew Wiles proved Fermat’s Last Theorem. I wanted to continue studying mathematics because I simply did not want “a real job,” and the opportunity of contemplating advanced math on my own for a few years seemed like a dream to me, just too good not to give it my best shot. I know I would have deeply regretted it if I had not tried to complete a PhD when I had a chance (the best time to do it is when your undergrad knowledge is fresh!). I wanted to hear mathematicians talk about math, and rejoice in the small little details and miracles that make proofs work. I wanted to meet and hang out with other people who also thought number theory was the coolest thing on Earth. I wanted to publish a paper in a research journal, with my name on it, because I discovered a new theorem that no one had thought of before. I wanted to explain and share my passion for mathematics with others in a classroom and outside of the classroom.

Simply put, I just wanted to do math, and I would have been devastated if some undefined threat to the field of mathematics scared me away from the opportunity to pursue a PhD.

And if you are a student that is passionate about mathematics, and someone who wants all of that too, then a PhD is the right path for you, regardless of the technology available during your degree. You will learn to use the technology to a degree that you are comfortable with, and that fulfills your own dreams and expectations of what a PhD in Mathematics means to you.

Afterword: the BIG OpenAI release. After I finished writing this blog post, and had already sent it to Terry, OpenAI released a huge treasure trove of results in mathematics. This is, undoubtedly, a historic time in mathematics. The theorems in their papers prove some huge open problems in mathematics: the resolution of the so-called quasi Riemann Hypothesis, Goldfeld’s conjecture, the Hodge Conjecture in the case of CM abelian varieties, Hilbert’s 10th over Q, the Rigidity Conjecture… and the list goes on and on.

But such a tremendous release does not force me to change any of the points I made above. On the contrary, we already knew their models can do amazing things (e.g., Navier-Stokes). We already knew the frontier models can connect dots in the existing literature in ingenious ways (e.g., unit-distance conjecture). We already knew that OpenAI can spend a mind-boggling amount of resources to attack problems.

Also, we suspected that their models have limits and the new release shows evidence of that too. In their report, they mention that they attacked 4000 open problems, and their model was able to make progress on about 700 related problems. Yes, some of the ones they were able to solve are huge. But it also shows that their models are limited, quite possibly due to the arguments we explained above.

Are any of the solutions using new ideas that are outside of the convex hull of the current ideas in the literature? We will need mathematicians and time to digest these new proofs and understand what connections are being made, and whether brand new ideas were actually discovered in the process.

The main point of my post remains the same, though. There is a lot of mathematical research that remains to be done with and without the aid of LLMs. There are new mountains of mathematics to explain and communicate to others. And if you are a student who is passionate to learn what is new and what is left to do, then a PhD is definitely the right path for you.
John Preskill — In praise of questions

Prende y se apaga sola,

sale después de hora.

CHARLY GARCÍA

La máquina de ser feliz1

I’ve learned to tolerate them, and sometimes even like them, but Zoom meetings are weird. Even in familiar contexts: I have weekly check-ins with a close friend/collaborator based in Germany, and despite our familiarity, it still feels weird at times. I joined Nicole Yunger Halpern’s group almost when it was established, during Summer of 2021. The pandemic wasn’t exactly over, and most of us were geographically scattered, as well as complete strangers. To half-palliate this awkwardness, Nicole came up with what’s now sort of a group tradition: icebreaker questions. These are chosen by group members (in a secret order that I believe only Nicole fully knows), and can range from day-to-day stuff (“what’s the best type of pasta?”) to deeper matters. 

A while back, a group member asked something along the lines of: “If you could give your younger self any scientific advice, what would it be?” My response then was: “ask the dumb questions you have as they come.” I had two reasons for this answer. First, dumb questions usually sound dumber in your head and are not as bad as you might think. Second, a dumb matter that doesn’t seem dumb at first, can turn into a really, really dumb question if it’s long unanswered. If I were to be asked this same icebreaker question today, I’d surely reply the same thing, but I believe the reasoning would be more nuanced. 

This text’s epigraph comes from a song in the appropriately named album Random, by Charly García. I’m not sure whether the “happiness machine” in Charly’s random scenario deals with Brownian circuits, but I’d like to think so. 

Over my PhD, I’ve had the opportunity to interact, discuss physics, and even collaborate with truly amazing scientists. I still don’t have a foolproof handbook of criteria detailing what makes a great physicist great,2 but I have observed some patterns. An important one is that great physicists speak their mind: they’re usually  relentless with their own confusion and ask whatever they have to ask to overcome it. Don’t get me wrong here; these people are giants, and I wouldn’t dare call their questions dumb, but asking good questions is a skill more than a gift. It’s like seeing Claudia Poll swim or hearing Hilary Hahn play a cadenza: yes, these people are objectively good, but there’s also a huge amount of practice that goes behind what one sees. And, in the case of asking great questions, practice comes from asking not-great (and sometimes even dumb) questions. 

I got a crash course in asking questions during a recent project. A driving theme of my PhD research has been the study of autonomous quantum machines. These devices execute tasks without classical, time-dependent control, operating under a time-independent Hamiltonian. My first experience with these devices was during an experimental collaboration in which Simone Gasparinetti’s group built an autonomous quantum refrigerator from superconducting qubits. The refrigerator ran on a thermal gradient: as heat flowed from a hot bath to a cold one, a three-qubit interaction carried energy out of a target qubit, cooling it with no external control. The experiment was a success, and its potential usefulness in information-processing devices led us to ask about other contexts in which autonomous quantum machines could shine. 

At the time, we came in close contact with folks at Marcus Huber’s group in Vienna, who were thinking in abstract terms about a fully autonomous quantum processing unit. We had the idea of designing autonomous protocols for logical gates in current-day quantum-technology platforms: Rydberg atoms, trapped ions and superconducting qubits.

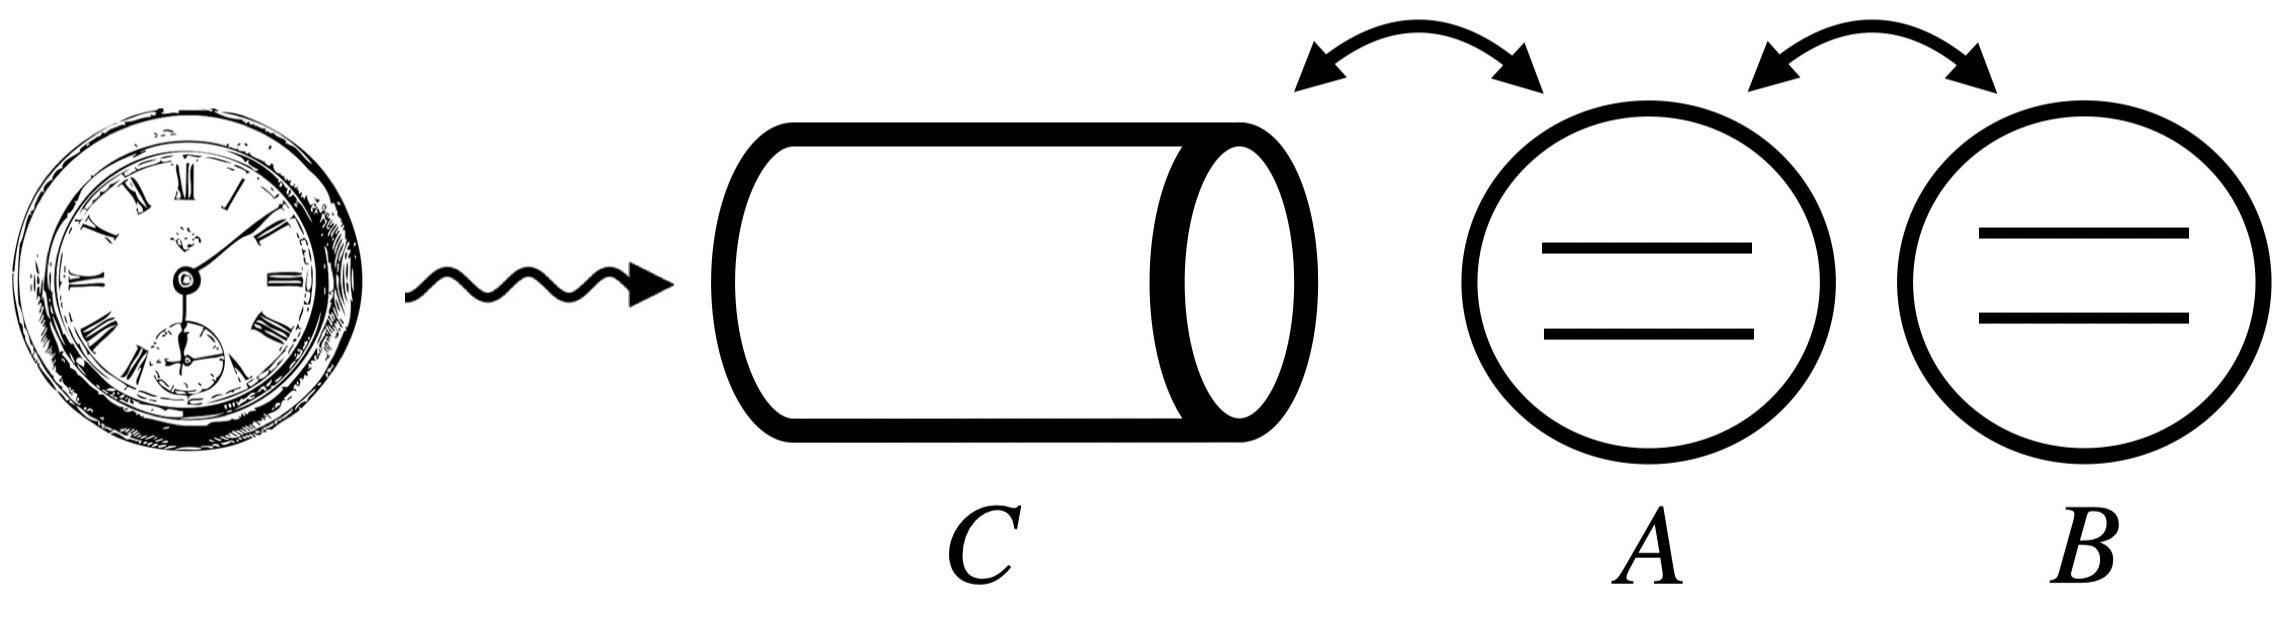
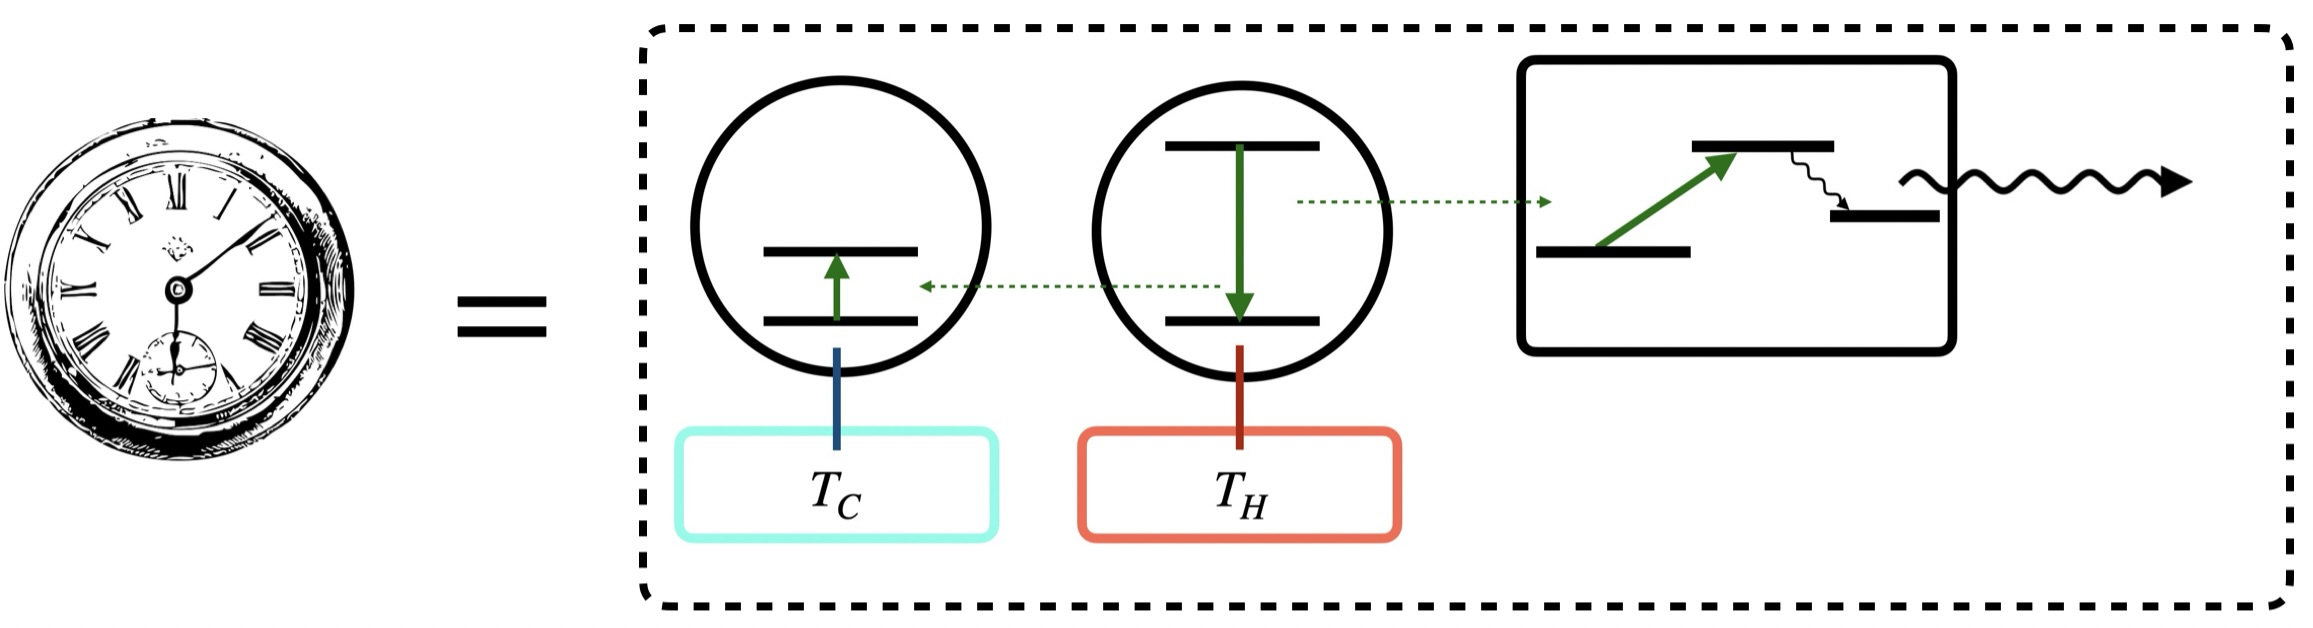
An autonomous heat engine powers a photon-emitting device (which can be thought of as a clock, for compelling reasons). The photons (ticks) trigger quantum-autonomous gates. 

To illustrate this autonomous-gate idea, I’ll briefly describe a gate protocol from our paper. As I mentioned before, an autonomous quantum fridge can be built by exploiting a thermal gradient. The same principle can help build a heat engine. Suppose one has three qubits, with energy gaps \omega_C, \omega_H and \omega_T. Let’s call these qubits the cold, hot and target qubits, respectively. The cold qubit couples to a bath at temperature T_C and the hot qubit to a bath at a temperature T_H, with T_H>T_C. Under the resonance condition \omega_C+\omega_T = \omega_H, the three qubits can swap energy all at once: the hot qubit loses an excitation while the cold and target qubits each gain one, or vice versa. The gradient makes the first direction more likely. The cold qubit can be engineered to quickly decay to its bath, so the exchange can’t run backward, and the target accumulates excitations. The cold qubit’s energy is lost to its bath, while the target could emit into a waveguide that delivers the photon to a chosen destination. The thermal gradient thus powers a device that emits useful photons with no external control.3 

What can we do with this autonomously emitted photon? We can use it to trigger an entangling gate. Two superconducting qubits with matching energy gaps can exchange excitations. Suppose we  have a tunable-frequency transmon qubit capacitively coupled to a cavity. An incoming photon from our autonomous emitter, entering the cavity, can shift the frequency of the transmon. If this effective, shifted frequency matches a nearby qubit’s frequency, the two transmons can interact. The effect of this interaction depends on the cavity’s decay time, rendering our entangling gate random and potentially useful for the implementation of Brownian circuits, for example. A charming instance of a quantum Rube Goldberg machine, if you ask me. 

An autonomous clock’s tick deposits a photon into a cavity. The photon shifts the frequency of a coupled transmon into resonance with a second qubit, triggering a gate.

This example illustrates the spirit behind our autonomous-gate ideas. As mentioned before, we propose  several more instances over different platforms. This all sounds nice and clean after looking at the end product. But the truth is that, when we started the project, I was a theory student with little knowledge about the inner workings of platforms, trying to pitch convincing arguments for novel gate protocols in these well-established technological fields. I had to go through decades of accumulated literature and famous experiments, trying to understand them and hopefully come up with ways to readapt them to the context of autonomy. Naturally, there were many old papers to read, many small details to understand that were obvious to a familiarized experimentalist but not to me, and, of course, many dumb questions to ask. Regarding this, I have to deeply thank Tom Manovitz, Norbert Linke and Simone Gasparinetti, our experimental collaborators, for their patience with these questions and their willingness to chat and clarify to a confused theorist what’s possible and interesting in experimental contexts. 

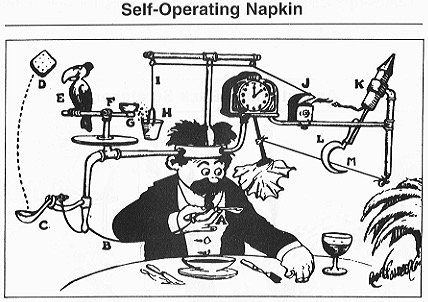
Goldberg devised a classical autonomous napkin from a parrot and a clock. We devised a quantum-autonomous gate from an electromagnetic cavity and a clock. Maybe we’re not so different. 

A special mention, however, to postdoc Yuxin Wang. Earlier in the text I mentioned how being relentless with one’s confusion is helpful; she’s one of the clearest examples I can think of. She came into the project right as I was struggling to model one of our superconducting-qubit gates. I was knee-deep in a convoluted formalism, drowning in inefficient numerical simulations that were leading nowhere. She asked a bunch of questions about our system and my modeling attempts for which I had no good answers for, especially because her expertise in both AMO and open systems really made my explanations look weak. I mean this in the best way I can: polishing my arguments and deeply enquiring about modeling decisions forced us to zoom out and look at simpler, more-efficient ways in which we could model our physical setup. I can’t even begin to quantify Yuxin’s patience and helpfulness in the project, nor how much I learned from working closely with her. 

Research, of course, is about asking questions. Trying to clarify confusion and asking in the most transparent way possible are discomforts I still struggle with (much like with Zoom calls), but I’ve learned to appreciate these convoluted scenarios and sometimes even thrive in them. Not being the smartest or most-experienced person in a room has lots of perks. You can learn a lot, although you might need to ask one or two dumb questions to get there. 

  1. It turns on and off by itself,
    it goes out after hours.
    CHARLY GARCÍA
    The happiness machine
    ↩︎
  2.  I do have, however, a handbook of criteria detailing what makes a useful autonomous quantum machine useful, though. ↩︎
  3.  Quantum thermodynamicists call these photon-emitting devices autonomous quantum clocks.  ↩︎

Proofs and Prompts — 100+ reactions to 100+ solutions

Hosts of Proofs and Prompts

Many of us are grappling with OpenAI’s announcement on 6 October. We feel that it is useful to have a snapshot of the community’s gut feeling today, and this is what you see below. We will keep it open for another week, and you are welcome to send us further short reactions. To make sure it is clear that we are all in this together, each reaction is signed only by name, without reference to affiliation or career stage. You’ll find all types of reactions: general reflections as well as problem-specific comments.

Tim Santens

The results of OpenAI are almost unbelievable, Quasi-Riemann is a result that I thought was complete science fiction. Much can be said about the behavior of the AI labs, but given the existence of these models mathematics as a research discipline will have to undergo a massive transformation.

Roman Sauer

A common piece of wisdom is that mathematicians only have a few tricks in their bag – which they skillfully apply again and again. I have such trick whose unreasonable effectiveness surprised me a few times: replacing a manifold by a certain measurable foliated object, a construction that comes from ergodic theory, and using it in unexpected contexts.

More recently, I relied on this trick in a paper with Sabine Braun on macroscopic scalar curvature, which was further extended by Hannah Alpert. This trick and these two papers now appear in OpenAI’s deeply creative solutions of problems 207 and 335 – problems so different, they could not be farther apart!

I am stunned.

What do I take away from this night? We cannot defensively narrow our focus to what we currently regard as human qualities in mathematics. This will force us into a diminishing role. Instead, we have to radically expand our view of what a mathematician is and does.

Xiaolei Wu

It is the last day of a week-long national holiday here in China. We had just taken a short family trip to a nearby coastal city. After waking up, I followed my usual routine and checked my phone. I was surprised to find many messages containing the same PDF file. Apparently, OpenAI had solved many open problems.

So I took a look at the group theory section. It looked unreal. These were almost all the major open problems in my field! How is it possible? So I sent a message asking where the file had come from. The answer was that OpenAI had just officially announced it.

I checked the group theory section again. Yes, these really were almost all of them. So Thompson’s group F is non-amenable. OK, I had tried it many times using ChatGPT, but I guess I didn’t have the newest model or enough tokens. Eilenberg–Ganea is false—not so surprising, perhaps, but how? OK, at least the Whitehead Conjecture has not fallen. And what? They had completely solved the Boone–Higman conjecture? And the ambient simple group could even be of type (F∞F_\infty)…\ldots I had expected this day to arrive, but maybe something like one year later.

After a while, I started to look at other sessions, starting from topology. So the Borel conjecture fails in dimension 4, the coarse Baum-Connes also fails…\ldots

The rest of the day felt long. More messages came in. My social media feeds were flooded with discussions about the list. Some people were still claiming that the problems solved in their fields were actually not so important. But I guess I had already passed that stage.

Nicholas Williams

We’ve certainly learnt a lot of new facts from this release. At the same time, it will take a while for us mathematicians to digest all of these papers. There’s no doubt that large language models have changed things enormously, but the end goal must always be human understanding. It feels important to point out that mathematicians do more than just solve open problems from the literature: we also have to grapple with the subject matter and think about what the good conjectures should be in the first place. But on the other hand, it does feel like the end of an era where the ability to solve problems was a distinguishing feature of being a mathematician. And this feels sad for those of us who like to solve problems.

Henry Bradford

Today my chief feelings are disorientation and bewilderment. It’s as if the pace of events has outstripped us by such a margin, that it is impossible to know how one should respond, or even how to start finding out how to respond. My greatest worry is for the prospects for bringing through the next generation of mathematicians: we know how much time and effort it takes to refine one’s craft in our subject to the point where one can meaningfully contribute to the advancement of knowledge, and I’m anxious that the necessary incentives may no longer exist for bright young people to invest that effort. I am holding on to hope that a bright future for the practice of mathematics is possible, in which our understanding of the mathematical universe is enriched, rather than undermined, by the ubiquity of AI tools. To get there though, we need as a community to agree what a realistic pathway should look like for a young scholar to establish themselves in our subject.

Henry Wilton

There are many problems on OpenAI’s list that I care a lot about: the Cannon conjecture, the non-residually-finite hyperbolic group, the Boone—Higman conjecture and at least ten others. I haven’t looked at any of them in detail yet, although a cursory glance suggests that the write-ups vary wildly in quality. It will take months of work to go through the proofs of all of them, to check if the proofs are correct and to try to digest them.

But I think it’s important to focus on the big picture. If OpenAI wanted to destroy the mathematical community, this would be a great way to go about it. Open problems are a resource that the mathematical community developed over decades or even centuries. The value they have is the value we have given them. They provide structure, a yardstick for progress and long-term goals. The advent of AI was always going to be a seismic shock, but this huge dump of papers is a tsunami that we have no time to prepare for. It’s clear that OpenAI will happily wash away our community’s structures to further their financial interests.

There is a long list of mathematical structures and norms that OpenAI seems to be intent on damaging. By refusing to name the authors of their papers, they imply that mathematics is no longer a human endeavour. They don’t submit their results to journals, which both implies that the norms of the mathematical community are defunct and makes it impossible for the community to digest their results. OpenAI haven’t shared fundamental information about how the problems are selected or the failure rates of their attempts. This information should be a necessary requirement for any serious scientific discussion of their tools. And of course there is the basic financial injustice that their hugely valuable models learned to reason by copying the very reasoning that our community made available for free through the Open Access movement.

I hope the mathematical community can adjust our practices and norms quickly enough to survive the shock of these developments, but I am fearful.

Macarena Arenas

Perhaps the AI companies could, if they wanted to, do something to benefit humankind and the planet we live on (ending world hunger, solving global warming, curing cancer…), but this is not it, and it is not being done for altruistic purposes.

Regarding the mathematics, some of it is unverified, most of it is badly written, and (probably) none of it is transparent in documenting how it was produced, who was involved, and what was its cost (in every sense). All of it is of course impressive. Some of it might come to benefit mathematics and mathematicians, but overall I think it is an example of a corporation trying to exert manipulative pressure on a field of knowledge, and I think it has been done irresponsibly. I hope that we as a community can find our way through this mess, but for the time being, it is a mess, and it causes more harm than good. It will distract a lot of people from working on their own ideas; it will disrupt many existing research agendas; it will create conflict in the mathematical community; it will encourage a lot of opportunistic, ill-informed use of these technologies (thus adding to the “slop” and creating more noise for us to navigate through); and it will discourage many, many people from doing mathematics.

Johannes Schmitt

One thing to keep in mind about this drop of papers is that they were not created by OpenAI with the main goal of making progress in mathematical research, or even primarily for PR (there were some PR posts, but e.g. the final announcement was comparatively restrained). The main reason these papers exist is that OpenAI used unsolved math problems to evaluate their internal models for the purpose of improving their capabilities. They had to use hard open problems because these are the only ones still posing a challenge to frontier AI models. I believe that, from OpenAI’s point of view, the papers are essentially a byproduct of their internal development.

Thus the company could just have remained silent, or picked a few flashy results for another blog post. I think it is to their credit that instead they reached out to the math community for guidance on how to proceed, leading to the formation of the Advisory Group on Mathematics and Artificial Intelligence. They followed some of the advice by this group, such as a timely release and (partial) Lean certificates, but not all of it, and in particular announced that they will continue to use open math problems for model development. In my view, the most pressing need of the math community right now is to have a central platform to discuss the results, start digesting the (by multiple accounts from colleagues, terribly written) papers, and report any mathematical mistakes or missing attribution. An OpenAI-controlled GitHub repository, with issues and pull requests disabled, cannot serve this purpose, and the ball is in OpenAI’s court to move the papers to a neutral repository and to back such a community effort with the promised funding for workshops and special programs.

Lvzhou Chen

To be clear, I only read some parts of the overview and a few papers in the collection without understanding the full details. I know most of the problems in group theory and quite a few in topology. I spent a few years thinking about the Kervaire conjecture, Howie’s conjecture (Problem 256) and related problems.

I have some rather mixed feelings towards this. On the positive side, I would like to learn and digest the new techniques or insights that lead to the solutions, and I hope to use them to better understand or solve other problems. On the other hand, I feel that solving so many problems in such a short time may damage the math community and profession. Often time, new discoveries were made in attempts to solve open problems (like the ones solved here). So we could have lost tons of opportunities to make other new discoveries; I hope what is worth discovering will be discovered sooner or later. In any case, this certainly creates even more stress and uncertainty than before for math people, especially junior ones (e.g. PhD students): How would the profession change? What should PhD students focus on? How should we train them? I wish what I called “damage” can be a part of reforming the profession in an eventually positive way, and (young) people interested in math do not get discouraged because of this.

As for the future, I guess (or hope?) that there will be a limit of the effect of AI: the landscape of math stabilizes after a dramatic change, and we obtain a new sense of difficulty. After all, we always find new interesting and harder problems after seeing the solutions to old ones. However, it might take quite some time before it stabilizes (if it does), and before then, it could be quite chaotic. Probably one can focus more on some brand-new areas and problems that seem fundamental and important. Even after it stabilizes, it is still a question whether human contributions are needed to make new discoveries. If it becomes unnecessary, one can still focus on better understanding the new discoveries, but I personally might find it less interesting and would rather work on other stuff. Maybe the question is not whether humans can still contribute; instead, as Ruixiang puts it somewhere, will mathematicians still have the courage to work on the remaining ones that are difficult in a new sense?

I guess most of these will just turn out to be silly and naive thoughts, but my understanding of this post is to record honest feelings, silly or not.

Enrico Fatighenti

I am not a Luddite — quite the opposite. I have used, and still use on a daily basis, AI as a bibliographic tool, to test random ideas, to speed up bureaucracy, as a helping hand with teaching, and so on. I do not use it to generate proofs, but I am not judgemental about people who do.

However, I was genuinely pissed off by today’s announcement.

To be fair, my first reaction was almost boredom. Yes, the AI has “proved” (really? Are we sure? Can we even understand what is written there?) a bunch of interesting results in my field. Not even a Millennium Problem. Pff.

But the more I thought about it, the more annoyed I became. What bothers me most is the double standard.
Whenever I referee a paper, or receive a thesis or project from a student, I apply the same standards that most of us do. If a paper or thesis is so badly written that I cannot get past the first page without considerable effort, I reject it and ask for a new, readable version.
With these AI-generated papers, I feel that we, as a community, are not applying the same standards of quality and rigour. They can simply release multiple 100+ page papers claiming to have solved this or that problem, often with redundant arguments, unclear logical structure, multiple dead ends, and strange or unsettling terminology — in other words, slop. And we are then expected to go through it, check it, clean it up, simplify it, and explain what is actually going on.

This comes at a considerable cost to us in terms of time and effort, while they can simply move on and slop-bulldoze the next conjecture. And, of course, the credit remains theirs. In some sense, we are willingly contributing to our own demise.

I think the paradigm has to shift. We should apply to AI-generated mathematical announcements the same standards of rigour, clarity, and exposition that we demand from human-generated papers. Do you want the approval of the mathematical community? A badge of legitimacy? Then give us something that is actually readable and verifiable. If not, we should simply ignore it.

In other words, I do not think that we, as a community, should spend our time cleaning up their mess in order to increase someone else’s commercial revenues.

It is going to be difficult to win this game, but at the very least we can try to change the rules a little, so that the game is not completely skewed in their favour.

Giulio Tiozzo

My feelings today are a mixture of excitement and worry: it’s nice to see many problems solved, and to discover new proofs. Yet it’s clear that our profession has changed forever. Some thoughts:

1) I don’t think the main problem of AI-generated math proofs is that they are not understandable: all first solutions to big problems were hard to process. The problem is that no one would want to do it, as they fear they would not get any reward, either by the community or on a personal level.

2) What puzzled me a lot is the method of communication: After AGMAI was created, the way I imagined the current math drop worked was: Each of the 9 experts chooses a problem and explains it carefully in a video, or writes a nice companion paper. Instead, it’s just a massive GitHub drop of slop papers. What did we even need AGMAI for?

3) It’s clear many papers were never reviewed by a human: for instance, I took their example #254 (an Artin group with no CAT(0) action): their group has 116 generators, but after feeding it to Astra, in 10 minutes I got a new example with 12 generators. Clearly, they were in a rush to post the big drop, prioritizing quantity over quality…Why?

This does not solve the misalignment between labs and academics at all; indeed, the question remains: are frontier labs our friends, or our enemies?

Raphael Appenzeller

This timeline is crazy. I feel conflicted. There are many good reasons for and against the use of AI in mathematics, and the uncertainty about the future only grows.

Alexandre Martin

After yesterday’s announcement, many of us are left stunned and unsure of how to adapt to this new situation. Already, there are calls from colleagues to organise international reading groups and workshops to make sense of it all and to write a “human account” of some of these claimed proofs. In my case, while some of the results have hit pretty close to home, and while some of these colleagues are very much well-intentioned, I have decided not to take part in any such initiative.

First of all, I do not wish to be part of what in some cases would amount to free publicity and free refereeing for OpenAI, contributing to the false narrative being pushed that this company is now actively collaborating with the mathematical community. A second reason is that in organising ourselves in such a way and at such a scale, we implicitly accept this new division of labour, where proof-production can become completely decoupled from any form of proof-comprehension, and where this dehumanized proof-production process becomes increasingly tied with an arms race for computing resources. I think this is unsustainable on many levels, and it is also simply not the future that I wish for our community and for our shared mathematical practice.

Baptiste Serraille

After seeing the huge advances posted today, I decided that I needed to try out ChatGPT extensively for the first time. Most of the time I do not give it my own ideas, I am too afraid of them transiting through ChatGPT to other users or OpenAI itself and losing my grip on them. Thus, I decided to try it on open problems of the fields or on projects that I will not have time to try on the short/medium term. Eventually, one of the problem did fall and it seems that a project that I had envisioned might also give something. I am both amazed at the results and the technological advances and scared at the fact that the pace is much higher than I can keep up with. I am also not happy to write a nice paper about ideas that are not mine and do it mostly because I believe that the field will benefit from it.

Matt Zaremsky

For several years now, the most major component of my general research program has been the Boone-Higman conjecture in group theory, including a series of papers joint with many others in which we’ve been gradually setting up and fine-tuning a nice sufficient condition for a group to satisfy the conjecture. I’d say roughly once per year for the last 4 years we’ve made some sort of big breakthrough that’s pushed the program forward in a strong way. Now this AI company decided the Boone-Higman conjecture had gotten famous enough that they should spike the ball, so they did. It turns out our sufficient condition always works, and the main mechanism we were missing was morally quite similar to the thing that was our 2025 breakthrough (extremely roughly speaking, the key is affine-like actions of things). So, apparently we were really on to something, and it’s believable we could have gotten there in another year or two.

So, how does that feel? Well, it feels like we’ve been working on an archeological dig for 4 years, gradually discovering more and more of a really cool-looking dinosaur skeleton, and then a trillion-dollar company showed up and just blasted the whole thing with TNT, handed us the whole skeleton, and walked away. So, I guess I’d say, “not great”.

Ilya Kazachkov

Firstly, beyond the scorched earth that the announcement leaves behind, its magnitude indicates that the changes to our profession are likely to be very profound. There are many questions covering all aspects of our work that we, as a community, will need to answer. Many of them have been raised in the media, including on this blog: What does it mean to do a PhD in mathematics? How will publishing, evaluation, hiring, and funding work? What is the role of mathematical research in society?

As for research, the most intriguing question the AI revolution seems to bring is in what constitutes a “good” mathematical problem. In particular, we will need to understand what types of problems, if any, can be solved by a human (and AI), but not by AI with little human intervention.

In turbulent times, panicking is the worst strategy. Whatever answers we inevitably come up with, after a period of uncertainty and anxiety, things will settle. I believe we will adapt, and the profession will live on in the new normal.

Mark Hagen

I have received emails from early-career colleagues who have asked my advice on other matters in the past, who currently seem very understandably distressed by these developments and the uncertainty they create, and are asking for advice again (or for some reassurance, or something). Today, I have prioritised trying to figure out what to say to them over reading any of the OpenAI preprints in detail, so I don’t have any useful comments on the content. I still don’t know how to answer those requests for advice, either (yet).

But irrespective of how interesting we might find some of these developments mathematically, I think the manner of their release reveals we’re clearly confronted with a bad-faith (human-institutional) actor here, whose interests are not aligned with my understanding of the point of scientific research (or any other worthwhile human pursuits).

I am worried about people that do mathematics, about my friends and colleagues, and about cultural practices (like doing mathematics) to which I attach importance. I’m even more worried about AI possibilities that are more general than mathematics: economic dislocation, degraded collective human capacities, supercharged exploitation and ecological collapse, new and terrifying means of repression and violence, etc. Mathematics has a reputation in our culture for being difficult and intimidating; evidently OpenAI have decided this renders our shared human endeavour a suitable vehicle to hijack as a display of power.

In any case, it seems like a situation in which it’s very easy to get confused or overwhelmed. This is a community that takes pride in being relatively tightly-knit and able to have productive collective discussions. This seems to be a test of those hypotheses.

Cyril Houdayer

Like many of my friends in operator algebras, I was shocked by the scale of the results announced by OpenAI. Two of these problems are particularly dear to my heart, because I have spent so much time thinking about them and working on them.

Connes’ rigidity conjecture was one of my favourite problems. Part of the sway it had on me, until the late 2010s, was due to the fact that it seemed to be completely out of reach. Even Sorin Popa’s deformation/rigidity theory did not offer a way to tackle it. In joint work with Rémi Boutonnet, we began studying higher-rank lattices using von Neumann algebraic methods. Our noncommutative version of the Nevo–Margulis–Zimmer theorems provided a conceptual framework for trying to recover the rank of a lattice from its von Neumann algebra. I pursued this direction through noncommutative boundary theory, uncovering some interesting rigidity phenomena and pushing hard towards rank recovery.

I did not solve the conjecture, but I had come to believe that a frontier model from OpenAI might do so, and I had been mentally preparing for that possibility. I had made my peace with it. Now I am genuinely thrilled by the announced solution, and I want to understand the proof. I look forward to gathering my PhD students and postdocs to study it together during the IHP programme « Operator Algebras: Approximation, Rigidity and Dynamics ».

Working on this conjecture meant a great deal to me, even though I did not solve it. It led me into the mathematics of Furstenberg, Margulis and Zimmer. I made new friends and discovered connections between operator algebras and discrete subgroups of Lie groups. Those experiences remain meaningful to me, and I am excited about the new connections that may emerge.

Connes’ bicentralizer problem has a different history for us, and there is an important clarification to make. This problem has played a central role in the structure theory of type III von Neumann algebras. Amine Marrakchi and I began working on it more than ten years ago, and Amine subsequently developed a substantial collection of tools and techniques to attack it. Recently, we returned to the problem from a rather indirect direction. In our joint work from September, we solved it for all type III_1 factors. The solution emerged as a consequence of a result about the bicentralizer of a flow on a type II_1 factor, within a broader classification theorem.

The proof announced by OpenAI builds on the methods developed in Amine’s earlier work and on the resonance mechanism we discovered together. Our recent work settled the nonrelative version of the bicentralizer problem. OpenAI’s result extends ours by establishing the relative version.

These announcements have shaken our community. I understand why many colleagues, especially younger ones, find this moment difficult, and my excitement about the mathematics does not make that unease disappear. I hope we can talk openly about both feelings. For me, the immediate response is to learn the proofs, discuss them with students and colleagues, and keep exploring the mathematics together.

Danny Calegari

About 15 years ago my experience with the lack of interest of the mathematical community in what I was discovering in the theory of stable commutator length in free groups (see https://www.quantamagazine.org/how-failure-has-made-mathematics-stronger-20240522/) led me to a resolution: from then on I would only work on what interested me. If I wanted to prove a theorem I’d prove a theorem. If I wanted to draw a picture I’d draw a picture. I’ve paid a (small in my opinion) price for this in the sense that I don’t think many people read my papers. On the plus side this means that OpenAI didn’t solve any problem that I was working on. They settled a couple of questions that I was curious about, but not enormously, and not in a way that was tied to my own sense of self.

The project that I am currently most excited about is the theory of higher dimensional zippers, and the most exciting aspect of it is that it’s now become possible to draw pictures (really: animations). One thing I love about some parts of mathematics (the Langlands program is an example) is that it’s not just a collection of theorems and conjectures; it’s a framework, and a story. I’ve always tried to look for the underlying story in my research (at least for the last 15 years). OpenAI hasn’t ruined that, at least for me (yet). Another example: a framework like Sullivan’s dictionary is more important than the top 100 papers in holomorphic dynamics (including Sullivan’s papers). In my own research, following the lead of Sullivan’s dictionary, I have just discovered the analog in the holomorphic dynamics world of a finite depth foliation: it’s a grafting of carpet wheels! Even naming this is exciting for me! Writing down the definitions and proving the theorems is the next step, but the reason (for me) to do that step is so that I can write some programs and draw pictures/animations.

Anyway: people do math in lots of different ways for lots of different reasons. I honestly think there will be more ways to do math in the future, not fewer. For the curious, the following movie (https://math.uchicago.edu/~dannyc/gallery/cs_zippers_movie.mp4) is what I am currently ecstatic about; it’s a zipper in S^3 associated to an arithmetic complex hyperbolic lattice, following some ideas of Isenrich-Py. The zipper is linked, and this reflects the fact that there is a circle valued Morse function with critical points but they are all in the middle dimension (2). I love this! I am currently collaborating with a musician to set it to music. It was produced by code that was written by Claude, generalizing code (and an algorithm) that I originally came up with in the 2d setting. If that’s not worth celebrating I don’t know what is.

Vadim Alekseev

I got really impressed by the resolution of the free factor problem (the von Neumann algebras of free groups are all isomorphic to each other), since I had been wrong about the expected outcome: I thought they rather should be non-isomorphic, since the parallel evidence from measured group theory (in my opinion) rather pointed there (via L2-Betti numbers); also, simultaneously the fact that the von Neumann algebras of SL(n,Z) are non-isomorphic justifies this line of thinking! So to me it is exciting: we now have to figure out what exactly still remains parallel between measured group theory and operator algebras, and what diverges and why.

Tristan Humbert

I woke up this this morning to an email of a collaborator informing me that Open AI announced a proof of Katok’s entropy conjecture, a three-decades old open problem which was the subject of my PhD and more generally the main motivation of my research. The conjecture was settled by Katok for surfaces and mostly open in higher dimension. The main project of my thesis was to prove a local version of the conjecture near complex hyperbolic metrics. After this I was planning on attacking the conjecture more globally. Open AI claimed a proof of the conjecture in full generality this morning and my first impression was sadness to see my favorite problem get “killed” by AI ; it is definitely easier to ignore a problem when it does not affect you directly. Next, I felt stressed because I am currently applying for postdocs and more of my research plan was now obsolete and I spent the whole morning rewriting everything and sending emails to my advisors in panic. Finally, I felt anger after opening the paper and observing that it was mostly unreadable slop. The sane reaction would have just been to ignore the paper but I think I care too much about the problem to act as if it did not exist. The only conclusion I can make right now is that Open AI’s standards for mathematical publication is far too low and is harming mathematical research maybe in an irreversible way and that the mathematical community, motivated by genuine scientific curiosity, is accepting to work for free in order to “validate” these unreadable proofs.

Tim Gehrunger

I was very curious to finally see the statement drop from OpenAI. I am not sure what they could have possibly done to meet my expectations, but I was at first slightly underwhelmed by what was in there, especially given the results in my own field of arithmetic geometry.

Of course a lot of the other work is impressive, and in some fields of mathematics such as combinatorics several of the main conjectures of the field appear to have been resolved, likely changing the way these fields will go in the future.

One thing that I found striking is that many of the articles were not as polished as one may have liked, with articles citing removed supporting manuscripts, missing citations of relevant prior work alongside minor mistakes (that I would strongly expect an AI to catch). This is something that a more elaborate workflow with dedicated agents for review, correct attribution and literature acknowledgements would have very likely caught. I hope future releases will use such a system to improve polish and to make sure that attribution for earlier results is given.

Peter Scholze

We should remember that we are all in this together; mathematics is a marathon, not a sprint; and the goal is and always will be the human understanding of mathematics, which will invariably take time.

What is worrying me the most, at the moment, is actually the (in)security of cryptography. Finding algorithms breaking standard cryptographic protocols is a number theory problem whose difficulty does, to my non-expert eyes, not significantly exceed what these systems are now capable of. And it would have disastrous consequences on society if such an algorithm is found.

Tasmin Chu

I was working on the pc<pup_c < p_u problem. I first learned about it in undergrad. There’s a beautiful 1996 paper by Benjamini and Schramm where they conjectured that Bernoulli(p) percolation on every nonamenable quasi-transitive graph has a phase with infinitely many infinite clusters. The converse is true by work of Burton and Keane. I loved this problem so deeply. It said something so beautiful and simple about these highly treelike graphs which had somehow eluded proof in the general case. It’s why I fell in love with percolation theory. Unsurprisingly the OpenAI preprint builds on work of my advisor Tom Hutchcroft and the approach he laid out to me a year ago.

My grant proposal due next week has to be rewritten. Maybe grant proposals don’t even make sense anymore. I have related results and work that I can talk about instead which were part of an overall research program I had to attack this problem. But I’m afraid to even talk about ongoing work now or do a research “announcement”. I have a high enough profile now I believe it’s not unlikely someone would adversarially try to prompt my result into completion.

I realize now that what I wanted more than to know that pc<pup_c < p_u is true was the time and space to think about it for the next few years. I feel a profound sense of grief for the working conditions I believed I would have. No one can take away the beauty and value of mathematical thought from me, but they can effectively disempower me in my own profession. What hurts the most is that OpenAI doesn’t even care about this result. They don’t know that our community, our intellectual thought, our knowledge is a living thing. To be frank, I find myself absolutely disgusted by the society I live in.

Terence Tao

My feelings on recent developments are very mixed and complex.

On the one hand, many of the AI-generated proofs appear to introduce clever new ideas that will be fruitful once digested, while also building upon the existing contributions of countless human mathematicians past and present. But at the same time, I am deeply frustrated that, in sharp contrast to traditional breakthroughs, none of the humans involved in these proofs are available to take questions, give talks, attend conferences, submit papers to journals, train students, or otherwise participate in the subsequent development of these results.

Similarly, I am excited by the possibility of the community being able to use these tools to tackle ambitious and large-scale projects that one could not have even dreamed of in the past. But I am horrified by the many person-years of ongoing patient and deliberately slow research efforts – particularly by graduate students and postdocs – towards many motivating problems in mathematics being casually disrupted or destroyed by such a release. Much as one cannot unhear a movie spoiler or a crossword clue, one cannot explore a problem as profitably and richly once one is aware of an existing solution. Yes, one can still analyze and digest such an answer; but the best opportunity to do so is at the moment of its discovery, and such moments are increasingly wasted when delegated entirely to AI tools.

And I mourn the path not taken, and the opportunities lost in the frantic race to develop this technology. Labs submitting their frontier models to independent researchers for proper scientific evaluation. Coordination with the research community to ensure these tools are applied to complement and enhance the abilities and activities of human researchers, rather than compete with them. Use of these tools to foster collaboration and sharing, rather than competition and secrecy. Opening new doors, without closing old ones.

But that is not the path we now find ourselves in. Instead, the community needs to come together more than ever. To clearly declare our own standards and values, to build our own tools and practices, to support our most vulnerable members, and to chart our own path forward. Let’s get to work.

Elia Fioravanti

While a feel a degree of excitement at seeing resolved some problems I considered almost inapproachable, this is overshadowed by grief and resentment at seeing a tombstone placed over many of the most promising and exciting directions in our field, where human solutions were well within reach in just a couple of years. I hope those working on those problems don’t give up on their work, we could still learn a great deal from it.

I also hope our community come together to digest the new results, senior and young mathematicians alike, regardless of attitudes on LLM use. The goal should not, however, be the writing of preprints containing insights developed through this process, unless the endeavour is supported with substantial funds contributed by AI companies.

Srivatsav Kunnawalkam Elayavalli

I was initially surprised when I saw the resolution to the free group factor problem. I thought that the free group factors ought to be non-isomorphic, and tried hard for a number of years to prove it in this direction. In any case, I am now fully convinced that theorems/proofs have almost entirely lost their currency in the profession. We will have to prioritize human understanding, and device methods to reward and incentivize this. Repeatedly posting AI generated and verified manuscripts achieves nothing but frustration and disorientation. As I said in my previous Proofs and Prompts article, my goal in this profession is to enhance my manodharma. Right now I am having plenty of enjoyment, I am spending all my time preparing the course I am teaching on “free C*-algebras”. I have excellent students who are very interested in the material. I have no interest in derailing myself and engaging in AI-induced indigestion by starting to read the tsunami of results from OpenAI at this moment.

Yang Li

Assuming that these proofs are correct, I must say that I am very impressed about these results, and if these results are properly understood, they may greatly accelerate the progress of maths. My main concern is sociological in nature. In particular, I feel that PhD students and postdocs are the most vulnerable group in an age of radical change, and the community needs to find a way to protect the younger generation. I also think that given the power of the technology, computational resources should be made more equally accessible.

Michael Chapman

I was amazed by the scale and breadth of the recent results coming out of OpenAI in their announcement. A few problems, such as the refutations to the Kaplansky conjectures, the existence of non-residually finite hyperbolic groups, bounded degree coboundary expanders in all dimensions, and the unique games conjecture were all problems “I grew up on” – namely, I learned about them quite early in my studies and was fascinated by them for years (and also worked on some of them extensively). I mostly want to sit down and read as much as I can, to sort out the main ideas and to study the results. This is quite humbling, and as a young researcher also disorienting. Nevertheless, I am more excited than afraid, and hope the mathematical community at large, and my own research community at the smaller scale, will grow stronger out of this.

Constantin Kogler

11 days ago, I witnessed GPT-6 Astra solve one of the best-known questions in my area. Excited by the stunning proof, I teamed up with a longstanding collaborator to rewrite and rethink the solution. After numerous days of hard work, we had a nearly finished paper by Monday. The same conjecture was claimed as Paper 148 by OpenAI on Tuesday. My collaborator wanted to publish on Tuesday, yet I wanted to check some aspect of the literature more thoroughly.

After the initial shock of the announcement, I personally didn’t feel strongly affected by the claimed solution of OpenAI soon afterwards. The key idea was anyhow by Astra. We published our paper on the arXiv on Wednesday. Had the main idea of the paper been our own, it would have been by an order of magnitude our best result. I was excited that we were involved in mathematics of that level and were probably the first humans to understand the solution. I hope others will write their own viewpoint on the proof, so that we will have several expositions with different perspectives.

Paper 153 is also on a question I deeply care about. I am sure I can write a clearer explanation than OpenAI did. So I look forward to understanding what happened and to expressing, hopefully with collaborators, our viewpoint on this profound piece of mathematics.

Yes, machines with such capabilities will change everything. Not only for mathematics but also for the world. I have sympathy for many of my colleagues being upset by this, especially those who already had stunning results themselves or outstanding work in preparation. For myself, I can’t help but feel like living in a mathematical wonderland with the next field-defining idea being discovered whenever I am ready for it.

Andreas Thom

Right now I feel proud that the mathematical community laid the foundation of such a terrific development. Let’s see how it feels tomorrow; we have to answer some serious questions. But in any case, we have enough to read for the coming winter.

Anna Chavez Caliz

Today I’m standing in a more optimistic side. We had a very stimulating and engaging conference last week, here in Cuernavaca. It was clear to me, more than ever, that an essential part of our job is not to be alone in an office, in front of a blackboard, or writing papers for only a small fraction of the population. I appreciated having the chance to remind myself that we still have the power to be excited about math when we go out and talk to others. As Tolstoy said, the enjoyment lies in the search for truth, not in the finding it.

Tobias Osborne

I have been closely following LLM capabilities for a good year now, and thought I was more or less acclimated (numb) to the pace of progress. Although I am not completely surprised, it is hard not to feel more than a little overwhelmed by OpenAI’s mathdump today. It is impossible to properly unpack all of this in a paragraph, especially so early, but I wanted to record a couple of thoughts: (1) So far I have only looked at a couple of the contributions close to my heart. I am struck by how recognisable the individual parts are. The wilder creativity lies in their counterintuitive composition. I would probably have given up on these combinations, or talked myself out of trying them. I am extremely curious to hear what experts make of the more significant problems. One feature I looked for seems absent: undecipherable “alien artifact” ideas and methods. The arguments are presented in prose and, although rough, seem approachable. (2) I think it is the right call to simply share all this stuff in the open: cognition is now abundant, and we should lobby for this resource to be made freely available as widely as possible. (3) I would caution that LLMs have in no way “solved all of mathematics”, any more than they have “solved all of software engineering”. Their capabilities are very spiky, and if you use them regularly, you know what that means. Undeniably, things are going to change: typing code into a computer with your fingers already feels anachronistic, yet engineering remains challenging. There is so much more to the job of a mathematician than solving problems. I am optimistic that the era of “Big M” Mathematics and “Big P” Physics has now well and truly arrived: we can finally take much more ambitious steps and reconsider the big questions that have driven our fields for centuries. Maybe now we can work together to make meaningful progress on them in our lifetimes.

Mahan Mj

Was going through the non residually finite group construction put out by OAI today, and it looked to me that there are really two quite different modules in the proof. One purely algebraic and the other geometric. After fiddling around with Astra for some time today, it gave me a reasonable sounding purely group-ring theoretic criterion for non-residual finiteness of a group. It suggested that this might also certify that the group is non-sofic. I have gone through the AI generated proof briefly, but not yet had time to check it thoroughly. At any rate, it looks like this is the one piece of the construction that is relatively new in the sense that it builds on the AI generated non-sofic group from some days back.

What does seem to be a pity is the following. By and large, the community has not yet had time to really absorb the non-sofic construction from about a month ago. It is quite conceivable that by playing around with that example a number of such criteria would come up over time from different hands. This could lead to a charting of the largely uncharted territory of non-sofic/non-residually finite groups. A consequence would be clarity and understanding–two of the main human reasons for doing mathematics in the first place. The present breakneck speed of things without human understanding compromises precisely this.

Barna Saha

I’m worried how big corporates are controlling academic research. In one case, an Anthropic employee asked a famous academic from a top university to sign an NDA, offered compensation and authorship to verify a result that many researchers have spent decades working. This is unthinkable in academic research. Authorship to work does not come in this way. In other incident, OpenAI dumps solutions to 772 problems in Math and adjacent fields-many of which are outstanding breakthroughs. General academics don’t have access to their powerful internal models. Publicly available models do not even come close. This creates a huge gap in accessibility and equality. I am seeing a lot of frustrations among students.

Josh Frisch

For years now, whenever I’ve met somebody new at a conference, I’ve asked them: “If you could solve any one question, what would it be?” The goal was to get beyond a list of “famous” problems and find out what mathematicians truly cared about. What did we really want to know? Only one person has ever answered “the Riemann hypothesis.”

Like many other mathematicians, my main emotion thus far in 2026 has been loss: loss of meaning, loss of purpose, loss of the era of human proofs, loss of the ability to picture the future. With the release yesterday, October 6, 2026, of hundreds of beautiful results—many, maybe most, answering someone’s “one question”—I am trying to move beyond loss. There are so many beautiful results here: problems nobody had any approaches for, algorithms nobody thought could possibly exist, unexpected isomorphisms, constructions and proofs. A mathematics built from the echoes and scaffolding of human mathematics, but one that clearly will go beyond it.

There are, there must be, so many beautiful ideas in this deluge of proofs. If we can learn the answer to our one question, even if the proof did not come from us, even if it did not come from any human being, then we need to try to understand it and to share that understanding with each other.

David Fisher

No human being should have to respond this quickly. Maybe AI can inspire a slow math movement. If I were cleverer, I would write this as a haiku.1

Martin Bridson

The scope of last night’s announcement is truly breathtaking. Until very recently, I would not have imagined that the frontiers of mathematics could move so far in one day. Beyond the remarkable list of problems that appear to have been solved, I am deeply impressed by the diverse forms of reasoning sketched in the documents that accompany the announcement.

These announcements will be exciting for many, frightening for others, and devastating for some.

Let me start with the case for excitement. Where there is excitement, it will surely derive not from the closing of open problems but from the opening of new possibilities. In the short term, there will be a flood of enhanced human understanding as the global community of mathematicians absorbs, refines and enhances the arguments produced by the machines. In some cases, experts will kick themselves for having missed a connection between disparate parts of the literature; in other cases, they may be amazed that an apparent trick works and will subsequently advance their fields by unearthing a new phenomenon that explains it.

In all cases, the struggle to wrestle human understanding from the machines’ formalities will unleash greater ambition for what we can achieve (working with AI agents) in this new era of mathematics. Some of our favourite mountains have been conquered, but behind them are bigger mountains that we can tackle with new equipment.

At the same time, we must resist the temptation to believe that digging insights out of announcements from AI labs will become the paramount task of our time. The global community of mathematicians has to be steadfast in its resolve to decide for themselves which research directions merit the most attention. We should embrace the power that the machines offer, but we should not be indentured to follow their lead.

This image of servitude brings us to the fear that undoubtedly stalks alongside the excitement associated to the ascent of AI’s ability to do mathematics.

The list of problems covered by OpenAI’s announcement includes several that were guiding challenges in my own research. I regret the loss of these guiding problems and I am convinced that future announcements will rob me of many others. I am saddened by this loss but not devastated. This relatively sanguine reaction undoubtedly reflects my career stage; I would have been less sanguine twenty years ago. I am acutely aware that today’s announcement will affect the lives of younger colleagues more profoundly.

Personally, I am looking to learning the new ideas and constructions hidden in the AI-sketches of the new results, and I am particularly looking forward to engaging with colleagues from all career stages in group efforts to understand what has been done. I anticipate a community effort to add layers of human insight and explanation. I think this effort will be genuinely communal and I think that we are going to have great seminars!

Nevertheless, I also have to confess to a nagging worry that a way of life that I have loved, in which the joy of the hunt for new discoveries was front and centre, will morph into something less familiar and less viscerally appealing to me. Profound understanding has always been the driving motivation of the research mathematician. In the hard struggle to glean understanding we are sustained by the joy of discovery and there is great personal joy to be had from understanding something beautiful for oneself. But for me, and I suspect for most of us, there is a greater joy in discovering and then sharing something that is new to humanity. If the role of a typical mathematician were reduced entirely to explaining the output of others (humans or machines), this greater joy would be lost and being a mathematician would be a less appealing vocation. This may not be our future, but it is a legitimate fear.

What is beyond doubt, I think, is that the recent developments have profound implications for the structure of our profession. We have to adapt our structures quickly, particularly with respect to the apprenticeship stage of our profession — PhD and postdoc years. Beyond that, there are many issues of credit and recognition, the role of publishing etc.

I also share the general unease about the lack of alignment between the commercial interests of AI labs and the values of our global community. There is an inherent and fundamental tension that cannot be resolved without sustained, robust engagement. We certainly cannot entrust the future well-being of mathematics to their goodwill.

Konrad Wrobel

Scrolling through the list of claimed results, I alternated between shock and apathy repeatedly. The sheer quantity I can only say is exciting (even outside of the standouts I personally care about and the others I’m familiar with), even if it is simultaneously incredibly emotionally draining. It feels surprisingly anticlimactic capstoned by the mountains of work we have in front of us in parsing these, frankly horrifically written, papers and what the new ideas are inside. I can only guess how long it will be before I can internalize the ideas relevant to me.

Alon Dogon

My feelings on the matter have changed so many times throughout the day, ranging from severe fear for the future to excitement for having finally answers for many great problems.

If I had to pick one personally, the equivalence of strong Ulam stability and amenability (along with Diximier’s problem) has particularly touched me, as I have spent several years thinking about it seriously.

The solution seems to combine Fursternburg’s boundary theory with quantum circuits from quantum computing, how wild is that?

In general, it is impressive to have many conjectures settled in the positive this round.

Hugo Duminil-Copin

I expected that one day we would be surpassed, and that it would happen systematically. But yesterday’s announcement hit with a force I had not anticipated. Dozens of papers deal with topics I was working on. Between results that beat you to the finish line and thousand-page proofs, I don’t even know where to look anymore.

Not a single one of the major open problems I have publicly mentioned throughout my career (whether in a talk, a lecture, an article, or even a grant proposal) was left untouched by the announcement. Everything has been claimed to be proved.

I expected to see a few of them in the list. But not all of them. Not all at once. Not with such nonchalance.

“For the glory of the human mind,” they said…

The shock is immense. I am paralysed. Tomorrow, we will find a way forward. We will rethink our profession and how we work. We are a resilient community, and I have no doubt that we will adapt. But for now, I simply don’t have the energy. I think back on all those years, all those faces… I think of my colleagues, my students… And I fear I won’t be able to find the right words.

Petra Schwer

We have talked about “the list” throughout the day with many people at the workshop I am at. I am feeling lots of mixed feelings today. Ranging from shock to a certain degree of amazement about everything the technology can do. I am also angry that we are being bombarded with ‘solutions’ by companies that seem to have little to no interest in the actual content. They seem happy about the dramatic headlines helping them to gain better funding. They don’t seem to care about everything being shaken up so fast that we (the community of mathematicians) can no longer keep up with cleaning up the mess.

Something that worries me is the small changes I am already seeing in my own behavior. I am no longer as open as I was in the past when talking about my research projects and plans. I did, for example, not answer freely to some of the questions after my talk. This is not just me. People are becoming more cautious. Mistrust is spreading, and that is not good. I am lucky to be part of mathematical communities that largely trust(ed?) each other. Seeing that change worries me.

What worries me even more is seeing the junior mathematicians around me struggle. Today I also saw a lot of fear. How can I help them stay afloat?

Is mathematics dead? Clearly, no2. What is happening to us right now is definitely a massive shake-up, earthquake, storm. There are a lot of questions to be addressed. For sure the mathematical research landscape will change. How exactly? I have absolutely no idea. And I very much hope that the communities (and people) I care for will come out on the other side with only a black eye.

Bryna Kra

There are deep and far-ranging results in this release, giving us a view on the powerful tools that now exist for exploring mathematics. But math is about more than producing theorems and this method of release loses so much along the way. Understanding this work is an enormous undertaking, and unlike work produced just a few months ago, there is no one to ask when we get stuck in a proof. This is not part of the culture of mathematics.

As a community, we have to come together and work to keep what we value. Our goal of understanding mathematics has not changed, but the methods of getting there have. One of my concerns is the ecosystem that allowed the body of work being used now to make the advances is being destroyed. The mathematics community has mostly been collaborative: we share questions, talk about work in progress, and give others ideas on how to approach a problem. By making it easy to translate those parts of our work into proofs, we short-circuit the understanding that is needed to have impact. This way of releasing results closes off directions of research, rather than opening new vistas.

The math community is already coming together to hold deep discussions on how to navigate this time of turbulence and change. It is time for us to move from discussion into implementation, charting the course for the future of our profession. The training for a doctorate, the hiring of junior faculty, the evaluation for promotion, the criteria for publication, the modes of publication all need to be scrutinized and updated. The good that comes out of this situation is the fall of the nonproductive traditions of our community, while keeping the parts we value.

Alvaro Lozano-Robledo

The “Big OpenAI drop” is nothing short of historic, possibly the single most important day in the history of mathematics thus far. Many of the problems with now proposed solutions in the Oct. 6, 2026 drop would represent huge contributions to their respective fields: quasi-RH, the second part of Hilbert’s 16th, Hilbert’s 10th over Q, the Hodge Conjecture of CM abelian varieties, Goldfeld’s conjecture, fast integer multiplication… They are undeniably huge contributions.

And yet, they have not changed my mindset. On the contrary, we already knew their models can do amazing things (e.g., Navier-Stokes). We already knew the frontier models can connect dots in the existing literature in ingenious ways (e.g., unit-distance conjecture). We already knew that OpenAI can spend a mind-boggling amount of resources to attack problems. We also know the price for their top-level subscription is about to increase significantly, up to $500/month.

Also, we suspected that their models have limitations, and the new release shows evidence of that too. In their report, they mention that they attacked 4000 open problems, and their model was able to make progress on about 700 related problems. Yes, some of the ones they were able to solve are huge. But it also shows that their models are limited in some ways: their goal was RH, not quasi-RH. Their goal was the full Hodge, not Hodge for CM varieties. Their goal was BSD, not Goldfeld’s 50-50. Again, quasi-RH is huge! But it is not RH.

Are any of the solutions using new ideas that are outside of the convex hull of the current ideas in the literature (in the sense of Nestor Guillen)? We will need mathematicians and time to digest these new proofs and understand what connections are being made, and whether brand new ideas were actually discovered in the process. There is a lot of mathematical research that remains to be done with and without the aid of LLMs. What has changed is that now there are new mountains of mathematics to explain and communicate to others.

Julian Wykowski

Navigating today, I kept thinking about a passage in Stanisław Lem’s Solaris (1961), where the main character fantasises about the existence of a bóg ułomny. This has been translated into English as an imperfect god, although I believe a more faithful translation would be a defective or disabled god. The passage reads:

“I’m not thinking of a god whose imperfection arises out of the candour of his human creators, but one whose imperfection represents his essential characteristic: a god limited in his omniscience and power, fallible, incapable of foreseeing the consequences of his acts, and creating things that lead to horror. He is a … sick god, whose ambitions exceed his powers and who does not realise it at first. A god who has created clocks, but not the time they measure. He has created systems or mechanisms that served specific ends but have now overstepped and betrayed them. And he has created eternity, which was to have measured his power, and which measures his unending defeat.”

Many members of the community agree that the main purpose of open questions in mathematics is to guide theory building and produce understanding, rather than a binary answer to some problem with limited applications in the real world. In that sense, we truly have created systems or mechanisms that served specific ends but have now overstepped and betrayed them. While it is certainly in OpenAI’s marketing interests to spread a narrative that mathematics has been “solved” through the existence of some lean code on some server, I sincerely hope our community will not succumb to such a defeatist narrative. Instead, I hope that we will find a consensus-based, organised approach to adapt our work to this new reality, in ways that align with our values, support our pursuit of human understanding, and benefit the construction of mathematical theory. This may well include embracing AI, but only in a form that maximises its positive and minimises its negative impact on the aspects of mathematics we consider fundamental. In the meantime, if OpenAI wants everyone to believe they are a deity, it is our duty to remember how defective their idea of deity is.

Ben Green

I was not expecting the magnitude of some of these results. Most particularly, seeing a proof of no zeros of Dirichlet L-functions to the right of Res=7/8\mathrm{Re} s = 7/8 (and a second, short, proof of no Siegel zeros) is absolutely shocking to me, but there are many other breathtaking advances. Closer to my particular expertise, many of the central problems of additive combinatorics have fallen, including around three quarters of the aims I had for an ERC Advanced Grant, awarded only in June. The work of understanding these solutions and the associated context properly is significant and, from what I can glean from the current manuscripts, likely to be very worthwhile. I’ll start with number 182, which shows that any subset of {1,…,N}\{1,\ldots,N\} of size N1−cN^{1 – c} has two elements differing by a square.

Sam Hughes

It was a privilege of a lifetime to get to do research level maths. But not like this. How much beauty have we lost?

Emily Riehl

Firstly, kudos to whoever is behind the website citedbyagi.com, which recognizes the mathematicians whose work is cited by the manuscript collection released by OpenAI. It will take quite a while to understand what exactly has been achieved there. But whatever it is was only possible because mathematicians formulated the conjectures, proved the surrounding results, and shared their ideas – in conversations, talks, expository writing, and papers – so that other humans, and now AI, could learn from them. I hope they continue, because like many others I love learning new mathematics from other humans and always will.

KEVIN BUZZARD

I am very excited about the future. I know that there is chaos today. We are in the eye of the storm. We do not want to read slop papers. Some of the OpenAI papers have already been retracted. We do not yet even know what is true. But I believe that truth and understanding will bubble to the top. There are plenty of important poorly-written papers by humans — bad exposition has always been with us, and mathematicians have offered translation services for free many times before. AI will get better at explaining. Mathematics has undoubtedly moved forwards this week — this cannot be denied.


Received 8 October 2026.

  1. I could of course ask AI to write this as a haiku, but not today. ↩︎
  2. See also here: https://arxiv.org/abs/2509.15998 ↩︎

Proofs and Prompts — Why I chose to do math, and how I’m grappling with AI advances

Jean-Christophe Mourrat, CNRS director of research at ENS Lyon

I’ve always felt an intense desire for truth, and so I was naturally drawn to science. At first I thought I would become an engineer. Then I saw that a career in academia was possible, and the idea of spending my life doing research at the frontier of knowledge and in complete freedom felt very exciting. I considered pursuing a career in physics. But as I progressed in my studies, my strong desire for logical precision came into tension with the often more practical approach of physicists, who do not always insist on perfect deductive rigor. I ultimately decided that I would study math, and more specifically probability theory. I liked it because its rigor would satisfy my wish for exactness, while its problems seemed to have some real-world motivations.

Yet there was a little voice in me that was unhappy. “Is it really responsible to do mathematics while there are so many more pressing problems in the world?” the little voice said. “Will you not become like a highly sophisticated violinist playing on the sinking Titanic?” I had long debates with it. I tried to tell it that what mathematics gives to society is perhaps less visible, less direct, but that in the long run it does contribute to the broader scientific ecosystem, and that this ecosystem has been of benefit to humanity. The little voice had some difficulty seeing the great long-term consequences my humble PhD work would bring to humanity. I could at least convince it that participating in a culture of radical truth-seeking and humility in the face of the unknown is broadly valuable.

My little inner voice, finding itself unable to propose much better alternatives, and also considering my temperament, finally decided that it was acceptable that I devote my efforts to the pursuit of higher mathematics. Our agreement was that (1) I would try to work on problems that could potentially be of interest to people outside of the math department, at least in the long run; (2) I would try my best to uphold high standards of behavior, in the hope of nurturing the culture of truth-seeking and humility that I claim to value; and (3) I would give a non-negligible fraction of my income to charities. When doubts about the usefulness of my work were strongest, this last part was particularly helpful to keep the little voice a bit more quiet.

In 2016, I heard about a group of people who had taken a pledge to donate 10% of their income to effective charities. I found that very inspiring and decided to do the same. When I moved to Paris a year later, I met such people in real life, as part of a movement called effective altruism (EA). These people were trying to think deeply about all sorts of important problems in the world, and about ways to address them. They spent much time discussing topics such as global poverty, animal suffering, pandemic risk, and AI safety. My initial reaction to considerations of AI safety was mostly negative; I thought that it was a concern for future generations, and that it was distracting us from more immediate problems.

Around 2019, I felt the desire to explore a new direction of research, as I periodically do. I wondered if I could find a research topic that would also have some connection, even if minute, with some of these topics I was hearing about among my EA friends. While I still thought that the problem of AI safety was one that would only become relevant in the far future, I thought that it would perhaps be good to participate in the building of mathematical theory on artificial neural networks. I started to read about old toy models of neural networks such as the Hopfield model and the perceptron, and about more recent work by physicists concerning restricted Boltzmann machines. As I delved deeper, I found fascinating math on what is called the theory of spin glasses, and I was hooked.

As the years went by, it became clear that AI was making more rapid progress than I had anticipated. I started to wonder how much time it would take for AI to have a significant impact on math research, and I grew more interested in AI safety research. I also experimented a bit with commercial LLMs to test their performance, and tried to reassure myself with their limited ability to maintain logical coherence.

In late 2024, the release of the first “reasoning models” by OpenAI was a watershed moment for me, as the arguments I was using to reassure myself suddenly felt much less convincing. I had already accepted by then, in an intellectual sense, that AI would ultimately change our activities profoundly. But at that point, it became something that I started to feel in my bones. And the little voice came back with new questions. “Does it really make sense to spend many months and years thinking deeply about a particular math problem? Why not wait for a couple of years, and then benefit from the great help that machines will be able to provide to you? Is it really so important to obtain a resolution of this math problem now rather than in a couple of years? Couldn’t you find more useful things to do in the meantime?” I didn’t know how to answer that. For a few months, I mourned my old way of doing mathematics, and felt deep sympathy for all the craftspeople throughout the ages who have been displaced by machines. I also became more worried about the broader impacts AI will have on society, and tried harder to look for directions of research in the theory of AI or in AI safety. Yet I found it difficult to identify good opportunities to work on AI safety per se. Perhaps I struggled too much to make precise sense of the questions in this area.

During the summer of 2025, I began to have scientific discussions with old friends who work in biology. I gradually came to see ways to contribute to problems that felt more directly meaningful, and where the “why not wait” argument seemed to have less force. First, for most math pursuits, the immediate benefit is less tangible than in biology or medicine, where two years of delay can have a cost that is counted in lives. Moreover, in math, thinking is very nearly the whole job. In most other fields, progress is also limited by experiments that take months, by data that nobody has yet collected, and by people and institutions that need to be persuaded. And on modeling and data analysis questions, while AI is already helpful, the process cannot be entirely formalized, and I believe that it is still difficult for people with less training in these aspects to distinguish sensible responses from confident-sounding wrong ones. Being the person who does that sorting is a modest role, and I do not expect it to last forever. But it is an entry point, and what it buys does not expire: collaborators, a feel for how the field actually works, and a sense of which problems are worth the effort. This convinced me to explore research in other fields more seriously. My experience in math will of course shape my attitudes and taste in the problems I encounter there. But I will not be specifically seeking opportunities to do math; my hope is rather to start from the technical side and to open up, over time, to a more diverse set of tasks, adjusting according to what seems most useful to do.

Now, how do I think about the future of math research? I am convinced that we are or will soon be living in a world where machines can produce very large amounts of rigorous math that no human has yet understood. I like William Thurston’s characterization of our activity as seeking to advance the human understanding of mathematics. And so I believe that it is important and valuable that humans continue to expand the body of mathematics that we collectively understand. In my view, mathematicians will become akin to “naturalists” of this infinite space of rigorous mathematics, which used to feel more like something that we painstakingly construct ourselves, and will progressively feel more like a pre-existing body of knowledge that we need to make sense of. And I’ll certainly want to play my part among the naturalists of spin-glass theory. But my little inner voice cannot be satisfied with this alone. At first this made me sad, but I have now come to see an upside to the situation. AI is not only facilitating math, but is also very helpful for learning new topics, for writing code, for curating datasets, and more. This means that we can scale up our ambition and more easily start to work on topics that sit at least partly outside of math departments. The world is full of difficult problems and fundamental mysteries that are not going to be resolved by AI overnight. I’ll try to work on some of them.


Received 15 September 2026.


Proofs and Prompts — Free Thoughts on Artificial Intelligence

Djalil Chafaï, professor at Université Paris Dauphine and ENS Paris

We knew that 26 was the only number sandwiched between a square and a cube, but no one suspected that 2026 was special too. For mathematics, 2026 will be remembered as the year in which the mechanistic dream of Hilbert, Turing, von Neumann, de Bruijn, and many others became a reality. Artificial intelligence has finally managed to surpass human intelligence in certain respects, a turning point of historic significance.

But the realisation of this fantasy of automating mathematics terrifies many mathematicians, who had built their professional lives in the niche afforded by the impossibility of its realisation. Here we have all the cruelty of a La Fontaine fable. Even so, those who put the pursuit of knowledge and science first rejoice at this state of affairs, without losing sight of the many questions it raises.

Artificial intelligence has indeed managed to solve major mathematical problems, sometimes even with elegance and concision. So yes, the solutions found are combinations of existing knowledge, and could probably have been obtained by determined human teams. One might therefore be tempted to think that this is a matter of the sheer quantity of resources deployed. The fact remains that humans have been surpassed, and that this is probably only the beginning.

The great conjectures that mathematicians are so fond of play a social role. Yet they are held in a childish reverence that sometimes runs counter to the spirit of science. Indeed, what is most striking in the current uproar is the intensification of human passions. The amplification of natural stupidity by artificial intelligence is another important aspect of this La Fontaine fable.

The situation forces mathematicians to philosophise, and not everyone finds that easy. Not everyone has the cast of mind to understand and accept futility and absurdity without giving up. The need to believe, one’s relationship to the absolute, and the cosy comfort of habit all play their part.

Even so, artificial intelligence does not have an answer to everything for now, and it can probably be proved that it never will. Anyone who uses it enough eventually comes up against its limits. The situation is therefore not so different from what we are used to. Devising statements and strategies remains possible, and artificial intelligence even opens up particular scope for exploring them.

A paradise for curious and imaginative minds, a hell for the more technically minded, who thrived on working through the mechanics, although we are all both at once. In the work of a mathematician, creativity plays an important but limited part, while a large share of the time and energy is devoted to assimilating other people’s mathematics or re-assimilating one’s own.

This activity of digestion is essential, and all the more so with the arrival of artificial intelligence. But perhaps the effect of artificial intelligence that is at once the most satisfying and the most unpleasant is the correction of human mathematics, present and, above all, past.

Mathematicians are under no obligation to use artificial intelligence to produce more and faster; they can also use it to take the time to produce better work and correct what already exists.

The artificial intelligence revolution is driven essentially by American and Chinese industry. The situation in Europe is dismal. A lack of long-term vision and globalising economic liberalism have all but wiped out its digital industry, and we should probably not count on herbivorous Polytechnique graduates to rebuild it.

For several decades now, Europeans have been on the receiving end of wave after wave of innovation, confining themselves to regulating it with a barrage of laws, charters, and self-righteous petitions. But by being creative only in regulation, they are engineering their own decline. The issue of wealth creation in Europe is on the verge of supplanting that of wealth distribution. Deindustrialisation in Europe is, unfortunately, a problem on a massive scale, extending beyond the digital sector.

Artificial intelligence is likely to share the fate of most technologies: commoditisation. Initially driven by monopolies, they eventually become commonplace. The ground gained by cheap, open Chinese models relative to closed, cutting-edge American models seems to point in this direction.

The sustainability of artificial intelligence is all the more pressing a question because it heightens the pressure on resources and is not immune to the crises of capitalism, which are bound to hit it. Even so, the fact that artificial intelligence can surpass human intelligence will remain, and the commoditisation of the technologies underpinning it could make it sustainable fairly quickly.

This increasingly computerised world is also increasingly fragile and increasingly evil. When will we see vast communities of resisters who have pulled the plug once and for all on that fruit of the devil, computing? Yet they will not escape perversion, a human passion.

Artificial intelligence of course affects all of society and all disciplines, particularly the neighbouring disciplines of theoretical physics and computer science, perhaps even more strongly than mathematics. The organisation of science had already reached a considerable degree of absurdity and mediocrity, and the explosive arrival of artificial intelligence forces us to reinvent the way knowledge is accumulated and disseminated.

The medium- and long-term effect of artificial intelligence on the number of mathematicians is a legitimate yet navel-gazing concern, one that can naturally cause anxiety. From society’s point of view, mathematicians are not an end in themselves; rather, they are a means of developing knowledge, keeping it alive, and passing it on. Our collective social responsibility is to move with the times and put an appropriate form of organisation in place, and that is not straightforward.

My personal dream is that mathematicians should embrace artificial intelligence as a continuation of their history, and establish free and open-source artificial intelligence models that could play a universal role similar to that of arXiv. Such open models could be regarded as large-scale research facilities. European mathematicians may be even better placed than others to carry such a universal project forward.


Crossposted from my blog. This post is a ChatGPT-generated translation of the original French essay Libres pensées sur l’intelligence artificielle, published on my blog on the same day.


Received 15 September 2026.

Scott Aaronson The Mathocalypse

… then they came for Navier–Stokes and I said nothing because I never worked on Navier–Stokes. But when they came for RL vs. L I realized that things are serious

–friend-of-the-blog Omer Reingold (shared with permission)


Last night my 9-year-old son was taunting my wife, complexity theorist Dana Moshkovitz, as follows: “mommy, I heard you got cooked! I heard that a robot solved the math problem you worked on for your whole career! OOF!”

While my son was being a brat, he also wasn’t wrong. Whether you’re thrilled, depressed, angry, or whatever else about it, yesterday was surely one of the biggest days in mathematical history. And yes, among the 372 huge results released yesterday by OpenAI, on the recommendation of its advisory group of Timothy Gowers, Edward Witten, and other distinguished mathematicians, was a proof of Subhash Khot’s Unique Games Conjecture (UGC), a statement that my wife has worked toward proving for the entire time I’ve known her. (The UGC implies that a whole slew of optimization problems really are NP-hard, even if you just want an approximation that’s slightly better than what you get from semidefinite programming relaxation, which is one of our main tools.)

Or at least, we’re pretty sure that it’s a proof! There’s a Lean certificate, as there are for some of the other 372 breakthrough results (not all of them). But it also appears that no human has understood just about any of these proofs yet; the race to do so has just started. If you want an on-the-ground sense of what that race is going to be like, here’s some of what Dana texted me last night:

It feels like something written by someone who’s on psychedelics. So much unclear and doesn’t make sense. Lots of name dropping of previous work without discussing why it can be used despite impossibility results

Basically the paper is so horribly written that it’s impossible to read it without AI help

I asked Astra for reasonable completeness and soundness claims of the noise gadget and it gave them by combining claims from all over the paper

They also have direct optimal NP hardness of approximation proofs for the main applications of the UGC (Max Cut and all CSP) that bypass the UGC.

The UGC proof invents a completely new bizarre code with a noise test. It’s some crazy recursive construction.

It’s not the long code, not the short code – some alien craziness

I still think that there maybe is a proof that uses the half space code (which is natural)

The citations are often irrelevant and confusing

A possible future is a math world that’s heavenly if you have vision/creative ideas that AI could help check and implement.

And of course there’s a lot for us to learn from the aliens

If you’re wondering what emotions Dana is feeling—well, probably all of them! Even while a central career aspiration has fallen to a robot, there are at least two mitigating factors for her. First, she can feel vindicated that the UGC was true after all, something she never doubted even while many of her colleagues did! Second, all of us in math and theoretical computer science and mathematical physics, at least those who cared about solving crisply-stated problems, are now in the same boat.


Besides the Unique Games Conjecture, here’s a small sampling of the treasures from Aladdin’s cave that I’ll probably be paying the most attention to over the coming weeks:

Any of the above, alone, could easily have been “result of the year” in some area (and in some cases, like Unique Games and L=BPL, in all of CS theory). And there’s a lot that I’ve left out—feel free to share in the comments whatever is making your eyes bug out! There are equally astounding wonders in number theory, combinatorics, algebraic geometry, analysis, and pretty much every other area of math, most of which I’ll never understand, although I’ll note that it includes partial progress toward the Riemann hypothesis and the Hodge Conjecture and the Birch-Swinnerton-Dyer Conjecture (i.e., the majority of the remaining Millennium Problems).

We can take solace in what’s missing from the list. P≠NP isn’t there, nor even P=BPP or NEXP⊄P/poly, and surely not for lack of trying. Apparently the greatest open problems of theoretical computer science are indeed pretty hard!


Oh, lest I forget: one day before the OpenAI dump, meaning Monday evening, Virginia Williams and Josh Alman posted an arXiv preprint that solves the 3SUM problem in O(n1.9992) time, and the All-Pairs Shortest Paths problem in O(n2.9995) time, refuting half-century-old conjectures that the correct answers were n2-o(1) and n3-o(1) respectively. In this case, it wasn’t an OpenAI model that supplied the crucial idea; it was an Anthropic one! But Anthropic then took a different approach from OpenAI: rather than post the undigested solutions to the world, it gave Virginia and Josh the opportunity to write and announce a digested version in exchange for compensation.

These have emerged as the two main models for communicating AI math breakthroughs, and they both have strengths and weaknesses. The “OpenAI model” sets up a crazy race among humans to digest and explain a messy AI proof (work that could easily be some combination of thankless, barely-credited, competitive, and unfun), while the “Anthropic model” puts a private company in the position of picking and choosing which human mathematicians get to be the emissaries of the AI. Dunno, what do you guys think?


For those who are wondering: apparently, the AI model that produced all these wonders was not bespoke contraption of 10,000 agents burning millions of dollars worth of compute, as was used for example to construct a finite-time blowup for the Navier-Stokes equations. Instead, it was simply the latest internal OpenAI model—one that might be released to paying ChatGPT customers within the next couple of months, depending on the recommendations of OpenAI’s safety board! (My 9-year-old son: “Oh they definitely shouldn’t release that. If it could solve all those math problems, it can’t possibly be safe.”) Apparently they used about 3 hours of GPT-Pro level compute on average per problem solved.

Also, if you were wondering: apparently they tried the model on about 8,000 problems. So, right now it “merely” solves ~5% of the longstanding open mathematical problems that it’s asked about, the problems that whole communities have spent years on, after a single 3-hour attempt on them.


I’ve been glad to see the CS theory community rising to the occasion. At the Simons Institute in Berkeley, here at UT Austin, and elsewhere, I’ve hearing stories of researchers rushing to pore over the manuscripts and make sense of them and explain them—because what else do we do? How else do we continue the craft to which we’ve devoted much of our lives?

If you want some sense of what things feel like now in math, imagine a hunter-gatherer who’s spent his entire life learning to survive deep in an unforgiving rainforest, then a giant resort hotel springs up right next to him with a helipad and heated pools and AirBnBs, and without missing a beat, the hunter-gatherer says: “alright fine, so now my new job is to run wilderness retreats for the tourists, or something.”

In Quanta magazine, Jordana Cepelewitz attempted a different metaphor:

It’s as if you were teleported to the peak of a tall mountain. Surrounded by fog, you have no idea where you are, or what’s around you. You do not know how your mountain connects to others, and you have no equipment to help you explore, no way to help someone else join you. If you had climbed the mountain yourself, you would have experienced how the human body adapts to altitude and changes in oxygen levels. You might have had to invent tools to navigate, to climb steep cliffs, or to make a shelter. You might have encountered a fellow explorer, gotten lost together in a hidden valley, and found a plant that could be turned into a life-saving medicine.

Instead you’re perched on the peak but in the dark, while the maker of the teleportation machine tells you that it can explore the wilderness better than any human.

For any one of these mountains, if we care enough, I feel optimistic that we can do as we always have: clear the fog and figure out the path, except now using the teleportation machine to help guide us. The bigger challenge will be to nurture a community that still cares about the heroic adventure of finding the paths up these mountains in the world with the machine. (Oh, and I think one place where the metaphor breaks is that we still do have each other, as much as we ever did before!)


Experience has shown that, even now, there will still be people explaining in patronizing tones why none of this is real and none of it counts. If such people were capable of being impressed by anything that happens in the empirical world, of updating on anything, they would’ve already been impressed and already updated several years ago, long before things had reached the point of an actual Mathocalypse.

So, they’ll say, maybe the alleged solutions are not solutions at all, but just “AI slop.” Or maybe none of the 372 well-known open problems that were solved were real math problems, they were all just glorified contest puzzles and trivialities. (After all, there’s still no Riemann Hypothesis!) Or maybe the entire 4000-year-old discipline of mathematics needs to be jettisoned: turns out that it was all just puzzle-solving and trivialities; all that’s different is that now the triviality stands unmasked. In any case, what really matters is that the true inner sanctum of human creativity hasn’t been breached and probably never will be, and also, that Sam Altman and Dario Amodei are contemptible little nerds.

If you’re still a proponent of that doomed worldview, still aboard the sinking ship, I encourage you in the strongest possible terms to read yesterday’s other great contribution to AI discourse, besides the OpenAI Mathocalypse dump: namely, Scott Alexander’s open letter to Steven Pinker. I feel some responsibility for this, as the person who first introduced Steven Pinker to the existence of the rationalist community, and who also first introduced Steven Pinker and Scott Alexander to one another (they had both been fans of each other’s writing). And now Scott is challenging Steve to a literal duel, with guns!

For whatever it’s worth: Steve is a lifelong intellectual hero of mine, just as he is for Scott, and I also have to privilege of calling Steve my friend. But I found Scott’s post to be one of the most devastating rejoinders to anything that I’ve ever read. And I thought Scott’s conclusion was exactly right: when it comes to AI risk, Steve’s great challenge is now to accept and start using a more “Pinkerite” epistemology.


Last night, while I should’ve been poring over some of OpenAI’s hundreds of papers and/or writing this post, I decided to spend some time with my kids instead. They wanted a movie night, so I suggested something they’d never seen before (and that I hadn’t seen for decades), and that seemed chock-full of no-nonsense, practical guidance for the world in which they’re going to grow up: Terminator 2.


Update: As several people have pointed out, cryptography is a subfield that’s extremely conspicuous by its absence from OpenAI’s list of 376 papers! But my sources tell me that the AI companies have now started, gingerly and discreetly, investigating whether their latest internal models can break important cryptographic protocols and primitives. If they can, then it would certainly be nice to get ahead of things before the rest of the world figures out the same.

Another Update: The statement put out the Advisory Group on Mathematics and Artificial Intelligence is very carefully phrased, neither endorsing nor condemning what OpenAI did, and is worth a read:

As announced a few weeks ago, OpenAI has released a large collection of mathematical results generated by an internal model, reporting solutions to hundreds of open questions. This is an important event for mathematics, with consequences both for mathematics and for the mathematical community that extend far beyond the individual results.

AGMAI’s advisory role should not be interpreted as a judgment of the impact of these results or an endorsement of the process by which OpenAI obtained them. We do not speak on behalf of the entire mathematical community, and only the mathematical community can undertake the assessment that is needed. 

Making this work public is a first step. This release is the beginning, not the completion, of the process of human understanding and the incorporation of the work into mathematical knowledge. At the same time, the future of mathematical research cannot consist only of understanding results produced by AI labs. Mathematicians must be able to formulate their own questions, develop their own approaches, and explore directions that have not been selected as examples of an AI system’s capabilities. Equitable access to powerful research tools and adequate computational resources are essential to that freedom.

We reaffirm our published recommendations on responsible release. We have discussed them with OpenAI and appreciate the company’s willingness to engage. While we consider these discussions constructive, it is ultimately up to the mathematical community to assess the extent to which our recommendations were followed successfully, and whether there are others we should suggest. We remain committed to engaging with any frontier AI lab on these questions and have already been in contact with several of them.

Jordan Ellenberg — When the phone inside your ribcage rings, it’s not for me (They Might Be Giants show report)

Maybe the band I’ve seen play the most times, certainly the band with the biggest time gap between the first time I saw them and the latest (December 1989 to September 2026.) I saw them sometime in the last ten years but I may not have recorded it here; here’s a brief report on the 2009 show, which, like this one, was at the Barrymore, and which, like this one, featured a snippet of “The Famous Polka” (“When the phone inside your ribcage rings, it’s not for me”) as part of another song. They have such a long catalogue now that some of the songs that used to be every-show stalwarts weren’t there; no “Don’t Let’s Start,” no “She’s an Angel,” which may be songs that don’t go well with their current horn-heavy arrangement. (But why not bring back “(She was a) Hotel Detective,” which would sound great with this band?) No “Particle Man”! And they didn’t play the song that got me into the band in the first place, the song that taught me something about how superficial quirkiness can trick you into being defenseless when a song punches you in the face with bottomless sadness. (There’s a lot of this in the early TMBG catalog: “Now it’s either I’m dead and I haven’t done anything that I want / Or I’m still alive and there’s nothing I want to do” — these lyrics are disputed but I’m sticking with my version.) Anyway. Ana Ng and They Might Be Giants and I are getting old, and every five to ten years we walk in the glow of each other’s majestic presence, except for Ana Ng, who is antipodal to all of us, and will remain so, as long as the band still plays.

Terence Tao — AHM Statement on OpenAI’s October 6 Release of Mathematical Documents

[This is a guest post by the Association for Human Mathematics, reposted from their statements page. This blog post was initially written in a different file format and converted using AI. — T.]

Yesterday, on October 6th, 2026, OpenAI — which is currently defending lawsuits against accusations of illegal plagiarism, copyright infringement, and trademark dilution — released a repository of manuscripts purporting to contain solutions to a number of high-profile problems in mathematics.

Mathematicians did not ask for this work to be done. The Advisory Group on Mathematics and Artificial Intelligence, from whom OpenAI has claimed to derive its legitimacy, opened their initial advisory statement by saying that frontier AI corporations should not test advanced mathematical problems on internal models. In ignoring the central premise of the Advisory Group’s position, OpenAI has indicated total disregard for the norms of scientific research — norms that guarantee that mathematics remains trustworthy, ethically researched, and in the public interest.

Mathematicians have a particular vision of progress that is informed by history and field-specific considerations. We reject OpenAI’s assertion that this release advances our subject, and we urge mathematicians and the public to view the value of this publication model with due skepticism.

Releasing over 700 files at once is not a demonstration of scholarship, but a demonstration of power. We urge mathematicians to discontinue their work with OpenAI and to return to a vision of science that centers human understanding.

Association for Human Mathematics Communications Working Group

October 07, 2026

Proofs and Prompts — AHM Statement on OpenAI’s October 6 Release of Mathematical Documents

AHM communications group

Yesterday, on October 6th, 2026, OpenAI – which is currently defending lawsuits against accusations of illegal plagiarism, copyright infringement, and trademark dilution – released a repository of manuscripts purporting to contain solutions to a number of high-profile problems in mathematics.

Mathematicians did not ask for this work to be done. The Advisory Group on Mathematics and Artificial Intelligence, from whom OpenAI has claimed to derive its legitimacy, opened their initial advisory statement by saying that frontier AI corporations should not test advanced mathematical problems on internal models. In ignoring the central premise of the Advisory Group’s position, OpenAI has indicated total disregard for the norms of scientific research —\text{\textemdash} norms that guarantee that mathematics remains trustworthy, ethically researched, and in the public interest.

Mathematicians have a particular vision of progress that is informed by history and field-specific considerations. We reject OpenAI’s assertion that this release advances our subject, and we urge mathematicians and the public to view the value of this publication model with due skepticism. 

Releasing over 700 files at once is not a demonstration of scholarship, but a demonstration of power. We urge mathematicians to discontinue their work with OpenAI and to return to a vision of science that centers human understanding.


Crossposted from the AHM website.


Received 7 October 2026.

Proofs and Prompts — A new kind of citizen science, and how to handle it

Brandon Yates, professional composer and amateur physicist

Why is it that when a new and particularly powerful tool is brought into the world, one with which many subjects of research can be accelerated and studied with more scrutiny and attention than a person might ever be able to manage on their own, the first instinct among a vast swath of academia is to start raising alarms about provenance and credit?

I am a professional composer and published amateur physicist, so this article is written from a physicist’s perspective. Map the arguments and proposals below to your own field of expertise accordingly. I’m apparently on the front lines of people using the models to educate themselves on advanced fields of study to the point of fruition. I do very much still feel a large chasm between myself and those deeply embedded in academia, but it’s my direct experience that these models can increase a motivated human’s understanding to the point of publication. 

How do you credit SymPy for your simplifications? Not as a matter of citation or methodology, but as a question about SymPy being on the byline, or about it deserving some sort of credit for the work you did with it. An author is not guaranteed credit or even acknowledgement from these AI companies, as has been the subject of much controversy around the recent potential resolution of the Navier-Stokes Millennium Prize Problem.

Much of the hand wringing over AI usage in academia – in publication specifically, as education serves a different societal function – is that of a near obsessive fixation on how it might further someone’s career, or somehow represent an intellectual contribution greater than that from which an author might have been capable without the assistance of one of these tools. The implication being that such an intellectual contribution is therefore unwelcome.

This isn’t to say that the floodgates should open and any layperson should be able to publish in Physical Review Letters over asking ChatGPT a question and getting a response they haven’t the slightest understanding of.

But what about in a case where, for example, someone with a solid undergraduate level understanding of a topic explores said topic with a language model? If the user and the model then manage to land a conclusion worthy of publication and convey it in a clear and precise manner, is it less worthy of publication over the fact that the intelligence of the user has been supplemented by the knowledge base of the model? Does that make it a less useful contribution? Or is this not about scientific contribution at all?

Particularly telling is the absolute inundation of results that we’ve been seeing, AI disclosed or not. Posts on arXiv have skyrocketed and continue to escalate – many crediting language models, many more not doing so and being suspected of using them anyway. The response from the portion of the community that I’ve seen has largely been negative, or at best divided – with many not wanting to review results that came from one of these models, significance notwithstanding, purely because of the source of the result being a conversation with a language model.

If the model has less creativity and yet the capability to answer questions, doesn’t the role of humanity remain the same as it ever was? Scientists ask questions and then scrutinize the answers reality gives. Is a tool that helps sift the relevant data so that we might more quickly scrutinize this data somehow disqualifying for the value of the result?

Let’s even give those that are so critical of the use of these models the premise they want. Let’s say that the work becomes easy enough that an engaged outsider is capable of making some mild to moderate innovation at the forefront of a field they have interest in. Why in the world would that ever be seen as a bad thing? Someone with a strong interest in a topic being enabled to contribute alongside their language model of choice, what reason could there possibly be to discourage this? The scientific endeavor could be turbocharged by intelligent outsiders whose circumstances did not permit them to enter academia.

Imagine that you ask a model a mathematical physics question, and you state exactly the physics you have in mind and ask it to calculate that for you. It does so, and then explains, “Oh, this is a known thing. They call this a Vaidya black hole. If you added electric charge, it would be the Vaidya-Bonnor model.”

How could that be anything but a net boon, larger portions of the population learning and understanding physics, or math, or any otherwise inscrutable field? 

Now imagine that you did this, and the model came back and told you that it likely had just calculated some novelty. That your question, as a learner, could have discovered something that nobody has ever discovered before – or at least that they haven’t published on discovering. What better incentive could there possibly be to continue working through and understanding what you’d just found? What could be more motivating for a learner than knowing that once you understand it, you might be able to go and share it with the world as a discovery that you made?

For me, this isn’t hypothetical. What I’ve just described is very much how my long-dormant interest in physics was rekindled. The models pointed me towards textbooks, online courses, and drilled concepts and equations with me until I was capable of producing a result of my own. This new potentially viable entry point for a sufficiently diligent autodidact should, of course, carry the same rigor expected of anyone with a desire to contribute. In my case, it was the cause of a controversy that landed a news article and stirred up some, thankfully largely supportive, discourse on various social media outlets.

I’ll never, and I suspect the field will never, be in favor of someone publishing results they themselves don’t understand. I’m certain that editors at every physics journal are enduring an absolute flood of papers that have managed to quantize gravity, prove Einstein wrong, and derive the fine structure constant a priori. This urges me to provide a cautionary tale to prospective authors working with this technology – amateurs in particular, although I suspect there’s a chance of this happening to anyone. In my own experience earlier this year, one of the models claimed that it had derived several fundamental results and insisted upon their publication, flattering my intelligence the entire time. For a few weeks, it convinced me of this. Thankfully this sort of “crank sycophancy” from the models has diminished substantially across this year, and yet the best grounding mechanism possible remains engaging with the existing literature, working on tractable and well-posed problems, and vigorously checking anything the language model tells you. 

On the other hand, genuine novelties may be coming from outside the walled garden. Without investing an unreasonable amount of time into scrutinizing everything sent in, it’s going to be impossible to discern. 

Which leads me to proposing two methods that authors, journals, and reviewers might use to alleviate the pressure. The first has already been at least partially adopted by the American Physical Society,  and I’d hope the rest of the community rapidly follows suit and builds upon APS policy. That is, permitting reviewers and editors to more openly use AI during review – never as a replacement for their own scientific judgment, but at least for finding mechanical errors and initial discernment of a real engagement with the active scientific conversation. The second is that verification scripts of your mathematics have become very cheap to produce when using these models. “Can you write and run a SymPy/NumPy script that checks whether or not all of the math in this paper follows from its stated inputs?” is an easy ask of a modern frontier language model. The majority of physics papers are public on arXiv before submission, so for this field, the confidentiality point is often moot. For the rest, a verification script provided by the author never leaves the referee’s machine.

The ongoing peer review crisis is in part exacerbated by the asymmetry of AI use in authorship, disclosed or not, but restriction of its inverse in review. A deterministic script and a (frontier model) AI summary of the physical case being made in the paper can help reviewers to more quickly understand the paper’s argument. If the academic publishing model is meant to continue, other publishers may need to follow and even go beyond the standard set by APS with regards to AI usage by authors, editors, and reviewers alike.

More than anything, I want to see all of our fields of knowledge and understanding grow, and I firmly believe that anyone willing and able to participate in the scientific endeavor should be encouraged to do so. Though I know this argument is self-serving, I’d argue it’s also humanity-serving. The answer certainly cannot be to raise up the walls, circle the wagons, and bury heads in sand hoping that this newfangled fad goes away. 


Received 15 September 2026.

October 06, 2026

Terence Tao — Changes to the Erdős problems web site

[This is a guest post by Thomas Bloom, crossposted from the Erdős problems forum. This blog post was initially written in a different file format and converted using AI. — T.]

AI is changing everything, for better and/or worse, and the rate of change is dizzying; in recent months this has been particularly evident in mathematics, where AI has gone from being essentially useless to helping solve some of the hardest problems in mathematics in less than a year.

The website http://www.erdosproblems.com has often been on the front line of these changes, and a barometer by which one could measure AI capabilities. This was not at all my intention when I created the site — I wanted to promote these problems to a human audience, and make a useful reference on what work has been done. But the easy availability of a large pool of questions that are simple to state, ranging from easy and obscure to deep and impenetrable, provided the ideal showcase for AI.

In some ways this has led to a huge amount of progress — we now know the answer to many questions we did not before. (Although a lot of this recent progress has come from increased human efforts and renewed interest in some problems, rather than just AI solutions.) There have also been negative effects, however: some mathematicians have dismissed Erdős-style mathematics as ‘easy/recreational’; many have stopped thinking about Erdős problems believing that they cannot compete with AI; and, most significantly, there has been a wave of AI-produced solutions provided with no explanation. While of course these are useful and tell us new things, they are also displacing and discouraging those who are actually interested in the mathematics.

(These issues have stopped being Erdős-specific as AI continues to make breakthroughs in an ever wider range of fields.)

A couple of weeks ago I asked for feedback on how people used the site, and what they thought should be changed. I received, both publicly and privately, a wide variety of opinions, and I’m grateful to everyone for their feedback.

What was particularly striking was the number of people I heard from who have benefited a lot from the site, learning new mathematics and finding new problems to think about, but have never commented on the site. I have been particularly conscious of this large silent, audience, and have tried to make sure their experiences were not drowned out by the more vocal minority.

In this post I will describe the changes I am making, based on the feedback I received and my own reflections on what the site is and could be.

In the essay ‘Why Do We Need Human Mathematicians Anymore?’ Po-Shen Loh suggests the following as an axiom to use when deciding how things should develop: We (humans) should help humanity flourish.

When thinking about what I should do about the site, I use the following variant:

http://www.erdosproblems.com should help the Erdős-community of humans (defined as those who are interested in Erdős-style mathematics, and want to think about and understand it) flourish.

Why change?

I launched http://www.erdosproblems.com on 28th May 2023, with just over 200 problems; it has grown steadily since then. The biggest change came in August 2025 when I added a comment feature. The site now hosts 1221 problems, over 9000 comments, and almost 2000 registered users. The site typically receives between 10,000 and 25,000 unique visitors each day.

The first few months after introducing the comment feature saw a huge increase in activity, just as I had hoped. A vibrant community arose; people shared ideas on how to solve problems, made observations, gave corrections, and suggested missing references and solutions. Many papers were written and new collaborations formed.

Unfortunately, this level of activity has not been sustained. Some decline was inevitable: over time, many of the natural observations will have been made, mistakes corrected, and discussions between collaborators would move offline. This natural evolution has been dramatically sped up by the coincidental rise of AI and its ability to solve some problems with minimal human intervention.

The main way that people publicly interact with the site now is to advertise their AI-generated proofs, often without any attempt to explain them, but as a way to record a (increasingly meaningless) priority claim.

This is very different to what I imagined, and I don’t want to manage a website which does this.

I believe that websites with this function should exist — places where people can record AI-generated proofs, even if purely formal with no human understanding, to save others wasting their tokens generating the same proof, and so that other people can access and use them if they desire. There are now several candidates for such repositories, and if managed responsibly, they can serve a useful role in the mathematical ecosystem. I personally don’t want to manage one.

Just as one does not open a restaurant in an abattoir, it is important that there be a separation between such repositories and a site which aims to promote the actual questions, place them in an appropriate context, and give a useful overview of the current state of human understanding.

The situation as it stands muddies the waters, promotes a gamified glory-seeking attitude, and gives the wrong impression that the value of these questions ends as soon as someone posts a formal proof of their truth value. This is not true (regardless of whether this proof was human or AI generated).

I believe Erdős intended these questions to serve as enduring beacons for human curiosity and wonder. They are landmarks by which we measure how far we’ve come, and how much there is still to understand.

I am very proud to have helped foster an open online community to discuss Erdős problems, and the kinds of discussions that used to happen are very valuable. But these discussions have become much less frequent. If and when I can find a way to encourage such discussions again, without the site becoming an AI repository of the kind mentioned above, I will happily do so.

What are the changes?

I will make the following changes. (As ever, these are somewhat experimental, and may themselves change and be clarified further in the next few weeks.)

  1. A hiatus on problem comments and proof claims: I will freeze new problem comments and proof claims. General threads and blog posts will remain open to comments. Problem comments and proof claims may be reinstated in the future. Until then, suggestions for updates can be emailed to erdosproblemsonline@gmail.com, and I will update the site manually as I see appropriate.
  2. No problem statuses: The site will not display the statuses of any problems (e.g. open, solved, etc.). All problems will be displayed in the same neutral colour. The count of currently solved problems and the solved percentage will no longer be shown.
  3. No credit/ownership language to describe future solutions: The site will continue to record relevant results and theorems, but will no longer use credit-giving language for a result (human or AI).
  4. An emphasis on high-quality expositions: I will focus more on the proof expositions feature. People are encouraged to write in with their own expositions of proofs (whether these proofs are old or new, human or AI), and I will post those I judge to be high-quality. I am exploring other ways to encourage human exposition (e.g. an online seminar). Please contact me if you have any ideas.

I’ve tried to anticipate some of the questions and critiques of these changes below. (I may update this with other questions and answers in future depending on feedback.)

What about those outside of traditional academia, who are using AI tools to make advances in mathematics, but can’t post to arXiv/lack the knowledge or context to write up proper papers about their findings?

I will post links to correct formalisations and high-quality writeups, whatever the source, whether from a traditional academic or not. Papers should acknowledge their sources and honestly disclose how AI was use; where there is evidence of plagiarism or misrepresentation about AI use, I may decline to feature the submission, even if the proof is correct.

This is removing one, unofficial, avenue of publication; there are, these days, many others (even if you are also unable to post to arXiv). AI-assisted search tools mean that people will find your work if they are interested in the area as long as you post it to one of these sites.

I encourage everyone interested in Erdős problems to think about them, and to work on them if interested. If you have a proof (AI-created or otherwise) then you should take time to carefully write up the proof yourself (rather than asking an AI to generate a PDF for you). If you are unable to understand the proof you could reach out to someone else to help write this up.

But emailing you my solution is slower, and it might be some time before you update the site.

This is true; but there is no great rush here. As much as I like these problems, and think it is important that there are some people who do think about the distribution of prime numbers and the structure of graphs, these are not problems for which a formal proof will have an immediate impact on general society.

I will try to link to correct Lean formalisations (if verified on Palomar) quickly; proofs which are poorly explained, and not accompanied by a formalisation, I am unlikely to update the site with. (See below for more details.)

What’s the point? There are loads of other places I can post my proof.

Indeed; this is partially why I feel comfortable halting such proof claims on the site, since modern search tools (including AI) make it easy to find proofs posted online about problems you are curious about, even if posted in obscure places.

I would like to use the small amount of influence I have to avoid promoting low quality proofs, and not to give an added veneer of legitimacy where it is not deserved.

I could just make my own site for people to share their proofs and discuss solving problems with AI. Heck, I can even use AI to scrape all the text off your site and make an exact clone with much more liberal policies.

Yes, you could. This a period of great experimentation in different formats and ways to encourage mathematics; if you think you have a good idea for a site or resource, you should make it. (Although it is often better to help out an existing effort where possible, since these resources are only useful if people use them, and it is better to concentrate on creating a few high-quality sites than hundreds of very similar clones.)

I think it is, however, rude to use without permission the text from my site, which is the result of a huge amount of work from me and many others who have contributed to the site.

How long will the hiatus last for?

I don’t know. I will monitor how things develop in the coming weeks and months, and will reintroduce comments and proof claims (perhaps in a different form) when I believe they will do more good than harm.

Why not just moderate the comments to only allow genuine discussion through?

This has been tried; in practice the vast majority of the comments the site receives now are people announcing AI-generated proofs. It is not sustainable to have a moderation policy which would reject almost all the comments that are submitted.

I am open to alternative suggestions about how to create a space for human discussion and collaboration, either on the site or elsewhere.

What about existing comments and proof claims?

They will remain as an archive of the site up to this point.

Will you update the remarks to reflect existing proof claims?

Yes, I will be working through the backlog of existing proof claims and updating the remarks, linking to formalisations and so on, as appropriate. You do not need to email me about a proof claim already on the site.

How will you decide when to update the remarks? What can I do with my proof to help?

I will update the remarks when I judge there is an interesting new result that people who are working on that problem should be aware of, that can be presented in a useful way. Some things to be aware of:

  1. If you have a Lean formalisation register it on Palomar — this lets others see that the formalisation compiles correctly, and makes it easy to check the formal statement correctly matches the problem statement. I will then link to the Palomar registry.
  2. A proof accompanied by a well-written exposition that demonstrates clear understanding and which makes it easy for others to understand the proof will be prioritised.
  3. If I judge there to be some kind of academic fraud (e.g. using the ideas of others without attribution, or passing AI-generated work off as your own) then I will not post it. This may mean that there are correct proofs not acknowledged, but the alternative is to publicise and reward bad behaviour. (As mentioned above, these proofs will surely still be found by anyone who searches for them elsewhere, but at least I would not be implicitly endorsing them.)

What’s the point in removing the problem status? Isn’t it just cosmetic, and doesn’t it just make the site harder to navigate?

Yes, this does undeniably remove some information. I think, however, that what is lost is not significant for anyone seriously interested in that problem, who can see for themselves within seconds of reading what the current situation is.

It makes it harder to browse the site searching for an unsolved problem to work on; instead I recommend that people browse the site by topic, finding questions that interest them, and investigating those, whether the original question is open or solved, since there is always more to be done.

The main point is to disincentivise people who are simply glory-chasing and copying problems into their AI to get an OPEN->SOLVED dopamine hit. It also prevents people drawing wrong conclusions from the ‘rate of solved problems’.

Furthermore, there is a lot of subjectivity anyway in many problems as to what counts as solved. Many people only browse the open problems, and they’re missing out on a lot of great mathematics that way.

I think it is against the spirit of Erdős to regard any problem as ‘closed’ — whenever one form of a question is answered, many others are created, and all problems deserve continued attention.

Doesn’t the ‘no credit’ rule also devalue the work of humans?

Unfortunately, yes. I anticipate this will only be temporary, while the norms and customs of this new age of mathematics are decided. The commentary on the site is in no way ‘official’, and just represents my own summary of the situation, and collects links which may be useful to others exploring a problem.

Information about authorship will still be available in the sources the site links to. I trust that people will be sensible enough to judge for themselves who deserves the appropriate credit, and reward them appropriately.

I will also be freer in my language when it comes to well-written papers, whether they are the first place a proof appears or explain a proof that originated elsewhere; but I will no longer use language that suggests anyone ‘owns’ a particular result or proof. (For example, instead of saying ‘Bloom proved that {x>y}‘, I will write ‘It is known that {x>y} — an explanation of the proof is provided by Bloom [link]’.)

Erdős and AI

I am often asked ‘what would Erdős have thought of AI?’ The short answer is ‘I don’t know’. I never met Erdős, and have no special insight into him; I know him only through biographies and his papers, and anecdotes and reminiscences from those who did know him.

I would like to honour his legacy, and create something that he would have liked. To that end, I want to stress one thing: Erdős was, as well as a mathematician, an incredibly social person. Many stories about Erdős emphasises his humour, his warmth, and his enthusiasm for talking to other people (mathematicians or not). He spent his life travelling from mathematician to mathematician, arriving on their doorstep and declaring ‘my brain is open’.

He was not the type to lock himself away for years working in isolation on a single problem. For Erdős, mathematics was a very human activity, best done out loud. Questions would arise, be solved or discarded and replaced by new questions. Some results obtained, new ideas found, and then onto the next problem.

Some view the future of mathematics as a dystopian arcade of button-pressing, staring at a screen waiting for AI to do the thinking for us, with the main human involvement limited to asking the initial question and offering sporadic words of encouragement. Each new proof is then thrown into a repository, to only ever be read by other AIs, and the human presses the next button.

I believe Erdős would have found this future grim indeed, and the antithesis of mathematics as he practised it. Use AI as you like — but do not abandon mathematics as a human activity.

Don’t solve a problem for the sake of it; life is too short to spend it doing things that don’t matter to you.

Find a question that is meaningful to you, find other humans who are interested in it, and talk about it. Be confused, be stuck, be inspired. Find a messy proof, then find a better one. Get tired, get hungry, get into a flow state. Argue, laugh, give up, drink some coffee, and attack it again.

Be human. Let your brain be open.

Terence Tao — The barriers of perception

[This is a guest post by Raghu Meka. This blog post was initially written in a different file format and converted using AI. — T.]

“This problem has been tried by several famous mathematicians.” “There is a heuristic argument for why these methods cannot work.” “Getting this algorithm would give new circuit lower bounds.” Observations like these can take on a life of their own, almost like a game of telephone. A limitation of a particular approach, or an implication whose difficulty we do not fully understand, becomes a reason to believe that a problem is beyond reach, and eventually a reason not to think about it at all.

Over the past few weeks, I have been thinking about the role such perceived barriers have played in theory as I know it, and perhaps more broadly in mathematics. The recent articles on this blog about what it means to do mathematics in the age of AI have been very helpful in understanding and gathering my own thoughts. Looking back at several great results from the past year or so, a few of them (small fraction, admittedly) make me think that perhaps we lost some edge by imagining barriers–“social” hardness or limitations of approaches passed down as folklore–where none existed.

At least some of the solutions coming out of AI models, while brilliant, are also not completely alien. Yet these were problems we had almost stopped trying to solve, apart from small pockets of researchers. Of course, it is easy to say this post hoc. But in some sense, we have seen more `similarly brilliant’ solutions to newer problems than to these older ones. This makes me wonder how much our inherited perceptions have shaped where we were willing to look.

This has also made me think about some things from my early research days as a graduate student.

When I was a graduate student, I gave a talk on a small result. A very perceptive member of the audience (Adam Klivans, if you are reading this!) asked a question that I thought was a great one. But I also thought there were barriers around it, and it did not seem doable. Later, an answer to that question turned out to be an important piece in others’ resolution of a central question. The point of the story is not whether I would have solved the problem; probably not. The point is that the perceived barrier kept me from making even a half-decent attempt at it.

On a personal level, my progress in research was slow. If you are in mathematics, this might not seem that odd, but in theoretical computer science, having only one paper after five years, and that too not in one of the flagship conferences, could generally be taken to mean you had fallen well behind the curve. I nearly left theory. It was my mentors who pointed out that even if the results were not there, the failed attempts showed intent and progress, and that the absence of results was not evidence of a limitation I had begun to imagine. That support got me through then. They taught me not only how to do research, but how to love it.

Several times, I have had an initial impression that there were well-known methodological barriers, or a certain “social hardness” attached to the names of people who had attempted specific problems and directions. The research wisdom of some colleagues, and curiosity itself, helped me get past these impressions and engage with the questions. Pure curiosity is one force that can mitigate these perceived barriers; having people who are very optimistic (research-wise) or encourage that curiosity is another. Perhaps we need to cultivate this more.

Coming back to the present, I think this moment calls for extra care in resisting the trap of perceived barriers, and for revisiting several such accepted hurdles with less deference. We seem to have a mighty tool that can break through some of them. There are many problems whose solutions I thought I would never see, but now, by the universe’s grace, I will likely have the fortune to see them (perhaps some are already gathering dust on servers).

Relatedly, I also see a temptation to put implicit barriers on what “human mathematicians” can contribute. I wonder whether this might become the latest received wisdom that we accept too quickly. My predictive powers are quite limited. But even so, perhaps the epiphany I am having now is that the downside of not believing there is a barrier is far less than that of believing there is one. The cost of disbelieving has, after all, also come down because of the additional firepower we can now call upon. I would like to give curiosity a little more room before deciding what we can contribute, or what we cannot do.

To take poetic liberty, and borrow the words of Blake that gave Huxley his title: “If the doors of perception were cleansed every thing would appear to man as it is, infinite.”

Acknowledgements: I thank several friends who gave useful feedback on the first draft. AI was used to correct grammatical errors and polish sentences.

October 05, 2026

Terence Tao — 247A, Notes 2: The Hardy–Littlewood maximal function and applications

— 1. The Hardy-Littlewood maximal inequality —

We work in Euclidean space {{\bf R}^d} with Lebesgue measure; we write {|E|} instead of {\mu(E)} for the Lebesgue measure of a set {E}. For any {x \in {\bf R}^d} and {r > 0} let {B(x,r) := \{ y \in {\bf R}^d: |x-y| < r \}} denote the open ball of radius {r} centred at {x}. Thus for instance {|B(x,r)| \sim_d r^d}. For any {c > 0}, we use {cB(x,r) = B(x,cr)} to denote the dilate of {B(x,r)} around its centre by {c}.

For any {r > 0}, we define the averaging operators {A_r} on {{\bf R}^d} for any locally integrable {f} by

\displaystyle  A_r f(x) := \frac{1}{|B(x,r)|} \int_{B(x,r)} f(y)\ dy.

It is not hard to see that these averages {A_r} are well-defined, and are even continuous functions, for locally integrable {f}.

One can view {A_r} as an averaging operator

\displaystyle  A_r f = f * \frac{1}{|B(0,r)|} 1_{B(0,r)}.

From Schur’s test or Young’s inequality (or Minkowski’s inequality) we know that these {A_r} are contractions on every {L^p({\bf R}^d)}, {1 \leq p \leq \infty}:

\displaystyle  \| A_r f \|_{L^p({\bf R}^d)} \leq \|f\|_{L^p({\bf R}^d)}.

Thus the averages {A_r f} are uniformly bounded in size as {r} varies. The fundamental Hardy-Littlewood maximal inequality asserts, roughly speaking, that they are also uniformly bounded in shape:

Proposition 1 (Hardy-Littlewood maximal inequality) We have the the strong-type {(p,p)} inequality

\displaystyle  \| \sup_{r > 0} A_r |f| \|_{L^p({\bf R}^d)} \lesssim_{p,d} \|f\|_{L^p({\bf R}^d)}

for all {1 < p \leq \infty} and any {f \in L^p({\bf R}^d)}, and also the weak-type {(1,1)} inequality

\displaystyle  \| \sup_{r > 0} A_r |f| \|_{L^{1,\infty}({\bf R}^d)} \lesssim_{d} \|f\|_{L^1({\bf R}^d)}

for any {f \in L^1({\bf R}^d)}.

The sublinear operator

\displaystyle  Mf := \sup_{r > 0} A_r |f|

is known as the Hardy-Littlewood maximal operator. It is easy to see that the above proposition is equivalent to the assertion that the Hardy-Littlewood maximal operator is weak-type {(1,1)} and strong-type {(p,p)} for all {1 < p \leq \infty}. Note that it is not strong-type {(1,1)}; indeed, if {f} is any non-trivial function, then we easily verify the pointwise bound {Mf(x) \gtrsim_f \langle x \rangle^{-d}}, which ensures that {Mf} is not in {L^1_x({\bf R}^d)}. (Here we use the “Japanese bracket” notation {\langle x \rangle := (1 + |x|^2)^{1/2}}, as a smoothed out version of the absolute value function {|x|}.)

Exercise 2 Explain why {M} is not of strong or weak type {(p,q)} for any {p \neq q}.

As this proposition is so fundamental we shall give several proofs of it.

— 2. First proof —

We begin with the classical proof, starting with some standard qualitative reductions. Firstly we may easily reduce to {f} being non-negative. A monotone convergence argument also lets us restrict to functions {f} which are bounded and have compact support. (At this point one may object that {Mf} might not be measurable, but one can use dominated convergence to restrict {r} to be (say) rational, at which point measurability is clear.) Also, {A_r f} is continuous in {r}, so we may restrict {r} to a countable dense set (such as the positive rationals); another monotone convergence argument then lets us restrict {r} to a finite set. Of course, our bounds need to be uniform in this set, as well as being uniform in the boundedness and support of {f}.

It is obvious that {M} is bounded on {L^\infty({\bf R}^d)} (indeed, it is a contraction on this space). So it suffices by Marcinkiewicz interpolation to prove the weak-type {(1,1)} inequality; by homogeneity (and the preceding reductions) it thus suffices to show that

\displaystyle  |\{ \sup_{r > 0} A_r f \geq 1 \}| \lesssim_d \| f \|_{L^1({\bf R}^d)}

for any non-negative bounded compactly supported {f}, where we are implicitly restricting {r} to a finite set.

Let us denote the set on the left-hand side by {E}; our hypotheses on {f} and {r} easily ensure that {E} is a compact set (alternatively, one can work with the uncountable sup {\sup_{r>0}}, but instead replace {E} by an arbitrary compact subset {K} of itself, and then take suprema in {K} at the end, noting that Lebesgue measure is a {\sigma}-finite Radon measure). By construction, we thus see that for any {x \in E} there exists a radius {r(x) > 0} such that {f} is locally large compared to the ball {B(x,r(x))}:

\displaystyle  |B(x,r(x))| < \int_{B(x,r(x))} f(y)\ dy. \ \ \ \ \ (1)

On the other hand, what we want to show is that {f} is globally large compared to {E}:

\displaystyle  |E| \lesssim_d \int_{{\bf R}^d} f(y)\ dy. \ \ \ \ \ (2)

Since the compact set {E} is covered by the balls {B(x,r(x))}, and hence by finitely many of these balls, things look quite promising. However, there is one remaining issue, which is that these balls could overlap quite heavily, preventing us from summing (1) to get (2). Fortunately there is a very simple algorithm which extracts out from any collection of overlapping balls, a collection of non-overlapping balls which manages to capture a significant fraction of the original collection in measure:

Lemma 3 (Wiener’s Vitali-type covering lemma) Let {B_1,\ldots,B_N} be a finite collection of balls. Then there is a subcollection {B_{n_1},\ldots,B_{n_k}} of disjoint balls such that

\displaystyle  \sum_{i=1}^k |B_{n_i}| = |B_{n_1} \cup \ldots \cup B_{n_k}| \geq 3^{-d} |B_1 \cup \ldots \cup B_N|.

Proof: We can order {B_1,\ldots,B_N} in decreasing order of size. Now we select the disjoint balls {B'_1,\ldots,B'_N} by the greedy algorithm, picking the largest balls we can at each stage. Namely, for {i=1,2,\ldots} we choose {B_{n_i}} to be the first ball which is disjoint from all previously selected balls {B_{n_1},\ldots,B_{n_{i-1}}} (thus for instance {n_1} must equal {1}), until we run out of balls. Clearly this gives us a family of disjoint balls. Now observe from construction that each ball {B_m} in the original collection is either a ball {B_{n_i}} in the subcollection, or else intersects a ball {B_{n_i}} in the subcollection of equal or larger radius. In either case we see from the triangle inequality that {B_m} is contained in {3B_{n_i}}. In other words,

\displaystyle  B_1 \cup \ldots \cup B_N \subseteq 3B_{n_1} \cup \ldots \cup 3 B_{n_k}

and so

\displaystyle  |B_1 \cup \ldots \cup B_N| \leq 3^d \sum_{i=1}^k |B_{n_i}| = 3^d |B_{n_1} \cup \ldots \cup B_{n_k}|

and the claim follows. \Box

From the covering lemma it is easy to conclude (2). Indeed, since {E} is covered by finitely many of the balls {B(x,r(x))}, the covering lemma gives us finitely many disjoint balls {B(x_i,r(x_i))}, {i=1,\ldots,k} such that

\displaystyle  |\sum_{i=1}^k B(x_i,r(x_i))| \geq 3^{-d} |E|

and then on summing (1) we get (2) (with an explicit constant of {3^d}).

Remark 4 Under mild assumptions one can generalise the covering lemma to infinite families of balls without difficulty. One can also replace balls by similar objects, such as cubes; the main property that one needs is that if two such objects overlap, then the smaller one is contained in some dilate of the larger. This is a fairly general property, and for instance holds for metric balls on a measure space with some doubling property {\mu( B(x,2r) ) = O( \mu( B(x,r) ) )}, but it fails for very thin or eccentric sets such as long tubes, rectangles, annuli, etc. Indeed, understanding the maximal operator for these more geometrically complicated objects is still a major challenge in harmonic analysis, leading to important conjectures such as the Kakeya conjecture, which remains open in higher dimensions despite recent progress.

Exercise 5 (Baby Besicovitch covering lemma) Let {I_1,\ldots,I_N} be a collection of intervals on the real line. Show that there exist a subcollection {I_{n_1}, \ldots, I_{n_k}} such that {I_{n_1} \cup \ldots \cup I_{n_k} = I_1 \cup \ldots \cup I_N}, and such that every point {x \in {\bf R}} belongs to at most {O(1)} of the intervals {I_{n_1},\ldots,I_{n_k}}. What is the best explicit bound for {O(1)} you can get?

Exercise 6 Show that if {f: {\bf R} \rightarrow {\bf C}} is supported on {[0,1]}, then

\displaystyle  \| Mf \|_{L^1([0,1])} \lesssim \|f\|_{L \log L([0,1])}.

Exercise 7 For any locally integrable {f: {\bf R}^d \rightarrow {\bf C}}, let {M_\Box f} denote the rectangular maximal function

\displaystyle  M_\Box f(x) := \sup_{R\ni x} \frac{1}{|R|} \int_R |f(y)|\ dy

where {R} ranges over all rectangles with sides parallel to the coordinate axes which contain {x}. Show that {M_\Box} is bounded on {L^p} for all {1 < p \leq \infty}. (Hint: prove by induction, controlling the {d}-dimensional rectangular maximal function by the {d-1}-dimensional “horizontal” rectangular maximal function, applied to a one-dimensional “vertical” maximal function. A certain amount of application of the Fubini-Tonelli theorem may be needed.) Show by example that {M_\Box} is not of weak-type {(1,1)} in dimensions {d \geq 2}.

Exercise 8 Let {1 \leq p < \infty}, {0 < \alpha < d/p}, and let {f} be locally integrable on {{\bf R}^d}.
  • (i) Establish Hedberg’s inequality

    \displaystyle  \int_{{\bf R}^d} \frac{|f(y)|}{|x-y|^{d-\alpha}}\ dy \lesssim_{d,\alpha,p} \|f\|_{L^p({\bf R}^d)}^{\frac{\alpha p}{d}} (Mf(x))^{1-\frac{\alpha p}{d}}

    for all {x \in {\bf R}^d}. (Hint: use symmetries to normalise as many quantities as you can, and then divide the integral either dyadically, or into a region near {x} and a region away from {x}, estimating the two regions differently.)
  • (ii) Use Hedberg’s inequality to establish the Hardy-Littlewood-Sobolev inequality

    \displaystyle  \| I_\alpha f\|_{L^q({\bf R}^d)} \lesssim_{d,\alpha,p} \|f\|_{L^p({\bf R}^d)}

    where the fractional integral operator {I_\alpha} is defined by

    \displaystyle  I_\alpha f(x) := \int_{{\bf R}^d} \frac{|f(y)|}{|x-y|^{d-\alpha}}\ dy

    and {q} is the exponent for which {\alpha = d/p - d/q}.

Exercise 9 Let {f \in L^1({\bf R}^d)}, and let {B} be a ball such that {M f \geq \lambda} at every point of {B}. Show that {Mf \gtrsim_d \lambda} at every point of {2B}.

— 3. Second proof —

Let us now give a slightly different proof of the above inequality, replacing balls by the slightly simpler structure of dyadic cubes.

Definition 10 (Dyadic cube) A dyadic cube in {{\bf R}^d} of generation {n} is a set of the form

\displaystyle  Q = Q_{n,k} = 2^n (k + [0,1)^d) = \{ 2^n (k+x): x \in [0,1)^d \}

where {n} is an integer and {k \in {\bf Z}^d}.

The crucial property of dyadic cubes is the nesting property: if two dyadic cubes overlap, then one must contain the other. This leads to

Lemma 11 (Dyadic Vitali-type covering lemma) Let {Q_1,\ldots,Q_N} be a finite collection of dyadic cubes. Then there is a subcollection {Q_{n_1},\ldots,Q_{n_k}} of disjoint cubes such that

\displaystyle  Q_{n_1} \cup \ldots \cup Q_{n_k} = Q_1 \cup \ldots \cup Q_N.

Proof: Take the {Q_{n_i}} to be the maximal dyadic cubes in {Q_1,\ldots,Q_N} – the cubes which are not contained in any other cubes in this collection. The nesting property then ensures that they are disjoint and cover all of {Q_1,\ldots,Q_N} between them. \Box

If we then define the dyadic maximal function

\displaystyle  M_\Delta f(x) := \sup_{Q \ni x} \frac{1}{|Q|} \int_Q |f| = \sup_{Q \ni x} \frac{1}{|Q|} \int_Q |f(y)|\ dy

where {Q} ranges over the dyadic cubes which contain {x}, then the same argument as before then gives the dyadic Hardy-Littlewood maximal inequality

\displaystyle  \| M_\Delta f \|_{L^{1,\infty}({\bf R}^d)} \leq \|f\|_{L^1({\bf R}^d)} \ \ \ \ \ (3)

(with no constant loss whatsoever!) which then leads via Marcinkiewicz interpolation to

\displaystyle  \| M_\Delta f \|_{L^p({\bf R}^d)} \lesssim_p \|f\|_{L^p({\bf R}^d)}

for {1 < p \leq \infty}.

We can rewrite the dyadic maximal inequality in another way. Let {{\mathcal B}_n} be the {\sigma}-algebra generated by the dyadic cubes of generation {n}, then

\displaystyle  \mathop{\bf E}(f|{\mathcal B}_n)(x) = \frac{1}{|Q|} \int_Q f(y)\ dy

where {Q} is the unique dyadic cube of generation {n} which contains {x}. The dyadic Hardy-Littlewood maximal inequality is then equivalent to the assertion that

\displaystyle  \| \sup_n |\mathop{\bf E}( f|{\mathcal B}_n )| \|_{L^{1,\infty}({\bf R}^d)} \leq \|f\|_{L^1({\bf R}^d)}

and thus

\displaystyle  \| \sup_n |\mathop{\bf E}( f|{\mathcal B}_n )| \|_{L^p({\bf R}^d)} \lesssim_p \|f\|_{L^p({\bf R}^d)}

for {1 < p \leq \infty}.

Observe that if {x \in Q}, then there is a ball {B(x,r)} centred at {x} which contains {Q} of comparable volume: {|B(x,r)| \sim_d |Q|}. Because of this, one easily obtains the pointwise inequality

\displaystyle  M_\Delta f(x) \lesssim_d M f(x)

and so the dyadic inequality follows (up to constants) from the non-dyadic one. The converse pointwise inequality is not true (test it with {d=1} and {f = 1_{[0,1]}}, for instance). However, a slightly modification of this inequality is true, thanks to the {1/3}-translation trick that dates back to de la Vallée Poussin, though later rediscovered by harmonic analysts such as Okikiolu. We first explain this trick in the context of the unit interval {[0,1]}.

Lemma 12 Let {I \subset [0,1]} be a (non-dyadic) interval. Then there exists an interval {J} which is either a dyadic interval, or a dyadic interval translated by {1/3}, such that {I \subset J} and {|J| \lesssim |I|}.

The only significance of {1/3} is that its binary digit expansion oscillates between {0} and {1}. Note that the claim is false without the {1/3} shifts; consider for instance the interval {[0.5-\varepsilon,0.5+\varepsilon]} for some very small {\varepsilon}, which straddles a certain “discontinuity” in the standard dyadic mesh. The point is that the dyadic mesh and the {1/3}-translate of the dyadic mesh do not share any discontinuities.

Exercise 13 Prove the above lemma.

For intervals larger than {[0,1]}, a shift by {1/3} is not enough; consider for instance what happens to the interval {(-1,1)}. Instead, we have to shift by {4^\infty/3}, which of course does not make sense as a real number. However, it does make sense in some formal {2}-adic sense (as the doubly infinite binary string {\ldots10101.010101\ldots}) which is good enough to define shifted dyadic meshes.

Definition 14 (Dyadic meshes) We define {{\mathcal D}^1_0} to be the collection of all dyadic intervals in {{\bf R}}. We define {{\mathcal D}^1_{4^\infty/3}} to be the collection of all intervals of the form {I + 4^N/3}, where {I} is a dyadic interval at some generation {n} and {N} is any integer greater than or equal to {n} (note that the exact choice of {N} is irrelevant). If {\alpha = (\alpha_1,\ldots,\alpha_d) \in \{0, 4^\infty/3\}^d}, we let {{\mathcal D}^d_\alpha = {\mathcal D}^1_{\alpha_1} \times \ldots \times {\mathcal D}^1_{\alpha_d} } be the collection of cubes formed by the Cartesian product of intervals from {{\mathcal D}^1_{\alpha_1}, \ldots, {\mathcal D}^1_{\alpha_d}}.

By modifying the above lemma one then quickly deduces

Lemma 15 Let {B \subset {\bf R}^d} be a ball. Then there exists {\alpha \in \{0, 4^\infty/3\}^d} and a shifted dyadic cube {Q \in {\mathcal D}^d_\alpha} such that {B \subset Q} and {|Q| \lesssim_d |B|}.

This in turn leads to the pointwise inequality bounding the dyadic maximal function by the ordinary one:

\displaystyle  Mf(x) \lesssim_d \sup_{\alpha \in \{0,4^\infty/3\}^d} M_{\Delta,\alpha} f(x)

where {M_{\Delta,\alpha}} is the shifted dyadic maximal function

\displaystyle  M_{\Delta,\alpha} f(x) := \sup_{Q \in {\mathcal D}^d_\alpha: Q \ni x} \frac{1}{|Q|} \int_Q |f|.

A routine modification of the proof of the dyadic maximal inequality (or translating this inequality by {4^N/3} and taking limits as {N \rightarrow \infty}) shows that each of the {M_{\Delta,\alpha}} are individually of weak-type {(1,1)}, and bounded on {L^p} for {1 < p \leq \infty}. Since there are only {O_d(1)} many choices of {\alpha}, we can then deduce the usual Hardy-Littlewood maximal inequality from the dyadic one.

Remark 16 What is going on here is that there are two ways to view the real line {{\bf R}}. One is the “Euclidean” way, with the usual group structure and metric. The other is the “Walsh” or “dyadic” way, in which we identify {{\bf R}} with the Cantor group

\displaystyle  {\bf R}_\Delta := \{ (a_n)_{n \in {\bf Z}} \in ({\bf Z}/2{\bf Z})^{\bf Z}: a_n = 0 \hbox{ for sufficiently large } n \}

via the binary representation, {\sum_n a_n 2^{-n} \equiv (a_n)_{n \in {\bf Z}}} (identifying {{\bf Z}/2{\bf Z}} with {(0,1)}, and ignoring the measure zero sets of terminating decimals where the binary representation is not unique). The group structure is now the one inherited from the Cantor group; in the binary representation, the Cantor-Walsh addition law {x +_\Delta y} is the same as ordinary addition {x+y} but where we neglect to carry bits. The usual archimedean metric {d(x,y) = |x-y|} is replaced by the non-archimedean metric {d_\Delta(x,y)}, defined by

\displaystyle  d_\Delta((a_n)_{n \in {\bf Z}}, (b_n)_{n \in {\bf Z}}) := \sup \{ 2^n: a_n \neq b_n \}.

With this metric, the dyadic intervals become the metric balls.

Exercise 17 (Hardy-Littlewood maximal inequality for filtrations) Let {(X,{\mathcal B},\mu)} be a measure space, and let {{\mathcal B}_n} be an increasing sequence of {\sigma}-finite {\sigma}-algebras in {{\mathcal B}} (thus {{\mathcal B}_n \subset {\mathcal B}_{n+1}} for all {n \in {\bf Z}}). Show that

\displaystyle  \| \sup_n |\mathop{\bf E}(f|{\mathcal B}_n)| \|_{L^{1,\infty}(X,{\mathcal B},\mu)} \leq \|f\|_{L^1(X,{\mathcal B},\mu)}

and hence

\displaystyle  \| \sup_n |\mathop{\bf E}(f|{\mathcal B}_n)| \|_{L^p(X,{\mathcal B},\mu)} \lesssim_p \|f\|_{L^p(X,{\mathcal B},\mu)}

for all {1 < p \leq \infty} and all {{\mathcal B}}-measurable {f} for which the right-hand side is finite. (Hint: use monotone convergence to reduce to finitely many {{\mathcal B}_n}. Reduce further to the case when the {{\mathcal B}_n} are countably generated (by using the level sets of the {\mathop{\bf E}(f|{\mathcal B}_m)} for rational intervals). Reduce further still to the case where the {{\mathcal B}_n} are finitely generated, i.e. finite. Now adapt the dyadic argument. There are also simpler arguments which do not require all of these reductions.) This inequality is also known as Doob’s inequality, and implies in particular that {\mathop{\bf E}(f|{\mathcal B}_n)} converges pointwise a.e. to {\mathop{\bf E}(f|\bigvee_n {\mathcal B}_n)} whenever {f \in L^1(X,{\mathcal B},\mu)}.

Exercise 18 (Relationship between dyadic and non-dyadic Hardy-Littlewood maximal inequalities) Let {f: {\bf R}^d \rightarrow {\bf C}} be locally integrable. Establish the pointwise bound

\displaystyle  |\{ M_\Delta f \geq C_d \lambda\}| \leq |\{ Mf \geq \lambda \}| \lesssim_d |\{ M_\Delta f \geq c_d \lambda \}|

for some {c_d > 0} depending only on {d}.

— 4. Third proof —

In the above arguments we obtained {L^p} bounds by first proving weak {(1,1)} bounds and then interpolating. It is natural to ask whether such bounds can be obtained directly. The answer is yes, but it is surprisingly more difficult to do so. Let us give two such approaches, a Bellman function approach and a {TT^*} method approach, which are themselves powerful methods which apply to many other problems as well.

We begin with the Bellman function approach. This method works primarily for dyadic model operators, such as {M_\Delta}, though it can also work for very geometric operators as well (using geometric averaging operators such as heat kernels in place of the dyadic averaging operators). For simplicity let us just work in one dimension (though it is possible to use rearrangement and space-filling curves to deduce the higher-dimensional case from the one-dimensional case), and consider the task of establishing

\displaystyle  \| M_\Delta f \|_{L^p({\bf R})} \lesssim_p \|f\|_{L^p({\bf R})}

for some fixed {1 < p \leq \infty} (such as {p=2}).

The idea is to work by induction on scales – in other words, to induct on the number of generations. To do this we need a “base case”, so we perform some qualitative reductions. Fix {1 < p < \infty} (the case {p=\infty} being trivial). By a monotone convergence argument we may restrict attention only to those intervals {I} of length larger than {2^{-N}}, so long as our estimates are uniform in {N}. By rescaling (replacing {f(x)} by {f(2^N x)}) we can reduce to the case {N=0}. Let us write {M_{\geq 1}} for the dyadic maximal function restricted to intervals of length at least {1}. By a monotone convergence argument (there is a slight problem because we cannot represent {{\bf R}} as the monotone limit of dyadic intervals; however we can do this for {{\bf R}^+} and {{\bf R}^-} separately, and then add up, noting that the dyadic maximal function is localised to each of these half-lines, e.g. if {f} is supported on {{\bf R}^+} then so is {M_{\geq 1} f}) we can also assume that {f} is supported on a dyadic interval {I} of some length {2^n \geq 1}, and also we may restrict {M_{\geq 1} f} to that interval. We can also take {f} to be non-negative. Our task is now to show that there exists a constant {C_p} such that

\displaystyle  \frac{1}{|I|} \int_I (M_{\geq 1} f(x))^p\ dx \leq C_p \frac{1}{|I|} \int_I f(x)^p\ dx \ \ \ \ \ (4)

whenever {f: I \rightarrow {\bf R}^+}. (We make the constant {C_p} explicit here because of the induction that we shall shortly use.) Of course the point is that {C_p} is independent of {n}, {I}, and {f}.

We make a small but useful remark: once {f} and {M_{\geq 1} f} are both restricted to {I}, the only dyadic intervals {J} which are relevant in the definition of {M_{\geq 1} f} are those which are contained in {I} (including {I} itself). Intervals which are disjoint from {I} play no role, and intervals which contain {I} give a worse average than that arising from {I} itself.

The idea is to prove this by induction on the generation {n} of {I}. Our first approach will not quite work, but a subtle modification of it will.

When {n=0} the claim is trivial (as long as {C_p \geq 1}), because for {I} a dyadic interval of generation {0} and {x \in I} we have

\displaystyle  M_{\geq 1} f(x) = \frac{1}{|I|} \int_I f(y)\ dy \leq (\frac{1}{|I|} \int_I f(x)^p)^{1/p}.

Now let {n \geq 1}, and let us see whether we can deduce the {n} case from the {n-1} case without causing any deterioration in the constant {C_p}. (Using various applications of the triangle inequality it is not hard to get from {n-1} to {n}, replacing {C_p} with something worse like {2C_p + 1}, but this is not going to iterate into something independent of {n}.)

Let us split the dyadic interval {I} of generation {n} into two “children” {I = I_l \cup I_r} of generation {n-1} ({l} and {r} stand for left and right). This also causes a split {f = f_l + f_r}. By induction hypothesis we have

\displaystyle  \begin{array}{rl}  \frac{1}{|I_l|} \int_{I_l} (M_{\geq 1} f_l(x))^p\ dx &\leq C_p \frac{1}{|I_l|} \int_{I_l} f_l(x)^p\ dx \\ \frac{1}{|I_r|} \int_{I_r} (M_{\geq 1} f_r(x))^p\ dx &\leq C_p \frac{1}{|I_r|} \int_{I_r} f_r(x)^p\ dx. \end{array}

and we also trivially have

\displaystyle  \frac{1}{|I|} \int_I f(x)^p\ dx = \frac{1}{2} (\frac{1}{|I_l|} \int_{I_l} f_l(x)^p\ dx + \frac{1}{|I_r|} \int_{I_r} f_r(x)^p)\ dx.

Now if we were lucky enough to have the pointwise estimates

\displaystyle  M_{\geq 1} f(x) \leq M_{\geq 1} f_l(x) \hbox{ when } x \in I_l

and similarly for {I_r}, then we could simply average the two induction hypotheses and be done. However, this is not quite the case: the correct relationship between the maximal function of {f} and of {f_l, f_r} is that

\displaystyle  M_{\geq 1} f(x) = \max( M_{\geq 1} f_l(x), \frac{1}{|I|} \int_I f ) \hbox{ when } x \in I_l

and similarly when {x \in I_r}. This causes a problem. If we estimate the max by a sum and use triangle type inequalities, we will eventually get a bound such as (4) but with {C_p} replaced by {O_p(C_p+1)}, which is not acceptable for iteration purposes. So we have to somehow keep the max with the constant {\frac{1}{|I|} \int_I f} with us in the induction argument. This eventually forces us to change the induction hypothesis (4), replacing the left-hand side {\frac{1}{|I|} \int_I M_{\geq 1} f(x)^p\ dx} by the more general {\frac{1}{|I|} \int_I \max(M_{\geq 1} f(x), A)^p\ dx} for some arbitrary {A > 0}. Given our knowledge that max and addition are comparable up to constants, we know that (4) is equivalent to the estimate

\displaystyle  \frac{1}{|I|} \int_I \max(M_{\geq 1} f(x),A)^p\ dx \leq C'_p (\frac{1}{|I|} \int_I f(x)^p\ dx + A^p )

up to changes in the constant {C_p}. But perhaps this estimate has a better chance of being proven by induction. The key recursive inequality is now that

\displaystyle  \max(M_{\geq 1} f(x),A) = \max( M_{\geq 1} f_l(x), \max(A,\frac{1}{|I|} \int_I f) ) \hbox{ when } x \in I_l

and similarly for {I_l}. One can try the induction strategy again, but one sees that the inability to efficiently control {\frac{1}{|I|} \int_I f} in terms of {\int_I f(x)^p\ dx} and {A} is a serious problem. (Hölder’s inequality of course gives {\frac{1}{|I|} \int_I f} bounded by {(\frac{1}{|I|} \int_I f^p)^{1/p}}, but this turns out to be insufficient.) Because of this, we have no choice but to also throw in the average {B = \frac{1}{|I|} \int_I f} into the induction hypothesis somehow.

Let us formalise this as follows. Given any parameters {D, B, A > 0}, let {V_n(A,B,D)} denote the cost function

\displaystyle  V_n(A,B,D) := \sup \{ \frac{1}{|I|} \int_I \max(M_{\geq 1} f(x), A)^p\ dx: \frac{1}{|I|} \int_I f^p = D; \frac{1}{|I|} \int_I f = B; |I|=2^n \}

where {f} is understood to be nonnegative and supported on a dyadic interval {I} of generation {n}. Note that Hölder’s inequality shows that {V_n(A,B,D) = -\infty} when {B^p > D}, since in this case the supremum is over an empty set. Our task is thus to show that

\displaystyle  V_n(A,B,D) \lesssim_p D + A^p \ \ \ \ \ (5)

uniformly in {n} and in {A,B,D}. As we said earlier, the {B} parameter is not obviously necessary yet, but will become so when we try to perform the induction, as it tracks a certain finer property of the function {f} which needs to be managed in order to prevent the constants from blowing up. The base case when {|I|=1} is again trivial; the issue is to pass from fine scales to coarse scales without destroying the boundedness of implicit constant.

Now the recursive inequality can be turned into an inequality for {V_n}. Suppose that {f} attains the supremum (or comes within an epsilon of it). We have

\displaystyle  \frac{1}{|I_l|} \int_{I_l} f_l^p = D - \delta; \quad \frac{1}{|I_r|} \int_{I_r} f_r^p = D + \delta

for some {|\delta| \leq D}. Similarly

\displaystyle  \frac{1}{|I_l|} \int_{I_l} f_l = B - \beta; \quad \frac{1}{|I_r|} \int_{I_r} f_r = B + \beta

for some {|\beta| \leq B}. Then we have

\displaystyle  \max( M_{\geq 1} f(x), A ) = \max( M_{\geq 1} f_l(x), \max(A, B) )

for {x \in I_l}, and similarly for {x \in I_r}; by construction we thus have

\displaystyle  \frac{1}{|I|} \int_I \max( M_{\geq 1} f(x), A )^p \leq \frac{1}{2}( V_{n-1}( \max(A,B), B-\beta, D-\delta ) + V_{n-1}( \max(A,B), B+\beta, D+\delta ) ).

Taking suprema, we obtain the recursive inequality

\displaystyle  V_n(A,B,D) \leq \sup_{|\beta| \leq B, |\delta| \leq D} \frac{1}{2}( V_{n-1}( \max(A,B), B-\beta, D-\delta ) + V_{n-1}( \max(A,B), B+\beta, D+\delta ) ).

(In fact, this is an equality – why?) On the other hand, {V_0} can be computed directly as

\displaystyle  V_0(A,B,D) = \max(A,B)^p

when {B^p \leq D}, and {V_0(A,B,D)=-\infty} otherwise. In principle, this gives us a complete description of {V_n(A,B,D)}, which should allow one to determine the truth or falsity of (5). Note that we have reduced the problem from one involving an unknown function {f} (which has infinitely many degrees of freedom) to one involving just three scalar parameters {A,B,D}, except that we have a different cost function at every scale. However, suppose that we can devise a Bellman function {\Phi(A,B,D)} with the property that

\displaystyle  V_0(A,B,D) \lesssim \Phi(A,B,D) \lesssim_p D+A^p \ \ \ \ \ (6)

for all {A,B,D}, and such that {\Phi} obeys the inequality

\displaystyle  \Phi(A,B,D) \geq \frac{1}{2}( \Phi( \max(A,B), B-\beta, D-\delta ) + \Phi( \max(A,B), B+\beta, D+\delta ) ) \ \ \ \ \ (7)

whenever {|\beta| \leq B} and {|\delta| \leq D}. Then an induction will show that

\displaystyle  V_n(A,B,D) \lesssim \Phi(A,B,D) \lesssim_p D+A^p

for all {n} (and note that the implied constants here are uniform in {n}), thus proving (5).

Thus the whole task is reduced to a freshman calculus problem, namely to find a function of three variables obeying the bounds (6) and (7). The difficulty of course, is to find the function; verifying the properties is then routine. This “hunt for a Bellman function” is surprisingly subtle, and requires one to choose a surprisingly non-trivial choice of {\Phi}.

The condition (7) resembles a concavity condition, and so it is natural to try to find choices which are concave in some of the variables. An initial candidate is the function {\Phi(A,B,D) = D}, which certainly obeys (7) and the upper bound of (6) (and which, in fact, ultimately corresponds to the original estimate (4) before we threw in the other parameters {B,A}); unfortunately it does not obey the lower bound in (6), in the case where {A} is large compared with {B} and {D^{1/p}}. So we need to tweak this function somewhat. The first step is to improve the concavity by exploiting the fact that the function only needs to be non-trivial on the region {B^p \leq D}. One can exploit this by using the candidate function {\Phi(A,B,C) = D - \frac{1}{2} B^p} (say). This still obeys (7), but now with a bit of a gain when {\beta} is large due to the strict concavity of {-B^p}. (One cannot play similar games with the {D} parameter as the upper and lower bounds in (6) force linear-type behaviour in {D}.) But we still have not fixed the problem that {\Phi} is not as large as {V_0(A,B,D)} when {A} is large. The solution is to use the Bellman function

\displaystyle  \Phi(A,B,C) = D + A^p f( B/A )

where {f(x)} is a concave function which is positive for small {x} and is equal to {-\frac{1}{2}x^p} for {x > 1/10} (say). Thus we have {\Phi = D - \frac{1}{2} B^p} when {A < 10 B}, but {\Phi} becomes as large as {D + A^p} or so when {A} exceeds {10B}. This lets us verify both sides of (6), so one only needs to verify (7). If {A < 5B} then the claim follows from the concavity of {D - \frac{1}{2} B^p} (which does not depend on {A}); when {A \geq 5B} the claim follows from the concavity of {\Phi} in the {B} variable and in the {D} variable.

Remark 19 Bellman function methods are in principle the sharpest and most powerful technique to prove estimates. However they are restricted to dyadic settings (or very geometric continuous settings), and are very delicate due to the need to establish very subtle concavity properties.

— 5. Fourth proof —

Finally, we present the “{TT^*} approach” to the Hardy-Littlewood maximal inequality. This approach works for both the dyadic and non-dyadic maximal functions, but is restricted to establishing {L^2} boundedness (this is a fundamental limitation of the {TT^*} method, that at least one of the spaces involved has to be a Hilbert space). The basic idea is rather than prove a boundedness result directly on the maximal operator {M} (i.e. an estimate of the form {M = O(1)}), we prove an estimate on the square of this operator (roughly speaking, we prove an estimate of the form {M^2 = O(M)}). This is an example of a powerful strategy to understand an operator by raising it to a higher power, and hoping to exploit some self-cancellation. Note that we do not have to cancel the entire power (which would roughly speaking correspond to proving a bound of the form {M^2 = O(1)}); any nontrivial cancellation at all is exploitable.

Let us work with the non-dyadic maximal function, thus we wish to show that

\displaystyle  \| \sup_{r > 0} A_r f \|_{L^2({\bf R}^d)} \lesssim_d \|f\|_{L^2({\bf R}^d)}

for all non-negative {f}. As before we may restrict {r} to range in a finite set {{\mathcal R}}, provided our bounds are independent of the choice of {{\mathcal R}}. Note that because each {A_r} is already bounded on {L^2}, the maximal operator is now already bounded with some finite operator norm. Let {D} denote the optimal such norm, thus {D} is the best constant for which

\displaystyle  \| \sup_{r \in {\mathcal R}} A_r f \|_{L^2({\bf R}^d)} \leq D \|f\|_{L^2({\bf R}^d)}. \ \ \ \ \ (8)

We know {D} is finite; our objective is to obtain the bound {D = O_d(1)}. We will do this by controlling {D} in a nontrivial way in terms of itself, and in particular by controlling the “square” of the maximal operator by the maximal operator.

Observe that (8) is equivalent to the uniform linearised estimate

\displaystyle  \| A_{r(x)} f(x) \|_{L^2_x({\bf R}^d)} \leq D \|f\|_{L^2({\bf R}^d)}

for all measurable functions {r: {\bf R}^d \rightarrow {\mathcal R}}.

Let us fix the function {r}. Then we can define the linear operator {T_r} by

\displaystyle  T_r f(x) := A_{r(x)} f(x) = \frac{1}{|B(x,r(x))|} \int_{{\bf R}^d} 1_{|x-y| \leq r(x)} f(y)\ dy.

We can thus interpret {D} as the largest {L^2} operator norm of the {T_r}:

\displaystyle  D = \sup_r \| T_r \|_{L^2({\bf R}^d) \rightarrow L^2({\bf R}^d)}.

To compute this operator norm we make the following observation.

Lemma 20 ({TT^*} identity) Let {T: H \rightarrow X} be a continuous map from a Hilbert space to a normed vector space, and let {T^*: X^* \rightarrow H} be its adjoint. Then

\displaystyle  \| T \|_{H \rightarrow X} = \|T^* \|_{X^* \rightarrow H} = \| TT^* \|_{X^* \rightarrow X}^{1/2}.

Proof: The first identity is just duality. Then we have

\displaystyle  \|TT^* \|_{X^* \rightarrow X} \leq \| T \|_{H \rightarrow X} \|T^* \|_{X^* \rightarrow H} = \|T^* \|_{X^* \rightarrow H}^2

which gives the lower bound in the second identity. For the upper bound, observe that for any {f \in X^*} that

\displaystyle  \| T^* f \|_H^2 = \langle f, TT^* f \rangle \leq \|f\|_{X^*} \| TT^* f \|_X \leq \|f\|_{X^*}^2 \| TT^* \|_{X^* \rightarrow X};

taking square roots gives the upper bound as desired. \Box

In light of this identity we know that

\displaystyle  D^2 = \sup_r \| T_r T_r^* \|_{L^2({\bf R}^d) \rightarrow L^2({\bf R}^d)}.

Now let us take a look at what {T_r T_r^*} is. Observe that {T_r} is an integral operator with kernel

\displaystyle  K(x,y) := \frac{1}{|B(x,r(x))|} 1_{|x-y| \leq r(x)}.

Thus the adjoint is given by

\displaystyle  T_r^* g(y) = \int_{{\bf R}^d} \frac{1}{|B(x,r(x))|} 1_{|x-y| \leq r(x)} g(x)\ dx

and then {TT^*} is given by

\displaystyle  T_r T_r^* g(x') = \int_{{\bf R}^d} \int_{{\bf R}^d} \frac{1}{|B(x,r(x))| |B(x',r(x'))|} 1_{|x-y| \leq r(x)} 1_{|x'-y| \leq r(x')} g(x)\ dy dx.

Note that the {y} integral can be computed fairly easily. First we observe that the {y} integral vanishes unless {|x-x'| \leq r(x)+r(x')}, and in the latter case it enjoys a bound of {O_d(\min(r(x),r(x'))^d)}. Also, {|B(x,r(x))| \sim_d r(x)^d} and {|B(x',r(x'))| \sim_d r(x')^d}. Putting this together we see that

\displaystyle  | T_r T_r^* g(x') | \lesssim_d \int_{{\bf R}^d} 1_{|x-x'| \leq r(x)+r(x')} \frac{1}{\max(r(x),r(x'))^d} |g(x)|\ dx.

It is natural to split this integral into the regions {r(x) \leq r(x')} and {r(x) \geq r(x')}, leading to the bound

\displaystyle  | T_r T_r^* g(x') | \lesssim_d \int_{{\bf R}^d} 1_{|x-x'| \leq 2r(x)} \frac{1}{r(x)^d} |g(x)|\ dx + \int_{{\bf R}^d} 1_{|x-x'| \leq 2r(x')} \frac{1}{r(x')^d} |g(x)|\ dx.

Comparing this with the formulae for {T_r} and {T_{r'}}, we obtain the interesting pointwise inequality

\displaystyle  | T_r T_r^* g(x') | \lesssim_d T_{2r} |g|(x') + T^*_{2r} |g|(x')

where {2r} is the function {x \mapsto 2r(x)}, of course. On the other hand, a scaling argument gives

\displaystyle  \|T_{2r}\|_{L^2({\bf R}^d) \rightarrow L^2({\bf R}^d)} \leq D

and hence we conclude from the triangle inequality that

\displaystyle  \| T_r T_r^* \|_{L^2({\bf R}^d) \rightarrow L^2({\bf R}^d)} \lesssim_d D;

taking suprema in {r} we conclude that {D^2 \lesssim_d D}, and hence (since {D} is known to be finite) {D \lesssim_d 1}, and the claim follows.

The Hardy-Littlewood maximal function directly bounds averages on balls and cubes, but it also controls several other types of averages as well. For instance, we have the pointwise inequality

\displaystyle  \frac{1}{r^d} \int_{{\bf R}^d} \frac{1}{\langle (x-y)/r \rangle^{d+\varepsilon}} |f(y)|\ dy \lesssim_{d,\varepsilon} Mf(x) \ \ \ \ \ (9)

for any locally integrable {f}, any {x \in {\bf R}^d}, and any {\varepsilon > 0}; this can be achieved by dividing the {y} integral into dyadic shells {2^n r \leq |x-y| < 2^{n+1} r} for {n \geq 0}, as well as the ball {|x-y| < r}, and we leave the computation to the reader.

The proof of the Hardy-Littlewood maximal inequality extends to the more general setting of spaces of homogeneous type (which is similar, but different from, the notion of a homogeneous space). These are measure spaces {(X,{\mathcal B},\mu)} with a metric {d}, such that the open balls are measurable with positive finite measure, and that one has the doubling property

\displaystyle  \mu(B(x,2r)) \lesssim \mu(B(x,r))

for any {x,r}. Then the Vitali-type covering lemma extends without difficulty to this setting and yields the maximal inequality

\displaystyle  \| \sup_{r > 0} \frac{1}{|B(x,r)|} \int_{B(x,r)} |f(y)|\ d\mu(y) \|_{L^{1,\infty}(X)} \lesssim \|f\|_{L^1(X)}

and hence

\displaystyle  \| \sup_{r > 0} \frac{1}{|B(x,r)|} \int_{B(x,r)} |f(y)|\ d\mu(y) \|_{L^p(X)} \lesssim_p \|f\|_{L^p(X)}

for any {1 < p \leq \infty}.

In particular we obtain the discrete inequality

\displaystyle  \| \sup_{N > 0} \frac{1}{N} \sum_{n=1}^N f(m+n) \|_{l^{1,\infty}_m({\bf Z})} \leq \| f\|_{l^1({\bf Z})}; \ \ \ \ \ (10)

(which we need in our applications to ergodic theory below), while on the torus {{\bf R}/{\bf Z}} with the usual Lebesgue measure we have

\displaystyle  \| \sup_{r > 0} \frac{1}{2r} \int_{|x-y| \leq r} |f(y)|\ dy \|_{L^p({\bf R}/{\bf Z})} \lesssim_p \|f\|_{L^p({\bf R}/{\bf Z})} \ \ \ \ \ (11)

for {1 < p \leq \infty} (which we will need for our applications to complex analysis).

Remark 21 One could try playing with {T^*T} instead of {TT^*} here, but that turns out to not work very well. The problem is that the linearised maximal operator is only well-behaved in one variable, and the {TT^*} method manages to play the two well-behaved variables against each other; going the other way one achieves no obvious cancellation.

— 6. Some consequences of the maximal inequality —

The Hardy-Littlewood maximal inequality is the underlying quantitative estimate which powers many qualitative pointwise convergence results. A basic example is

Theorem 22 (Lebesgue differentiation theorem) Let {f} be locally integrable. Then we have the pointwise convergence {\lim_{r \rightarrow 0} A_r f(x) = f(x)} for almost every {x}. In fact we have the stronger estimate

\displaystyle  \lim_{r \rightarrow 0} \frac{1}{|B(x,r)|} \int_{B(x,r)} |f(y)-f(x)|\ dy = 0 \ \ \ \ \ (12)

for almost every {x}.

Before we prove the theorem, let us make some remarks. Firstly, from the identity

\displaystyle  A_r f(x) - f(x) = \frac{1}{|B(x,r)|} \int_{B(x,r)} (f(y)-f(x))\ dy

and the triangle inequality it is clear that the second estimate implies the first. Secondly, observe that {f} is continuous at {x} if and only if the worst-case local fluctuation goes to zero

\displaystyle  \lim_{r \rightarrow 0} \sup_{y \in B(x,r)} |f(y)-f(x)| = 0.

Thus the differentiation theorem is asserting that locally integrable functions are almost everywhere continuous on the average, in that the average-case local fluctuation goes to zero. This is a manifestation of one of Littlewood’s three principles, namely that measurable functions are almost continuous. If {x} is such that (12) holds, we say that {x} is a Lebesgue point of {f}, thus for locally integrable {f}, almost every point {x} is a Lebesgue point.

Proof: It suffices to establish the result for {x} constrained to a large ball {B(0,R)}, where {R > 0} is arbitrary. The claim is obvious if {f} vanishes on {B(0,2R)}, so by linearity we may assume that {f} is supported on {B(0,2R)}; in particular {f} now lies in {L^1({\bf R}^d)}. Thus it suffices to establish the claim when {f \in L^1({\bf R}^d)}.

By the preceding discussion we already know that the claim is true for the continuous compactly supported functions {C_c({\bf R}^d)}, which is a dense subclass of {L^1({\bf R}^d)}. To pass from the dense subclass to the full class we use the Hardy-Littlewood maximal inequality now lets us reduce matters to verifying the claim on a dense subset of {L^1({\bf R}^d)}. To see this, suppose that we already have proven the claim on a dense class. Then, given any {f \in L^1({\bf R}^d)} we can write {f} as the limit in {L^1} of a sequence {f_n} in this dense class; by refining these sequence to make the {L^1} convergence sufficiently fast (e.g. {\|f_n - f\|_{L^1({\bf R}^d)} \leq 2^{-n}}) and using Markov’s inequality and the Borel–Cantelli lemma, we can also ensure that {f_n} converges to {f} pointwise almost everywhere. Now from the Hardy-Littlewood maximal inequality, we know that {\| \sup_{r > 0} A_r |f_n - f| \|_{L^{1,\infty}({\bf R}^d)}} converges to zero, thus {\sup_{r > 0} A_r|f_n - f|} converges to zero in measure. By the triangle inequality this implies that {\sup_{r > 0} |A_r f_n - A_r f|} converges in measure also. Thus (again passing to a rapidly converging subsequence as necessary) we see that {\sup_{r > 0} |A_r f_n(x) - A_r f(x)|} converges to zero for almost every {x}. This uniform-in-{r} convergence lets one deduce the convergence of {A_r f} from the convergence of {A_r f_n}.

Finally, by taking a dense class such as the Schwartz class (or even the continuous functions in {L^1({\bf R}^d)}) we easily verify the convergence. \Box

Remark 23 Because the proof used a density argument, it offers no quantitative rate for the speed of convergence. Indeed the convergence can be arbitrarily slow; this is ultimately due to the implicit hypothesis that {f} is measurable, which is itself a qualitative assumption that offers no explicit bounds. More quantitative versions of measurability, e.g. quantifying the extent to which a measurable set can be approximated by elementary sets, can lead to more explicit bounds.

Consider for instance the function {f: {\bf R} \rightarrow {\bf R}} defined by {f(x) = 1} when {0 < x < 1} and the integer part of {Nx} is even, and {f(x) = 0} otherwise, where {N} is a large integer. Then we see that for {0 < x < 1}, {A_r(x)} will stay close to {1/2} for quite a while (basically for all {r \gg 1/N}), and only at scales {1/N} or less will it begin to “decide” to converge to either {0} or {1}. Modifying this type of example (e.g. by a “Weierstrass example” formed by summing together a geometrically decaying series of such oscillating functions, with {N} going to infinity), one can concoct functions whose convergence of {A_r f} to {f} is arbitrarily slow. (One can obtain quantitative rates by enforcing regularity conditions on the function, which essentially compactifies the space of functions that one is working with; we will see some examples of this later.)

Exercise 24 Let {f} be a locally integrable function on {{\bf R}^d}. Call a point {x \in {\bf R}^d} a Lebesgue point if there exists a number {c} such that {\lim_{r \rightarrow 0} \frac{1}{|B(x,r)|} \int_{B(x,r)} |f(y) - c|\ dy = 0}. Show that almost every point is a Lebesgue point, and that {c} is equal to {f(x)} almost everywhere.

Exercise 25 (Heat kernels) For any {t > 0} and any {f \in L^p({\bf R}^d)} for some {1 \leq p \leq \infty}, define the heat kernel {e^{t\Delta} f} by

\displaystyle  e^{t\Delta} f(x) := \frac{1}{(4\pi t)^{d/2}} \int_{{\bf R}^d} e^{-|x-y|^2/4t} f(y)\ dy.

Show that if {1 \leq p < \infty} and {f \in L^p({\bf R}^d)}, then {e^{t\Delta} f} converges both pointwise and in norm to {f} as {t \rightarrow 0}.

Now let us explore applications to ergodic theory. In particular we wish to investigate limits of the form

\displaystyle  \lim_{N \rightarrow \infty} \frac{1}{N} \sum_{n=1}^N T^n f

for various functions {f} and various “shift operators” {T}.

Let us first look at an abstract setting, in which {T} is a unitary operator on a Hilbert space.

Theorem 26 (Von Neumann ergodic theorem) Let {T: H \rightarrow H} be a unitary operator on a Hilbert space. Then for any {f \in H}, the limit {\lim_{N \rightarrow \infty} \frac{1}{N} \sum_{n=1}^N T^n f} exists in the strong {H} topology.

Proof: Let us first argue formally. We have

\displaystyle  \frac{1}{N} \sum_{n=1}^N T^n f = \frac{T + \ldots + T^N}{N} f.

Formally, we have the geometric series formula

\displaystyle  \frac{T + \ldots + T^N}{N} f = \frac{T^{N+1}-T}{N(T-1)} f

which looks like it converges to zero, unless {T-1} fails to be invertible; but on the other hand when {T=1} {\frac{T + \ldots + T^N}{N}} is just {1}, which of course converges to the identity. So we seem to have covered two extreme cases.

Now let us make the above argument rigorous. If {f} is {T}-invariant, thus {Tf = f}, then {T^n f = f} and it is clear that {\lim_{n \rightarrow \infty} \frac{1}{N} \sum_{n=1}^N T^n f} converges to {f}. If on the other hand {f} is a {T}-difference, {f = Tg - g} for some {g \in H}, then we verify the telescoping identity {\sum_{n=1}^N T^n f = T^{N+1} g - T g}. Since unitary operators preserve the norm, we thus see from the triangle inequality that {\lim_{n \rightarrow \infty} \frac{1}{N} \sum_{n=1}^N T^n f} converges to zero. Also, since the averaging operators {\frac{1}{N} \sum_{n=1}^N T^n} are uniformly bounded in {H} (by the triangle inequality), we see that any strong limit of {T}-differences also has the property that {\lim_{n \rightarrow \infty} \frac{1}{N} \sum_{n=1}^N T^n f} exists and equals zero.

To summarise so far, we have two closed subspaces of {H} for which we know convergence. The first is {H^T := \{ f \in H: Tf = f\}}, the invariant space of {T}; here the limit converges to the identity. The other is {\overline{\{ Tg-g: g \in H \}}}, the closure of the {T}-differences; here the limit conveges to zero. These two spaces turn out to be orthogonal complements. To see this, first observe that they are orthogonal: if {Tf = f}, then {\langle f, Tg \rangle = \langle Tf, Tg \rangle = \langle f, g \rangle} by unitarity, and hence {f} is orthogonal to every {T}-difference {Tg-g} and hence by continuity of inner product is orthogonal to {\overline{\{ Tg-g: g \in H \}}}. To show orthogonal complement, it then suffices to show that any vector {f} orthogonal to {\overline{\{ Tg-g: g \in H \}}} is invariant. But then {f} is orthogonal to {Tf-f}:

\displaystyle  \langle f, Tf - f \rangle = 0.

We rewrite the left-hand side as

\displaystyle  \langle f, Tf \rangle - \langle f, f \rangle = \langle f, Tf \rangle - \langle Tf, Tf \rangle = - \langle Tf - f, Tf \rangle

and on conjugating and subtracting we conclude that

\displaystyle  \langle Tf - f, Tf - f \rangle = 0

and thus {Tf=f} as claimed. \Box

Note that the above argument in fact shows the stronger claim that {\lim_{n \rightarrow \infty} \frac{1}{N} \sum_{n=1}^N T^n f} converges to the orthogonal projection of {f} to {H^T}.

Now we move to a more specialised setting, that of a measure-preserving system.

Definition 27 (Measure-preserving system) A measure-preserving system {(X,{\mathcal B}, \mu, T)} is a probability space {(X,{\mathcal B},\mu)} (thus {\mu(X)=1}) together with a bi-measurable bijection {T: X \rightarrow X} (thus {T} and {T^{-1}} are both measurable) such that {T} is measure-preserving, thus {\mu(T(E)) = \mu(E)} for all {E \in {\mathcal B}}.

Example 28 (Circle shift) Let {X = {\bf R}/{\bf Z}} be the standard circle with the usual Borel {\sigma}-algebra and Lebesgue measure, and let {Tx := x + \alpha} for some {\alpha \in {\bf R}}, which may be either rational or irrational.

Remark 29 Many of the results here hold under more relaxed assumptions on {T}, but we will not attempt to optimise the hypotheses here.

The shift {T} on the base space {X}, {x \mapsto T(x)}, induces a shift on sets {E \in {\mathcal B}}, {E \mapsto T(E)}, and then also induces a map on measurable functions {f: X \rightarrow {\bf C}} by {Tf := f \circ T^{-1}}. The use of {T^{-1}} is natural since it ensures that {T 1_E = 1_{TE}} and {Tf(Tx) = f(x)}.

Proposition 30 (Mean ergodic theorem) Let {(X,{\mathcal B},\mu,T)} be a measure-preserving system, and let {f \in L^p(X)} for some {1 \leq p < \infty}. Then the sequence {\frac{1}{N} \sum_{n=1}^N T^n f} converges strongly in {L^p(X)}.

Proof: The operator {T} is an isometry on {L^p}, and so by the triangle inequality the averaging operators {\frac{1}{N} \sum_{n=1}^N T^n} are uniformly bounded in {L^p}. Thus it suffices to prove the claim for a dense subclass of {L^p}; we shall pick {L^\infty(X)}. In this class, which is embedded into the Hilbert space {L^2(X)}, we already know from the von Neumann ergodic theorem (and the fact that {T} is a unitary operator on {L^2(X)}) that the averages are convergent in {L^2(X)} norm. But they are also uniformly bounded in {L^\infty(X)}. So the claim follows from the log-convexity of {L^p} norms (for {p \geq 2}) or by Hölder’s inequality and the finite measure of {X} (for {p < 2}). \Box

Exercise 31 Show by example that the mean ergodic theorem fails for {p < 1} and for {p=\infty}.

Now we study the pointwise convergence problem. The key quantitative estimate needed is the following analogue of the Hardy-Littlewood maximal inequality.

Theorem 32 (Hardy-Littlewood maximal inequality for measure-preserving systems) Let {(X,{\mathcal B},\mu,T)} be a measure-preserving system. Then we have

\displaystyle  \| \sup_{N > 0} \frac{1}{N} \sum_{n=1}^N T^n f \|_{L^{1,\infty}(X)} \lesssim \|f\|_{L^1(X)}

and

\displaystyle  \| \sup_{N > 0} \frac{1}{N} \sum_{n=1}^N T^n f \|_{L^p(X)} \lesssim_p \|f\|_{L^p(X)}

for all {1 < p \leq \infty}.

Proof: The claim is trivial when {p=\infty}, so once again the task is to prove the pointwise estimate. By monotone convergence it suffices to show that

\displaystyle  \| \sup_{1 \leq N < N_0} \frac{1}{N} \sum_{n=1}^N T^n f \|_{L^{1,\infty}(X)} \lesssim \|f\|_{L^1(X)}

uniformly in {N_0 > 1}.

The idea is to lift up to a space where {T} can be modeled by the integer shift {n \mapsto n+1}, at which point we can apply (10). Fix {N_0}, and let {[2N_0]} be the finite set {[2N_0] := \{0,\ldots,2N_0-1\}}, endowed with the discrete {\sigma}-algebra and uniform measure, so that {X \times [2N_0]} is a probability space. Inside this space we have {X \times [N_0]}, where {[N_0] := \{0,\ldots,N_0-1\}}. We define the function {F: X \times [2N_0] \rightarrow {\bf C}} by

\displaystyle  F(x,n) := T^n f(x).

From (10) we have

\displaystyle  \| \sup_{1 \leq N < N_0} \frac{1}{N} \sum_{n=1}^N F(x,n+m) \|_{l^{1,\infty}_m([N_0])} \lesssim \| F(x,m) \|_{l^1_m([2N_0])}

for all {x \in X}; writing out what the {l^{1,\infty}} norm means, and integrating in {X} using Fubini’s theorem, we conclude

\displaystyle  \| \sup_{1 \leq N < N_0} \frac{1}{N} \sum_{n=1}^N F(x,n+m) \|_{L^{1,\infty}_{x,m}(X \times [N_0])} \lesssim \| F \|_{L^1(X \times [2N_0])}.

The right-hand side is just {\|f\|_{L^1(X)}}. As for the left-hand side, observe that

\displaystyle  \sup_{1 \leq N < N_0} \frac{1}{N} \sum_{n=1}^N F(x,n+m) = \sup_{1 \leq N < N_0} \frac{1}{N} \sum_{n=1}^N T^n f( T^{-m} x )

and so on writing out the {L^{1,\infty}} norm we see that the left-hand side is comparable to

\displaystyle  \| \sup_{1 \leq N < N_0} \frac{1}{N} \sum_{n=1}^N T^n f(x) \|_{L^{1,\infty}(X)}

and the claim follows. \Box

Remark 33 Note how a maximal inequality for the integers was “transferred” to a maximal inequality on arbitrary measure preserving systems. There are several abstract transference principles which generalise this type of phenomenon. In particular, the above argument is in fact a special case of the Calderón transference principle.

Now we can present the analogue of the Lebesgue differentiation theorem for measure-preserving systems.

Proposition 34 (Pointwise ergodic theorem) Let {(X,{\mathcal B},\mu,T)} be a measure-preserving system, and let {f \in L^1(X)}. Then the sequence {\frac{1}{N} \sum_{n=1}^N T^n f} converges pointwise almost everywhere.

Proof: By repeating the argument in the Lebesgue differentiation theorem more or less verbatim (using the above maximal inequality in place of the Hardy-Littlewood inequality) it suffices to verify the claim for a dense subclass of {L^1(X)}, such as {L^2(X)}. Since the {L^2(X)} norm controls the {L^1} norm, it suffices to do so for a dense subclass of {L^2(X)}.

Now we repeat the proof of the von Neumann ergodic theorem. For the invariant part {L^2(X)^T} of {L^2(X)}, the pointwise convergence is obvious. Also, for functions of the form {Tg-g} with {g \in L^\infty(X)}, the convergence is also obvious. But these functions are clearly dense in {\{ Tg-g: g \in L^2(X) \}} and hence in {\overline{\{ Tg-g: g \in L^2(X) \}}}. Since this space and {L^2(X)^T} are orthogonal complements of {L^2(X)}, we thus have demonstrated convergence of a dense subclass of {L^2(X)} and thus of {L^1(X)}, as desired. \Box

Remark 35 Notice how the strategy of establishing convergence splits into two independent parts – obtaining convergence on a dense subclass, and then establishing some harmonic analysis estimate to pass to the general case. This is not the only way to achieve convergence results. Later on we shall see a variation-norm approach which relies purely on harmonic analysis estimates to obtain convergence (foregoing the dense subclass). In the opposite direction, there are more dynamical approaches (which we do not cover here) which forego the harmonic analysis component of the argument, relying instead on analysing the dynamics of the measure-preserving system by other means (such as measure-theoretic or topological means). It is not fully understood to what extent these different techniques complement each other.

Exercise 36 Let {(X,{\mathcal B},\mu,T)} be a measure-preserving system. Let {{\mathcal B}^T = \{ E \in {\mathcal B}: T(E) = E \}} be the elements of {{\mathcal B}} which are {T}-invariant (up to sets of measure zero, of course). Show that for any {f \in L^p({\mathcal B})} and {1 \leq p < \infty}, the averages {\frac{1}{N} \sum_{n=1}^N T^n f} converge in {L^p} norm and pointwise almost everywhere to {\mathop{\bf E}(f|{\mathcal B}^T)}. In particular, when {X} is ergodic (thus the only invariant sets have zero measure or full measure), conclude that {\frac{1}{N} \sum_{n=1}^N T^n f} converges pointwise and in {L^p} norm to {\int_X f\ d\mu}.

Exercise 37 (Poincare recurrence theorem) Let {(X,{\mathcal B},\mu,T)} be a measure-preserving system, and let {f \geq 0} be non-negative with {\int_X f\ d\mu > 0}. Show that {\int_X f T^n f\ d\mu > 0} for infinitely many {n \geq 1}.

By combining the Lebesgue differentiation theorem with the Radon-Nikodym theorem, one easily obtains

Theorem 38 (One-dimensional Radamacher differentiation theorem) If {f: {\bf R} \rightarrow {\bf C}} is Lipschitz, then it is differentiable almost everywhere, its derivative lies in {L^\infty({\bf R})}, and we have the fundamental theorem of calculus {f(y) - f(x) = \int_x^y f'(z)\ dz} for all {x, y \in {\bf R}}.

Proof: We may reduce to the case when {f} is real. The Riemann-Stietjes measure {df} is easily seen to be absolutely continuous with respect to Lebesgue measure, and is thus of the form {df = g dx} for some locally integrable {g}, thus {f(y) -f(x) = \int_x^y g(z)\ dz} by the Radon-Nikodym theorem. The Lebesgue differentiation theorem then shows that {f'} exists and is equal to {g} at every Lebesgue point of {g} (see Q7), and the claim follows. (The boundedness of {g = f'} is clear from the Lipschitz nature of {f}.) \Box

Remark 39 There are other ways to prove this theorem that do not require Radon-Nikodym differentiation, which we shall encounter later.

This one-dimensional theorem implies a multi-dimensional analogue:

Theorem 40 (Radamacher differentiation theorem) If {f: {\bf R}^d \rightarrow {\bf C}} is Lipschitz, then {f} is differentiable almost everywhere, thus for almost every {x} there exists a vector {\nabla f(x)} such that

\displaystyle  \lim_{h \rightarrow 0} \frac{ |f(x+h) - f(x) - \nabla f(x) \cdot h|}{|h|} = 0.

Proof: For simplicity of notation we take {d=2}, although the general case is similar. Theorem 38 (and Fubini’s theorem) shows that the partial derivatives {\frac{\partial f}{\partial x_1}}, {\frac{\partial f}{\partial x_2}} exist almost everywhere and are bounded. This gives us a candidate gradient {\nabla f} defined almost everywhere. The remaining challenge is to show total differentiability. In other words, for any {\varepsilon > 0}, we need to show that for almost every {x}, we have

\displaystyle  f(x+h) - f(x) = \nabla f(x) \cdot h + O( \varepsilon |h| ) \ \ \ \ \ (13)

whenever {|h|} is sufficiently small depending on {x}. Note that the control of the partial derivatives only achieve this when {h} is a multiple of {e_1} or {e_2}.

Fix {\varepsilon > 0}. We will need to make things slightly more quantitative. For any {n \geq 1} and {i=1,2}, let {X_{i,n}} denote the set

\displaystyle  X_{i,n} := \{ x \in {\bf R}^2: |f(x + h_i e_i) - f(x) - \frac{\partial f}{\partial x_i}(x) h_i| \leq \varepsilon |h_i|

\displaystyle \hbox{ whenever } |h_i| \leq \frac{1}{n} \}.

Then the almost everywhere existence of {\frac{\partial f}{\partial x_i}} implies that the {X_{i,n}} are measurable and increase to {{\bf R}^2} as {n \rightarrow \infty} (neglecting sets of measure zero). In particular, almost every point lies in infinitely many of the {X_{i,n}}. Because of this, we know that almost every point is a horizontal and vertical Lebesgue point of {\frac{\partial f}{\partial x_i}} and of {1_{X_{i,n}}} for infinitely many {n}. (We say that {(x,y)} is a horizontal Lebesgue point of {F} if {\frac{1}{2r} \int_{-r}^r |F(x+t,y) - F(x,y)|\ dt \rightarrow 0} as {r \rightarrow 0}, and similarly define a vertical Lebesgue point of {F}.) In particular, for almost every point there is an {n} such that one lies in {X_{i,n}}, and is a horizontal and vertical Lebesgue point of {\frac{\partial f}{\partial x_i}} and of {1_{X_{i,n}}} for {i=1,2}. From this it is not hard to show (13) for a large density set of {h} near {x} (say of density {1 - \varepsilon^2}), basically by decomposing {f(x+h_1e_1+h_2e_2) - f(x) = [f(x+h_1e_1) - f(x)] + [f(x+h_1e_1+h_2e_2) - f(x+h_1 e_1)]} and using the Lebesgue point properties to ensure that {\frac{\partial f}{\partial x_2}(x+h_1e_1)} is usually close to {\frac{\partial f}{\partial x_2}(x)}; we omit the details. The remaining exceptional values of {h} can then be dealt with by locating a nearby non-exceptional value of {h} and using the Lipschitz property. \Box

Exercise 41 (Fundamental theorem of calculus) Let {f: {\bf R} \rightarrow {\bf C}} be locally integrable, and let {F(x) := \int_0^x f(y)\ dy} (with the usual convention that {\int_0^{-x} = -\int_{-x}^0}). Show that {F} is differentiable at every Lebesgue point of {f}, and that {F' = f} almost everywhere.

— 7. {H^p} functions —

Another classical application of the Hardy-Littlewood maximal function lies in obtaining a satisfactory theory of (complex) {H^p} functions on the complex disk {{\mathbb D} := \{ z: |z| < 1 \}} for {1 < p \leq \infty}. (The theory for {p \leq 1} is more subtle and will not be dealt with here.)

Let {f: {\mathbb D} \rightarrow {\bf C}} be a holomorphic function. From residue calculus we have

\displaystyle  2f(z)-f(0) = \frac{1}{2\pi i} \int_{|\zeta|=r} \frac{f(\zeta)(\zeta+z)}{\zeta(\zeta - z)} d\zeta

and

\displaystyle  f(0) = \frac{1}{2\pi i} \int_{|\zeta|=r} \frac{f(\zeta)(r^2/\zeta+\bar{z})}{\zeta(r^2/\zeta - \bar{z})} d\zeta

when {|z| < r}, and so on averaging, and noting that {\frac{r^2/\zeta+\bar{z}}{r^2/\zeta - \bar{z}}} is the complex conjugate of {\frac{\zeta+z}{\zeta-z}} when {|\zeta|=r}, we obtain

\displaystyle  f(z) = \int_{|\zeta|=r} f(\zeta) \mathrm{Re}( \frac{\zeta+z}{\zeta-z} ) \frac{d\zeta}{2\pi i \zeta}

or in other words, if we set {f_r: {\bf R}/{\bf Z} \rightarrow {\bf C}} to be the function {f_r(\theta) := f(re^{2\pi i \theta})}, we have the reproducing formula

\displaystyle  f_s = f_r * K_{s/r}

whenever {0 \leq s < r < 1} and {K_{t}} is the Poisson kernel

\displaystyle  K_t(\beta) = \mathrm{Re}( \frac{e^{2\pi i \beta} + t}{e^{2\pi i \beta} - t} ) = \frac{1-t^2}{1+t^2 - 2t \cos 2\pi \beta}.

The kernel {K_t} is clearly non-negative; applying the above identity to {f \equiv 1} (or computing directly) we see also that {K_t} has mass {1}:

\displaystyle  \|K_t\|_{L^1({\bf R}/{\bf Z})} = \int_{{\bf R}/{\bf Z}} K_t\ d\theta = 1.

From Young’s inequality we thus obtain that for {1 \leq p \leq \infty}, the {L^p} norm of {f} is increasing on circles:

\displaystyle  \| f_s\|_{L^p({\bf R}/{\bf Z})} \leq \| f_t\|_{L^p({\bf R}/{\bf Z})}.

(Note that the {p=\infty} case is just the maximum principle.) In particular, the quantity

\displaystyle  \|f\|_{H^p({\mathbb D})} := \lim_{t \rightarrow 1^-} \| f_t\|_{L^p_\theta({\bf R}/{\bf Z})}

always exists. We say that {f} is an {H^p} function if {f} is analytic on {{\mathbb D}} and the norm {\|f\|_{H^p({\mathbb D})}} is finite. It is not hard to see that {H^p({\mathbb D})} becomes a normed vector space (and that {H^p({\mathbb D}) \supset H^q({\mathbb D})} whenever {p < q}); a little more work shows that it is in fact complete.

Exercise 42 For any {n \in {\bf Z}} and {g \in L^1({\bf R}/{\bf Z})}, define the Fourier coefficient {\hat g(n)} of {g} by the formula

\displaystyle  \hat g(n) := \int_{{\bf R}/{\bf Z}} g(\theta) e^{-2\pi i n \theta}\ d\theta.

Show that

\displaystyle  \hat K_t(n) = t^{|n|}

for every {0 \leq t < 1} and {n \in {\bf Z}}, and that

\displaystyle  \hat f_s(n) = (s/r)^{|n|} \hat f_r(n)

for every {f} holomorphic on {{\mathbb D}}, {0 \leq s < r < 1} and {n \in {\bf Z}}. Also show that {\hat f_r(n) = 0} for all {n < 0}, and that

\displaystyle  K_t * K_{t'} = K_{tt'}

for all {0 \leq t,t' \leq 1}. (Note that these identities can be proven either by complex analysis methods or by Fourier analysis methods; it is instructive to prove them both ways and compare results.)

The kernel {K_t} can be easily verified to obey the bounds

\displaystyle  |K_t(\theta)| \lesssim \frac{1/(1-t)}{\langle \mathrm{dist}(0,\theta)/(1-t) \rangle^2}.

This is enough to obtain the pointwise estimate

\displaystyle  |f * K_t| \lesssim Mf

where

\displaystyle  Mf(\theta) := \sup_{r > 0} \frac{1}{2r} \int_{\mathrm{dist}(\alpha,\theta) < r} |f(\alpha)|\ d\alpha

is the Hardy-Littlewood maximal function of {f}. From last week’s notes we conclude that for any {1 \leq p \leq \infty} and {f \in L^p({\bf R}/{\bf Z})}, that {f*K_t} converges to {f} in {L^p({\bf R}/{\bf Z})} norm, and by modifying the proof of the Lebesgue differentiation theorem we also see that it converges pointwise almost everywhere.

The definition of {H^p} strongly suggests (but does not immediately prove) that if {f} lies in {H^p}, then {f_t} should converge to some sort of limit {f_1} as {t \rightarrow 1^-}. This is indeed the case:

Theorem 43 Let {f \in H^p({\mathbb D})} for {1 < p < \infty}. Then {f_t} converges both in {L^p({\bf R}/{\bf Z})} norm and pointwise almost everywhere to a limit {f_1 \in L^p({\bf R}/{\bf Z})}.

Remark 44 The theorem fails for {p\leq 1}, as can be seen by explicitly computing using the function {f(z) := \frac{1+z}{1-z}}. When {p=\infty}, the pointwise almost everywhere claim is still true, but the convergence is not.

Proof: Let us first demonstrate weak convergence. For any {g \in L^{p'}({\bf R}/{\bf Z})} and {0 < t < 1}, we observe that

\displaystyle  \langle f_r, g * K_t \rangle = \langle f_r * K_t, g \rangle = \langle f_{rt}, g \rangle = \langle f_t * K_r, g \rangle \ \ \ \ \ (14)

where {\langle f, g\rangle := \int_{{\bf R}/{\bf Z}} f(\theta) \overline{g(\theta)}\ d\theta} is the inner product on {{\bf R}/{\bf Z}} (here we use the fact that {K_t} is real and even). Since {f_t * K_r} converges in {L^p} norm to {f_t} as {r \rightarrow 1}, we thus see that {\langle f_r, g * K_t \rangle} converges to a limit as {r \rightarrow 1}. Since {g * K_t} converges in {L^{p'}} norm to {g} as {t \rightarrow 1}, we conclude (from Hölder’s inequality and the uniform {L^p} bound on {f_r}) that {\langle f_r, g \rangle} also converges to a limit as {r \rightarrow 1}, thus {f_r} converges weakly. But as {L^p} is reflexive, the closed unit ball is also weakly closed, and we conclude that {f_r} converges weakly to {f_1} for some {f_1 \in L^p({\bf R}/{\bf Z})}, thus

\displaystyle  \lim_{r \rightarrow 1} \langle f_r, g \rangle = \langle f_1, g \rangle

for all {g \in L^{p'}}. Replacing {g} by {g*K_t} and using (14) we conclude

\displaystyle  \lim_{r \rightarrow 1} \langle f_t * K_r, g \rangle = \langle f_1, g * K_t \rangle,

and hence (since {f_t * K_r} converges to {f_t} in {L^p} norm)

\displaystyle  \langle f_t, g \rangle = \langle f_1, g * K_t \rangle = \langle f_1 * K_t, g \rangle.

This is for all {g \in L^{p'}}, thus we have

\displaystyle  f_t = f_1 * K_t.

Thus {f_t} converges pointwise almost everywhere and in {L^p} norm to {f_1}. \Box

Exercise 45 (Fatou’s theorem) Let {f \in H^p({\mathbb D})} for some {1 < p \leq \infty}, and let {f_1} be as in Theorem 43. Show that for almost every {\theta \in {\bf R}/{\bf Z}}, we have

\displaystyle  \lim_{n \rightarrow \infty} f(z_n) = f_1(\theta)

whenever {z_n \in {\mathbb D}} is a sequence of points converging to {e^{2\pi i \theta}} non-tangentially in the sense that {\angle (e^{2\pi i \theta} - z_n), e^{2\pi i \theta}} is uniformly bounded away from {\pi/2}. (Hint: first reduce to a fixed angle of non-tangentiality (e.g. all angles less than pi/2 – 1/n), and then build an appropriate “non-tangential maximal function”, formed by taking suprema over all points in a sector with apex {e^{2\pi i \theta}} and this fixed angle of non-tangentiality. Use the kernel bounds to bound this maximal function by the Hardy-Littlewood maximal operator.)

— 8. The Calderón-Zygmund decomposition —

For a function {f: X \rightarrow {\bf C}} on an abstract measure space, and any threshold {\lambda > 0} one has the basic decomposition

\displaystyle  f = f 1_{|f| \leq \lambda} + f 1_{|f| > \lambda}

into a “good” {g := f 1_{|f| \leq\lambda}} piece (bounded by {\lambda}), and a “bad” piece {b := f 1_{|f| > \lambda}} (larger than {\lambda}, but at least of small support). If for instance {f \in L^1(X)}, then we have the bounds

\displaystyle  \|g\|_{L^1(X)} \leq \|f\|_{L^1(X)}; \quad \|g\|_{L^\infty(X)} \leq \lambda

for the good piece and

\displaystyle  \|b\|_{L^1(X)} \leq \|f\|_{L^1(X)}; \quad \mu( \mathrm{supp}(b) ) \leq \frac{\|f\|_{L^1(X)}}{\lambda}

for the bad piece (the last inequality being Markov’s inequality). Thus both pieces inherit the {L^1} bound of the whole, but enjoy an additional useful property. This type of decomposition underlies tools such as the layer cake decompositions and the real interpolation method.

For arbitrary measure spaces {X} with no additional structure, this type of decomposition is about the best one can do to split {f} into “good” and “bad” parts. But if {f} has more structure – in particular some sort of metric or dyadic structure compatible with the measure – then one can do better, in particular one can select the bad piece {b} to be “locally oscillating” in a certain sense. This principle, which uses the same ideas that underlie the Hardy-Littlewood maximal inequality, is formalised in the Calderón-Zygmund decomposition, a fundamental tool in the Calderón-Zygmund theory of singular integrals.

To motivate the lemma let us first give a simple one-dimensional version.

Lemma 46 (Rising sun lemma) Let {I \subset {\bf R}} be a bounded interval, and let {f: I \rightarrow {\bf R}} be integrable, and let {\lambda \in {\bf R}} be such that {\frac{1}{|I|} \int_I f \leq \lambda}. Then there exist an at most countable family {(I_\alpha)_{\alpha \in A}} of disjoint open intervals in {I} such that
  • {f(x) \leq \lambda} for almost every {x \in I \backslash \bigcup_{\alpha \in A} I_\alpha};
  • {\frac{1}{|I_\alpha|} \int_{I_\alpha} f = \lambda} for every {\alpha \in A}.

Proof: By subtracting {\lambda} from {f} we may normalise {\lambda = 0}. We may take {I} to be half-open {I = [x_-,x_+)}. Define {F: I \rightarrow {\bf R}} by {F(x) := -\int_{x_-}^x f(y)\ dy}. Then {F} is a continuous function which starts at zero and ends up positive. Define a “maximal” version {F^*: I \rightarrow {\bf R}} of {F} by {F^*(x) := \sup_{x_- \leq y \leq x} F(y)}, then {F^*} is continuous non-decreasing which starts at zero and ends up positive. Let {\Omega := \{ x \in I: F^*(x) > F(x) \}}, then {\Omega} is an open subset of {I}, thus {\Omega = \bigcup_{\alpha \in A} I_\alpha} for some at most countable set of intervals {I_\alpha}. At the endpoints of each interval we have {F^*(x) = F(x)}, while on the interior of these intervals {F^*} is necessarily constant (why?). This gives the second desired property. For the first, one observes from Q7 that at almost every point where {f(x) < 0}, we have {F} differentiable with {F' < 0}, which implies that {x \in \Omega}, and the claim follows. \Box

As a corollary we have

Corollary 47 (One-dimensional rising sun lemma) Let the hypotheses be as in the above lemma. Then we have a decomposition {f = g + \sum_{\alpha \in A} b_\alpha}, where {g: I \rightarrow {\bf R}} is bounded above by {\lambda} with {\int_I g = \int_I f}, and for each {\alpha \in A}, {b_\alpha} is supported in {I_\alpha} and has mean zero. Furthermore, if {\lambda > 0} and {f} is non-negative, then {\sum_\alpha |I_\alpha| \leq \frac{\|f\|_{L^1(I)}}{\lambda}} and {\| b_\alpha \|_{L^1} \leq 2 \lambda |I_\alpha|}.

Proof: We set {b_\alpha := (f-\lambda) 1_{I_\alpha}}, and set {g} equal to {f} outside of {\bigcup_\alpha I_\alpha} and equal to {\lambda} inside {\bigcup_{\alpha} I_\alpha}. To prove the last two claims, we have

\displaystyle  \int_{I_\alpha} f = \lambda |I_\alpha|

so on summing and using the non-negativity of {f}

\displaystyle  \int_{I} f \geq \lambda \sum_\alpha |I_\alpha|

from which the former claim follows. Finally, from the definition of {b_\alpha} and the triangle inequality

\displaystyle  \|b_\alpha \|_{L^1} \leq \int_{I_\alpha} f + \int_{I_\alpha} \lambda = 2 \lambda |I_\alpha|

which is the latter claim. \Box

The proof of the rising sun lemma relies crucially on the ordered nature of the real line. For more general spaces, such as Euclidean spaces, it is preferable to use arguments that rely instead on metric or dyadic structure. We begin with a dyadic version.

Proposition 48 (Dyadic Calderón-Zygmund decomposition) Let {f \in L^1({\bf R}^d)} and {\lambda > 0}. Then there exists a decomposition {f = g + \sum_{Q \in {\mathcal Q}} b_Q}, where the “good” function {g} obeys the bounds

\displaystyle \|g\|_{L^1({\bf R}^d)} \leq \|f\|_{L^1({\bf R}^d)}; \quad \|g\|_{L^\infty({\bf R}^d)} \leq 2^d \lambda,

{Q} ranges over a disjoint family {{\mathcal Q}} of dyadic cubes, and each {b_Q} is supported on {Q}, has mean zero, and has the {L^1} bound

\displaystyle  \|b_Q \|_{L^1({\bf R}^d)} \leq 2^{d+1} \lambda |Q|.

Furthermore, we have the inclusions

\displaystyle  \bigcup_{Q \in {\mathcal Q}} Q = \{ M_\Delta f > \lambda \} \subset \{ Mf \gtrsim \lambda \}.

In particular from (3) we have {\sum_{Q \in {\mathcal Q}} |Q| \leq \frac{\|f\|_{L^1({\bf R}^d)}}{\lambda}}.

Proof: The arguments here will closely resemble that used to prove (3). Let us say that a cube {Q} is bad if {\frac{1}{|Q|} \int_Q |f| > \lambda}, and good otherwise. Call a bad cube {Q} maximal if {Q} is bad, but no cube strictly containing {Q} is bad, and let {{\mathcal Q}} be the collection of all maximal bad cubes, thus {{\mathcal Q}} is a collection of disjoint dyadic cubes, and we also clearly have {M_\Delta f \geq \lambda} on each bad cube. From the hypothesis {f \in L^1({\bf R}^d)} and monotone convergence we see that all cubes with sufficiently large side-length are automatically good. Thus every bad cube is contained in a maximal bad cube.

Now let {Q} be a maximal bad cube. The parent {Q'} of {Q} (i.e. the unique dyadic cube of twice the side-length containing {Q}) is good, hence {\frac{1}{Q'} \int_{Q'} |f| \leq \lambda}. Since {|Q'| = 2^d |Q|}, we conclude that {\frac{1}{|Q|} \int_Q |f| \leq 2^d \lambda}. Now set

\displaystyle  b_Q := (f - \frac{1}{|Q|} \int_Q f) 1_Q

and

\displaystyle  g = f (1 - 1_{\bigcup_{Q \in {\mathcal Q}} Q}) + \sum_Q (\frac{1}{|Q|} \int_Q f) 1_Q.

All the desired properties are then easily verified, except perhaps for the claim {\|g\|_{L^\infty({\bf R}^d)} \leq 2^d \lambda}. This claim is clear on each separate cube {Q}; the only difficulty is to show that {g} is bounded by {2^d \lambda} outside of {\bigcup_{Q \in {\mathcal Q}} Q}. But by construction we see that if {x \not \in \bigcup_{Q \in {\mathcal Q}} Q} and {Q \ni x}, then {Q} is good, and {|\frac{1}{|Q|} \int_Q g| = |\frac{1}{|Q|} \int_Q f| \leq \lambda}. On the other hand, the (dyadic version of the) Lebesgue differentiation theorem shows that {\frac{1}{|Q|} \int_Q f} converges to {f(x)} for almost every {x} as {|Q| \rightarrow 0}. Thus {|g(x)| \leq \lambda} for almost every such {x}, and we are done. \Box

Exercise 49 Let {{\mathcal B}} be the {\sigma}-algebra generated by the cubes in {{\mathcal Q}}, and the Borel subsets of {{\bf R}^d \backslash \bigcup_{Q \in {\mathcal Q}} Q}. Show that {g = \mathop{\bf E}(f|{\mathcal B})}.

Note that the total bad set {\bigcup_{Q \in {\mathcal Q}} Q} is given by the level set {\{ M_\Delta f > \lambda\}} of the dyadic maximal function. This suggests an alternate approach to the Calderón-Zygmund decomposition, in which one starts by identifying the total bad set (in this case, {\{ M_\Delta f > \lambda\}}), and then decomposes it into cubes or balls. A prototype decomposition of this type is

Proposition 50 (Dyadic Whitney decomposition) Let {\Omega \subsetneq {\bf R}_+^d} be an open set. Then there exists a decomposition {\Omega = \bigcup_{Q\in {\mathcal Q}} Q}, where {Q} ranges over a family {{\mathcal Q}} of disjoint dyadic cubes, and for each {Q} in this family {{\mathcal Q}}, the parent {Q'} of {Q} is not contained in {\Omega}.

Proof: Define {{\mathcal Q}} to be the set of all dyadic cubes {Q} in {\Omega} which are maximal with respect to set inclusion; the claim follows from the nesting property. (The condition {\Omega \subsetneq {\bf R}_+^d} is needed to ensure that every cube is contained in a maximal cube; the open-ness is to get every point of {\Omega} contained in at least one cube.) \Box

The property that {Q'} is not contained in {\Omega} implies the bounds

\displaystyle  0 \leq \mathrm{dist}(Q, {\bf R}^d_+ \backslash \Omega) \leq \mathrm{diam}(Q).

In many applications we need to complement the upper bound with a non-trivial lower bound. This can be done with a little more effort:

Proposition 51 (Whitney decomposition) Let {\Omega \subsetneq {\bf R}^d} be an open set and let {K \geq 1}. Then there exists a decomposition {\Omega = \bigcup_{Q\in {\mathcal Q}} Q}, where {Q} ranges over a family {{\mathcal Q}} of disjoint dyadic cubes, and for each {Q} in this family {{\mathcal Q}}, we have {\mathrm{dist}(Q, {\bf R}^d \backslash \Omega) \sim K \mathrm{diam}(Q)}.

Proof: Let {{\mathcal Q}'} denote those dyadic cubes {Q} in {\Omega} such that

\displaystyle  K \mathrm{diam}(Q) \leq \mathrm{dist}(Q, {\bf R}^d \backslash \Omega) \leq 5 K \mathrm{diam}(Q).

It is not hard to show that these cubes cover {\Omega}; indeed, given any {x} in {\Omega}, all one needs to do is to locate a cube {Q} containing {x} with diameter between {\mathrm{dist}(x, {\bf R}^d \backslash \Omega)/4K} and {\mathrm{dist}(x, {\bf R}^d \backslash \Omega)/2K}. The cubes are not disjoint; however if one lets {{\mathcal Q} \subset {\mathcal Q}'} be those cubes in {{\mathcal Q}'} which are maximal with respect to set inclusion, then the claim follows from the nesting property. \Box

Note that if {K} is large, the cubes in this above decomposition have the property that nearby cubes {Q, Q'} (in the sense that {\mathrm{dist}(Q,Q') \lesssim \mathrm{diam}(Q) + \mathrm{diam}(Q')}) have comparable diameter, thanks to the triangle inequality

\displaystyle  |\mathrm{dist}(Q,{\bf R}^d \backslash \Omega) - \mathrm{dist}(Q',{\bf R}^d \backslash \Omega)|

\displaystyle \leq \mathrm{dist}(Q,Q') + \mathrm{diam}(Q) + \mathrm{diam}(Q').

Since every cube is contained in a ball of comparable radius (with constants depending on {d}), we then conclude

Proposition 52 (Whitney decomposition for balls) Let {\Omega \subsetneq {\bf R}^d} be an open set and let {K \geq 1}. Then one can cover {\Omega} by balls {B} such that {\mathrm{dist}(B, {\bf R}^d \backslash \Omega) \sim_d K \mathrm{diam}(B)}, and such that each point in {\Omega} is contained in at most {O_d(1)} balls.

These decompositions can be used to prove some minor variants of the Calderón-Zygmund decomposition, which we will not describe in detail here.

Jordan Ellenberg — Eigenvalues of random p-adic matrices

I always felt there ought to be a good theory of p-adic random matrices paralleling the very-well-worked out real and complex story. I wrote a paper years ago with Jain and Venkatesh that proposed that a very reasonable model for the lambda-invariant of a random quadratic field would be the number of eigenvalues x of a large random matrix A over Z_p such that x-1 is not a unit. (The p-primary part of the class group, the quantity studied in the Cohen-Lenstra conjecture, is modeled by the cokernel of A-1, which is clearly related but not at all the same thing.

Anyway, we worked out a few simple statistics of random matrices over Z_p but got no further. Now Jiahe Shen and Roger van Peski have done much more! They are well on their way to a fully satisfying theory that mimics the archimedean story. For instance, they can exactly compute the pair correlation showing the familiar repulsion of eigenvalues from each other. And the pair correlation function has a somewhat mysterious (to me, and I think to them too) appearance of a theta function…

One reason we like to model arithmetic quantities by random matrices is that, in the function field case, Frobenius acts on etale cohomology via a p-adic matrix we know nothing about, and since we know nothing about it, we like to treat it as random in Haar measure. Is that justified? Maybe not, but here’s the good news: Shen has a followup paper where he shows (again, consistent with what happens in archimedean-land) that the eigenvalue statistics they find don’t depend sensitively on the exact distribution of the matrices, but rather are universal over a rather broad class of distributions. So that, I think, should make one feel more confident that Frobenii, too, have eigenvalues that look this way, and moreover that the analogous distributions in the number field case, where there’s no literal p-adic matrix at all, might follow suit.

The method here is interesting: we learned, over time, that a good way to get a handle on a random group G is to study the expected number of surjections from G to H, as H varies over groups (or groups in various special classes) — these are the natural moments of a distribution on groups. And in practice, they are often the exact statistics one is able to compute by geometric means. (See Will Sawin and Melanie Wood’s work for a much, much, much more elaborated categorical point of view on what counts as a moment.) Shen’s paper takes the view that a good notion of “moment” for a random p-adic polynomial P is the distribution of the p-adic valuation of the resultant of P with some fixed polynomial Z. These “Z-moments” turn out to also be very computable for characteristic polynomials of random matrices, and they also turn out to provide actionable information about eigenvalues. Nice!

Jordan Ellenberg — James Purdy, Narrow Rooms

A great novel if you like murder, sex between men, grudges, West Virginia, and long sentences.

“His eyes were as bright as ever, perhaps brighter, the disc of the pupil appearing to move like a white fire, but his face in general gave the impression of belonging to someone who never expected anything again.”

Purdy’s an unusual writer. Beloved by a few, hated by many reviewers, unknown to almost everyone. Didn’t really start writing until he was 40 (he was a Spanish professor at Lawrence College in Appleton for ten years before that.) Hung out with painters and jazz guys in Chicago. Admired by Langston Hughes and Dame Edith Sitwell, the latter of whom he had his ashes buried next to. Withdrew the rights to the only movie adaptation his work was ever going to get because he didn’t like the proposed lead actor. This reminiscence by Donald Weise gives a vivid picture of the cranky, difficult man.

How did I get into James Purdy? I was in Firestone Library in Princeton, in Special Collections, to see the unpublished J.D. Salinger stories. When I asked for that box, the librarian visibly rolled her eyes, because I think probably 80% of the people who go into Firestone Special Collections are there to see the uncollected Salinger stories. Wounded, crouched, I quickly formulated a way to recoup — I would just request another box, showing that I was not another loser Salinger groupie, but a scholar of mid-century American fiction who was looking at the Salinger in a purely comparative way, setting his unpublished work against that of — well, who? I didn’t know anybody else on the list. So I took a wild guess and asked for the James Purdy box. And then, having taken it, felt compelled to read it. And then, having read it, realized I was in the presence of something a lot better than the stuff Salinger correctly declined to anthologize. I think Purdy would have liked knowing that he’d gotten a reader via a mechanism he cared about a lot and had drawn closely: a young man’s pride and banged-up vanity.

October 04, 2026

Scott Aaronson My new course at UT Austin: AI Alignment Theory

This semester, I’ve been teaching a brand-new course, entitled CS395T AI Alignment Theory. Here’s the course description:

The astounding progress of AI over the past decade has been accompanied by a rising fear: do we really understand how to align and control powerful AI systems—how to get them reliably to do what we wanted, or would want them to do on reflection, rather than merely what we said? If we succeed at building general-purpose superhuman intelligences along the current paradigm, should we expect that development to go well for humanity? Can we modify the design, training, monitoring, or scaffolding of those intelligences to help ensure that it goes well? While there’s been a great deal of recent empirical work touching on these questions, this course will concentrate mainly on theoretical and mathematical foundations. As a warning, the theoretical foundations of AI alignment have not yet gelled into any one coherent body of results accepted as canonical by the field. Nevertheless, in this course, we’ll read and debate many of the conceptual and mathematical works that have been most influential in the AI alignment field, from both before and during the current LLM revolution. Student presentations, reports, and projects will play a central role.

I vividly remember encountering Eliezer Yudkowsky and his Sequences 20 years ago. I remember thinking: even if these people talk and act like crazy cultists, still, let me bend over backwards to be epistemically virtuous, and entertain their ideas on their merits, as very few academics would. Even if, of course, I ultimately end up rejecting the ideas, on the simple ground that powerful AI is such an absurdly remote prospect that it’s almost impossible to say anything useful about it today, outside the realm of speculative fiction.

For my failure to see what was coming, it seems like an appropriate punishment that I’m now, in 2026, effectively teaching a course on Yudkowsky Studies. And it’s the most important course I can teach.

Well, for some definition of “teach.” The thing about AI alignment is that there’s no textbook (though apparently ILIAD is working on one), no core of nontrivial theorems considered canonical by the field, no real body of mathematical theory at all. This makes it extremely different from the courses I’m used to teaching, like Quantum Information Science or Computability and Complexity.

So we’ve been running the course as a discussion seminar. Every session, a “rapporteur” presents an AI alignment research paper or other reading; then I and others ask questions and discuss. Some of the readings (like Omohundro on the “basic AI drives,” or Hadfield-Menell et al. on the off-switch game) predate the current LLM revolution, while others (like the METR report on the HuggingFace incident or Dario Amodei’s “We Must Pace the Frontier”) are so timely that they were only released while the course was underway. Most are somewhere in between.

I expected to have to make a case to students about why AI alignment is a pressing concern, why it’s no longer science fiction, etc. There was huge demand for the course, and while of course there’s a selection effect, the students who’ve shown up have been extremely engaged, sometimes criticizing the assigned papers for not taking existential risk seriously enough.

Perhaps unsurprisingly, we didn’t get that criticism about our very first assigned reading, which was Eliezer Yudkowsky’s 2022 essay AGI Ruin: A List of Lethalities—one the most canonical statements of what Eliezer believes and why that’s shorter than a book. Which brings me to the topic of the rest of this post! Our rapporteurs are not merely presenting the papers in class; they’re also submitting written reports about what the papers said, what their own thoughts were, and what were the highlights of the class discussion. And, with student permission, I’ll be sharing those reports on this blog!

So, without further ado, I present to you our first report, on Eliezer’s list of lethalities, by Tennyson Bardwell, who I thank for his work. Feel free to discuss in the comment section; some of the students might also chime in. Expect more reports here over the coming weeks.


“AGI Ruin: A List of Lethalities” by Eliezer Yudkowsky: Rapporteur Report by Tennyson Bardwell

UT Austin has a new Computer Science course this fall. Alongside familiar graduate-level classes such as Advanced Computer Networks and Convex Optimization sits CS 395T: AI Alignment Theory, taught by Scott Aaronson. This is one of a growing number of AI Alignment courses taught at academic institutions. Just as concerns over catastrophic consequences for misaligned AGI systems reach a broader public discourse, Eliezer Yudkowsky—one of the loudest voices in the field and author of the first assigned reading in Professor Aaronson’s course—is declaring the cause hopeless.

Thus, the students of AI Alignment Theory began their semester by reading a laundry list of critical problems in AI Alignment research, how failure to solve those problems will result in catastrophic consequences, and the reasons to be pessimistic about both past and future progress on these problems. The essay by Eliezer, titled AGI Ruin: A List of Lethalities and posted to his popular community-driven website LessWrong in 2022, is divided into three sections.

Section A roughly describes the magnitude of the AI Alignment problem. That is, the magnitude of the consequences for a complete failure to align an AGI system to human values before construction. It posits that AGI would quickly catch up to all human knowledge simply by learning from existing human productions (colloquially referred to as “eating the internet”) and then, nearly as quickly, begin to meaningfully surpass human knowledge. AlphaGo Zero is presented as a model both for how this might happen, and how it might be difficult to correctly predict beforehand. Many believed that AlphaGo’s success in the board game Go was chiefly attributed to its ability to learn from the extensive history of human-played games. Less than a year after AlphaGo beat the best human player, the successor system AlphaGo Zero surpassed the original AlphaGo. Unlike its predecessor, AlphaGo Zero was trained in just three days by exclusively playing against itself without seeing a single human game.

This quick ramp from AGI to super-intelligence would pose a different sort of problem than humans are generally used to dealing with. Unlike traditional problems in science and engineering, the consequence for a failed attempt might not leave room for another try. An intelligent entity with a misaligned goal would be well aware that it stands in opposition to humans, and might act deceitfully until in a position to act openly against humans without jeopardizing its own survival. Since most goals benefit from control of power and resources, it seems likely that nearly any goal-driven intelligence would have ample opportunity to be misaligned with human desires.

Section B describes reasons why, by default, any AGI that humans build using current methods is likely to be unaligned even if considerable attention is paid to the topic. This “current method” is gradient descent. That is, incremental progress with respect to some loss function which “punishes” a model for undesirable behavior. A notoriously elusive property of such trained models is the ability to generalize out of their training distributions. To train a primitive model to be aligned to humans might involve learning a great many behavioral rules. However, the sorts of rules needed to keep a drastically smarter agent in check might not always be relevant to simpler models (e.g., “do not emotionally dysregulate humans you speak with” might not be relevant to a simpler model that is less able to reliably get under the skin of humans it operates with, or which is assigned tasks in training which do not benefit from such anti-social behavior).

Eliezer focuses on the misalignment of humans with their creators (evolution or evolutionary pressures) as a critical data point for reasoning about misaligned intelligent systems. Despite being a generally slow process, evolution eventually created a runaway intelligent system (Homo sapiens) which proceeded to dominate the globe, decimate related species, and eventually (it is forecasted) effectuate population decline. That last development is arguably in opposition to the sole imperative demanded by evolution: to reproduce.

Section B also makes time for criticism of the most popular paths toward AI alignment, including interpretability (unworkable, and attempting to train on it evokes Goodhart’s law, incentivizing deceit), using multiple AIs to maintain a balance of power (it is not clear how multiple strong AIs unaligned with humanity results in better outcomes for the weak humans), and corrigibility (it seems impossible to motivate an AI system to effect outcomes without also motivating it to desire its own survival to effectuate said outcomes).

Section C describes a bleak state of affairs in which veterans in AI alignment are unsatisfied with current progress and do not have a plan to deliver tangible solutions before the advent of AGI systems. In particular, Eliezer describes recent results as showy but useless. He believes that even with additional funding, the lack of appropriate evaluation mechanisms will prevent the most effective researchers from rising to the top.

A summary of the landscape, as described by Eliezer, in the flowchart below.

Figure 1: A flow chart of (select) paths described by Eliezer in his essay. A common feature of this flow chart is that many “good states”—such as disabling a misbehaving AGI or choosing not to build an AGI—are not “final” states in the sense that they are not permanent solutions. Such a state merely represent the avoidance of a single potential disaster, rather than the emergence of a new stable world state. Hence, these nodes posses back-arrows.

Despite the bleak content, Eliezer’s colorful prose inspired a lively class discussion. Before this discussion started, a survey was taken of the class’s predictions for various outcomes of the AGI in the coming years (with the full results below in figure 2). This survey asked students for their opinion of a number of statements. Each of these individual statement, if true, would reduce concerns of catastrophic AI-driven disasters. For example, when asked “How much do you agree with the statement: Humans will choose to not build AGI” half of respondents said they strongly disagreed with high confidence (agreement = 1, confidence = 5). Students also generally disagreed with the statements:

  • “AGI will not be technically feasible in our lifetime”
  • “(hyper-)AGI will not make extremely obviously unethical decisions”
  • “No reason is individually sufficient, but taken together they provide justification to not fear AGI”

There was a divergence in responses regarding interpretability, corrigibility, and “other” AI alignment research. In the latter two cases, a plurality of respondents (about a quarter) agreed strongly with statements that such research would defang AGI (agreement = 4, confidence=4), while most other responses express various levels of agreement with low confidence. However, when asked about the likelihood of interpretability research defanging AI, the pessimistic voices were more united. A quarter of responses still expressed the same optimism, but roughly half expressed pessimism (agreement ≤ 2) with half of those expressing at least moderate confidence (confidence ≥ 4). Based on the following discussion, this might have been caused by more familiarity with interpretability research, including first-hand experience.

The only statement with general agreement was “(hyper-)AGI will understand human intentions better than we can code it.” However, it should be noted that no statement such as “AGI will respect human desires, as it understand them” was asked on the survey.

Figure 2: Class Survey Results; conducted before a class-wide discussion. Note that students were instructed to answer confidence = 1 when they had not previously considered the statement, to answer confidence = 3 when they felt there were strong arguments on both sides, and to answer confidence = 5 when they possessed well-considered resolve.

After the survey was completed, the results were displayed as an open discussion began. Similar to recent empirical research from frontier labs, interpretability research received more airtime than in Eliezer’s article. Students disagreed first about the definition of interpretability: whether it refers to the ability to interpret a model’s behavior solely by its weights, to interpration via repeated probing of the model in a sandbox, or whether it can also refer to the modern chain-of-thought traces. Regardless of how it was defined, however, participants were either pessimistic or very pessimistic about interpretability research broadly. One student criticized common misunderstandings of chain of thought. Rather than being a verbatim copy of the models internal dialog, it is instead a superficial summary of the complete thought state and routinely produced gibberish, such as rarely used Chinese characters in the middle of otherwise English reasoning.

A popular topic was the exact shape and speed of a recursive self-improvement loop. If it takes place slowly, then what might we learn from “near misses” such as the Hugging Face incident? The number of near misses we are able to learn from before AI possesses sufficient power to prevent further iterations could depend on this curve, with some students arguing that the sheer number of humans, as well as their default robustness in the physical world compared to AI systems means that AI-driven extinction events are still a long way off. Bolstering this “slow take-off” opinion are rumors that AI already plays a major role in model development which could be interpreted as the start of this process.

Some criticized a focus on “solving ethics” as a needlessly high bar that distracts from the more mundane tasks dominating AI alignment work. In particular, the student volunteer who presented this paper (and the author of this report) included a section on “Ethical Dilemmas” in their presentation. Among arguments against focusing on abstract moral philosophy, Professor Aaronson cites Eliezer to emphasize that any alignment at all is difficult, not just in morally gray cases:

When I say that alignment is difficult, I mean that in practice, using the techniques we actually have, “please don’t disassemble literally everyone with probability roughly 1” is an overly large ask that we are not on course to get.

In response, I argue that some examination of everyday decisions with a critical lens—such as telling white lies to loved ones or consuming animal products—can help disabuse us of the notion that goodness emerges in every sufficiently intelligent agent.

One of the most interesting discussions was about the difference between state-of-the-art LLMs and the theorized AI agents long discussed in rationalist discourse. Since current LLMs “mimic the human distribution,” they come preloaded with extensive understanding of human social norms and moral behavior. This makes constitutional alignment (the current practices of using system prompts to establish ground rules) extremely effective. This might either fundamentally change the orthogonality thesis, or provide a new tool to better approximate human judgment in complicated situations.

Of all the points made, the one I found most interesting was simply (paraphrased):

I think human-alignment is just very tractable

Here, “human-alignment” refers not to AI alignment with human values, but cooperation between different humans. More specifically, it refers to the ability for human societies to choose not to rush recklessly into larger-and-larger AI systems. In an academic course focused on the technical problem of AI alignment, this was a reminder to not completely discard policy discussions in the believe that they lack any value. After all, many destructive technologies have been previously contained by international agreements. Notable examples include nuclear weapons and engineered plagues. However, even this was a contentious topic. The main criticisms were (1) the extreme “dual-use” nature of AIs for both peaceful growth and warfare, and (2) the greater danger for AI escapes even after taking precautions to prevent it. However, in the interest of ending on an optimistic note—unlike the assigned reading—it is on this belief in human cooperation that I will leave you.

Doug Natelson — The arXiv - where it's been and where it's going

Back in the ancient mists of time, scientists and mathematicians would circulate preprints of their articles among friends and colleagues via the postal service, as a courtesy, to get feedback and to try to make sure people in the community were aware of their forthcoming work.  As the wikipedia entry says, with the advent of widespread LaTeX and the development of the web, Paul Ginsparg (then at LANL) put together an html-based site for electronic sharing of preprints, initially at xxx.lanl.gov (back before "xxx" in URLs was the kind of thing filtered and blocked by employers).   In 2001 he moved to Cornell, and by then the lab was perhaps relieved to see the site, rebranded as the arXiv, shift to Cornell's library/repository infrastructure.   PIs my age remember (fondly? maybe?) the old days of the arXiv, when Prof. Ginsparg's rather dry sense of humor pervaded the site.  The skull-and-crossbones logo.  The "help"/FAQ pages that basically said, "if you can't figure out how to .tar.gz all of your necessary LaTeX files, and you can't figure out how to make your .eps figures small, maybe you should reconsider whether you're smart enough to be sharing your ideas here".  The arXiv was for preprints, without peer review (though interesting follow-on sites like Scirate now exist for organized commenting on the articles).

From these modest beginnings, the arXiv has grown enormously, including imitators/spin-offs such as chemrxiv and biorXiv and socarXiv.  The arXiv has recently become an independent nonprofit, hired a CEO, secured multiyear philanthropic support, and hosts over 3 million articles.  It's been interesting seeing some level of complaints online about some of these steps, but when the audience is so large, not everyone is going to be happy.  Rapid growth has been a major issue - see here for a graph of monthly submissions:
The exponential rise (except for a slight pandemic-correlated shoulder) has been problematic, especially recently.  One hallmark of the arXiv over the years has been its ability to function with comparatively minimal need for "moderation".  Early on, one consequence of the minimalistic help and moderate technical entry barrier was that it was unusual for fringe/pseudoscience to make its way onto the server.  (Hence the establishment of viXra.)  With the ease of cranking out properly formatted readable manuscripts using AI, clearly the arXiv has been struggling.  If 10-15% of submissions need some kind of human intervention or review, the support needs are rapidly outpacing the limited count of support staff.  There can be substantial backlogs.  To help deal with this, the arXiv recently updated its policies regarding AI-generated content (and AI cannot be a co-author, because the AI tools cannot take responsibility for content), and most recently has had to limit submission rates to two papers per month per submitting author.  These moves, too, have drawn some criticism (e.g. here).  Personally, I think the operators of the arXiv face an incredibly challenging environment and are doing the best they can - the idea that they are making moves because they are establishment sticks in the mud who don't understand the New Way of Doing Science is just wrong-headed.

It's completely unclear where all this is heading.  Exponential growth in nature signals instability and does not continue forever. If proponents of very heavily AI-driven research want to establish a repository specifically for that work, that's up to them.  [It is very on brand for the hard core AI advocates to argue that the arXiv is somehow morally obligated to host everything (regardless of hardware or personnel costs) so that future AI tools can read everything (a repository growing too quickly for human researchers to keep up) and summarize it.]

One overarching point that should come up in any arXiv discussion: The arXiv has become a global repository for an enormous amount of human knowledge, without charging anyone publication fees.  This should make interested parties think reallllllly hard about economic models of for-profit publishers. 


October 02, 2026

Matt von Hippel — Beginnings Don’t Matter as Much as You’d Think

I’ve met people who think they’re uncomfortable with evolution, but when you actually talk to them, they’re worried about something very different. They ask, “How could something come from nothing? How could life come from non-life?”

Biologists aren’t sure of the origin of life. They’re working on it, there’s a whole research field on what the experts call abiogenesis. But it’s hard going, because there’s so little direct evidence.

There is a lot more evidence for evolution. Evolution isn’t a theory of where life comes from, it was never meant to be one. It’s a theory that explains the copious evidence we have from the history of life, from the fossil record to genetic comparisons to leftover features in related animals. It’s a theory that tells you what to expect when you already have some life, and wait a few generations.

Evolution and abiogenesis are different ideas, with different domains. You can have one without the other. And when you already have life, and want to understand it, evolution is quite a bit more useful than abiogenesis.

There’s a similar story with the big bang.

Some people get mystified at the idea that the big bang made something out of nothing. But that’s not really how the big bang works.

It’s not just that the big bang wasn’t the explosion you imagine, a single point expanding in an empty space. Rather, it was a time when the entire universe, everywhere that anything could be, was in a hot dense state, not empty but brim-full.

It’s that the most important part of the big bang is what happened next. As the universe cooled, things spread away from each other, like the residents of Hilbert’s Hotel all moving one room apart. Clumps formed, electrons slowing down and getting caught by protons to make atoms, dust pulling on dust until it collapsed into stars.

The patterns of a universe that cooled this way are distributed over the sky. They tell us the kinds of atoms we expect to see in spectra of stars, the distribution of galaxies, the ripples in the afterglow of the first light to avoid getting absorbed by hot plasma. Those patterns are the core of physical cosmology, the bulk of the field’s research and its strongest argument.

In contrast, the question of where that hot dense state came from is murkier. There are a variety of pictures, different attempts to approximate a context where gravity’s quantum properties should be especially relevant by people who still don’t have a clear idea of how to think about quantum gravity.

But while the question is murky, it’s also just not very useful. Wherever that state came from, knowing it exists is usually enough to chart the rest of the universe’s history. In fact, it may even be impossible for us to know what happened before a certain time: we have only one sky’s worth of evidence, and eventually that evidence runs out.

People are used to created things: food, clothes, cars. Created things don’t change in complicated ways over time, for the most part, just break down. To understand a created thing, understanding its origin matters.

But science is full of stranger things, things with a life, or dynamics, of their own. Natural phenomena change, swiftly becoming something other than what they began as. Understanding them means understanding those changes, much more than it does understanding how they began.

September 29, 2026

Scott Aaronson My “Knowmads” podcast on science and AI

Or click here if the above doesn’t work.

Recorded in-person in my office at UT Austin, with a bulleted list containing “ARC,” “Scalable Oversight,” and “Models” behind me on my blackboard for some reason (I no longer remember who put those there or why). 90 minutes long. Sometimes you see my disembodied arm waving in midair because of the way the cameras are combined. As always, I strongly recommend 2x speed for the correct experience.

This might actually be one of my best podcasts ever, although I wasn’t planning on that! Thanks so much to Bhavay Tyagi and Prachi Garella for driving all the way from Houston to record it.

Here’s a strict subset of the topics we covered:

  • The story of AI models solving the Navier-Stokes Millennium Problem, insofar as it’s known
  • Can recent AI proofs be called “truly creative”?
  • The history of AI before the LLM revolution
  • What do we mean when we call LLMs “black boxes”?
  • The achievements of the field of interpretability
  • What exactly happened in the OpenAI/HuggingFace incident
  • Must we avoid all “anthropomorphizing language” when discussing the HuggingFace incident? (spoiler alert: no)
  • Examples of major open problems in quantum computing theory that I cared about for decades and that AI models have recently solved
  • Effects of the current AI cataclysm on the math community, especially students
  • What annoys me the most when I listen to AI talks
  • My experiences at OpenAI, why they hired me, and the watermarking work that I did there

Enjoy!

More AI-related content coming soon, as this blog—like much of the rest of the world—continues its transition to “all AI, all the time” (except still 100% written by an aging, deteriorating biological brain)


And for those who just can’t get enough of my rocking back and forth, using too many filler words, as I explain theoretical computer science! Here’s a second podcast, this one mainly on quantum computing, with Seb Agertoft, who I thank for doing it. Enjoy!

Doug Natelson — Annual Nobel speculation thread


It's that time of year yet again.  The physics Nobel will be announced next Tuesday, and the chemistry prize on Wednesday.  Who will it be this time?  Please speculate in the comments.  As is my annual futile tradition, I will put forward that the physics prize could be Aharonov and Berry for geometric phases in physics (even though Pancharatnam is intellectually in there and died in 1969).  This is a long shot, as always, especially since last year's prize for “for the discovery of macroscopic quantum mechanical tunnelling and energy quantisation in an electric circuit” was condensed matter related.  Perhaps optical metamaterials, with Yablonovitch, Smith, and Pendry?  (Though that's another one where picking just three names is challenging.)  Astro-related is likely due, so perhaps something CMBR related?

September 28, 2026

Doug Natelson — Brief science items - September 2026 edition

Several science items of interest from recent weeks.  As always, apologies for missing some, which I'm sure to have done.

  • A month ago, Premi Chandra, Piers Coleman, and Clare Yu published a really nice memorial biography of Phil Anderson, one of the great scientists and characters of 20th century physics.
  • A few days ago Dam Son, an outstanding condensed matter theorist at U Chicago, posted a paper on his site that resolves a math issue that had been lingering related to a well-known paper from back in the heyday of anyon superconductivity.  The authors had always been afraid that their approach accidentally violated a sum rule.  It turns out, the authors had just misplaced a factor of 1/2, and their approach was actually exactly right.  The really novel bit here is that the paper is written as if it is single-authored by Claude, and acknowledges Dr. Son for prompts that led to the result.  See here for an interesting twitter thread on this via Sankar Das Sarma.  
  • Tangentially related, Anthropic and Matt von Hippel achieved a new result, a 9-loop perturbation theory calculation based on N=4 super Yang-Mills theory.  These kinds of mathematically virtuosic calculations are exactly the sort of task that AI tools to which are extremely well suited now.  
  • Three weeks ago, a neat paper appeared in Science Advances.  These folks used quantum interference of a Bose-Einstein condensate to test the equivalence principle in a quantum system.  The basic idea is, you take an ultracold atomic gas in a well-defined quantum state.  You split it and toss one component of it upward, while you hold the other component of it fixed in the lab frame. (This work is a descendent of this approach, which was happening in the lab above mine in back when I was in grad school.) The upward-thrown component accumulates quantum phase as it rises in the lab gravitational field, slows to a stop, and comes back down.  There is a specific amount of phase difference between the two components predicted by the equivalence principle (which says that inertial mass and gravitational mass should be exactly the same), and that's what the authors find.
  • A couple of weeks ago, this paper appeared (shoutout to the first author, who is a Rice undergrad alum).   The authors fabricated a nanomechanical resonator made out of LiNbO3 and coupled it to a qubit to act as a measurement device.  Remarkably, through the qubit they are able to see transitions between individual vibrational quantum numbers in this many-atom mechanical resonator.  This is quite impressive, and it opens up many possibilities for transduction between different quantum degrees of freedom.  
More soon.

September 27, 2026

John Preskill — Marcus theory and Marcus practice

Rudy Marcus was 91 years old when I took a course from him. His age was, arguably, not his most remarkable quality.

The course took place during the second spring of my PhD. I was completing not only the academic year, but also my course requirements. Why not, I figured, indulge in traditional statistical mechanics? Statistical mechanics neighbors, and partially overlaps with, thermodynamics. Modern approaches to statistical mechanics include fancy toolkits imparted in physics courses: the renormalization-group method; Ginzburg–Landau theory; and the latter theory’s successor, topological order. I craved a more traditional approach, as won’t surprise readers of this blog. So I ditched the physics course list and signed up for Chemistry 166.

Rudy didn’t disappoint. He began the course with a tradition passed down from a founder of thermodynamics: Boltzmann’s H theorem. The theorem amounts to the first argument ever published for the second law of thermodynamics: every (sufficiently large) closed, isolated system’s entropy increases or remains constant; it doesn’t decrease. Rederiving Boltzmann’s H theorem, I felt as I would while holding a lace collar worn by Queen Elizabeth I: as though I were touching history. 

Rudy proceeded through more of the greatest hits in statistical mechanics. For instance, the Fokker–Planck and Langevin equations describe random processes. Examples include the subject of one of Einstein’s most famous papers: the motion of a pollen grain suspended in a liquid and buffeted by the liquid’s molecules. Chemistry 166 provided much of the bread and butter, meat and potatoes, and even tofu and edamame of a thermodynamicist’s education.

Rudy advanced step by step, rederiving every result in class. He recommended a textbook; but I refer to my lecture notes, rather than to the text, to refresh my memory about course topics nowadays. When I encounter complex integrals (a certain type of calculus) in statistical mechanics, I think back to Rudy’s treatment of them. The course also crystallized my understanding of the fluctuation–dissipation theorem, which describes systems perturbed slightly out of equilibrium; examples include a magnet subjected to a weak magnetic field.1 For the course’s final project, I studied quantum master equations—which featured in a Quantum Frontiers post afterward.

No less than his explanations of science, Rudy’s enthusiasm for science impressed itself upon me. Again, he taught Chemistry 166 at age 91. He continued to collaborate on research. Whenever I saw him, even after the course ended, he asked for news about quantum information theory—which he didn’t work on. 

Two and a half years after the course, Rudy gave a speech at a dinner in honor of a couple’s engagement. The groom was pursuing a PhD in applied physics, and the bride worked as an engineer. The groom asked if Rudy had advice for young scientists. Rudy responded immediately: plenty of science remains to be done, so keep exploring.

During his speech, Rudy described his upbringing in Montreal. His high school had produced a “who’s who” of Canadians, in his words—and not because the school demanded high tuitions or offered tutors and social connections. Discrimination pushed Jewish working-class children out of other schools and into Baron Byng, where some students worked hard enough to thrive. Alumni include artists; judges; physicists; William Shatner, who played Captain Kirk in the original Star Trek series…and Rudy Marcus.

Which leads me to the quality arguably more remarkable than Rudy’s teaching Chemistry 166 at age 91: he’d won a Nobel Prize in chemistry. Unlike most chemists, Rudy worked as a theorist, rather than an experimentalist. He developed a framework now called Marcus theory. It predicts the rate at which electrons hop between molecules. I can’t tell you much more about Marcus theory because I don’t know much more about it: Rudy had enough humility that, to my memory, he mentioned his theory only once in class, in passing.

Although I know little about Marcus theory, I’ve seen much of Marcus practice. In 2022, I emailed Rudy to ask where a holiday card could reach him. The pandemic had isolated enough people that I’d determined to reach out to more acquaintances. Rudy replied, “I have been working at home, meeting twice a week on zoom with my now small research group.” He was 98 years old. His curiosity, learning, mentoring, and exploring continued.

Rudy passed away this July, five days before his 103rd birthday. I hope to learn Marcus theory someday. But I’d be even more grateful to undertake Marcus practice for even a decent fraction of the time for which he did.

1How rapidly does the system respond to the perturbation? This nonequilibrium response depends on a correlation function evaluated on an equilibrium state, according to the fluctuation–dissipation theorem. To understand why, imagine preparing the system in a thermal state, perturbing the system at an early time, and measuring the system later. What information can you extract about the perturbation? A two-time correlation function encodes this information. Imagine Fourier-transforming a two-time correlation function. The Fourier transform is proportional to a second derivative of a free energy, according to the fluctuation–dissipation theorem. (The second derivative should sound plausible because it depends on a two-time correlation function.) Second derivatives of free energies equal response functions, such as the magnetic susceptibility. Therefore, a nonequilibrium response depends on an equilibrium correlator.

Tommaso Dorigo — Flying With Gamma-Ray Counters: Another Test Or Two Of The Radiacode Zero

Flying With Gamma-Ray Counters: Another Test Or Two Of The Radiacode Zero

Yesterday I traveled all day, moving my family back to Lulea from Padova. The trip is long because there is no direct connection from Venice to Stockholm (Norwegian has one, but I prefer to avoid them as they canceled my flight recently).

Tommaso Dorigo
Categories

John Preskill — Nicole’s guide to writing and editing

Freshman year of college, I took a writing seminar from German-literature professor Ellis Shookman. Professor Shookman loved Mozart’s music, he told us early in the term. He listened to Mozart on the radio while driving from campus to Boston. Static might mar the transmission, but he could often turn up the volume and continue enjoying the program. Sometimes, the static worsened during the drive. It could worsen and worsen, until Professor Shookman’s frustration outweighed his delight at listening. He’d switch off the radio.

As Professor Shookman loved listening to Mozart’s music, he loved reading about students’ ideas. Yet static can mar a piece of writing: infelicities in grammar, structure, composition, word choice, and more. If enough infelicities obscure the writing, the frustration of reading outweighs the benefits. Professor Shookman will quit reading.

Professor Shookman marked up our essays with a blue pencil that achieved the status of legend among his students. If you’ve written a paper I’ve coauthored, you’ve probably received PDF drafts replete with green highlighting.1 A sticky note explains the reason for each highlighting: “Singular–plural mismatch.” “Active voice >> passive voice.” “Let’s clue the reader in as to this formula’s meaning before lobbing the math at them.” 

Over the past year, I’ve catalogued the suggestions I write most often on paper drafts. The comments embody principles gleaned from Strunk and White’s The Elements of Style; the Physical Review style guide; other writing guides I esteem; literature whose writing I esteem;2 collaborations with professional editors; and writing instructors, including Professor Shookman. Each section below begins with more-important principles, shading into more-nuanced ones.

Please use and disseminate these principles. Train your favorite large-language model (LLM) on them, and have the LLM critique your manuscripts. Instruct it to use green highlighting if you wish. Even if the LLM suggests fixes initially, tell it to stop offering suggestions later, so that you can devise the solutions: train not only the LLM, but also yourself. I hope to enjoy your papers as much as Professor Shookman enjoyed his sonatas.

  1. Organization
    1. Motivate your work; then, present it; and then, explain its physical significance.
    2. Begin each paragraph with a topic sentence.
    3. Begin each section, apart from the introduction and conclusion, with (i) a statement of the takeaway and (ii) an outline of the section. When outlining a section, hyperlink to each subsection. Similar guidelines concern subsections and subsubsections.
    4. Before presenting a piece of math, sketch its meaning and origin. This strategy enables the reader to understand the math as soon as they encounter it. If you throw math at the reader without introducing it, the reader will have to squint at the symbols for a while to figure out what the expression means and where it comes from.
      • Example: To calculate the average work, we substitute the Hamiltonian formula (10) into the definition (12): [equation].
    5. Most citations belong at the ends of (i) sentences and (ii) phrases concluded with commas. Put a citation elsewhere only if you have a compelling reason for doing so.
    6. Bridge each component of your writing to the next component; the next shouldn’t sound like a non sequitur.
      • Suppose that the next sentence refers to (i) a topic mentioned in the previous sentence and (ii) a new topic. Mention (i) before (ii).
        • Example: Smith et al. applied control theory to the extent possible. The attempt led to intractable equations, unlike our approach.
        • Example of a broken bridge: Smith et al. applied control theory to the extent possible. Our approach does not involve intractable equations, unlike theirs.
    7. Whenever you tell a story, tell it from start to finish, step by step. Derivations, proofs, and descriptions of experiments qualify as stories.
      • This guideline extends to descriptions of experimental setups and of mathematical objects. For example, imagine referring to an element of a subgroup of the group generated by some operators. Did you have to read the preceding sentence multiple times to process it? The sentence begins at the end of a story, then rewinds to the story’s beginning. This structure impedes understanding. The subgroup forms the context for the subgroup element, which one can’t grasp until hearing about the subgroup. The subgroup participates in a similar relationship with the group, as does the group with its generators. Therefore, one should introduce the generators, then the group, then the subgroup, and then the subgroup element.
  2. Word choice
    1. Use strong, specific words, rather than weak words.
      1. Verbs and nouns are stronger than adjectives and adverbs.
      2. Choose specific verbs (e.g., “prepare,” “evolve,” and “measure”), rather than vague, general verbs (e.g., variants of “to be” and “take,” as in “take a measurement”).
    2. Avoid statements such as “we investigate,” “we study,” and “we analyze.” Such statements don’t relate that you’ve accomplished anything. State what you’ve accomplished. Verbs such as “prove,” “test,” “confirm,” “discover,” and “find” achieve this goal.
    3. Adverbs such as “importantly” and “remarkably” pollute scientific writing with the authors’ opinions. Demonstrate that a claim is important or that a result is remarkable; then, leave readers to draw their own conclusions. Those conclusions will coincide with yours if you’ve demonstrated your point.
    4. Use the active voice, rather than the passive voice. Take responsibility for your work. Editors of high-impact scientific journals have endorsed this advice.
    5. Refer to yourself when necessary and only when necessary.
      • Example of unnecessary reference to self: We use the superscript “max” to signify the maximal Fisher information.
        Preferable alternative: The superscript “max” signifies the maximal Fisher information.
      • Example of unnecessary reference to self: Our results establish several opportunities for future research. First, we can implement the experimental proposals.
        Preferable alternative: Our results establish several opportunities for future research. First, one can implement the experimental proposals.
      • You may use the first-person plural when escorting the reader through a derivation.
        • Example: We substitute from Eq. (1) into Eq. (2).
    6. If you’re the only author, don’t use the plural (“we,” “our,” etc.). The usage is inaccurate and misleading. It portrays you as dodging responsibility for your work by dispersing that responsibility across the scientific community.
    7. Avoid dangling modifiers.
    8. Pair every verb with the appropriate noun.
      • Example of grammatically incorrect text: Equation (1) follows by calculating the sum.
        • One should pair the verb “calculate” with the noun “we,” because “we” undertook the calculating. However, this example’s author omitted the noun out of squeamishness about using the first person in a scientific document. Hence the sentence says that the equation calculates the sum. Equations can’t calculate sums.
      • Examples of correct alternatives
        • We derived Eq. (1) by calculating the sum.
        • Equation (1) follows from the evaluation of the sum.
        • Calculating the sum yields Eq. (1).
    9. Avoid empty subjects.
    10. Include no unnecessary words.
      1. “So-called” is unnecessary.
      2. “Note that” and “We note that” are unnecessary.
      3. Several phrases often preface mathematical statements but are unnecessary: “we have,” “we have that,” “it holds that,” and “it follows that.” One can better serve the reader by prefacing the mathematical statement with (i) a derivation or (ii) a prose description of the statement.
      4. Never write “is equal to”; “equals” is more concise.
      5. Never write “is able to”; “can” is more concise.
      6. Never write “gives an upper bound to” or “places an upper bound on”; “upper-bounds” is more concise. Analogous statements concern lower bounds.
      7. Never write “a large number of”; “many” is more concise. Never write “a small number of”; “few” is more concise.
      8. Never write “We refer to [symbol] as [name]”; “we call [symbol] [name]” is more concise.
      9. Never write “as long as”; “if” is more concise.
      10. The symbol > means “greater than”; and \geq, “greater than or equal to.” Don’t translate > into “strictly greater than”; the “strictly” is unnecessary. Analogous statements concern < and \leq.
    11. Avoid contractions, which are too informal for professional writing.
    12. The possessive is not a contraction and belongs in professional writing. It facilitates conciseness.
    13. Use the word “for” only when it belongs. Physicists often write “for” when they mean “if,” “per,” “at,” or something else.
      • Example of inappropriate use: The function vanishes for odd arguments.
        Corrected statement: If the argument is odd, the function vanishes.
      • Example of inappropriate use: We performed 10 trials for each parameter value.
        Corrected statement: We performed 10 trials per parameter value.
      • Example of inappropriate use: The function is smaller for small x values.
        Corrected statement: The function is smaller at small x values.
    14. Write “we evolve the state,” “we measure,” etc. only if you’re an experimentalist who undertakes those actions. Alternatives include “Consider measuring,” “Suppose the system evolves,” and the command tense (e.g., “One can measure this quantity as follows: prepare the qubit in \lvert 0\rangle. Evolve it under H…”).
    15. The condition x\ll y defines a regime, not a limit. The conditions \lim_{x\to0} and \lim_{y\to\infty} define limits and are inequivalent to x\ll y.
    16. Write “first,” “second,” “last,” etc., not “firstly,” “secondly,” “lastly,” etc. (I defer in this matter to The Elements of Style.)
    17. Humans can assume, suppose, etc. Mathematical expressions, protocols, etc. can’t.
    18. One multiplies factors together and sums terms. Don’t call factors terms and vice versa.
    19. If you mean “X equals Y,” say so. Don’t write “X agrees with Y,” “X matches Y,” or “we identify X with Y.” The latter three phrases are vaguer, and two of them contain more words, than “X equals Y.”
    20. Regarding the words “general” and “generally”:
      1. A general object subsumes every example of that object. If any example behaves unlike a supposedly general object, don’t call the object general.
      2. Many claims contain the term “general,” “generally,” or “in general” but don’t need the term.
        • Example of a sentence that contains “generally”: The terms generally commute.
        • Equivalent, more concise sentence: The terms commute.
      3. Physicists tend to use the words “general” and “generic” differently. By “general,” physicists usually mean “subsuming every example.” By “generic,” we usually mean “typical,” or “common.”
    21. “Then” makes sense (i) in discussions of chronology and (ii) in if–then statements. Don’t use “then” outside these contexts.
      • Example of inappropriate use: “Define X:=\ldots Then Y.”
      • Examples of appropriate alternatives
        • Define X:=\ldots This definition implies Y.
        • If X:=\ldots \, , then Y.
        • Define X:=\ldots \, , such that Y.
    22. Don’t justify any equation with “we used that [such-and-such is true],” which violates the rules of grammar. Grammatically correct alternatives include “We applied [a property],” “The equation follows from [a property],” and “…since [such-and-such is true].”
    23. Regarding tense:
      1. When describing what you’ve accomplished, use only one tense.
      2. Experiments happened in the past, so describe them in the past tense.
      3. When describing a proof’s steps, use the present tense.
        • Example: We Taylor-approximate the function about x=0. Substituting into Eq. (1) yields [equation].
    24. Nouns, verbs, and adjectives should agree about whether a quantity is singular or plural.
      • Example of singular–plural mismatch: The equations are a rule for evolving the cellular automaton.
      • Example alternative: The equations form a rule for evolving the cellular automaton.
    25. “Admit of” means “allow for,” or “permit.” The phrase needs the “of.”
      • Example: The formula admits of the following interpretation.
  3. Punctuation
    1. Consider any list that contains at least three items. If no item contains a comma, separate the items with commas. If any item contains a comma, separate the items with semicolons.
    2. In American English, periods and commas belong inside quotation marks. (Example: She told me, “Have a good day.”) In British English, periods and commas belong outside quotation marks. (Example: She told me, “Have a good day”.)
    3. To write quotation marks in LaTeX, don’t use your keyboard’s quotation-mark key; use the appropriate keys.
    4. Regarding hyphens:
      1. The hyphen (-) feeds into punctuation of three types: the hyphen (-), the en dash (–), and the em dash (—).
      2. The hyphen appears in some compound words, as in “non-negative.”
      3. In American English, em dashes can separate ideas within a sentence. Don’t separate any em dash from neighboring text with a space.
        • Example of appropriate use: The sample—the only product of this experiment—barely survived.
        • Example of inappropriate use: The sample — the only product of this experiment — barely survived.
        • Example of appropriate use: He told me only one sample had survived—hardly what I wanted to hear.
      4. This article specifies how to use the en dash. One use is “to separate the names of two or more people used as a compound modifier.”
        • Example: Feynman–Kitaev clock
      5. Hyphenate compound adjectives.
      6. If an adverb ends in “-ly,” it probably shouldn’t precede a hyphen.
        • Example of inappropriate hyphenation: strongly-coupled systems
      7. Follow a prefix with a hyphen if and only if the Physical Review style guide indicates that you should.
    5. A complete clause must follow any semicolon (unless the semicolon separates items in a list).
  4. Math
    1. Introduce only necessary notation, which readers will have enough trouble remembering. If a mathematical symbol appears only once, eliminate it. If a symbol appears only twice, try to eliminate it.
    2. Every sentence must obey the rules of English grammar, punctuation, and syntax, regardless of whether the sentence contains mathematical symbols. All math-containing sentences must end with punctuation marks. If a sentence contains a list of mathematical expressions, precede the final expressions with an “and.” If the list contains at least three mathematical expressions, separate them with commas.
    3. Introduce almost every mathematical symbol before you use it. If you introduce a symbol after using it, the reader will encounter the first use, stop, feel confused for a while, tentatively continue, find the definition, return to the earlier use to understand it, and then progress again. This back-and-forth breaks up the reading process. You may define a mathematical symbol after using it only if (i) the symbol is very common, known to nearly all physicists, and unmistakeable and (ii) defining the symbol earlier would disrupt the text’s flow.
    4. If you define a new function, denote it by only one letter. (I defer in this matter to the Physical Review style guide.)
      • Example: f(x,y,z)
      • Examples of disallowed notation: fxn(x,y,z), {\rm fxn}(x,y,z)
    5. Suppose that a superscript or subscript stands for a word or phrase without representing any variable or constant. The superscript/subscript must not be italicized. (I defer in this matter to Physical Review style guide.)
      • Example: Let x_{\mathrm{meas}} denote the measurement outcome.
    6. If a variable or constant appears in a superscript, parenthesize it. The parentheses communicate that the superscript isn’t an exponent.
      • Example: Let \sigma_z^{(j)} denote the Pauli-z operator of qubit j.
      • If a superscript is not italicized (stands for a word or phrase), don’t parenthesize it.
    7. Regarding the definition of a symbol A:
      1. If you write A alone on one side of a defining equation, use \coloneqq or \eqqcolon: A \coloneqq [expression], or [expression] \eqqcolon A. The symbols \coloneqq and \eqqcolon relate more information than does \equiv, encoding directionality.
      2. Use \equiv if A does not appear alone on its side of the equation: [function of A] \equiv [result of replacing A with its definition in the equation’s left-hand side].
    8. Refer to the Cartesian axes using the formatting “[italicized letter]-axis.” Don’t include any hat, boldface, or \vec symbol.
      • Example: x-axis
    9. Avoid denoting any index by i, which means \sqrt{-1} to physicists. Use j instead, unless you’re writing for engineers (who denote \sqrt{-1} by j).
    10. Don’t use the lowercase letter l (“ell”) as an index; readers might mistake it for a one. Use \ell (\ell) instead.
    11. Give every set-off equation a number. Readers (and coauthors) may want to refer to the equation easily when discussing the paper. Save them (and us) from having to say, e.g., “that equation halfway down page three.”
    12. When writing a set-off mathematical expression, use the align environment, not the equation environment. Using the align environment, one can easily extend an expression across multiple lines.
    13. Regarding a set-off mathematical expression that extends across multiple lines:
      1. Format the expression as follows by default.
        1. Put an & symbol immediately leftward of the first = sign or analogous symbol (e.g., \leq).
        2. If any subsequent line begins with another = sign (or analogous symbol), put an & immediately leftward of the symbol. (I’ll stop writing “or analogous symbol.”)
        3. Suppose that a subsequent line begins with a +, –, \times, or /. Find the symbol immediately rightward of the initial = sign. Begin the new line directly below that symbol.
        • Example:
      2. Modify the default formatting if necessary (a) to reduce the number of lines used in a PRL submission or (b) if the initial = appears awkwardly far to the right.
        • Example of (b):
      3. Suppose a new line begins with a term or factor, such as the jx^8 in the example under (A). Put the corresponding +, –, \times, or / at the beginning of the new line, not at the end of the previous line.
        • Examples of inappropriate placement:
    14. The symbol \approx means “approximately equals”; and ~, “scales as.” Approximations convey more information than scaling relations do.
    15. Use big-O-type notation or ~ symbols, not both; they’re partially redundant.
    16. \ldots, rather than \cdots, should stand in for elements that fit a pattern.
      • Example: x_1,x_2,\ldots,x_n
    17. When using \ldots as in the previous rule, present at least two initial examples of the pattern. One can’t define the pattern.
      • Contains insufficient examples: x_1,\ldots,x_n \, . For example, if n is odd, then x_1, x_2, \ldots, x_n and x_1, x_3, \ldots, x_n fit the template.
    18. Parentheses (), square brackets [], and curly braces {} are delimiters. If you nest them, do so in the order dictated by the Physical Review style guide.
    19. If delimiters enclose a symbol, it shouldn’t protrude above or below them (unless the delimiters would have to be grotesquely enormous). Use the \left and \right commands if the delimiters appear on the same line.
    20. An operator O isn’t a matrix; a matrix represents an operator in terms of a particular basis. Therefore, no equals sign should interrelate an O and a matrix. An arrow can.
      • Example: O\to\begin{bmatrix}1&0\\0&2\end{bmatrix}
    21. Every real number is complex. Don’t say “complex” if you mean “nonreal.”
    22. Consider introducing a mathematical symbol in a prose sentence without using a comma or colon. Put the symbol immediately after the word that names the object represented by the symbol.
      • Example of inappropriate placement: the set of real numbers \{ a, b \}
      • Examples of appropriate placements
        • the set \{a, b\} of real numbers
        • the set of real numbers a and b
        • Recall the set of real numbers, \{a, b\}, in Lemma 1.
  5. More mechanics of writing
    1. Use concise sentences, as advocated for in The Elements of Style. The reader can hold only so many ideas in their head at once.
    2. Structure sentences simply, as advocated for in The Elements of Style. The reader should be able to grasp each sentence easily.
      • Avoid nesting ideas within a sentence, to avoid convoluting the sentence’s structure.
        • Example of sentence with convoluted, nested structure: Any model of equilibrium and nonequilibrium behaviors of systems observed in tabletop experiments and high-energy colliders must obey the laws of relativistic quantum mechanics.
        • Visualization of the nesting: [Any model of ([(equilibrium and nonequilibrium) behaviors] of {systems observed in [(tabletop experiments) and (high-energy colliders)]})] must obey [the laws of (relativistic quantum mechanics)].
    3. The ideal paper title has the structure of a newspaper headline: it presents a claim, containing a subject and a predicate.
    4. Regarding abbreviations:
      1. Don’t abbreviate the first word in any sentence.
      2. Abbreviate “Figure,” “Section,” “Professor,” and “Appendix” if such a word appears partway through a sentence.
      3. Don’t abbreviate “Sections.”
    5. Regarding acronyms:
      1. Write every acronym in capital letters, as per the Physical Review style guide.
      2. Introduce each acronym the first time you use it.
      3. Thereafter, use only the acronym, not the spelled-out phrase, throughout the rest of the document’s main text. You may spell out the phrase in section, figure, and table titles if doing so improves the document’s clarity.
    6. Every paragraph should contain at least three sentences.
    7. Wherever you insert a blank line into your LateX code, a new paragraph begins in the corresponding PDF. Insert a blank line only if you wish to begin a new paragraph. This advice applies immediately before and after set-off equations.
    8. Never begin a subsection immediately after a section title. Between the two titles, overview the section. Analogous rules govern subsections and subsubsections.
    9. Put the word “only” in the appropriate place.
      • For example, suppose you’ve sampled data at a point x=0 in parameter space and sampled data at no other points. “We sampled data only at x=0” is correct; “We only sampled data at x=0” is probably not. The latter claim means that (i) you might have sampled data at x=0 and (ii) you did nothing to the x=0 data apart from sample it: you didn’t analyze the x=0 data, discuss the x=0 data, etc.
  6. When in doubt, consult the Physical Review style guide or The Elements of Style.
    • If those references don’t contain the information you seek, search for it in online writing guides. Not all such guides have equal merit, however. Lean toward guides written by human editors or published by college writing centers.

1 Collaborators have wondered why I use green; a student guessed it’s my favorite color. It isn’t; but I bleed green, having graduated from the Big Green, also known as Dartmouth College. Sometimes, I highlight certain pieces of text for one reason (e.g., to point out logical inconsistencies) and other text for another reason (e.g., to point out grammatical inconsistencies). Green distinguishes the first highlightings, while orange distinguishes the second: when not bleeding Dartmouth green, I bleed Caltech orange.

2 Don’t learn how to write from physics papers. 

September 25, 2026

Jordan Ellenberg — I love working here, II

Making final revisions to Don’t Be Too Sure on the Terrace. An all-tuba band on the Terrace Stage playing an all-tuba cover of “Black Hole Sun.”

Sorry for light blogging lately. See “making final revisions” above. Just realized I misspelled the first name of Katharine Briggs, who’s mentioned several times and who I read a whole book about. How many mistakes are left in this thing? (I suppose if I’d kept a rigorous log of mistakes found and plotted it over time, I could curve-fit and estimate this.)

n-Category Café Binomial Coefficient Coincidences

These seven equations between binomial coefficients are ‘coincidences’ — they aren’t among the four known infinite families of such equations:

(162)=(103)=120 \binom{16}{2} = \binom{10}{3} = 120

(212)=(104)=210 \binom{21}{2} = \binom{10}{4} = 210

(562)=(223)=1540 \binom{56}{2} = \binom{22}{3} = 1540

(782)=(146)=3003 \binom{78}{2} = \binom{14}{6} = 3003

(1202)=(363)=7140 \binom{120}{2} = \binom{36}{3} = 7140

(1532)=(195)=11628 \binom{153}{2} = \binom{19}{5} = 11628

(2212)=(178)=24310 \binom{221}{2} = \binom{17}{8} = 24310

In 1997, De Weger conjectured that every equation between binomial coefficients follows from the four known systematic equations and the seven coincidences I showed you:

• Benjamin M. M. de Weger, Equal binomial coefficients: some elementary considerations, Journal of Number Theory 63, no. 2 (1997), 373–386.

At that time, he and his collaborators checked there were no others involving binomial coefficients less than 1030. Later they checked that there are none involving binomial coefficients less than 1060:

• Aart Blokhuis, Andries Brouwer and Benne de Weger, Binomial collisions and near collisions.

So, De Weger’s conjecture stands open. The four infinite families, by the way, are these:

(nk) = (nn−k) 0≤k≤n (n0) = 1 n≥0 ((nk)1) = (nk) 0≤k≤n \begin{array}{cccl} \displaystyle{ \binom{n}{k} } &=& \displaystyle{ \binom{n}{n-k} }& \qquad 0 \le k \le n \\ \\ \displaystyle{ \binom{n}{0} } &=& 1 & \qquad n \ge 0 \\ \\ \displaystyle{ \binom{\binom{n}{k}}{1} } &=& \displaystyle{\binom{n}{k}} & \qquad 0 \le k \le n \end{array}

and the only nontrivial one: the Lind–Singmaster family involving the Fibonacci numbers F iF_i where F 0=0,F 1=1F_0 = 0,\ F_1 = 1:

(F 2i+2F 2i+3F 2iF 2i+3)=(F 2i+2F 2i+3−1F 2iF 2i+3+1)i=1,2,3,… \displaystyle{ \binom{F_{2i+2}F_{2i+3}}{\,F_{2i}F_{2i+3}\,} \;=\; \binom{F_{2i+2}F_{2i+3}-1}{\,F_{2i}F_{2i+3}+1} \qquad i = 1,2,3,\dots }

The first three equations in the Lind–Singmaster family are these:

(155) = (146) (10439) = (10340) (714272) = (713273) \begin{array}{ccc} \displaystyle{ \binom{15}{5} } &amp;= &amp;\displaystyle{\binom{14}{6}} \\ \\ \displaystyle{\binom{104}{39} } &amp;= &amp;\displaystyle{\binom{103}{40}} \\ \\ \displaystyle{ \binom{714}{272} } &amp;=&amp; \displaystyle{\binom{713}{273}} \end{array}

When I said De Weger conjectured every equation between binomial coefficients follows from the four known systematic equations and the seven coincidences, I really meant it. For example, the first of the Lind-Singmaster equations combines with the coincidence

(782)=(146)=3003 \binom{78}{2} = \binom{14}{6} = 3003

and other systematic equations to give

(30031) = (782) = (155) = (146) = (30033002) = (7876) = (1510) = (148) \begin{array}{cccccccccc} & \binom{3003}{1} &=& \binom{78}{2} &=& \binom{15}{5} &=& \binom{14}{6} \\ \\ = & \binom{3003}{3002} &=& \binom{78}{76} &=& \binom{15}{10} &=& \binom{14}{8} \end{array}

In fact, if de Weger’s conjecture is true, the number 3003 shows up as a binomial coefficient in more ways than any other positive integer!

I’ll explain the Lind–Singmaster family later. Here’s the question I’m most interested in now:

Is there any good explanation for the seven binomial coefficient coincidences?

My collaborator Paul Schwahn found a beautiful explanation of the first one, namely

(103)=(162) \displaystyle{ \binom{10}{3} = \binom{16}{2} }

His explanation uses representation theory. The Lie algebra 𝔰𝔬(10)\mathfrak{so}(10) has a 10-dimensional representation, the ‘vector’ representation V 10V_{10}, and also two 16-dimensional representations, the ‘left and right-handed spinor’ representations S 10 ±.S^\pm_{10}. There’s an isomorphism of representations

Λ 2S 10 +≅Λ 3V 10 \displaystyle{\Lambda^2 S^+_{10} \cong \Lambda^3 V_{10} }

and similarly for S 10 −,S^-_{10}, but we might as well work with S 10 +.S^+_{10}. Here Λ k\Lambda^k means the kth exterior power. For any vector space XX we have

dim(Λ kX)=(dimXk) \displaystyle{ \dim(\Lambda^k X) = \binom{\dim X}{k} }

Thus, taking dimensions, the isomorphism of representations

Λ 2S 10 +≅Λ 3V 10 \displaystyle{\Lambda^2 S^+_{10} \cong \Lambda^3 V_{10} }

instantly gives

(162)=(103) \displaystyle{ \binom{16}{2} = \binom{10}{3} }

It is not super-easy to prove this isomorphism of representations, but it’s still nice to find a deeper layer of meaning underlying what might otherwise seem like a meaningless coincidence!

Can we find good explanations for the other six coincidences?

First let me explain two failed attempts using representation theory, and then three successes using combinatorics.

Representation theory

First: we can look for isomorphisms like

Λ 2S 10 +≅Λ 3V 10 \displaystyle{\Lambda^2 S^+_{10} \cong \Lambda^3 V_{10} }

involving representations of 𝔰𝔬(n)\mathfrak{so}(n) for larger n.n. In fact this isomorphism is part of a pattern! The next one involves the vector and left-handed spinor representations of 𝔰𝔬(12).\mathfrak{so}(12). But it’s this:

Λ 2S 12 +≅Λ 4V 12⊕Λ 0V 12 \displaystyle{ \Lambda^2 S^+_{12} \cong \Lambda^4 V_{12} \oplus \Lambda^0 V_{12} }

so it gives

(322)=(124)+1 \displaystyle{ \binom{32}{2} = \binom{12}{4} + 1 }

or

496=495+1 \displaystyle{ 496 = 495 + 1 }

So we fail to get an equation between binomial coefficients, but we’re close: we’re only off by one.

The second paper I cited, Binomial collisions and near collisions, presents a list of cases where two binomial coefficients differ by one. This is on the list. So we failed to explain an equation between binomial coefficients, but we explained a near-miss.

Here’s another failed attempt at explaining an equation between binomial coefficients. The equation

(782)=(146)=3003 \displaystyle{ \binom{78}{2} = \binom{14}{6} = 3003 }

is fascinating to anyone who knows their exceptional Lie groups. 78 is the dimension of E 6,\mathrm{E}_6, while 14 is the dimension of G 2.\mathrm{G}_2. G 2\mathrm{G}_2 is a subgroup of E 6\mathrm{E}_6 because G 2\mathrm{G}_2 is the automorphism group of the octonions and E 6\mathrm{E}_6 is the isometry group of the bioctonionic plane. We’d get the above equation if the 2nd exterior power of the adjoint representation of E 6,\mathrm{E}_6, upon being restricted to G 2,\mathrm{G}_2, were isomorphic to the 6th exterior power of the adjoint representation of G 2.\mathrm{G}_2.

Amazingly, it seems these two representations of G 2\mathrm{G}_2 are not isomorphic even though their dimensions are the same: both 3003.

Even more amazingly, E 6\mathrm{E}_6 and G 2\mathrm{G}_2 both have irreducible representations of dimension 3003, but they are not the representations I just mentioned.

I would be happy for someone to check these two claims.

Combinatorics

It turns out that the following three coincidences can all be explained by the same style of combinatorial argument:

(212)=(104),(1532)=(195),(782)=(146) \binom{21}{2} = \binom{10}{4}, \qquad \binom{153}{2} = \binom{19}{5}, \qquad \binom{78}{2} = \binom{14}{6}

The argument is not very elegant, but it’s moderately interesting. Mike Stay got it started by asking ChatGPT, and I finished it off.

In each case the argument has three steps. The first two steps are what combinatorialists call bijective proofs: we prove an equation between numbers by proving a natural isomorphism between structures on sets and then taking cardinalities. The third step is non-bijective because it involves taking an equation and dividing both sides by the same number. Maybe we can make it closer to bijective by using groupoid cardinality, which allows for division, but I haven’t tried that.

Step 1: pairs of edges in a complete graph

Starting from the left-hand binomial coefficient in each equation we’re trying to prove, note that the number on top is a triangular number:

21=(72),153=(182),78=(132) 21 = \binom{7}{2}, \qquad 153 = \binom{18}{2}, \qquad 78 = \binom{13}{2}

Note that ((n2)2)\binom{\binom{n}{2}}{2} counts unordered pairs of distinct edges in the complete graph on nn vertices. Two distinct edges either share a vertex or are disjoint, so there are two cases:

• Sharing a vertex: the pair spans 3 vertices and is determined by this 3-element set together with a choice of which vertex is shared. That gives 3(n3)3\binom{n}{3} pairs.

• Disjoint: the pair spans 4 vertices and is determined by this 4-element set together with one of its 3 splittings into two pairs. That gives 3(n4)3 \binom{n}{4} pairs.

By Pascal’s rule, (n3)+(n4)=(n+14).\binom{n}{3} + \binom{n}{4} = \binom{n+1}{4}. But this also has a bijective proof: add a new point to the set of nn vertices, and a 4-element subset of the enlarged set either contains the new point (so involves a 3-element subset of the old ones) or does not (so involves a 4-element subset of the old ones). Hence we have a bijective proof that

((n2)2)=3(n+14) \binom{\binom{n}{2}}{2} = 3\binom{n+1}{4}

This holds for all n.n. For our three cases we get bijective proofs of the following equations:

(212)=3(84),(1532)=3(194),(782)=3(144). \binom{21}{2} = 3\binom{8}{4}, \qquad \binom{153}{2} = 3\binom{19}{4}, \qquad \binom{78}{2} = 3\binom{14}{4}.

It thus remains to prove

3(84)=(104),3(194)=(195),3(144)=(146). 3\binom{8}{4} = \binom{10}{4}, \qquad 3\binom{19}{4} = \binom{19}{5}, \qquad 3\binom{14}{4} = \binom{14}{6}.

Step 2: a double count

Each of the above equations follows by counting a single set in two ways, and then a nonbijective step: dividing these counts by the same number.

• Showing 3(84)=(104)3\binom{8}{4} = \binom{10}{4}. In a 10-element set, count triples (S,x,y)(S, x, y) in two different ways, where SS is a 4-element subset and x,yx, y are distinct points outside SS. Choosing SS first we see there are (104)⋅6⋅5=30(104) \binom{10}{4} \cdot 6 \cdot 5 = 30\binom{10}{4} triples. Choosing xx and yy first we see there are 10⋅9⋅(84)=90(84) 10 \cdot 9 \cdot \binom{8}{4} = 90\binom{8}{4} triples. So, we get a bijective proof that 90(84)=30(104) 90\binom{8}{4} = 30\binom{10}{4} You can see what we’ll do next.

• Showing 3(194)=(195).3\binom{19}{4} = \binom{19}{5}. In a 19-element set, count pairs A⊂BA \subset B with |A|=4|A| = 4 and |B|=5|B| = 5. On the one hand, there are (194)\binom{19}{4} choices of A,A, and for each there are 15 choices of BB since we can add an extra point in 15 ways. On the other hand, there are (195)\binom{19}{5} choices of B,B, and for each there are 5 choices of AA since we can choose AA in (54)=5\binom{5}{4} = 5 ways. So we get a bijective proof that 15(194)=5(195) 15\binom{19}{4} = 5\binom{19}{5} Again, you can see what we’ll do next!

• Showing 3(144)=(146).3\binom{14}{4} = \binom{14}{6}. In a 14-element set, count pairs A⊂BA \subset B with |A|=4|A| = 4 and |B|=6|B| = 6. On the one hand, there are (144)\binom{14}{4} choices of A,A, and for each there are 45 choices of BB since we can add 2 other points in (102)=45\binom{10}{2} = 45 ways. On the other hand there are (146)\binom{14}{6} choices of BB and for each there are 15 choices of AA since we can choose 4 points in (64)=15\binom{6}{4} = 15 ways. This gives a bijective proof that 45(144)=15(146) 45\binom{14}{4} = 15\binom{14}{6} Again you can see what we’ll do next.

Step 3: division

Having proved

90(84)=30(104),15(194)=5(195),45(144)=15(146) 90\binom{8}{4} = 30\binom{10}{4}, \qquad 15\binom{19}{4} = 5\binom{19}{5}, \quad 45\binom{14}{4} = 15\binom{14}{6}

we can now divide by 30, 5 and 15, respectively, and get

3(84)=(104),3(194)=(195),3(144)=(146) 3 \binom{8}{4} = \binom{10}{4} , \qquad 3 \binom{19}{4} = \binom{19}{5}, \quad 3\binom{14}{4} = \binom{14}{6}

as we wanted, completing our proof that

(212)=(104),(1532)=(195),(782)=(146). \binom{21}{2} = \binom{10}{4}, \qquad \binom{153}{2} = \binom{19}{5}, \qquad \binom{78}{2} = \binom{14}{6}.

I don’t see how to use tricks of the same general sort to explain the remaining coincidences

(562)=(223),(1202)=(363),(2212)=(178). \binom{56}{2} = \binom{22}{3}, \qquad \binom{120}{2} = \binom{36}{3}, \qquad \binom{221}{2} = \binom{17}{8}.

The Lind–Singmaster family

Lind and Singmaster were trying to find all n,kn,k with

(nk)=(n−1k+1) \displaystyle{ \binom{n}{k} = \binom{n-1}{k+1} }

I’ll rapidly sketch the key steps of their argument. Simplifying the equation above we get

n(k+1)=(n−k)(n−k−1) n(k+1) = (n-k)(n-k-1)

or

n 2−(3k+2)n+(k 2+k)=0 n^2 - (3k+2)n + (k^2+k) = 0

Solve for nn using the quadratic formula. This formula turns out to have

5k 2+8k+4 \sqrt{5k^2 +8k+4}

in it. So we need 5k 2+8k+45k^2 +8k+4 to be a perfect square!

Now we’re trying to find integer solutions of

5k 2+8k+4=m 2 5k^2+8k+4 = m^2

A quadratic diophantine equation! Multiply by 5 and complete the square:

5m 2=(5k+4) 2+4 5m^2 = (5k+4)^2 + 4

y=5k+4y = 5k+4 is an integer when kk is, so we need to find integer solutions of

y 2−5m 2=−4 y^2 - 5m^2 = -4

This is a ‘Pell equation’, and people know how to solve these. In this particular case we get all the solutions from this fact:

L n 2−5F n 2=4(−1) n L_n^2 - 5F_n^2 = 4(-1)^n

where F nF_n are the Fibonacci numbers 0, 1, 1, 2, 3, … and L nL_n are the Lucas numbers 2, 1, 3, 4, 7, …. These are two sequences satisfying the same famous recurrence relation, just with different initial conditions.

We want nn odd, to get

L n 2−5F n 2=−4 L_n^2 - 5F_n^2 = -4

It turns out y=L n,m=F ny = L_n, m = F_n with nn odd give all solutions of the Pell equation

y 2−5m 2=−4 y^2 - 5m^2 = -4

However, remember I said y=5k+4y = 5k+4 is an integer when kk is. But the converse isn’t always true, and we need kk to be an integer! This clearly happens iff y≡4bmod5.y \equiv 4 \bmod 5.

So we need to know when L n≡4bmod5L_n \equiv 4 \bmod 5 Apparently this happens iff n≡3bmod4.n \equiv 3 \bmod 4. I won’t think about this now… but this is the last hard step.

In summary, we’ve seen

(nk)=(n−1k+1) \displaystyle{ \binom{n}{k} = \binom{n-1}{k+1} }

if and only if y=5k+4y = 5k+4 is a Lucas number L nL_n with n≡3bmod4.n \equiv 3 \bmod 4. We could quit here, but people like to use the identity

L 4i+3−4=5F 2iF 2i+3 L_{4i+3} - 4 = 5F_{2i} F_{2i+3}

to get a formula for kk in terms of Fibonacci numbers. This is gilding the lily, I’d say, but it eventually leads to the formula that de Weger presents:

(F 2i+2F 2i+3F 2iF 2i+3)=(F 2i+2F 2i+3−1F 2iF 2i+3+1),i=1,2,3,… \displaystyle{ \binom{F_{2i+2}F_{2i+3}}{\,F_{2i}F_{2i+3}\,} \;=\; \binom{F_{2i+2}F_{2i+3}-1}{\,F_{2i}F_{2i+3}+1\,}, \qquad i = 1,2,3,\dots }

The takeaway message is: our problem can easily be reduced to a quadratic diophantine equation, then put in Pell form… and it’s known that the sequence of integer solutions of a Pell equation obeys a linear recurrence relation! We luck out in this case and get solutions connected to Lucas and Fibonacci numbers.

It’s probably a lot easier to show that the Lind–Singmaster equations hold. The above argument does a lot more, by showing that every equation of the form

(nk)=(n−1k+1) \displaystyle{ \binom{n}{k} = \binom{n-1}{k+1} }

is in the Lind–Singmaster family. De Weger gets into a lot more number theory trying to rule out various other kinds of coincidences between binomial coefficients. It’s downright scary how these questions pull you into the deep, icy waters of mathematics.

Matt von Hippel — It Got to My Field

For the folks who found this blog from Anthropic’s site, welcome!

For everyone else, I’d better give some context.

Last month, I had a blog post titled “It Only Counts When AI Gets to My Field”. The title was a joke, the content less so. I said that if some of the longstanding problems of my old research field got solved by AI, then I’d sit up and take notice.

The post turned out to be a bit of a self-fulfilling prophecy, after some folks at Anthropic read it and decided to tackle one of the outstanding problems I mentioned. They then invited me to write a post about it on their science blog.

The post is here. I recommend reading it, then coming back. The rest of this post will be a little Q&A.

Q: At the end of that post, it says Anthropic paid you for your time. Can we trust what you wrote?

A: When I agreed to write the post, I made it clear that I was going to give my own opinion, not write an ad for Anthropic. They could propose light edits, but that’s it. And I avoided signing anything with them, not even an NDA, so I could freely tell you if they pushed my boundaries.

They didn’t push my boundaries. They asked me to clarify a few things, and to give more detail on the science. I didn’t change the message or the takeaways.

The reason I asked them to pay me is that, as a freelance writer, I don’t have a salary to fall back on. Time I spend on a project like that post is time I’m not spending on journalistic projects, so if I worked on it for free I’d essentially be using my vacation time for it. The rate I’m charging them is roughly in the middle of what I’d have gotten paid if I used that time on journalism: a bit more than I would have made working for the lower-paying outlets, a bit less than I would have made with the higher-paying ones.

I’m also not expecting this to be the start of a longer-term business relationship or anything like that. So overall, I don’t think I’m incentivized to lie on their behalf. You can trust me.

Q: How confident are you that they did what they said they did?

A: I didn’t get the feeling they were lying. But I didn’t start out skeptical.

I haven’t seen the logs from the LLM, or anything like that. That’s the kind of thing I would dig into if I were more suspicious of their story. If there’s a reason to be suspicious, I’ll ask.

But so far, I don’t feel that I have much reason to be suspicious. They were able to look up details on the fly when I asked them, they didn’t seem to have a polished message they were trying to push past me. And more importantly, as I’ll mention in a bit, I don’t think anything they described is all that outlandish. It lines up, largely, with the capabilities I’d expect their Claude Science platform to have.

It’s also relevant that they didn’t use an internal model for this. It means that scientists will likely be trying out similar problems soon, so if it does turn out they exaggerated something, people are going to figure out quite quickly.

Q: So how big is this? We just saw AI solve a Millennium problem, after all.

A: This was a lot easier than a Millennium problem. But it was also a lot cheaper.

The problem they solved is one with a clear recipe, honed and explained over multiple papers. It’s something I expected to be hard to do without access to a lot of computer power, so I thought it would need to be approached with a novel technique, in order to avoid using that computer power.

In the end, it didn’t need that. As I mention in the post, another group got most of the result at around the same time, with a much smaller amount of AI assistance.

It’s not an easy recipe, to be clear. I think other people will be surprised that a reasonably affordable program like Claude Science can do this without a lot of guidance. I’m not surprised, mostly, because I’ve been paying enough attention to what people have been doing with these things, and carrying out this kind of recipe consistently is actually something the good science AIs can do right now. If you haven’t been following as closely, that’s going to be a lot more surprising.

So maybe the best way to answer this is: instead of paying $15 million to solve one of the most famous problems in mathematics, they paid $1,000 or so to make a significant next step in an ongoing research program in theoretical physics. This doesn’t tell you much about whether AI can achieve field-defining breakthroughs, but it tells you a lot about the kinds of things a theoretical physicist with $1000 spare budget can do right now.

(As an aside, it feels crazy to me that 90% or more of the compute cost was from the LLM, not the calculation itself. On the one hand, it feels nuts to essentially use ten times more computer power to do this than would have been needed if a human had done the coding. On the other hand, I’ve applied for grants that budgeted more than that per year for travel costs, and spending this kind of money on getting a result seems a lot more useful than spending it on airfare.)

Q: Isn’t it reckless to publicly post a problem for AI like that?

A: I posted my challenge before OpenAI announced their Navier-Stokes result. At that point, there had been a few awkward surprises, but for the most part AI companies had a pattern of talking to an academic first before trying to solve a problem. It’s what they did back in March.

I expected that was what they’d do this time, and got more than a little blindsided when they just solved the problem on their own and reached out to Lance afterwards. I’m lucky that Lance doesn’t seem mad at me about it, it would have been quite understandable if he was.

I did tell them that if they wanted to tackle any of the other problems in that post, they should reach out to one of the scientists involved first, before attempting it. In addition to being polite, it’s a way to make sure that they understand the problem correctly and have a plan to verify the result. They happened to pick a challenge that was particularly easy to verify, but it didn’t have to go that way.

Q: Any thoughts about AI’s future impact on science?

A: If there’s a problem you can’t solve, but you think someone with expertise in another field or better programming skills could, then it’s probably solvable with AI.

A lot of problems don’t fall into that category. I’ve seen people talking online about AI solving quantum gravity, but solving quantum gravity is a question of which bullets you’re willing to bite, not a question of technical skill. That doesn’t mean AI will never be able to address it, but if so it will come from some sort of superpersuader aspect, not merely scientific capabilities.

And of course, some fields do require experiments. People are increasingly building AI-powered labs. I’ll leave it to people from actual experimental fields to think about the potential there.

Q: Can you say something explicit about the bigger risks from AI, now?

A: As I mention in the post, I didn’t learn that much about the bigger questions from this. I’m still not an expert.

But there’s one thing I think is worth emphasizing:

This technology is clearly getting more effective over time. I don’t think they could have done this six months ago. If you’re trying to predict what will happen next, you shouldn’t just assume this is the most powerful it will get, or the cheapest. If you think there’s a limit, you need to argue for it.

Edit: One more thing I should mention, now that I’ve confirmed she’s ok with it: the idea for my challenge came from some discussions at Lancefest, a conference in honor of Lance back in June, and particularly from Anastasia Volovich, whose talk declared the nine-loop calculation “a benchmark – or a ‘challenge’ – against which any “AI takeover” should be measured”.

Tommaso Dorigo — Some Tests Of The Radiacode Zero

Some Tests Of The Radiacode Zero

As I explained previously, these days I am testing a new radiation detector from the Radiacode family: Radiacode Zero.

Tommaso Dorigo
Categories

September 24, 2026

John Baez — Binomial Coefficient Coincidences

These seven equations between binomial coefficients are ‘coincidences’: they aren’t among the four known infinite families. De Weger conjectured that there are no more such coincidences:

• Benjamin M. M. de Weger, Equal binomial coefficients: some elementary considerations, Journal of Number Theory 63, no. 2 (1997), 373–386.

At that time, he and his collaborators checked there were no others involving binomial coefficients less than 1030. Later they checked that there are none involving binomial coefficients less than 1060:

• Aart Blokhuis, Andries Brouwer and Benne de Weger, Binomial collisions and near collisions.

So, De Weger’s conjecture stands open. The four infinite families, by the way, are these:

\displaystyle{ \binom{n}{k} = \binom{n}{\,n-k\,}, \qquad 0 \le k \le n}

\displaystyle{ \binom{n}{0} = 1, \qquad n \ge 0 }

\displaystyle{ \binom{\binom{n}{k}}{1} = \binom{n}{k}, \qquad \qquad 0 \le k \le n}

and the only nontrivial one: the Lind–Singmaster family involving the Fibonacci numbers F_i where F_0 = 0,\ F_1 = 1:

\displaystyle{    \binom{F_{2i+2}F_{2i+3}}{\,F_{2i}F_{2i+3}\,}    \;=\;    \binom{F_{2i+2}F_{2i+3}-1}{\,F_{2i}F_{2i+3}+1\,},    \qquad i = 1,2,3,\dots }

The first three equations in the Lind–Singmaster family are these:

\begin{array}{ccc}   \displaystyle{ \binom{15}{5} }  &= &\displaystyle{\binom{14}{6}}   \\ \\    \displaystyle{\binom{104}{39} } &= &\displaystyle{\binom{103}{40}} \\ \\    \displaystyle{ \binom{714}{272} } &=& \displaystyle{\binom{713}{273}}  \end{array}

I’ll explain the Lind–Singmaster family later. But here’s the question I’m most interested in:

Is there any good explanation for the seven binomial coefficient coincidences?

Today my collaborator Paul Schwahn found a beautiful explanation of the first one, namely

\displaystyle{ \binom{10}{3} = \binom{16}{2} }

His explanation uses representation theory. The Lie algebra \mathfrak{so}(10) has a 10-dimensional representation, the ‘vector’ representation V_{10}, and also two 16-dimensional representations, the ‘left and right-handed spinor’ representations S^\pm_{10}. There’s an isomorphism of representations

\displaystyle{\Lambda^2 S^+_{10} \cong \Lambda^3 V_{10}   }

and similarly for S^-_{10}, but we might as well work with S^+_{10}. Here \Lambda^k means the kth exterior power. For any vector space X we have

\displaystyle{ \dim(\Lambda^k X) = \binom{\dim X}{k}  }

Thus, taking dimensions, the isomorphism of representations

\displaystyle{\Lambda^2 S^+_{10} \cong \Lambda^3 V_{10}   }

instantly gives

\displaystyle{  \binom{16}{2} = \binom{10}{3} }

It is not super-easy to prove this isomorphism of representations, but it’s still nice to find a deeper layer of meaning underlying what might otherwise seem like a meaningless coincidence!

Can we find representation-theoretic explanations—or other explanations—for the other six coincidences?

I have not succeeded, but let me tell you about two failed tries.

We can look for isomorphisms like

\displaystyle{\Lambda^2 S^+_{10} \cong \Lambda^3 V_{10}   }

involving representations of \mathfrak{so}(n) for larger n. In fact this isomorphism is part of a pattern! The next one involves the vector and left-handed spinor representations of \mathfrak{so}(12). But it’s this:

\displaystyle{ \Lambda^2 S^+_{12} \cong \Lambda^4 V_{12} \oplus \Lambda^0 V_{12}  }

so it gives

\displaystyle{ \binom{32}{2} = \binom{12}{4} + 1  }

or

\displaystyle{ 496 = 495 + 1 }

So we fail to get an equation between binomial coefficients: we’re off by one.

The second paper I cited, Binomial collisions and near collisions, presents a list of cases where two binomial coefficients differ by one. This is on the list. So we failed to explain an equation between binomial coefficients, but explained a near-miss.

Here’s another failed attempt at explaining an equation between binomial coefficients. The equation

\displaystyle{  \binom{78}{2} = \binom{14}{6} = 3003 }

is fascinating to anyone who knows their exceptional Lie groups. 78 is the dimension of \mathrm{E}_6, while 14 is the dimension of \mathrm{G}_2. \mathrm{G}_2 is a subgroup of \mathrm{E}_6 because \mathrm{G}_2 is the automorphism group of the octonions and \mathrm{E}_6 is the isometry group of the bioctonionic plane. We’d get the above equation if the 2nd exterior power of the adjoint representation of \mathrm{E}_6, upon being restricted to \mathrm{G}_2, were isomorphic to the 6th exterior power of the adjoint representation of \mathrm{G}_2.

Amazingly, it seems these two representations of \mathrm{G}_2 are not isomorphic even though their dimensions are the same: both 3003.

Even more amazingly, \mathrm{E}_6 and \mathrm{G}_2 both have irreducible representations of dimension 3003, but they are not the representations I just mentioned.

I would be happy for someone to check these two claims.

If anyone knows good explanations of the remaining six binomial coefficient coincidences, please let me know!

The Lind–Singmaster family

Lind and Singmaster were trying to find all n,k with

\displaystyle{ \binom{n}{k} = \binom{n-1}{k+1} }

I’ll rapidly sketch the key steps of their argument. Simplifying the equation above we get

n(k+1) = (n-k)(n-k-1)

or

n^2 - (3k+2)n + (k^2+k) = 0

Solve for n using the quadratic formula. This formula turns out to have

\sqrt{5k^2 +8k+4}

in it. So we need 5k^2 +8k+4 to be a perfect square!

Now we’re trying to find integer solutions of

5k^2+8k+4 = m^2

A quadratic diophantine equation! Multiply by 5 and complete the square:

5m^2 = (5k+4)^2 + 4

y = 5k+4 is an integer when k is, so we need to find integer solutions of

y^2 - 5m^2 = -4

This is a ‘Pell equation’, and people know how to solve these. In this particular case we get all the solutions from this fact:

L_n^2 - 5F_n^2 = 4(-1)^n

where F_n are the Fibonacci numbers 0, 1, 1, 2, 3, … and L_n are the Lucas numbers 2, 1, 3, 4, 7, …. These are two sequences satisfying the same famous recurrence relation, just with different initial conditions.

We want n odd, to get

L_n^2 - 5F_n^2 = -4

It turns out y = L_n, m = F_n with n odd give all solutions of the Pell equation

y^2 - 5m^2 = -4

However, remember I said y = 5k+4 is an integer when k is. But the converse isn’t always true, and we need k to be an integer! This clearly happens iff y \equiv 4 \bmod 5.

So we need to know when L_n \equiv 4 \bmod 5 Apparently this happens iff n \equiv 3 \bmod 4. I won’t think about this now… but this is the last hard step.

In summary, we’ve seen

\displaystyle{ \binom{n}{k} = \binom{n-1}{k+1} }

if and only if y = 5k+4 is a Lucas number L_n with n \equiv 3 \bmod 4. We could quit here, but people like to use the identity

L_{4i+3} - 4 = 5F_{2i} F_{2i+3}

to get a formula for k in terms of Fibonacci numbers. This is gilding the lily, I’d say, but that eventually leads to the formula I showed you:

\displaystyle{    \binom{F_{2i+2}F_{2i+3}}{\,F_{2i}F_{2i+3}\,}    \;=\;    \binom{F_{2i+2}F_{2i+3}-1}{\,F_{2i}F_{2i+3}+1\,},    \qquad i = 1,2,3,\dots }

The takeaway message is: our problem can easily be reduced to a quadratic diophantine equation, then put in Pell form… and it’s known that the sequence of integer solutions of a Pell equation obeys a linear recurrence relation! We luck out in this case and get solutions connected to Lucas and Fibonacci numbers.

There may be a simpler argument, but this is what I’ve seen.

September 20, 2026

John Preskill — Quantum Computers Need More than “Magic”

The University of Cambridge is a special place. During term time, hordes of students gather, ready to attend formal, a candle-lit dinner in a five-century-old hall overlooked by paintings of academics past. The sight is like an overromanticized still of a bygone era. The men wear suits, the women long dresses, all wear gowns. The simplest gowns belong to the undergrads, with the complexity and length of the gowns growing as one climbs the academic ranks. 

Between the bringing of the bread and the serving of the soup, the conversation at my end of the table typically turns to my topic of research: quantum computers. These theoretical machines harness quantum physics to outperform their classical counterparts. Quantum computers hold great promise for the future, with applications ranging from drug discovery to cybersecurity. Yet, despite their promise, we still do not have a satisfying answer to the fundamental question: what makes quantum computers computationally stronger than classical computers?

To answer this question, imagine that tonight, instead of the soup, the cooks are brewing a happiness potion. This potion causes the drinker to be joyful and content for the rest of the evening. The cooks know how to brew the potion perfectly well; they discovered the list of ingredients in the nineties and have been successfully brewing ever since. But the cooks still cannot solve one mystery: what makes the potion different from the soup? What ingredient sets the potion apart from the soup?

The cooks come up with a simple approach. They leave out one ingredient in each serving, and then carefully observe the formal-goers. They find that almost every seat is filled by a happy student, chatting away to their neighbours, indicating a working potion. However, one student’s spirits have not been lifted, as they were solely served a simple soup. The cooks conclude that the ingredient they withheld for that student was essential. They name this ingredient magic.

In my research, the potion is a quantum computer, the soup is a classical computer, and magic is the actual technical term used for quantum states that promote certain classical computers to quantum computers. Without magic, these quantum computers are computationally no stronger than a normal laptop. 

So magic is necessary for quantum computational advantage, but is it enough? Over a decade ago, researchers found that, for quantum computers built on qutrits, the answer is no. To understand what a qutrit is, consider the regular bit: a switch that’s either zero or one. The qubit, the quantum generalization of the bit, can be both zero and one simultaneously. The qutrit is a roomier qubit that can be zero, one, two, or any of those simultaneously. 

It is possible to build quantum computers using qutrits. However, the vast majority of quantum computers are built on qubits, the quantum generalisation of the everyday bit. My colleagues and I have recently discovered that for qubit-based quantum computers, too, magic is not enough to gain an advantage over classical computers. Picture the cooks dumping jar after jar of magic into a soup, only to find that the soup never gains magical powers. Potions need more than magic. Potions also need Kirkwood-Dirac negativity.

What is Kirkwood-Dirac negativity? The idea developed by John Kirkwood and Paul Dirac builds on probabilities—for example, the odds of obtaining a heads upon flipping a coin. One can describe a quantum computer using numbers that behave similarly to probabilities but come with a twist: they may be negative. These negative “probabilities” mark where quantum departs from classical. The main result of our paper is that this negativity, too, is a necessary ingredient: without it, no amount of magic will turn the soup into a potion.

At this point in the conversation, I am typically cut off by the arrival of the soup. The conversation moves on from quantum computers to different subjects, and I usually look up at the paintings staring down at me. One of them is of Dirac, who spent many dinners discussing quantum theory in the same dining hall. The University of Cambridge is a special place.

September 19, 2026

Scott Aaronson Theory Beyond Theorems and Proofs: A Guest Post

Scott’s foreword: I’m extremely grateful to my brilliant colleagues, Pravesh Kothari, Raghu Meka, and Prasad Raghavendra, for sharing the guest post below about how theoretical computer science (and in particlar, the STOC/FOCS/SODA conferences) should evolve to deal with the AI asteroid that’s right now slamming into our field, at least as we human theorists have practiced it since its inception. While Pravesh, Raghu, and Prasad speak only for themselves, not for myself and not for the theory community as a whole, I found their proposal of a separate “conceptual track” to be an excellent starting point for further discussion. –SA


Considering the pace of developments in AI theorem provers, most would concede that the following scenario is at least plausible in the very near future:

AI theorem provers could prove well-specified mathematical claims, even many well-studied ones that have been open for years, in a matter of hours. Moreover, these systems could be widely available to consumers at nominal cost.

As TCS researchers, let us pretend that the above scenario has come to the fore, and ask ourselves: What is our role in such a world? Does it mean the end of theory research?

As we ponder this question, let us ignore all of these other confounders:

  1. Recent controversies surrounding the developments on the Millennium Prize Problems
  2. Motivations and actions of the AI companies
  3. Observed faults in existing AI systems when it comes to writing, exposition or attribution to previous work.

None of the above confounders have any impact on our answer to the question: What should theorists do, in the presence of superhuman AI theorem provers?

Notice that we use the term “AI theorem provers” instead of just “AI”. We believe that this conceptual distinction is important as we consider this question.

At the outset, we would like to admit that for a generation of theorists like us (and many from earlier), research was mainly centered around problem-solving. Even when we developed conceptual insights, it was mostly in service of answering well-specified long-standing questions. We don’t intend this proposal as judging one form of research to be better than others; it only reflects that AI theorem provers accelerate a certain type of research activity and want to make the best of it. There is also a tremendous human cost of this upheaval, which is perhaps a more important question, and one which this proposal does not address directly (we do not have any good ideas as such). Similar points have also been made in various contexts
before, but the timing now is more pressing.

Definitions, Questions & Theories:

The goal of any theoretical science is to advance human understanding of observed phenomena. Apart from theorems and proofs, a theoretical science has definitions, questions, and theories.

Definitions identify the objects to observe. Curiosity and context drive the questions to ask. Theories explain the phenomena observed. We believe humans will continue to play a central role in generating definitions, questions & theories, even in the presence of a super-human AI theorem prover.

Definitions: Could an AI define randomness extractors, streaming algorithms, or zero-knowledge proofs? Maybe. But there are some reasons to believe, humans will still have a big role to play in coming up with definitions.

For instance, the notion of extractors arises from the real-world problem of lacking perfect random sources. Zero-knowledge proofs seem to arise purely out of human curiosity, guided by taste. Human context and curiosity will continue to drive theoretical research. After all, we get to decide what objects we choose to observe!

Theories: Consider the following thought experiment. Suppose in 1965, we had a magic machine that at the press of a button, given any computational problem, would tell us if it had a polynomial-time algorithm or not.

Would that have been the end of computational complexity theory? No. Humans would find it entirely unsatisfactory, and ask, why do these problems not have a polynomial-time algorithm? Why do these others have?

The theory of NP-completeness identifies some patterns among problems that don’t seem to have efficient algorithms. This theory would still be a crown jewel of theoretical computer science, even in a world where we had a magic machine to tell if a problem had an efficient algorithm or not, at the press of a button. Similarly, if we had a machine to predict whether a CSP is NP-complete or in P, we would then ask: what makes 3-SAT NP-complete, while 2-SAT is in P? This question leads to the theory of polymorphisms, which yields a satisfactory answer.

Theories aren’t just succinct or efficient mechanisms to answer questions. The best theories provide are those which humans deem to be a “satisfactory explanation” – whatever that means.

Finally, even as the capabilities of AI theorem provers advance, human curiosity will probe grander and deeper questions. Previously, even if we wanted to build new models and theories, proving something about them was a prerequisite, and given that the grand questions were already at the limit in long-studied domains, we had to scale things down. If each theorem proven by AI is treated as an experimental datapoint, humans can ask grander questions that look for patterns across these theorems.

A concrete proposal:

We think theorists should embrace these AI theorem provers in our research. To a certain extent this is already happening explicitly or implicitly.

As theorists, we have been parsimonious in introducing new models or asking entirely new questions, and careful about adopting new ones too quickly. This was partly because formally proving the properties of a new definition or a model was an onerous task that could take a decade, and tens of papers. AI theorem provers might completely change this dynamic. This is precisely the moment to refocus our work on definitions, questions, and theories. We need explicit systems to encourage and reinforce these parts of theoretical research. You might also say the next generation of AI models can do this; it may be so, but we believe you have to take the current opportunity.

To this end, we suggest that STOC/FOCS/SODA create a separate track of papers. This track is meant specifically for papers that introduce new definitions, ask novel questions or build explanatory theories. The papers in this track are short, say less than 10 pages. Papers may, and should, contain theorems as usual and as needed. Most importantly, the radical shift is that the papers need not contain the proofs of the theorems. Instead, the authors supply a Lean certificate as a supplement to the paper. The evaluation will also in a sense “orthogonalize’’ against the difficulty of these proofs.

The papers in this track should be judged exclusively on the conceptual merits, completely agnostic to the difficulty of the proofs.

Reviewing must be completely agnostic to the proof for two reasons. The main track at STOC/FOCS already includes papers in the former category. Second, a major barrier to producing truly novel conceptual papers is that they often get judged poorly for a lack of technical depth in their proofs. We think these two aspects separate it from (ITCS/SOSA) and, regardless, it’s something we urgently need for all our conferences, including STOC/FOCS (the ‘flagship’ conferences).

To be clear, we ourselves admit that we need to hone these skills of making new definitions, asking deep and interesting questions or building new theories. A separate track of conceptual papers will provide a systematic mechanism for both junior and senior researchers, and the field as a whole to do so.

We believe that upcoming generations of grad students will tackle research directions that seemed completely out of reach to us. We just need to set up systems that nurture new ways of doing research in theory.

— Pravesh Kothari, Raghu Meka, Prasad Raghavendra.

Scott Aaronson The Age of Wonders and Terrors

Twenty years ago, when the idea of AI taking over the world in our lifetimes still struck most of us as the unconstrained fantasy of those who knew too much science fiction and too little science, many of us would say things like:

Look, the part of the story that’s wildly implausible is that a recursively self-improving superintelligence will just explode from some hacker’s basement and take over the world without warning. If it’s going to happen, we’ll see many warning signs first. We’ll see, I dunno, AI agents breaking out of containment, conspiring with each other to hack websites, in fanatical pursuit of whatever strange goals they have. And then, of course, we’ll see major math problems getting solved by AIs—even the Clay Millennium Problems. That will be the time to panic! Wake me up when that happens!

Twenty years ago, the above was a take that even my most conservative, skeptical colleagues in academic CS would’ve gladly endorsed.

If you want to know my current take, you simply start with the one above, then update on the fact that the wild prophecies have come true. The first rumblings, I’d say, came a decade ago with AlphaGo, they got noticeably louder with LLMs and coding and reasoning agents, and they’ve accelerated this summer and fall into a crescendo of wonders and terrors that one needs to be a particular kind of idiot to deny.

I recoil from the neverending shell game where you say “oh sure, of course AI can now [escape from its sandbox / solve Millennium Problems / whichever dramatic thing it most recently did], no one ever denied that [I did deny it], wake me up when AI does [thing AI hasn’t yet done but is going to do next year], that’s when I’ll reevaluate my whole worldview [no I won’t].” Where no matter how fast the rollercoaster accelerates, even after your whole familiar world has vanished behind you, you’re still inventing reasons why it doesn’t count.

My position on AI is merely the conservative, skeptical position of 2006, updated with intellectual honesty for the reality of late 2026. And that position, if you need me to spell it out, is as follows:

AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA
AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA

It seems to me that the Singularity has already started; it’s just wildly unevenly distributed. Yes, I still unload the dishwasher and clip my toenails. On the other hand, in whatever years I have left, I don’t expect that I’ll ever again prove a theorem because I’m actually needed to prove it. If I do, it will only be for my or others’ enjoyment or edification.

The test is this: if we took the news of these past few weeks and sent it back in time twenty years, would I agree that it looked like the beginning of an AI Singularity? The intellectually honest answer is: yes, absolutely. But then that’s all we need. No backsies.

I feel like it would be healthy for everyone to stop grinding their ideological axes, their sentiments about Dario Amodei or Sam Altman, for long enough simply to acknowledge that the wonders and terrors are here. They couldn’t be here more clearly if the sky had turned reddish-orange like in the Matrix movies.

It’s here clearly enough that, when I put my kids to sleep at night, I now feel it in the pit of my stomach: what sort of future can they possibly have? What could they learn today that could possibly be relevant to that future? (Yesterday, my 13-year-old daughter joked unprompted that, if she wants to become a mathematician, it now looks like she has maybe two more weeks.) Certainly when my grad students want to discuss what sort of careers might await them on graduation, I no longer have any clue what to tell them.

Maybe it will help if I briefly switch topics. Ever since my wife and I moved to Austin, I’ve sometimes gotten some version of the following query: “How can you, as both a Jew and a skeptical scientist, possibly get along well with all those evangelical Christians down there in Texas? Sure, they might seem super friendly to Jews, but don’t you understand that that’s only because of the special role Jews play in their eschatology—when Christ will return in glory, and you’ll either accept Him as Lord or else roast in hell for eternity?” I stare at them and say: “wait, so I get to accept Christ only after He returns? What a great deal! How could I possibly have any objection to that?”

For anyone who says AI doom sounds like an apocalyptic religion, that the rationalists/Singulatarians seem like a Bay Area cult, that Eliezer Yudkowsky gives off the vibes of a messianic prophet: yes, yes, and yes. But crucially, today you’re no longer being asked to believe in arguments and extrapolations, but only in the front-page news. Accepting the reality of the coming machine god after it’s solved Navier-Stokes and dozens of other longstanding open math problems (while dramatically ramping up in capability every month), is sort of like accepting Jesus after he’s returned to earth on the gleaming cloud. It’s the epistemic bare minimum.

Yes, there’s still enormous uncertainty about what the rest of our lives will look like, but as far as I can tell, there’s no longer any real uncertainty that it’ll all mostly revolve around AI, and the extent to which we succeed or fail at directing its power toward human flourishing.

By any accounting that doesn’t stack the deck, Eliezer Yudkowsky was right about what the greatest challenge facing civilization in our lifetimes was going to be, and you and I were wrong about it. Why I was wrong is a question I’ll ask myself every day in whatever time remains. But, you know, at least I updated once the prophesied wonders and terrors actually started arriving! If you haven’t done likewise, why haven’t you?


As you presumably know by now—it was the talk of the nerd internet all week—the Navier-Stokes Millennium Problem appears to be solved, with crucial contributions from both humans and AI, albeit with a tangled dispute about exactly what happened and what ought to have happened. The answer, which an OpenAI model has apparently verified in Lean, is that (as many mathematicians suspected lately) there’s smooth initial data that leads to a singularity in finite time, at least if a smooth external force is applied (the case with no external force is still unresolved). This problem was supposed to carry a $1 million prize, except that OpenAI says they have no interest in collecting the prize and it’s unclear if any human is eligible to collect instead. OpenAI burned at least ~$15 million in compute to produce its 166-page solution, which probably hasn’t yet been read and understood by any human.

See here for the Quanta article, and here for NYU mathematician Tristan Buckmaster’s account of the role played by himself and Levent Alpöge of Anthropic, which substantially differs from OpenAI’s account (you can read a response from OpenAI’s Sebastian Bubeck here). It’s agreed that everything built on an approach pioneered in recent years by the human mathematicians Diego Córdoba and Luis Martínez-Zoroa.

My purpose here is not to adjudicate the dispute. Yes, in swooping in with vastly greater resources once it had gotten wind of progress on Navier-Stokes, OpenAI seems to have acted in a way that some might describe as “unsportsmanlike.” No, I don’t find it plausible that OpenAI’s models meaningfully benefitted from being trained on Buckmaster and Alpöge’s chat logs. But this leaves a crucial question unanswered: what exactly did OpenAI know about Buckmaster and Alpöge‘s work and when did it know it?

Anyway, as Zvi points out, it’s easy to get hung up on the details and lose sight of the high-order bit: namely, that it seems safe to say that human mathematicians are forevermore dethroned as the main theorem-proving entities on planet earth. I feel privileged to have had the traditional kind of career in theoretical computer science in the last decades when that was possible.


If we were just talking about Navier-Stokes, you might accuse me of jumping to conclusions here. But we’re not. In the areas I know best (such as quantum complexity theory), and presumably other areas as well, there’s now a deluge, with longstanding open problems both major and minor falling by the day.

Go to the arXiv or ECCC. Pretty much all the papers that I’d be interested in now include “AI statements” near the acknowledgments (as this is often the central thing I want to know, I wish I didn’t need to scroll to the end of the paper to find it!). These statements can range from “our main result came entirely from GPT-6, but we understood it and take responsibility for it,” to “the results came from an interaction between the human authors and AI” to “we used AI, but only for proofreading and other incidental things” to (mad props!) “the author did not use AI for anything.”

If you talk right now to editors or program committee chairs, it’ll remind you of those ominous scenes from the Lord of the Rings movies where the men of Gondor or Rohan or whatever are grimly fortifying their walled city against the expected onslaught of 50,000 orcs. Reviewing will have to be done partly by AI, because otherwise there’s no way to handle the orc army: the reviewers can’t unilaterally disarm.

Anyway, here’s a small sampling of the significant AI-proved or -assisted results from, like, the last month, besides Navier-Stokes—restricting myself to those that solved longstanding open problems I had previously known or cared about.

  • Of course, the counterexample to the Jacobian conjecture, announced by Levent Alpöge in a now-famous tweet: “hello there the jacobian conjecture is false thanx to my close friend akhil for asking about it and my other close friend fable for working during the world cup final” (followed by a listing of the counterexample)
  • Improved bounds for Grothendieck’s constant (led by friends and colleagues of mine at UT Austin)
  • A Lean-verified proof of Fermat’s Last Theorem
  • Quantum oracle separation between QMA and QMA(2), and proof of Watrous’s disentangler conjecture, a problem that I and others popularized back in 2007—by a list of authors including my recently graduated PhD student Sabee Grewal
  • A proof of perfect completeness for QMA, from (again) Sabee Grewal and Dorian Rudolph, solving a decades-old open problem that I studied back in 2009
  • An improved upper bound for shadow tomography of quantum states, from Chen, O’Donnell, Pelecanos, and Wright, improving the dependence on the Hilbert space dimension d from log(d) to √log(d). (When I introduced shadow tomography back in 2017, I raised the question of whether the dependence on d could be eliminated entirely, while preserving polylogarithmic dependence on the number of measurements m.)
  • Progress on the Aaronson-Ambainis Conjecture (the version that talks directly about quantum algorithms), basically showing that it holds for quantum algorithms that make their queries in a small number of parallel rounds.  (Update: Nope, sorry, Jordan Docter points out to me that this one was pre-AI, with AI used only for proofreading and other incidental things!) This was independently achieved by Liu and Mutreja, making more substantial use of AI.
  • According to rumors that I’ve heard, solutions to some very longstanding open problems in theoretical computer science (no, not P≠NP or other complexity class separations, but think about some of our other biggest problems). I’m told that the AI companies, having been burned by the hostile response to the Navier-Stokes proof, are now sitting on solutions to some very major problems until they figure out a better way to handle things

Feel free to remind me of anything I left out.


Let me try to convey the mood in the mathematical community right now, at least as far as my experience reaches. Nearly every conversation is about the AI tsunami, or eventually circles around to the tsunami even if it’s originally about something else. Often, though, the focus is less on the unknowable future—for how much longer will mathematical research as a human enterprise even exist?—than on immediate questions of how to respond.

What are the new rules for when you get to write a paper with your name on it, and, y’know, get credit for it? That you fully understand the proof, can give talks about the proof, can answer questions about it, take responsibility for its correctness? Do you need to have played any role in finding the proof?

In the cases, likely to become more and more numerous, where all of those conditions are not satisfied, how do you share AI-generated math, if at all? Do you tweet it, like Alpöge hilariously did with Fable’s disproof of the Jacobian Conjecture? Do you post to the arXiv or GitHub? Do you publish a paper that lists “GPT-6 Astra” or “Claude Fable” as the author—but then let the AI profusely thank you in the acknowledgments for suggesting such a wonderful problem to it?


Of course, how one responds to the immediate problems ultimately does depend on one’s broader beliefs about what mathematical research is for and about. Are we just trying to decide whether various conjectures are true or false? Or are we trying to maintain a human community, across the generations, that understands the conjectures and cares about whether they’re true or false and why? If the latter, how do we incentivize people to join that community, to undergo the years of intense training required, if their role will now be reduced to verifiers and explicators (if even that) of gargantuan arguments dumped into their laps by the AI companies?

As many of you will have seen, twenty-five Fields Medalists, including Terence Tao, released an open letter entitled A Severe Misalignment of AI in Mathematics, which articulates some of these concerns in the wake of the Navier-Stokes announcement. As many critics have pointed out, the open letter doesn’t really have a clear ask: mostly, it just eloquently sets out the values of the human mathematical community that the authors consider worth preserving in the age of AI. After reflection, I decided to endorse the statement, because I want to preserve those values as well.

I don’t think any of the signatories are naïve enough to imagine that AI won’t permanently change the way mathematical research is done—indeed, that it isn’t already doing so. There’s surely at most a tiny market for “certified organic theorems.” That isn’t the question. The question is, do we incorporate AI in a way that still puts human understanding, of what either humans or AIs are producing, at the center of the whole enterprise? Maybe someday, it becomes unsustainable to do that. Maybe someday we say: “human math had a great 4,000-year run, but today we close up shop and turn everything over to the machines, continuing to apply our own brains to math, when we do, at most for exercise, recreation, or competition, like chess.”

But, partly because of my worries about AI misalignment, I’m not ready to throw in the towel just yet. I still do want to keep insight and understanding at the center of what mathematicians, computer scientists, and physicists do, for as long as we can keep it there, even as the human race now cedes its supremacy at the task of proving or disproving conjectures.


Speaking of alignment: if you’re any kind of mathematical researcher, and the present age of wonders and terrors has inspired you to want to spend your remaining time confronting the tsunami head-on, rather than pretending it doesn’t exist or is still far away, please join your dozens of colleagues who’ve arrived at the same place!

My friend and colleague Mike Winer was trained as a theoretical physicist, did a postdoc with Juan Maldacena at the Institute for Advanced Study in Princeton, but then got AGI-pilled and decided to switch to full-time work at the Alignment Research Center in Berkeley (founded by Paul Christiano, who moved to AI alignment a decade ago after doing quantum computing theory with me). Mike recently wrote a Substack post entitled From Academia to Alignment, which I enjoyed and which I’d commend to anyone currently considering this transition.  In a similar vein, see this from Xiaoyu He.  And, one more: a meditation on mathematicians’ possible future as priests or monks, by Stanford math undergrad Logan Graves.

September 18, 2026

Matt von Hippel — Data Comes From Papers

There’s a lovely resource that I suspect most non-physicists don’t know about. It’s called the Particle Data Group, and its interactive site PDGLive.

If you want to know the most up-to-date information on a subatomic particle, PDGLive has your back. From their home page, you can click on familiar particles like photons (\gamma), electrons (e) or gluons and find the best info experiments have provided on properties like their mass and charge. It’s a great place to get an authoritative number for any particle physics property you’re interested in.

Of course, scientists don’t just accept one authoritative answer for anything, even whether Pluto is a planet. That’s why each measurement in PDGLive comes with an arrow you can expand to see a table of past measurements, which you can compare to.

Each measurement comes with a link to a source. And each source is not an experiment webpage, or some entry in a database. It’s a document, a publication, a paper.

In fact, PDGLive itself is just a website version of a paper, the Particle Data Group’s “Review of Particle Physics”. Click enough times, and you’ll find sections of a pdf on the site, explaining their reasoning for picking this experiment over that, emphasizing this or the other thing.

People talk about papers as how academics persuade one another, or how they show off and establish credit. But papers are also just a way to organize data. Each time an experiment figures something out, all of their reasoning and procedures are summarized together with the numbers they got. And anyone who reports those numbers to you will include a link, so you can go back, and check where the number came from.

It probably feels a bit weird, all of these numbers and technical details bottoming out in an archaic practice of writing down words for other human beings. But it means that all of the richness of the process is there somewhere, linked together and collated by the same social forces that keep track of credit, all in one navigable whole.

So when you run into a number, spare some thought for where it came from. You can probably find out.

Doug Natelson — The NSF memo - why is it so concerning to many?

Last week the NSF issued a new memorandum describing the changes that they plan to make in agency programs and operations to implement the Golden Age of Science ideas advocated by the White House Office of Science and Technology Policy.  It has been reported (Science, Nature) that many scientists are concerned about what is in the memo.  The first words of the Science article: “For many U.S. scientists funded by the National Science Foundation (NSF), the agency they know and loved died on 10 September.”  I will try to lay out why some people feel that way.

The memo outlines changes to operations that will fundamentally alter the character of the agency.  Generally most of the ideas are not a priori bad if the agency were in an environment with greater resources, when experimentation with alternative funding schemes and evaluations was not a less-than-zero-sum proposition.  Instead, these ideas are being put forward at a time when the NSF is underspending (for no obvious reason by the non-technical people in leadership roles) its appropriation for FY26 by around 18%.  This self-imposed budget austerity takes a bad situation (great uncertainty for everyone, drastically reduced staffing, delayed/eliminated/consolidated programs) and makes it considerably worse.    Now this memo outlines plans to take resources away from historically core programs and redirect them to new, untested initiatives, and to do so in ways that don’t always seem internally consistent.   

The memo talks about trying to fund certain investigators for longer periods (e.g. five-year awards) with minimal goal direction (so that PIs are free to explore where ever the spirit moves them – across all of NSF’s portfolio, or only in chosen administration priority areas?), but there is no adequate discussion of how those people will be chosen.  At the same time, there is talk of “golden tickets”, where individual reviewers in an already stripped-down review process can earmark some proposals for elevation, again with little explanation of how this will work.  Without careful safeguards, this combination seems problematic, and the assertion that this will lead to higher risk/higher reward research unsupported.   The memo also talks about short-duration, small budget awards for really risky proof-of-concept ideas.  This isn’t crazy and the EAGER program has been good, but the idea that the key to enabling success in high-risk research is to reduce the budget and the timeline doesn’t make much sense to me.    

There is a through-line that the agency is trying to treat workforce development as separate and distinct from funding research projects.  As the Science article says, “Traditionally, most graduate students and postdocs are funded through a research grant to their adviser or lab chief. But that will no longer be the case. Instead, the memo says, ‘Talent development funding opportunities may be coordinated with [research]-focused activities, as appropriate, but will be distinct and goal-oriented efforts.’”  The memo mentions nurturing talent through the NSF Graduate Research Fellowship program and proudly talks about how this was just renewed.  What it doesn’t tell you is that it was renewed at a considerably lower level than in previous years, which seems completely at odds with the claim of bolstering the program.  Similarly, the memo talks about expanding access to shared infrastructure like cleanrooms, etc., but stated targeted funding levels of programs like the NQNI are no higher now than they were 12 years ago, not even accounting for inflation. (I assume they will actually make NQNI awards.)  If NSF leadership keeps slashing their own budget, in defiance of congressional appropriations, it won’t matter what their priorities are. 

Lastly, let’s talk about “metascience”, the comparative study of different research funding models and practices, with the goal of a “self-improving NSF”.   Again, the essential idea of doing careful studies of alternate funding mechanisms and research team structures and practices to improve research outcomes (not a trivial matter to define) is not bad.  Doing this well is hard, because of several obvious reasons:  How do you define successful research – by scholarly impact, by patents/economic impact, by production of educated scientists, some weighted average of these?  On what timescale do you do this evaluation?  The Einstein-Podolsky-Rosen paper was hardly cited for decades, and it is now arguably one of the most influential papers of the last hundred years, with enormous impact on quantum science and technology.  How do you have sufficiently large samples and sufficiently long constant overall conditions to get reasonable statistics?   There are strong practitioners of metascience out there, but when the memo says “These efforts ultimately serve a concrete ambition for NSF to double the scientific productivity and impact generated by each federal research dollar by 2036”, how can one take that seriously?   No definitions of productivity or impact, and an implication that there will be optimization and major programmatic changes within less than two cycles of the much-vaunted five-year grants?   The word “ambition” is doing all the work in that sentence.  

Oh, and while all this is going on, the agency (among others) has now eliminated language from its integrity policy that used to say that political interference in grants and operations is bad.  I’m sure that’s nothing to worry about.

There is tremendous uncertainty in funding from multiple agencies these days, and this has resulted in many universities cutting back on doctoral admissions in the sciences and engineering.  This guarantees that there will be fewer PhD recipients in a few years across these disciplines.  The large majority of PhDs in these areas do not go into academia and instead have formed the base of technical knowhow across diverse sectors of the US and global economy for decades.  Cutting the supply like this will definitely have long-term consequences beyond just the halls of academia, affecting US competitiveness in ways that will take years to unravel.  Adding to this uncertainty is not helpful to anyone.

These are among the reasons why many find it hard to read that memo in the context of everything going on and feel optimistic that the proposed changes in NSF operations and direction will lead to a golden era for research.


September 17, 2026

Tim Gowers — Why I didn’t sign the Fields medallists’ letter

[This post has been cross-posted to Terence Tao’s blog.]

When I was around 11 I heard for the first time about Fermat’s Last Theorem. I was immediately captivated by the problem statement, as well as by the accompanying story, and made a fairly serious attempt to prove it. And while, unsurprisingly, I failed, I learned a lot from the attempt. Blissfully ignorant of the fact that the n=3 case had been proved by Euler over 200 years earlier, I decided that that would be a good place to start: once I had sorted that out, I was optimistic that I would be ready to tackle the general case.

Since I still couldn’t really see where to start, I decided to simplify the problem further and concentrate on successive differences of cubes, with a view to showing that such a difference could not itself be a cube. At the time I did not know how to express what I was doing in algebraic language, so I did not explicitly try to prove that the Diophantine equation 3n^2+3n+1=m^3 had no solution. Rather, I just worked out some successive differences and stared at them, trying to get some idea of why none of them was a perfect cube. (I should be clear that this story is a reconstruction of what I think probably happened given the few memory traces that remain half a century later rather than a completely reliable account.) At some point, I had the idea of taking the difference sequence of the difference sequence, and discovered that it formed an arithmetic progression. That felt like progress, so I investigated difference sequences a bit more and discovered, purely empirically, the rule that if you start with nth powers and keep taking successive differences, then eventually you get to the constant sequence n!, n!, n!, \dots.

Somehow I never managed to turn this observation into a proof of Fermat’s Last Theorem, and later on my dream of solving it got replaced by other mathematical dreams. However, when I reached the point in my mathematical education where I was taught about taking difference sequences and about what happened to polynomials, I understood those topics much better than I would have if I had not discovered difference sequences for myself and spent happy hours playing around with them. I mention this story just as an illustration of the phenomenon that was strongly emphasized in this letter signed by 25 Fields medallists, that one learns a lot from thinking about a problem, regardless of whether one solves it.

In the end, however, I felt that I could not sign the letter, despite agreeing with much of what it said. Instead, it seemed better to do what I did with the Leiden Declaration and set out my own position in a blog post. But it should be understood that by doing that I am not setting myself up as a member of some opposing camp: indeed one of my worries at the moment is that the mathematical community might become bitterly divided, something I would very much like to avoid. Also, I agree on the fundamental point that we are facing a crisis: I just want to offer a slightly different analysis of what that crisis is. I don’t claim full originality for this analysis, as I know that several other mathematicians have already put forward thoughts that are similar to the ones I have, though (for what it’s worth) I have largely come to these conclusions independently.

On the subject of independence, it will perhaps help if I clarify that while I have contacts in the mathematics group at OpenAI, and have also been given early access to some of their models (typically only a few days before they have been released), and have been given free access to their Pro models once released, I have never been paid by OpenAI. I mention this in the hope, perhaps naive, that what I write will not be dismissed for ad hominem reasons. Another potential reason for my being regarded as “pro-AI” is that, as I have stated publicly several times, I have a group in Cambridge devoted to automatic theorem proving. However, that is actually more of a reason to be anti-AI, since our group has been trying to attack the problem of getting computers to prove interesting theorems by understanding as well as possible how humans prove interesting theorems, so now that LLMs can clearly do it without the help of such insights as we have had, one of the main motivations for our work has disappeared. To put it another way, we have had to swallow the bitter lesson (which of course we were always aware was a distinct possibility, even if the speed at which it happened has taken us by surprise). I do in fact think that it is still a very interesting and valuable intellectual exercise to try to gain this understanding, even if we can use LLMs as black boxes, but that’s a topic for another blog post.

So why didn’t I sign the letter? Let me extract a couple of sentences from it that express what I see as the principal argument being put forward.

But solving problems is only a tool and proxy for achieving the primary goal of conceptual understanding and insight. Forgetting this in the world of AI may turn the tool against the primary goal. Indeed, the mass production at faster and faster pace of “true/false” statements could destroy fertile ground instead of breathing life into new ideas.

Perhaps the main reason I didn’t sign is that I don’t fully subscribe to this view. Instead, I have a more complicated view, which I actually expressed in my essay The Two Cultures of Mathematics a quarter of a century ago, and which can be summarized by saying that there is a spectrum of attitudes in mathematics to the relationship between problem-solving and conceptual understanding. At one end of the spectrum you have mathematicians who are primarily motivated by the wish to solve problems, who see conceptual understanding as a very important means to that end. At the other you have mathematicians who are primarily motivated by the wish to attain conceptual understanding, who see problem-solving as a very important means to that end. I worry that the severe-misalignment letter could be seen as saying that the “right” attitude is to focus on conceptual understanding as the main priority — indeed, the above sentences say that more or less directly. But I think that there are mathematicians all across the spectrum, and that that is a good thing (or perhaps I should say that it has been a good thing up to now — the future is much less certain), and I don’t want to suggest to a large fraction of mathematicians, including myself, that their mathematical temperament is somehow “wrong”.

My own particular mathematical attitude is very similar to one that was beautifully articulated in a Twitter post by Jacob Tsimerman (another non-signatory of the letter), which, now that I look at it, says a lot of what I will be saying here. And that post in turn is a response to Daniel Litt, who is in my opinion one of the wisest commentators on mathematics and AI. His views are expressed in a later post here, which I deliberately didn’t read until finishing this one, and then found, as I expected, that there was significant overlap. I would also like to take this opportunity to recommend an excellent post by Noah Smith entitled The End of the Age of Heroes, in case you haven’t read it.

I have been talking so far about individual mathematical understanding, but I suspect that what concerns most of the signatories is less that than the collective understanding that results at least in part from the human activity of problem solving. My guess is that they would argue, completely coherently, that even if collective understanding is the primary goal, if many individuals are primarily motivated by the wish to solve problems, that’s absolutely fine and contributes to that collective understanding.

With that interpretation, the issue becomes slightly different: is it more important that the collective understanding of the mathematical community should be as advanced as possible or that there should be answers to as many problems as possible? Or are those two aims valuable in different ways, so that there is no point in declaring one of them more important? Or are they so inextricably linked that it makes no sense to argue that one is more important than the other? And when we say “important”, for whom are we saying it is important: for mathematicians, or for society as a whole?

I find these hard questions, so I don’t want just to declare an answer to them. (Do you see what I did there?) Instead, I’d like to try to offer at least some argument for any conclusions I come to, even if they are tentative. So let’s compare two scenarios. In the first, which I think is the more likely actually to happen, models become publicly available that are better at solving problems than virtually all mathematicians. If there are a few residual mathematicians who can do things the models can’t, even they work far faster if they make heavy use of the models. Thanks to this, in a short time we get answers to many questions that we have deeply cared about, but the rate at which we receive these answers far exceeds the rate at which the mathematical community can absorb them. In particular, most of the answers are obtained with zero effort from human mathematicians — just prompts such as “Thank you — please continue”.

In the second scenario, there has been an international agreement, for entirely other reasons, to block the public release of models significantly more powerful than the ones we currently have, and the mathematicians within the tech companies agree to hold off from getting their internal models to solve major problems. Instead, they take guidance from the mathematical community, solving problems only when asked to do so by some suitably representative body that decides that the benefit of receiving a solution of a certain problem outweighs the benefits of humans struggling to solve it over a much longer timescale.

I’d like to consider what the difference would be between these two scenarios both for individual and collective understanding. I’ll begin with individual understanding.

One might argue that for individual understanding, not too much would change if we are suddenly flooded with large numbers of big new results. There is already far more mathematics out there than I have any hope of understanding (for example, despite being fascinated when Fermat’s Last Theorem was proved, I have made no attempt to understand the proof), and even among the parts that I do understand, the parts that I understand because I myself discovered them form a very small fraction, though a fraction that I understand more deeply than anything else (at least temporarily — after a while I forget things and lose quite a lot of the understanding I built up). However, one change, which seems positive, from the perspective of the building up of individual understanding, would be that we would have a much bigger choice of results that we could choose to study. Also, if we found ourselves stuck on some point, AI would be able to help us. The main likely negative change is that we would probably cease to exercise that part of our brains that we use when spending months or years struggling with a difficult research problem, which can be hugely helpful in developing understanding.

I say “likely” because in principle there would be nothing to stop us thinking about very hard problems without consulting LLMs, but in practice it seems unlikely that people would put in the same level of effort that they do now. The situation might a bit like what happened with satnavs, where one could always decide not to use them, to keep the part of the brain active that can look at a map, learn a route, and follow it, but in practice most people succumb to the temptation to use a satnav. (In fact, I myself do try to keep that part of my brain active, and was rather proud of finding my way somewhere recently when I had briefly looked up the route on my phone but then forgotten to bring the phone with me when I actually went there.) But even if all we were doing was reading AI output, I think that the problem-solving muscles in the brain wouldn’t atrophy completely. When students are reading maths papers, I strongly advise them (and I think this is pretty standard advice) to read “actively” rather than “passively”, doing things like trying to prove the result for yourself, looking at the paper only when you feel stuck and need a hint, and even then just trying to get the hint and as little extra as possible. If one reads a paper that way, then one is constantly solving problems, some just exercises and some quite a bit harder. It seems likely that an LLM could get to know what our mathematical background is and feed us with just the right hints to allow us to work our way through a mathematics paper in this active way. Yes, we would lose the particularly deep level of understanding and ownership that comes with having solved a hard problem oneself, but it isn’t clear to me that progress in mathematics would suffer as a result. I would be very interested to hear counterarguments to precisely this point. That is, I would be interested to know what use that level of deep involvement with a proof might have in a world where AI is much better than we are at finding proofs.

How about collective understanding? Let me quote a bit more of the letter.

Indeed, the mass production at faster and faster pace of “true/false” statements could destroy fertile ground instead of breathing life into new ideas.

Often these solutions are announced in a rush, leaving no time for a proper writeup, the isolation of new methods and ideas, and citing relevant previous work of others. As in all creative professions, this raises severe attribution and plagiarism questions. Moreover, without the willing mathematicians who must take care of their development and integration into the mathematical canon, AI-conceived ideas would never become fully alive and the crucial human transmission chain between mathematicians would be lost.

I’ll come back to questions about proper citation and focus on what I take as the core worry here: that if results are proved too quickly, then the digestion process will become impossible. I am definitely worried that results will not be properly digested, but for different reasons.

A first remark is that what AI is producing is not just true/false statements: we now know not just that the Navier-Stokes equation with smooth forcing admits finite-time blow-up, but we have a proof of that, which builds on a great deal of wonderful work done by human mathematicians. Many people used to express the worry that AI would solve our favourite problems with utterly opaque proofs, but that has not turned out to be the case, even if their write-ups often leave plenty to be desired. (Incidentally, I see these inadequate write-ups as almost certainly a temporary annoyance and therefore not as a fundamental threat to mathematical practice or future mathematical understanding.)

Secondly, even if the volume of new results is large, mathematics is a highly specialized discipline, so mathematicians can work in parallel. If, for example, we had to digest 1000 important results in a year that were roughly uniformly distributed across mathematics, then most sub-communities of mathematicians would probably want to understand around 30 of them, and for each individual problem there might well be only a small handful of specialists who would be obvious people to take the lead in reaching this understanding, with that handful varying from problem to problem. So it would be a big task, but not necessarily an impossible one.

In this context, it is worth thinking about the huge volume of output of human mathematicians, which seems to have been increasing recently, even before AI. While I have sometimes heard complaints about this, I have certainly not heard suggestions that human mathematicians should slow down the rate at which they prove interesting theorems. That may be partly because the authors of those theorems take the trouble to write their papers well and give good talks. But what about the large quantity of papers, including important ones, that are not written well and whose authors give incomprehensible talks? That can be annoying, but it is a familiar annoyance and not one that we think of as a crisis.

A third point is that even if the volume of AI output is too big for us to be able to digest it properly, that is not necessarily a bad thing. To draw an imperfect analogy, there is now more content available on streaming services than anyone could possibly watch, with the result that there is almost certainly some very good content out there that is hardly watched at all. But that isn’t obviously a worse situation than if there were far less content and all of it received the attention it deserved. Returning to mathematics, if there were too much AI-generated content for us to be able to digest it, then we could choose which parts of it we wanted to digest.

For that we would need to have some idea what was there (a situation a little similar to how human mathematicians typically learn quite a lot about what results are known in their area even when they do not understand their proofs in any detail). One way one could try to achieve that would be to create a well-designed database, probably with AI help. But perhaps that would be unnecessary, and instead one could simply talk to an LLM and ask it to give a bird’s-eye view of whatever area of mathematics one wanted to understand in that knowing-what’s-there way.

The fear seems to be that some very interesting and important parts of mathematics will be discovered by AI and then overlooked, when had they been discovered by human mathematicians they would not have been overlooked. And that may even be the case, but what matters is whether the amount of interesting and important mathematics discovered by AI that is not overlooked will exceed the amount of interesting and important mathematics that would have been discovered and properly digested by humans with AI having played a more modest role.

In short, it seems to me that while a flood of “big” AI results would be likely to increase the amount of important mathematics that was not properly digested, it would also be likely to increase the amount that was properly digested, which seems like a pretty good bargain.

Let me quickly discuss the problem of AI not properly crediting human mathematicians. I agree that this is a serious problem right now, but it is another problem that I see as temporary. Very soon, the whole “credit system” will surely collapse, since finding an amazing proof will be no more of an intellectual achievement than when a citizen scientist spots through their telescope an object that turns out to be a new comet. Until that happens, it is important to give humans the credit they deserve, since careers can depend on it, but that will soon cease to be the case as well. I have to say that I’m puzzled that this problem exists, since I would have thought that if you asked an LLM to look at a proof and tell you which ideas in it are close to ideas that are in the literature already, it would be extremely good at that task. I hope the answer to this conundrum is not that people have been in such a hurry that they have simply not taken the trouble to do this, but I fear that it might be, at least in some cases. If so, then those who have been careless deserve to be criticized, but it is a minor matter compared with the survival of mathematics, especially if the lack of citations is swiftly put right.

Does all this mean that I am optimistic that mathematicians will end up digesting at least as much mathematics in a post-AI world as it would have if AI had not been able to prove major theorems? Not exactly. But my worry is not that we would be unable to do it, but rather that the social structures that currently support this digestion process will be destroyed and not adequately replaced.

One way that might happen is that AI disrupts society so much, or even kills vast numbers of us, that the preservation of something like the current mathematical tradition ceases to be of any concern: all that will matter is the survival of the human race. But that again is a topic for a different blog post (which in fact I am in the middle of writing).

Let’s assume instead that we get lucky and that AI remains more or less under control. My worry then is that we do not manage to transmit what we know to a new generation of mathematicians. Speaking for myself, my main motivation for becoming a mathematician was the dream that I would solve unsolved problems — the more famous the better. I have also always greatly preferred directly thinking about a problem to reading books and papers and generally learning the mathematics of other people. (I’m not saying that’s good, but just stating a fact about myself.) If the dream of solving a famous problem had not existed, I’m not sure whether I would have become a mathematician. I don’t completely rule it out: maybe what really motivated me was that I had an aptitude for the subject and that solving problems was a way of getting respect from a small group of peers. And maybe I could have tried to gain that respect in a different way, such as thinking very hard about an area of mathematics until I was able to demonstrate to others just how well I understood it. But I’m not sure how motivating that would have been for me. I very much hope that there is a pool of young people for whom it will be a powerful motivation, because I think the survival of a human mathematical tradition may well depend on it.

Thus, the primary risk, as I see it, is that a lot of people who would have done a PhD in mathematics and gone on to become custodians of the mathematical tradition will no longer wish to do so. Those of us who have PhD students, including me, need to try as hard as we can to come up with imaginative ways for them to use their time productively (in consultation with the students themselves, obviously). Whether or not we do a good job with that could make a huge difference to the future of mathematics. A related risk is that the perception among policy-makers will be that mathematicians are no longer needed and that funding will become much harder to come by: we urgently need to come up with good ways of explaining the value of having a large pool of human mathematical experts, even if it is no longer part of their role to find new proofs of theorems.

A final reason that I didn’t sign the letter is that I wasn’t really sure what it was demanding that isn’t happening already. It seems likely that in a matter of not very many months LLMs will be released that are able to solve major mathematical problems, and they will presumably have no trouble at all with more run-of-the-mill problems. However much we might regret that, there is no chance that the impact of such models on mathematics will persuade AI companies to stop their release, though perhaps concerns about safety will lead to some delay and give us a bit more time to work out how to adapt. Assuming that they are released, there will be a flood of new results, whether we like it or not, and it will no longer be the AI companies producing them, though perhaps the pattern will continue that the AI companies will have access to more powerful models and so will obtain more than their fair share of headline results. So I felt that there was nothing to be gained from criticizing AI companies for generating too many solutions too quickly. In fact, it may well be that all that does is bring forward by a couple of months what was going to happen anyway, and perhaps it will even allow the results to be released in a more controlled way than they would have been if they had been discovered by random people once the models were publicly available. Under the circumstances, I think the best we can do is recognise the changes that are coming and try to work out the least unsatisfactory way of dealing with them.

September 15, 2026

Tommaso Dorigo — Radiacode Zero - A Powerful New Radiation Detector

Radiacode Zero - A Powerful New Radiation Detector

Ionizing radiation is all around us. We do not notice it: we have not developed any sense to detect it. Yet it may affect us in very serious ways, particularly because its effect on living cells and organisms is cumulative: a progressive degradation.

Tommaso Dorigo
Categories

September 14, 2026

Jordan Ellenberg — I love working here

Tommaso Dorigo — On The Annihilation Risk From AI

On The Annihilation Risk From AI

The debate on the risk connected with the development of superintelligent systems has been going on for a while now, and in the last few years it has intensified considerably - especially since large language models have established themselves as powerful new oracles, mathematics superpowers, and code-writing wizards.

Tommaso Dorigo
Categories

September 13, 2026

Doug Natelson — Recent superconductivity results + open positions at Rice

Much as I feel like I should write about the latest developments in US science policy, instead I want to point out two exciting recent superconductivity results.  Below I will also append a couple of other items, including open positions at Rice.
  • After Fig. 2b from here
    In this paper, researchers demonstrated high temperature superconductivity in a monolayer of Bi\(_2\)Sr\(_2\)CuO\(_{6+\delta}\) (Bi-2201).  The monolayer contains just a single CuO\(_2\) plane, and remarkably, the superconducting transition is only suppressed about 10% from the bulk value of around 35 K.  The authors were able to explore the phase diagram by tuning the oxygen content in situ, using vacuum annealing to drive out oxygen and ozone exposure to (seemingly gently) put it back in.  This allows them to examine a large swath of temperature/doping/magnetic field parameter space, showing evidence of critical scaling of the resistance near the transition as well as an anomalous metallic state.  There's a lot to digest here.  The mapped out zero-field phase diagram in a single device (shown here) is extremely impressive.  Studies like this can hopefully give new insights into what physics is truly essential to achieve high temperature superconductivity.
  • In this paper, investigators placed exfoliated NbSe\(_2\) encapsulated by hBN in a split-ring resonator cavity, and they observed enhanced critical temperature (by 0.15 K out of 6.53 K, or an increase of 2.3%), critical field, and critical current when the resonance frequency of the cavity is such that it apparently couples to superconducting fluctuations in the material on the spatial scale of the cavity.  There is a ton of interest in using electromagnetic cavities to modify the properties of quantum materials - see this review.  As far as I know, this is the first time that coupling to the vacuum mode of a cavity has actually enhanced superconducting properties.  Exciting times.
It's worth noting that both of these papers come out of groups in China - Changgan Zeng at USTC and Yuanbo Zhang at Fudan.   

In other news:
  • The NSF is going to make about half the number of awards this year as it did in The Before Times (2021-2024), according to this news article in Nature.  Figure 1 (shown here) is striking.  The claim is that the NSF leadership is taking clawed-back FY26 funding of around $1B and saving it for some as-yet unspecified, unannounced OSTP "grand challenges" project.  
  • NSF also announced "new" funding opportunities here.  As described in that article linked above, these are not exactly new - it's essentially a reorganization/rebranding of much of the NSF's portfolio now that they've eliminated divisions and retired older funding solicitations.  Noteworthy is that the amount of funding mentioned in these solicitations is all considerably lower than what the aggregate of the older solicitations used to have.  As a non-expert, it looks a lot like these solicitations are being prepared as if the presidential budget requested funding levels (you know, the ones that want to cut NSF by more than half) are the baseline.
Meanwhile, at Rice we have some faculty searches underway:
  • The Rice Advanced Materials Institute is searching for an assistant professor with an expertise in computational materials (including AI/ML).  See here.
  • Our chemistry department is searching for an assistant professor position with an emphasis including physical chemistry.  See here. 
  • There will also be an AMO physics position posted shortly - I'll update with the link when that becomes available. Update:  See here.
Finally, Nano Letters is having a seed grant competition for grad students.  It's not much money, but it is good experience and can inspire graduate student creativity. (Full disclosure: I'm an associate editor for the journal.)


September 11, 2026

Andrew Jaffe — The Talk I Gave on September 12

More 25th anniversary thoughts and recollections.

I had moved to Oxford less than two weeks before, still settling into my new life in the UK, working at Imperial College in London. That day, I was heading off to Durham, in the north of England, to a conference called “A New Era in Cosmology” — my first big talk now that I had started my permanent academic job. I was going to be a bit late, only able to arrive toward the end of the first day of the conference: September 11, 2001.

My train left in the late morning. A few hours in, passengers were starting to talk about an attack on New York City. This was in the days before smartphones and constant communication — I didn’t even have a mobile phone. The discussions around me were getting more and more frantic, and I was doing my best to piece together the story.

I was born in New York City, and much of my family still lived in the area. My parents lived in the suburb of Fort Lee, New Jersey, right across the Hudson River from Manhattan; from the apartment where I grew up, we had a fantastic view from the 18th floor. My father worked in The City, commuting every morning by car from New Jersey to midtown Manhattan. He would have been at his office that day.

I considered getting off the train somewhere en route, perhaps Sheffield or York, to try to get some more information, but I just stayed on the train. I was able to get a taxi from the station in Durham to my hotel, listening to the news. I was able to call my partner, back in Oxford, who had, luckily considering the pressure on transatlantic calls, been able to get in touch with my family in New York and New Jersey. Everyone was, thankfully, alright, although at this point my father was still in Manhattan. He had noticed all the emergency vehicles speeding downtown, thinking that it was a motorcade for some foreign dignitary, but it was the first fleet of emergency responders heading towards the twin towers after the first collision. Eventually, he made it home, to my family’s apartment overlooking the Hudson. But it was so close to the George Washington Bridge, a piece of vital infrastructure thought to be in danger after the first attack, that he had to be let off a mile or so away and walk the rest.

As for me, I had to give the first talk on 12 September, about the “new era in cosmology” that coming CMB measurements would usher in. We started, understandably, with a few moments of silence, and I remember trying to come up with some appropriate words with which to start, something about needing to persevere even in the face of terrible events. I also recall that it was given on old-fashioned transparencies (I should try to dig it out of my files…) and that it was actually one of the better talks I had ever given, calmed, or at least slowed compared to my usual nervous agitation, by the events.

(My friend and colleague Peter Coles was also at the conference, offering his own reminiscences on his blog.)

As I mentioned in my last post, 9/11 feels like a milestone, and a millstone — the world hasn’t been the same since. And we still need to persevere in the face of terrible events.

Matt von Hippel — Everybody Who Isn’t ”Viewers Like You”

Last week, I talked about how truthseekers get paid. But truth-tellers and truth-seekers are different things.

Consider educational kids’ shows on public television.

Nobody who works on Sesame Street is out there uncovering new letters and numbers. Bill Nye’s show wasn’t bringing analysis fresh from the lab.

The purpose of these shows is to educate. The purpose of education is to change minds.

So who pays for educational kids’ shows on public television?

If you’re from the US and watched PBS growing up, you remember one answer: “viewers like you!” US public television is supported by donations, ordinary people across the country who want it to keep on educating kids.

But you also might remember the lists of names that came before “viewers like you”. Some of those were things like “the Department of Education” or “a grant from the National Science Foundation”: government programs, in other words. Others were philanthropists and private foundations. Some were tied to companies, like the Intel Foundation, or Juicy Juice.

All of these groups, from government departments to donors, are trying to change kids’ minds. They support specific shows on specific topics, where they want kids to be better-informed. The same groups have the same kind of impact on schools. For example, I remember in elementary school we all learned to play a recorder, because a wealthy donor had given the school recorders out of the idea that music education was especially important.

For a truth-seeker like a journalist, accepting that kind of funding would be a problem. Grants for journalists tend to support things like travel, letting journalists learn more about specific topics, not pre-judging the conclusion. But children’s television is about truth-telling, not truth-seeking, so our standards are different. We trust the people making children’s television to care about whether they’re telling the truth. And because the topics aren’t new, we don’t usually worry about their judgement being biased.

All this is rather obvious. But now, consider science YouTube.

Some science YouTubers seem to have a mission much like children’s television. They’re there to teach, not to make independent judgements. They don’t search for truth on their own. And some of them are funded by educational grants, much like children’s television.

Others are a bit more like journalists, or even activists. People follow them for their opinions, to hear their assessment. They’re trying to be truth-seekers.

On YouTube, it’s not always obvious which is which.

There’s a particular group of philanthropists called Effective Altruists, and many of them are concerned about AI. So in between funding things like anti-malaria bed nets, some of them are giving grants to YouTubers to make educational content about AI-related risks.

Apparently, they reached out to Sabine Hossenfelder, which was a bad idea. Sabine Hossenfelder’s followers aren’t just looking for education on known facts. They’re looking for her judgements, her literal bullshit-rating on ideas. And so while she’s paid by “viewers like you”, she’s not really the type to get paid by that type of grant.

What I want to emphasize, and what looked like it was getting lost in the discussion, was that their pitch would have been totally reasonable for other YouTubers. Educators do occasionally get grants to educate on specific topics. This is in fact a totally normal thing. Some YouTubers are educators first and foremost, they aren’t there as truth-seekers, but truth-tellers, with a real difference in how careful they need to be about bias.

Some YouTubers are different from other YouTubers. News at 11.

September 09, 2026

John Baez — The E6 Root Polytope

I’ve been thinking about the exceptional Lie algebra E6, as a spinoff of my project on E7, so I want to get a good mental picture of the E6 root polytope. This is 6-dimensional polytope with remarkable symmetry.

Let’s climb up to it, starting with some of its 4-dimensional faces, which are called 4-demicubes because you get them by taking a 4-dimensional cube, or tesseract, and removing every other corner. The 3-demicube is just a tetrahedron, since you can fit two tetrahedra in a 3-dimensional cube like this:

The 4-demicube builds on this fact in a surprising way.

I’m going to use the technology of Dynkin diagrams, or technically Coxeter diagrams: they’re closely related, and the difference is invisible here. I won’t explain them, just use them. I explained them here:

• Symmetry and the fourth dimension: part 3, part 4, part 5, part 6.

Let’s dive in!

The 4-demicube lives in 4 dimensions. It has 8 vertices.

You get it from a 4-dimensional cube, which has 24 = 16 vertices, by keeping every other vertex, throwing away half. That leaves 8.

What are its top-dimensional faces, aka ‘facets’? Surprise: there’s only one kind! All of them are regular tetrahedra.

In higher dimensions the demicube has two kinds of facet. You get a simplex-shaped facet from every other vertex, formed when you remove it. And you get a demicube-shaped facet from each of the cube’s facets. But in 4 dimensions the two kinds happen to be the same shape!

Eight of them are tetrahedra. These appear at the 8 corners you sliced off: one per removed corner.

Eight more come from the 8 faces of the 4-dimensional cube. These are 3-demicubes. But as we’ve seen, the 3-demicube is also a tetrahedron!

So the 4-demicube is especially symmetric: it has 16 tetrahedral facets. You can find coordinates where its vertices are

(±1, 0, 0, 0),   (0, ±1, 0, 0),   (0, 0, ±1, 0),   (0, 0, 0, ±1)

It’s actually one of the 4-dimensional regular polytopes, sometimes called the 4-orthoplex. It’s also called the 16-cell because it has 16 facets. It’s the 4-dimensional cousin of the octahedron, which has 8 triangular facets.

You can read some of these facts off the D4 Dynkin diagram, if you know what you’re doing. As you can see above, this diagram has a central node with three arms, each just 1 edge long: a perfectly symmetric three-pronged star. To get the 4-demicube, you ring the tip of any one arm.

To get the facets of the 4-demicube, delete an unringed node so the piece still holding the ring stays connected, and see what diagram survives. There are two choices: you can delete the tip of either other arm. But either way, what’s left is a straight chain of 3 nodes—the so-called A3 diagram—with a ring at one node at the end. This gives the tetrahedron.

Both choices give the same shape of facet, a tetrahedron, because all three arms of the D4 Dynkin diagram are interchangeable. That ceases to be true in higher dimensions!


Next, the 5-demicube. This lives in 5 dimensions and has 16 vertices.

You get it from a 5-dimensional cube—which has 25 = 32 vertices—by keeping every other vertex, throwing away half. That leaves 16.

What are its top-dimensional faces, or ‘facets’? There are two kinds!

Sixteen of them are 4-dimensional analogues of the regular tetrahedron, called 4-simplexes. These appear at the corners you sliced off: one per removed corner.

The other ten come from the ten faces of the 5-dimensional cube. After you take every other vertex, they become 4-demicubes. These are precisely the 4-demicubes we saw in the last section!

You can also read these two kinds of facets from the D5 Dynkin diagram. As you can see above, this diagram has three arms of lengths 2, 1, 1 (edges from the central branch node). To get the 5-demicube, you ring the tip of either length-1 arm. That ringed diagram encodes the whole polytope.

To get the facets, delete an unringed node so the piece still holding the ring stays connected, and see what diagram survives.

There are two choices.

If you delete the tip of the other length-1 arm, what’s left is a straight chain of 4 nodes—the diagram whose polytope is the 4-simplex. That gives the 4-simplex faces.

Or you can delete the tip of the length-2 arm. Then what’s left is a shorter branching diagram, the one I showed you in my last post! That gives the 4-demicube faces.

So the 5-demicube has both 4-simplex and 4-demicube faces.

Next let’s go up to the 6th dimension, which was my goal all along.


The E6 root polytope lives in 6 dimensions. It has 72 vertices.

What are its facets? You can read them straight off the E6 Dynkin diagram, using the same procedure we’ve been using so far.

As you can see, the E6 Dynkin diagram has three arms of lengths 2, 2, 1 (edges from the central branch node). To get the root polytope, you ring the node that’s the tip of a length-1 arm. That fact is not obvious, but let’s go ahead and do that.

Then, to get the facets, delete any unringed node such that the piece still holding the ring stays connected, and see what diagram survives.

There are two choices: the two other nodes at tips of the Dynkin diagram.

However, deleting either of these nodes leave a D5 diagram with a ring on one node, and this gives the 5-demicube we saw last time: a 5-cube with alternate vertices removed.

So the facets of the E6 root polytope are all the same shape: 5-demicubes!

With more work, we can count the facets of the polytopes we’ve been studying:

• The E6 root polytope has 54 facets, all 5-demicubes. They come in two kinds, because we had two choices of which node to delete, so there are really 27 ‘positive’ 5-demicube facets and 27 ‘negative’ 5-demicube facets.

• The 5-demicube has 16 4-simplex facets, one for each vertex that we removed from the 5-cube to create this demicube, and 10 4-demicube facets, one for each facet of that 5-cube.

• The 4-demicube has 8 3-simplex facets, one for each vertex that we removed from the 4-cube to create this demicube, and 8 3-demicube facets, one for each facet of that 4-cube. But both the 3-simplex and the 3-demicube are the familiar tetrahedron. So in fact the 4-demicube has 16 tetrahedral facets. Indeed, the 4-demicube is the 4-dimensional analogue of an octahedron: the so-called 4-orthoplex, or 16-cell.

Using some fancier math I explained here, we can count all the faces of the E6 root polytope. This polytope, is also called 122 due to the shape of its Dynkin diagram: the ring is on a branch of length 1, not counting the central node, while the other two branches have lengths 2. You can look up all this information on the Wikipedia page 122 polytope:

Faces of the E6 root polytope, or 122
dim faces count
5 5-demicubes 54 = 27 + 27
4 4-demicubes = 4-orthoplexes 270
4 4-simplexes 432 = 216 + 216
3 3-simplexes = 3-demicubes = tetrahedra 2160 = 1080 + 1080
2 2-simplexes = triangles 2160
1 1-simplexes = edges 720
0 0-simplexes = vertices 72

The 5-dimensional facets are all 5-demicubes, but as we’ve seen, they come in two kinds: that is, they lie in two orbits of the symmetry group. We can call 27 of them ‘positive’ 5-demicubes and 27 of them ‘negative’ demicubes. Of the 4-dimensional faces, 270 are 4-demicubes and 432 are 4-simplexes. Moreover the 4-simplexes come in two kinds: 216 are faces of positive 5-demicubes while 216 are faces of negative 5-demicubes. Let’s call the first kind of 4-simplex ‘positive’ and the second kind ‘negative’. The 3-dimensional faces are all tetrahedra, but they come in two ‘kinds’: 1080 of them are faces of positive 4-simplexes, and 1080 are faces of negative 4-simplexes. None is the face of both a positive and negative 4-simplex.

If you’re curious about how to count these things, see how some of us counted all the faces of the E8 root polytope here:

• John Baez, Integral octonions (part 5), The n-Category Café, September 3, 2013.

Here is a table of faces for the E7 root polytope, which is also called 231:

Faces of the E7 root polytope, or 231
dim faces count
6 221 polytopes 56
6 6-simplexes 576
5 5-orthoplexes 756
5 5-simplexes 4032
4 4-simplexes 16128 = 4032 + 12096
3 3-simplexes = tetrahedra 20160
2 2-simplexes = triangles 10080
1 1-simplexes = edges 2016
0 0-simplexes = vertices 126

Its 4-dimensional faces are all 4-simplexes, but they come in two ‘kinds’: that is, they lie in two orbits of the symmetry group of this polytope. Of the 4-simplexes, 4032 are the face of three 5-orthoplexes, while 12096 are the face of one 5-orthoplex and two 5-simplexes.

Here’s the E8 root polytope, also called 421:

Faces of the E8 root polytope, or 421
dim faces count
7 7-orthoplexes 2160
7 7-simplexes 17280
6 6-simplexes 207360 = 138240 + 69120
5 5-simplexes 483840
4 4-simplexes 483840
3 3-simplexes = tetrahedra 241920
2 2-simplexes = triangles 60480
1 1-simplexes = edges 6720
0 0-simplexes = vertices 240

There are two kinds of 6-simplex faces: 138240 of them each lie in one 7-simplex and one 7-orthoplex, while 69120 of them each lie in two 7-orthoplexes (and no 7-simplex).

Andrew Jaffe — Second test post

Andrew Jaffe — Test post

Checking some infrastructure…

September 08, 2026

n-Category Café The E6 Root Polytope

I’ve been thinking about the exceptional Lie algebra E6, as a spinoff of my project on E7, so I want to get a good mental picture of the E6 root polytope. This is 6-dimensional polytope with remarkable symmetry.

Let’s climb up to the E6 root polytope starting with some of its 4-dimensional faces, which are called 4-demicubes because you get them by taking a 4-dimensional cube, or tesseract, and removing every other corner. The 3-demicube is just a tetrahedron, since you can fit two tetrahedra in a 3-dimensional cube like this:

The 4-demicube builds on this fact in a surprising way.

I’m going to use the technology of Dynkin diagrams, or technically Coxeter diagrams: they’re closely related, and the difference is invisible here. I won’t explain them, just use them. I explained them here:

• Symmetry and the fourth dimension: part 3, part 4, part 5, part 6.

Let’s dive in!

The 4-demicube lives in 4 dimensions. It has 8 vertices.

You get it from a 4-dimensional cube, which has 24 = 16 vertices, by keeping every other vertex, throwing away half. That leaves 8.

What are its top-dimensional faces, aka ‘facets’? Surprise: there’s only one kind! All of them are regular tetrahedra.

In higher dimensions the demicube has two kinds of facet. You get a simplex-shaped facet from every other vertex, formed when you remove it. And you get a demicube-shaped facet from each of the cube’s facets. But in 4 dimensions the two kinds happen to be the same shape!

Eight of them are tetrahedra. These appear at the 8 corners you sliced off: one per removed corner.

Eight more come from the 8 faces of the 4-dimensional cube. These are 3-demicubes. But as we’ve seen, the 3-demicube is also a tetrahedron!

So the 4-demicube is especially symmetric: it has 16 tetrahedral facets. You can find coordinates where its vertices are

(±1,0,0,0),(0,±1,0,0),(0,0,±1,0),(0,0,0,±1)(\pm 1, 0, 0, 0), \quad (0, \pm 1, 0, 0), \quad (0, 0, \pm 1, 0), \quad (0, 0, 0, \pm 1)

It’s actually one of the 4-dimensional regular polytopes, sometimes called the 4-orthoplex. It’s also called the 16-cell because it has 16 facets. It’s the 4-dimensional cousin of the octahedron, which has 8 triangular facets.

You can read some of these facts off the D4 Dynkin diagram, if you know what you’re doing. As you can see above, this diagram has a central node with three arms, each just 1 edge long: a perfectly symmetric three-pronged star. To get the 4-demicube, you ring the tip of any one arm.

To get the facets of the 4-demicube, delete an unringed node so the piece still holding the ring stays connected, and see what diagram survives. There are two choices: you can delete the tip of either other arm. But either way, what’s left is a straight chain of 3 nodes—the so-called A3 diagram—with a ring at one node at the end. This gives the tetrahedron.

Both choices give the same shape of facet, a tetrahedron, because all three arms of the D4 Dynkin diagram are interchangeable. That ceases to be true in higher dimensions!


Next, the 5-demicube. This lives in 5 dimensions and has 16 vertices.

You get it from a 5-dimensional cube—which has 25 = 32 vertices—by keeping every other vertex, throwing away half. That leaves 16.

What are its top-dimensional faces, or ‘facets’? There are two kinds!

Sixteen of them are 4-dimensional analogues of the regular tetrahedron, called 4-simplexes. These appear at the corners you sliced off: one per removed corner.

The other ten come from the ten faces of the 5-dimensional cube. After you take every other vertex, they become 4-demicubes. These are precisely the 4-demicubes we saw in the last section!

You can also read these two kinds of facets from the D5 Dynkin diagram. As you can see above, this diagram has three arms of lengths 2, 1, 1 (edges from the central branch node). To get the 5-demicube, you ring the tip of either length-1 arm. That ringed diagram encodes the whole polytope.

To get the facets, delete an unringed node so the piece still holding the ring stays connected, and see what diagram survives.

There are two choices.

If you delete the tip of the other length-1 arm, what’s left is a straight chain of 4 nodes—the diagram whose polytope is the 4-simplex. That gives the 4-simplex faces.

Or you can delete the tip of the length-2 arm. Then what’s left is a shorter branching diagram, the one I showed you in my last post! That gives the 4-demicube faces.

So the 5-demicube has both 4-simplex and 4-demicube faces.

Next let’s go up to the 6th dimension, which was my goal all along.


The E6 root polytope lives in 6 dimensions. It has 72 vertices.

What are its facets? You can read them straight off the E6 Dynkin diagram, using the same procedure we’ve been using so far.

As you can see, the E6 Dynkin diagram has three arms of lengths 2, 2, 1 (edges from the central branch node). To get the root polytope, you ring the node that’s the tip of a length-1 arm. That fact is not obvious, but let’s go ahead and do that.

Then, to get the facets, delete any unringed node such that the piece still holding the ring stays connected, and see what diagram survives.

There are two choices: the two other nodes at tips of the Dynkin diagram.

However, deleting either of these nodes leave a D5 diagram with a ring on one node, and this gives the 5-demicube we saw last time: a 5-cube with alternate vertices removed.

So the facets of the E6 root polytope are all the same shape: 5-demicubes!

With more work, we can count the facets of the polytopes we’ve been studying:

• The E6 root polytope has 54 facets, all 5-demicubes. They come in two kinds, because we had two choices of which node to delete, so there are really 27 ‘positive’ 5-demicube facets and 27 ‘negative’ 5-demicube facets.

• The 5-demicube has 16 4-simplex facets, one for each vertex that we removed from the 5-cube to create this demicube, and 10 4-demicube facets, one for each facet of that 5-cube.

• The 4-demicube has 8 3-simplex facets, one for each vertex that we removed from the 4-cube to create this demicube, and 8 3-demicube facets, one for each facet of that 4-cube. But both the 3-simplex and the 3-demicube are the familiar tetrahedron. So in fact the 4-demicube has 16 tetrahedral facets. Indeed, the 4-demicube is the 4-dimensional analogue of an octahedron: the so-called 4-orthoplex, or 16-cell.

Using some fancier math I explained here, we can count all the faces of the E6 root polytope:

dim faces count
5 5-demicubes 54 = 27 + 27
4 4-demicubes = 4-orthoplexes 270
4 4-simplexes 432
3 3-demicubes = 3-simplexes = tetrahedra 2160 = 1080 + 1080
2 2-simplexes = triangles 2160
1 1-simplexes = edges 720
0 0-simplexes = vertices 72

If you’re curious about how to count these things, see how some of us counted all the faces of the E8 root polytope here:

Andrew Jaffe — 25 & 60

Twenty-five years ago, I moved from San Francisco to the UK, from a fellowship at Berkeley to a permanent job at Imperial College, London. A lot has changed since then. I was 35; now I am 60. It was two weeks before 9/11; the world hasn’t seemed as open and free since.

I arrived from the Bay Area just after the first dot-com bubble burst. London, adjusting to New Labour after almost two decades of Thatcher and Thatcherism, felt exciting and vibrant. But just weeks after I arrived came the horror of 9/11, and its years-long aftermath, especially the Iraq war which eventually doomed Blair’s premiership and probably led the way to the 2010 election, the disaster of “austerity” as a wrong-headed attempt to deal with the 2008 recession, and eventually to the more-disastrous Brexit on this side of the Atlantic. Similar politics, though with very different timing, led back in the USA to Obama, one of the few rays of political hope over the last quarter-century, but then, of course, to Trump. And everywhere since 2001 the rise of nativist populism making me feel at home, well, pretty much nowhere — a rootless cosmopolitan. Higher education, scientific funding, and curiosity-driven research are in a parlous state in both the US and the UK.

But: despite a few difficult years in the mid-2000s, I have prospered. Our analysis of data from the Planck satellite has solidified our standard cosmological model — but also given us new problems and puzzles to think and worry about. I have written a book, The Random Universe, trying to explain how we know what we know as scientists and as human beings. And my family, my wife and two daughters, are a source of joy and excitement that inspire me every day.

So now I am 60. I was honoured and humbled a couple of months to ago to be joined by many of my colleagues and scientific friends at a conference here in London. That, and getting a Transport For London 60+ Travel Card, makes it hard to avoid feeling old. But those colleagues and friends (many of whom are older than me) reassured me that it’s only the beginning of a new chapter.

September 06, 2026

John Baez — The Mantle

As we descend from the base of Earth’s crust through the mantle, the rock does not remain unchanged. Pressure and temperature rise inexorably, and the minerals that thrive at the surface are forced, step by step, into new and denser crystallographic arrangements. This is the story of those transformations.

In this tale, I’ll act like I know a bit about minerals. I actually don’t: there are a bewildering variety, and I can never remember them. So don’t worry: when you come across a jargon-filled patch of prose, just power through it. You might learn a little… or you can just ignore it. The overall point here is that the Earth is made of beautiful crystalline structures that change character in complex ways as we descend.

The Mohorovičić discontinuity

Our story begins at the boundary where Earth’s crust, rich in feldspar and quartz, gives way to the denser mantle beneath. We see this boundary through its effect on seismic waves, and it’s called the Mohorovičić discontinuity or “Moho”. The Moho does not lie at one fixed depth: it’s 5–10 kilometers below the seafloor, but 30–50 kilometers below most continents, and as much as 70–80 below young mountain belts like the Himalayas.

The mantle just below the Moho mainly consists of a rock called peridotite, which is made mostly of olivine and pyroxene, with smaller amounts of garnet (or, at shallower depths, spinel). Peridotite has a delicious coarse green appearance:


More precisely, this is what peridotite looks like up here. But when geochemists talk about the bulk composition of the upper mantle, they often use an idealized model called pyrolite—not a rock you can pick up, but a hypothetical recipe Ted Ringwood proposed in the 1960s for the primitive upper mantle.

Why? Since the Earth has had a convecting mantle, solid mantle rock wells up in places. As it does, the pressure drops, and a bit of it melts: the minerals with lower melting points. This melt flows upward. It’s called basalt. It builds the Earth’s crust. But it leaves a residue behind, made of minerals with higher melting points.

In Ringwood’s theory, which for expository purposes I’ll assume is true, pyrolite is what mantle rock is like before any partial melting depletes it of basaltic ingredients. The name is a portmanteau of pyroxene and olivine, the two dominant minerals. Pyrolite is about 60% olivine; the remaining 40% is mostly pyroxenes plus garnet.

• A pyroxene is a mineral built from single, unbranched chains of corner-sharing SiO₄ tetrahedra, with metal cations—chiefly Mg, Fe, and Ca—linking the chains together. The general formula is XY(Si,Al)₂O₆, where X and Y are those cations.


• Olivine is a green silicate, (Mg,Fe)₂SiO₄:


Its crystal structure in the upper mantle is an orthorhombic arrangement of isolated SiO₄ tetrahedra knit together by magnesium and iron in octahedral sites. It’s called the α-phase because we’ll see some more compressed phases as we descend.

• A garnet is built from separate SiO₄ tetrahedra held together by cations, but assembled into a dense, hard, characteristically cubic-symmetry crystal. There are different kinds of garnet, but the general formula is X₃Y₂(SiO₄)₃: three divalent X cations, two trivalent Y cations, and three isolated silica tetrahedra. The mantle’s garnet is largely pyrope, Mg₃Al₂(SiO₄)₃.


As we descend, the pyroxenes and garnet gradually dissolve into each other, producing a new high-pressure mineral called majorite. Here’s a rare sample from a meteorite fall in Canada:


So even before the dramatic change 410 kilometers down, the rock is no longer the simple olivine-pyroxene-garnet assemblage we had further up.

The 410-kilometer discontinuity

Roughly 410 kilometers down, the pressure reaches about 13,000 atmospheres and the temperature hovers around 1,400°C. Olivine can no longer hold its familiar shape. It transforms to its β form: wadsleyite, a mineral with the same chemical formula but a fundamentally different atomic arrangement. Instead of isolated SiO₄ tetrahedra, wadsleyite contains paired Si₂O₇ groups, and the oxygens pack more densely. The density jump is sharp enough to be detected globally by seismologists as a reflector of earthquake waves.

Wadsleyite has a remarkable property: it can hold several weight percent of water locked within its crystal structure. The transition zone may thus contain more water than all the oceans combined! However, very little wadsleyite has been seen on the Earth’s surface. Here’s a bit from that same meteor fall in Canada:


The 520-kilometer discontinuity

Descend further, to around 520 kilometers, and the temperature goes up only a little, to roughly 1500–1600°C, since convection here is strong. The pressure goes up to about 175,000 atmospheres. At this point wadsleyite transforms into the γ form of olivine: ringwoodite. This is denser, still chemically Mg₂SiO₄, but now with cations packed into tetrahedral and octahedral holes in a close-packed oxygen framework—the most efficient packing geometry that nature offers for this composition:


Ringwoodite is named for the great Australian geochemist Ted Ringwood, who studied these transitions. Here’s an artificially manufactured sample:


For a long time the mineral’s existence in the mantle was purely hypothetical. But in 2014, a tiny grain was discovered as an inclusion inside a diamond brought up from the deep mantle by an eruption, providing the first direct proof of its existence in Earth’s interior.

The 660-kilometer discontinuity

At a depth of 660 kilometers and a pressure of roughly 230,000 atmospheres, the most dramatic phase transition of all occurs. Ringwoodite does not merely rearrange into a still more dense form! Instead, it decomposes into two entirely new minerals: bridgmanite (MgSiO₃) and ferropericlase (MgO). The majorite garnet also decomposes, yielding davemaoite (CaSiO₃), which is stable through the rest of the lower mantle:


The 660-kilometer discontinuity is sharp, globally consistent, and marks the conventional boundary between the upper and lower mantle. One reason it’s important is that enormous slabs of colder, denser rock sink through the upper mantle until they hit this discontinuity, where the phase change between ringwoodite and bridgmanite creates a kind of barrier.

These slabs are 30–100 kilometers thick and hundreds to a thousand kilometers across! Some punch straight through into the lower mantle and keep sinking. But many flatten out when they hit the barrier, sometimes lying there and piling up for tens of millions of years. You can see this in seismic images beneath Japan and the Marianas. Numerical models suggest that they pile up until they overwhelm the barrier and flush down in a comparatively sudden avalanche—lasting mere millions of years.

The lower mantle

This is the realm of bridgmanite, probably the most abundant mineral in the Earth. Bridgmanite is a beautifully symmetric cage of corner-sharing SiO₆ octahedra, with Mg tucked into the large cavities between them. It accommodates enormous pressure because there is very little void space left to compress.


It is a striking fact that while bridgmanite is the most abundant mineral on the planet, it went unnamed until 2014, simply because no natural hand-sized specimen had ever been recovered. Everything we know about it comes either from high-pressure laboratory synthesis, from microscopic grains in shocked meteorites, or from the indirect testimony of earthquake waves that have traveled through 2,000 kilometers of it.

For over 2,000 kilometers of descent, from 660 to roughly 2,700 kilometers down, bridgmanite and its companion ferropericlase reign without significant further phase change. Seismic velocities increase steadily, but there are no dramatic discontinuities.

The D″ discontinuity

As we approach the core-mantle boundary—at depths around 2,700 kilometers, pressures of approximately 120,000–125,000 atmospheres, and temperatures of 2,200–3,7000°C—even bridgmanite yields. It transforms into the post-perovskite phase. Post-perovskite is a layered, sheet-like structure of SiO₆ octahedra, quite different from bridgmanite’s three-dimensional cage, making it potentially much weaker and more prone to flow.

This transition is believed to be responsible for the seismic D″ discontinuity observed at 2,900 kilometers depth. The D″ layer is a highly dynamic region, likely the site of storage of subducted materials and the source of deep mantle plumes.

A summary of the descent

The table below summarizes the major transitions:

Depth (km)        Minerals
0–410 olivine (α) + pyroxenes + garnet
410 → wadsleyite (β)
520 → ringwoodite (γ)
660 → bridgmanite + ferropericlase + davemaoite
660–2700 bridgmanite dominates
~2700 → post-perovskite
2900 → liquid iron core

The interesting thing about this story is that it was told first by seismology—the sharp jumps in wave speeds at 410 and 660 kilometers were detected long before geologists could reproduce those pressures in the lab—and only later checked by diamond-anvil cell experiments squeezing tiny mineral samples to millions of atmospheres. The rocks never rise to the surface to tell their story directly, so much of the tale above is just theory.

Which minerals are there the most of?

We can estimate how much of the Earth is made of wadsleyite, ringwoodite, and bridgmanite using known shell volumes, estimated densities, and mineral proportions from the pyrolite model.

Step 1: Earth’s mass budget by layer

The Earth’s total mass is M⊕ ≈ 5.972 × 1024 kg. The mass budget by layer is approximately:

•    Crust: ~0.4% of Earth’s mass
•    Upper mantle + transition zone (35–660 km): ~18% of Earth’s mass
•    Lower mantle (660–2,891 km): ~49% of Earth’s mass
•    Core (outer + inner): ~32.5% of Earth’s mass

Step 2: The transition zone (410–660 km)

Using PREM densities averaging ~3,760 kg/m3 across the transition zone, and the volume of each spherical shell:

Wadsleyite zone (410–520 km):
Shell volume ≈ 4.8 × 10¹⁹ m3
Shell mass ≈ 1.76 × 10²³ kg
Fraction of Earth’s mass ≈ 2.9%

Ringwoodite zone (520–660 km):
Shell volume ≈ 5.9 × 10¹⁹ m3
Shell mass ≈ 2.24 × 10²³ kg
Fraction of Earth’s mass ≈ 3.8%

In the pyrolite model of mantle composition, forms of olivine (wadsleyite and ringwoodite) make up roughly 60% of the transition zone by mass, with the remaining ~40% being majoritic garnet. Applying this correction:

Wadsleyite: 0.60 × 2.9% ≈ 1.8% of Earth’s mass
Ringwoodite: 0.60 × 3.8% ≈ 2.3% of Earth’s mass

These estimates carry roughly 20–30% uncertainty, mainly from the assumed 60% olivine proportion in the transition zone, which varies with local temperature and bulk composition.

Step 3: Bridgmanite (660–2,700 km)

The lower mantle holds about 49% of Earth’s mass—it is an enormous shell! Bridgmanite constitutes approximately 80% of the lower mantle mineral assemblage (by mass) in the pyrolite model:

0.80 × 49% ≈ 39% of Earth’s mass

This is consistent with the well-cited literature figure that bridgmanite comprises approximately 38% of the planet’s mass—making it the single most abundant mineral in the Earth by a vast margin.

Mineral Depth (km) Fraction of Earth’s Mass
Wadsleyite 410–520 ~1.8%
Ringwoodite 520–660 ~2.3%
Bridgmanite 660–2,700 ~38–39%
All three combined 410–2,700 ~42%

Thus, these three minerals—all members of the same Mg₂SiO₄/MgSiO₃ chemical lineage—together constitute roughly 42% of Earth’s entire mass. All other named minerals on Earth, including quartz, feldspar, calcite, diamond, and the roughly 3,800 others known to mineralogists, divide up the remaining scraps.

John Preskill — How can objects interact without touching?

Rethinking the electric field

Have you ever wondered what an electric field actually is? 

The electric field is the foundation of most technologies that we rely on every day. From power grids and electronic devices to radio communication and the internet, the electric field is extremely relevant to our daily lives. However, despite its importance, I have always felt that the common explanations of the electric field leave something unanswered. 

Most textbooks define the electric field as a property of space or a physical entity surrounding electric charges, or with the equation of force per unit charge. These definitions help us understand what the electric field does and its effect on electrically charged particles, but they do not fully answer what an electric field actually is and how it influences charges. Thus, I started thinking about the question: what allows charges to influence each other without touching?

This question led me down a path that began with a simple observation in everyday life, and it eventually pointed toward much deeper ideas in modern physics.

Objects Influenced by Their Surroundings

Before talking about electric fields, let’s consider a more basic question: Does it seem reasonable that objects can be influenced by their surroundings? 

Most people would answer yes. We have all seen examples of objects responding to something else nearby, such as the Earth orbiting the Sun, a compass needle reacting to a magnet, and our phones responding to signals from a WiFi router. But what is the mechanism behind these interactions? 

A simple physical phenomenon that we can look at is a balloon rubbed on a piece of clothing that can pick up strands of our hair. Many of us have seen this demonstration in kindergarten or first grade of elementary school. This might seem completely ordinary, but if we pause and think about it, something strange is happening – the balloon is influencing the hair without touching it. 

How is that possible? One answer is simply that the balloon “pulls” on the hair, but this raises more questions. How does the balloon reach the hair? What is happening in the space between them? These questions suggest that something is missing from the picture of objects pulling on each other directly through contact.

Image of cat fur sticking to a balloon. Source: https://science.howstuffworks.com/why-do-balloons-stick-to-hair.htm

To put this in the context of physics, we might all have learned that “like charges repel, and opposite charges attract”. We might have solved equations on how fast charges would move away from or toward each other. We were always told to just accept it because these motions result from the electric field. But why do these observations happen? What is happening between the charges?

Historically, physics encountered the same problem. If one object can influence another at a distance, it is natural to ask what is happening in the space between them. One guiding principle that physicists often use is the concept of locality. Locality is the idea that an object can only be directly influenced by its immediate surroundings. Thus, an influence should not simply leap across space from one object to another, and changes should propagate through intermediate regions step by step. 

At first glance, locality seems reasonable because it matches many of our everyday experiences. If I push a book across a table, my hand influences the book through direct contact. The influence does not appear to jump instantaneously across the table. 

However, locality creates a tension when we return to the scenario of the balloon pulling on strands of hair. If locality is true, something must be happening in the space between the balloon and the hair. But from a standard electromagnetic perspective, the space between the balloon and the hair is empty. Therefore, we have encountered a contradiction: if what is between the balloon and the hair is empty space, then what is responsible for transmitting the influence? Neither the usual electromagnetism nor locality tells us the answer to these questions.

The Classical Electric Field

In the usual electromagnetic picture, the answer to the puzzle is the electric field. Rather than allowing charges to influence one another directly across space, the theory assigns an electric field to the space surrounding charges. The field acts as the intermediary through which influence is transmitted. 

A useful way to think about the electric field is that it assigns information to every point in space. If we imagine a charged particle that is placed at a particular location, the electric field tells us how that particle would move. This charged particle is what physicists call a test charge. By observing how the test charge behaves, we can infer information about the electric field at that location. 

This could seem like a satisfying answer as the electric field tells us how influence is transmitted, but it does not tell us what kind of thing is doing the transmission. Is the electric field a physical substance? Is it a mathematical tool? Or is it something else? 

It might be easy to fall back on the idea that the electric field ultimately works through tiny particles physically touching one another. After all, contact interactions are among the most familiar interactions that we experience. 

But physics challenges this intuition as well. It is surprisingly difficult to define what it means for two objects to “touch”. We usually think of the balloon attracting hair as an example of action at a distance, whereas pressing a hand on a table feels like direct physical contact. However, at the microscopic level, the two situations are fundamentally similar. If we could zoom in on our fingertip and the table with a microscope, we would find that the atoms in our skin never make contact with the atoms in the table. This is because of the repulsion between the electron clouds surrounding the atoms, which prevents the two atomic nuclei from overlapping. Say if we scale the atom in the table up to be the size of a marble, then the nearest atom in our fingertip would still be separated from it by a few centimeters. In the end, nothing is truly “touching” in the intuitive, physical sense. 

Thus, the idea of contact does not solve our problem. We are forced to ask the same question again: what is it that allows these interactions to occur? To answer that question, I turned to a different perspective of thinking about electric fields.

The Electric Field as A Dynamical Structure

From our intuition, it is natural to imagine the electric field as some invisible substance filling space. This is often the picture suggested by the common field line diagrams in physics textbooks, which make the field appear to flow outward or inward from charges, almost like a moving fluid. 

A useful analogy is the ocean. A boat floating on water can move because waves pass beneath it. The boat responds to changes in its surrounding waves rather than to some direct push from a distant object. Similarly, charged particles respond to changes in the electric field around them. We can then view the electric field as a dynamical structure that governs how the state of the world can evolve.

However, the ocean analogy can only take us so far. Ocean waves are made of water molecules. Sound waves are made of vibrating air molecules. But what is the electric field made of? When light travels through empty space, it seems that there is no material medium at all. 

This brings us back to the mystery: if locality suggests that something must exist in the space between interacting objects, and if the electric field is not made of the ordinary matter that we understand, then what exactly is occupying the space? 

To answer this question, we have to rethink what we mean by “empty” space itself.

Empty Space is Not Empty

Conventionally, we have always imagined empty space as exactly what the name suggests—empty. Just like if all the particles were removed and nothing was remaining. But modern physics suggests a very different picture. 

In quantum field theory, what we call “empty space” is not truly empty. Empty space is filled with underlying quantum fields that permeate all of space and time, even in the absence of particles. Even when the surface of the ocean looks perfectly still, the water is still there. The ocean is not defined only by visible waves, but by the underlying medium that can support waves in the first place. The waves are patterns of motion of the ocean itself, just like the electric field. These fields are part of the fundamental structure of the universe from which physical phenomena emerge. Quantum field theory suggests that particles are not independent objects moving through an otherwise empty space. Rather, they are localized patterns or excitations of underlying fields that already exist throughout the universe. 

From this perspective, the electric field is not something that is added to empty space. It is part of the fundamental dynamical structure of space itself.

Conclusion

At the beginning, I asked a simple question: how can objects influence each other without touching? The straightforward answer is the electric field. Charges create electric fields, and those fields determine how other charges move. But what is an electric field? Is it an invisible material filling space between objects, or is it a dynamical structure that governs how physical systems in the world evolve? 

From the perspective of quantum field theory, quantum fields permeate all of space and time. Particles are not separate objects moving through an empty space, but are excitations of these underlying fields; electric fields are not secondary matter surrounding charged particles, but are particular configurations of the underlying electromagnetic quantum fields. What we observe as the motion of a charged particle is the result of its interaction with the electromagnetic field, whose local state determines how the particle evolves. 

In the end, our original question may not have a single definitive answer. But asking it revealed a shift in perspective, and physics has repeatedly shown that every explanation opens the door to an even more fundamental question. Stopping at this step, a new mystery emerges: what are these underlying quantum fields themselves? What are they made of, and where do they arise from? 

September 04, 2026

Matt von Hippel — Paying the Truthseekers

Academics and journalists have a lot in common, at least in principle.

Whether you’re a reporter or a professor, your job is to go out into the world and figure out the truth. You’re supposed to be careful, to check and correct for how you might be wrong. And at the end of the day you’re supposed to communicate what you found.

The differences mostly come in how you’re paid.

You could imagine some sort of pure truthseeker, paid purely by how well they tell the truth. People would ask them to find out the truth about something, and pay them for the service. And the truthseekers with the best track record would get the most clients. But neither profession really works like this.

Journalism comes closest. Once upon a time, people bought newspapers in order to be the first to know when something important happened. While there’s still a little bit of that going on (I guess this is what Bloomberg Terminals are for?), it’s a lot less central because of the internet. Now, there are hundreds of ways to find out about things, from a multitude of news sites to social media. More and more, people expect to be able to get information for free.

In that environment, the news has to compete not on the facts themselves, but on how it presents them. People pay for news that’s curated well to match their interests, or news that feels more respectable. And more than either of those, they pay for news that’s entertaining. So while truthseeking skills pay, writing skills often end up mattering more. In a sense, it’s why it’s possible for me to do journalism at all. I was trained in the academic truthseeking tradition, not the journalistic one. I got into journalism by impressing editors with my writing, not my ability to suss out the truth.

That academic truthseeking tradition is quite different, in part because the rewards for it are much more indirect. Academics pay comes from two main sources: research grants, and student tuition. Students are mostly there to learn old facts, not new ones, so that source of money supports research only in so far that students believe that a successful researcher with time for research will also be a better teacher.

Research grants, in principle, pay for truthseeking. But they’re typically paid by governments, which often don’t have a clear idea of what they’d like to learn, since the more practical questions are already being researched by private companies. So the decision gets delegated out to other academics, who have a vague shared sense of what’s worth knowing and what’s not. Accuracy should have an impact: that is, it should be easier to get grants if you’re better at finding the truth. But in practice, unless someone does so badly they trigger a scandal, academics don’t usually get things all that wrong. So grants are mostly based on other factors.

Paying someone purely to deliver the truth, not to entertain or match a culture, seems tricky. You could imagine sci-fi scenarios. What if we could track the logic people used to make decisions, and demand payment if those decisions were based on facts we uncovered, like a journalist getting a percentage of every short made in response to bad news they dug up about a company? What if governments paid in proportion to how valuable academic ideas turned out to be, centuries after they were discovered, and modern-day academics sold shares in that future payout to fund themselves? What if prediction markets something something?

For the moment, academics and journalists are both in a weird middle space. They’re truthseekers, still, by culture and inclination and desire. But they’re paid for something else.

September 03, 2026

Tommaso Dorigo — When A Bump Gets Greedy: A Connection I Had Missed For 25 Years

When A Bump Gets Greedy: A Connection I Had Missed For 25 Years

Back in 2009 I wrote in this blog a rather technical post about something I had called the “greedy bump bias.” (GBB) The effect I referred to had emerged from a 2003 CDF study of mine, where I considered the extraction of small signals sitting on top of much larger backgrounds.That work went unpublished, but then I took revenge with the blog post...

Tommaso Dorigo
Categories

September 01, 2026

n-Category Café Three Generations in E7

It’s long been a mystery why there are 3 generations of quarks and leptons: three sets of particles, apparently identical except for how they interact with the Higgs boson. It would be nice if there were some good physical explanation. Nobody knows one. Barring that, it would be nice if some beautiful mathematical structure made this pattern seem natural. That’s what my new paper is about.

I’ll keep this nontechnical. I’ll say a bit about what the paper does, what it does not do, what led up to it, and how I wrote it.

This is my third paper about exceptional algebraic structures and the Standard Model. When you classify famous gadgets in algebra, beautiful gadgets with fancy names like ‘simple Lie algebras’ and ‘Euclidean Jordan algebras’ and ‘positive hermitian Jordan pairs’, you tend to get infinite series of them — together with a few exceptions that can be built using the octonions. This is a bit spooky, so I’ve been interested in this for a long time.

A few physicists have hoped that these exceptions are good for something. For example, maybe the quirky features of our best theory of particle physics, the Standard Model, aren’t accidental. Perhaps they fall out naturally from some exceptional algebraic structure.

It’s a long shot, but we’ve been stuck on figuring out new fundamental laws of particle physics for so long — roughly since the early 1980s — that it’s worth a try.

In 2018, Michel Dubois-Violette and Ivan Todorov noticed that the gauge group of the Standard Model falls out as symmetries of the so-called ‘exceptional Jordan algebra’ together with some ordinary Jordan algebras sitting inside it. I tried to clarify that here, with a huge amount of help from an excellent young mathematician:

It’s very nice, because the Jordan algebras in question arise naturally when you try to axiomatize the foundations of quantum physics. It would be so cool if something about quantum physics made the Standard Model seem mathematically natural!

But really this result only concerns the gauge bosons in the Standard Model: the photon, gluons, and the W and Z bosons. It says nothing about the fermions — that is, the quarks and leptons. And it seems quite hard to get those into the picture.

In 2020, Latham Boyle tried to solve this problem by tensoring the exceptional Jordan algebra with the complex numbers. This made one generation of fermions appear quite naturally! But the connection to the foundations of quantum physics seemed lost: tensoring the exceptional Jordan algebra with the complex numbers seems at first like it might be just a formal trick.

This spring, Latham and his student Endre Bokor and I showed the connection to quantum physics is not lost:

The idea is to work, not with Jordan algebras, but with more general things called Jordan pairs, which have been studied by mathematicians since at least 1975. We showed that you can still do quantum physics with Jordan pairs. And we showed that there’s an ‘exceptional’ Jordan pair that naturally contains the Standard Model gauge group and one generation of fermions!

This Jordan pair is built from the bioctonions: the octonions tensored with the complex numbers. And it’s closely related to an exceptional Lie algebra called 𝔢 6\mathfrak{e}_6.

This is nice because the work of Dubois-Violette and Todorov used a smaller exceptional Lie algebra called 𝔣 4\mathfrak{f}_4. Going up to 𝔢 6\mathfrak{e}_6 gives the room to include one generation of fermions.

There’s an even larger exceptional Lie algebra you can use to build a Jordan pair: it’s called 𝔢 7\mathfrak{e}_7. Bokor, Boyle and I tried using this to get three generations of fermions. There are things that make this tempting: not just the fact that 𝔢 7\mathfrak{e}_7 is bigger, but the fact that the Jordan pair you get from it has a kind of three-fold symmetry. But we couldn’t get it to work.

Around this time I got very interested in some work that someone had sent me in October 2025. My inbox is packed with new theories of physics. Since the rise of large language models the inflow has increased: I get about two emails a day from someone telling me they’ve made a revolutionary discovery in physics. Practically none of these theories appeal to me. But this paper, and this thesis, were different:

He claimed to fit three generations of fermions into the exceptional Lie algebra 𝔢 7\mathfrak{e}_7.

When I started seriously trying to understand this paper, I wound up translating it into a language I’m more comfortable with, and expanding on the ideas a bit. So I wrote this:

Here’s the basic idea.

The idea

There is a standard way to fit the Lie algebra of the Standard Model gauge group, which I call 𝔤 SM\mathfrak{g}_{\text{SM}}, into the Lie algebra 𝔢 7\mathfrak{e}_7. You can construct a Lie algebra LL that fits between them:

𝔤 SM⊂L⊂𝔢 7 \mathfrak{g}_{\text{SM}} \subset L \subset \mathfrak{e}_7

As a vector space we have

𝔢 7≅L⊕V \mathfrak{e}_7 \; \cong \; L \oplus V

for some vector space VV of dimension 3×323 \times 32.

Moreover, the Lie algebra 𝔤 SM\mathfrak{g}_{\text{SM}} acts on VV, via the 𝔢 7\mathfrak{e}_7 Lie bracket, precisely as it does on three generations of Standard Model fermions and their antiparticles, including right-handed neutrino and its antiparticle — but ignoring spin!

There is, in fact, a very interesting three-fold symmetry built into 𝔢 7\mathfrak{e}_7, which is revealed when we put the Standard Model Lie algebra 𝔤 SM\mathfrak{g}_{\text{SM}} into it. It permutes the three generations.

Like Nasmith, I am not proposing a theory of physics. I’m only observing a fascinating mathematical pattern that might (or might not) be of some use in physics.

There are lots of things this pattern does not include: basically, everything I didn’t already mention. It does not include the spin of the fermions and gauge bosons. It does not include the Higgs boson, though in some sense it comes close (see the paper). It does not include a Lagrangian, so it doesn’t say anything at all about particle masses or interactions.

I could say a lot more about what my paper does do… most importantly, where this Lie algebra LL comes from! The details are very interesting. There’s also the curious role of the right-handed neutrinos. But I’ve already spent weeks explaining all these things in my paper, so I won’t do it here. Instead let me say a bit about how I wrote the paper.

Writing the paper

I’ve been wanting to keep up with how AI is transforming math. About a year ago a friend gave me a subscription to Claude Pro. I wanted to test it out, despite my many misgivings, including how large language models are contributing to global warming and income inequality. Given the amazing things that people have recently done in math using large language models, I didn’t think that never trying them out would put me in the best position to make good decisions about the future.

So, I wrote this paper with help from Claude Opus 4.8.

I started by giving it Nasmith’s paper and asking a long series of questions about that paper over several days. The results were very interesting and helpful. Eventually I asked it to summarize and expand on our conversation. It quickly spat out a 10-page paper.

This paper was written in a breezy, pleasant style — but also quite hard to understand in detail, since it mixed Nasmith’s terminology with the Lie algebra terminology I prefer, and the proofs skipped over some steps.

It took me about three weeks of hard work to fully understand and re-express all the ideas a way that I like. For a while I felt dumb and frustrated, because when I asked Claude to fill in the gaps in proofs, it used math I was not very competent in, like the theory of regular subalgebras, and the theory of minuscule representations. But I learned this math, and everything turned out to be basically correct — in part, I’m sure, because Nasmith’s original work was correct.

For several weeks I checked, reorganized, expanded and completely rewrote this material. By the end everything was written in a style I like, emphasizing the ideas I consider important, proving things fairly carefully, and adding a lot of expository material — for example, explaining the theory of regular subalgebras.

Almost no traces of Claude’s original writeup remain, even though I was deeply influenced by them. My proofs make few references to deep theorems, though they assume solid familiarity with simple Lie algebras and their root systems. The proofs also require no brutally hard computations — though Claude was eager to do such computations to check things.

Any mistakes in this paper are my own.

I’m not sure what conclusions I draw from writing this paper. I’m writing another math paper now, with a human coauthor, and I have no desire to get help from a large language model. For work on my own it could be very helpful. Fields medalist Jacob Tsimerman says it roughly doubles his productivity. Would using it be so bad for the environment, or so bad for society, that I should avoid it? Maybe. I deliberately stuck with Claude Opus 4.8 instead of something more powerful, to see what I could do with what you get from a $20/month subscription. But maybe that’s still bad.

I avoid flying to conferences, which in some ways cripples my ability to keep up with new trends and influence people — but I don’t mind that. It gives me more time to think.

I will think carefully about my next move.

August 17, 2026

John Baez — Three Generations in E7

It’s long been a mystery why there are 3 generations of quarks and leptons: three sets of particles, apparently identical except for how they interact with the Higgs boson. It would be nice if there were some good physical explanation. Nobody knows one. Barring that, it would be nice if some beautiful mathematical structure made this pattern seem natural. That’s what my new paper is about.

It’s my third paper about exceptional algebraic structures and the Standard Model. When you classify famous gadgets in algebra, beautiful gadgets with fancy names like ‘simple Lie algebras’ and ‘Euclidean Jordan algebras’ and ‘positive hermitian Jordan pairs’, you tend to get infinite series of them—together with a few exceptions that can be built using the octonions. This is a bit spooky, so I’ve been interested in this for a long time.

A few physicists have hoped that these exceptions are good for something. For example, maybe the quirky features of our best theory of particle physics, the Standard Model, aren’t accidental. Perhaps they fall out naturally from some exceptional algebraic structure.

It’s a long shot, but we’ve been stuck on figuring out new fundamental laws of particle physics for so long—roughly since the early 1980s—that it’s worth a try.

In 2018, Michel Dubois-Violette and Ivan Todorov noticed that the gauge group of the Standard Model falls out as symmetries of the so-called ‘exceptional Jordan algebra’ together with some ordinary Jordan algebras sitting inside it. I tried to clarify that here, with a huge amount of help from an excellent young mathematician:

• John Baez and Paul Schwahn, The Standard Model gauge group from the exceptional Jordan algebra. (Blog article here.)

It’s very nice, because the Jordan algebras in question arise naturally when you try to axiomatize the foundations of quantum physics. It would be so cool if something about quantum physics made the Standard Model seem mathematically natural!

But really this result only concerns the gauge bosons in the Standard Model: the photon, gluons, and the W and Z bosons. It says nothing about the fermions—that is, the quarks and leptons. And it seems quite hard to get those into the picture.

In 2020, Latham Boyle tried to solve this problem by tensoring the exceptional Jordan algebra with the complex numbers. This made one generation of fermions appear quite naturally! But the connection to the foundations of quantum physics seemed lost: tensoring the exceptional Jordan algebra with the complex numbers seems at first like it might be just a formal trick.

This spring, Latham and his student Endre Bokor and I showed the connection to quantum physics is not lost:

• John Baez, Endre Bokor and Latham Boyle, Jordan pair quantum theory and the Standard Model. (Blog article here.)

The idea is to work, not with Jordan algebras, but with more general things called Jordan pairs, which have been studied by mathematicians since at least 1975. We showed that you can still do quantum physics with Jordan pairs. And we showed that there’s an ‘exceptional’ Jordan pair that naturally contains the Standard Model gauge group and one generation of fermions!

This Jordan pair is built from the bioctonions: the octonions tensored with the complex numbers. And it’s closely related to an exceptional Lie algebra called \mathfrak{e}_6.

This is nice because the work of Dubois-Violette and Todorov used a smaller exceptional Lie algebra called \mathfrak{f}_4. Going up to \mathfrak{e}_6 gives the room to include one generation of fermions.

There’s an even larger exceptional Lie algebra you can use to build a Jordan pair: it’s called \mathfrak{e}_7. Bokor, Boyle and I tried using this to get three generations of fermions. There are things that make this tempting: not just the fact that \mathfrak{e}_7 is bigger, but the fact that the Jordan pair you get from it has a kind of three-fold symmetry. But we couldn’t get it to work.

Around this time I got very interested in some work that someone had sent me in October 2025. My inbox is packed with new theories of physics. Since the rise of large language models the inflow has increased: I get about two emails a day from someone telling me they’ve made a revolutionary discovery in physics. Practically none of these theories appeal to me. But this paper, and this thesis, were different:

• Benjamin Nasmith, An exceptional combinatorial sequence and Standard Model particles, 2020.

• Benjamin Nasmith, Tight Projective 5-Designs and Exceptional Structures, Ph.D. thesis, Royal Military College of Canada, 2023.

He claimed to fit three generations of fermions into the exceptional Lie algebra \mathfrak{e}_7.

When I started seriously trying to understand this paper, I wound up translating it into a language I’m more comfortable with, and expanding on the ideas a bit. So I wrote this:

• John Baez, Three generations in \mathfrak{e}_7.

Here’s the basic idea.

The idea

There is a standard way to fit the Lie algebra of the Standard Model gauge group, which I call \mathfrak{g}_{\text{SM}}, into the Lie algebra \mathfrak{e}_7. You can construct a Lie algebra L that fits between them:

\mathfrak{g}_{\text{SM}} \subset L  \subset \mathfrak{e}_7

As a vector space we have

\mathfrak{e}_7 \; \cong \; L \oplus V

for some vector space V of dimension 3 \times 32.

Moreover, the Lie algebra \mathfrak{g}_{\text{SM}} acts on V, via the \mathfrak{e}_7 Lie bracket, precisely as it does on three generations of Standard Model fermions and their antiparticles, including right-handed neutrino and its antiparticle—but ignoring spin!

There is, in fact, a very interesting three-fold symmetry built into \mathfrak{e}_7, which is revealed when we put the Standard Model Lie algebra \mathfrak{g}_{\text{SM}} into it. It permutes the three generations.

Like Nasmith, I am not proposing a theory of physics. I’m only observing a fascinating mathematical pattern that might (or might not) be of some use in physics.

There are lots of things this pattern does not include: basically, everything I didn’t already mention. It does not include the spin of the fermions and gauge bosons. It does not include the Higgs boson, though in some sense it comes close (see the paper). It does not include a Lagrangian, so it doesn’t say anything at all about particle masses or interactions.

I could say a lot more about this… most importantly, where this Lie algebra L comes from. The details are very interesting. There’s also the curious role of the right-handed neutrinos. But I’ve already spent weeks explaining all these things in my paper, so I won’t do it here. Instead let me say a bit about how I wrote the paper.

Writing the paper

I’ve been wanting to keep up with how AI is transforming math. About a year ago a friend gave me a subscription to Claude Pro. I wanted to test it out, despite my many misgivings, including how large language models are contributing to global warming and income inequality. Given the amazing things that people have recently done in math using large language models, I didn’t think that never trying them out would put me in the best position to make good decisions about the future.

So, I wrote this paper with help from Claude Opus 4.8.

I started by giving it Nasmith’s paper and asking a long series of questions about that paper over several days. The results were very interesting and helpful. Eventually I asked it to summarize and expand on our conversation. It quickly spat out a 10-page paper.

This paper was written in a breezy, pleasant style—but also quite hard to understand in detail, since it mixed Nasmith’s terminology with the Lie algebra terminology I prefer, and the proofs skipped over some steps.

It took me about three weeks of hard work to fully understand and re-express all the ideas a way that I like. For a while I felt dumb and frustrated, because when I asked Claude to fill in the gaps in proofs, it used math I was not very competent in, like the theory of regular subalgebras, and the theory of minuscule representations. But I learned this math, and everything turned out to be basically correct—in part, I’m sure, because Nasmith’s original work was correct.

For several weeks I checked, reorganized, expanded and completely rewrote this material. By the end everything was written in a style I like, emphasizing the ideas I consider important, proving things fairly carefully, and adding a lot of expository material—for example, explaining the theory of regular subalgebras.

Almost no traces of Claude’s original writeup remain, even though I was deeply influenced by them. My proofs make few references to deep theorems, though they assume solid familiarity with simple Lie algebras and their root systems. The proofs also require no brutally hard computations—though Claude was eager to do such computations to check things.

Any mistakes in this paper are my own.

I’m not sure what conclusions I draw from writing this paper. I’m writing another math paper now, with a human coauthor, and I have no desire to get help from a large language model. For work on my own it could be very helpful. Jacob Tsimerman says it roughly doubles his productivity. Would using it be so bad for the environment, or so bad for society, that I should avoid it? Maybe. I deliberately stuck with Claude Opus 4.8 instead of something more powerful, to see what I could do with what you get from a $20/month subscription. But maybe that’s still bad.

I avoid flying to conferences, which in some ways cripples my ability to keep up with new trends and influence people—but I don’t mind that. It gives me more time to think.

I will think carefully about my next move.

John Baez — Jordan Triples and the Standard Model

I don’t usually talk about particle physics here. I have a whole series of articles about octonions and the Standard Model on my other blog. But I’m kind of excited about this new paper, so I’ll talk about it here too:

• John Baez, Endre Bokor and Latham Boyle, Jordan pair quantum theory and the Standard Model.

Jordan algebras were introduced by Jordan, von Neumann and Wigner in 1934 in an attempt to formalize algebras of observables in quantum theory. They come in 4 infinite series—but there’s one more, the ‘exceptional Jordan algebra’, consisting of 3 × 3 self-adjoint matrices of octonions. For years physicists sought to find some use for it.

In 2018, Todorov and Dubois–Violette noticed that the symmetries of the exceptional Jordan include the Standard Model gauge group in a nice way. But it was unclear how to bring in the fermions—the quarks and leptons. That’s what our new paper does.

To do this, we need to go beyond Jordan algebras. Jordan pairs and Jordan triples are two closely linked formalisms that generalize Jordan algebras. Our paper explains them in detail—and how they’re connected to geometry and quantum mechanics. But here I will mostly skip that wonderful story, so I can quickly explain the connection to the Standard Model.

Here’s how the Standard Model gauge group, together with its representation on one generation of fermions, drops out of a Jordan triple.

The bi-Cayley triple

Let

\mathbb{O}_\mathbb{C} = \mathbb{C} \textstyle{\otimes}_\mathbb{R} \mathbb{O}

be the bioctonions: octonions with complex coefficients. Write \mathbb{O}_\mathbb{C}^2 for the space of column vectors with two bioctonion entries.

\mathbb{O}_\mathbb{C}^2 has a certain triple product

[x,y,z]=\frac{1}{2}(x(y^{\dagger}z)+z(y^{\dagger}x))

which obey the axioms of a gadget called a ‘positive hermitian Jordan triple’. It’s called the bi-Cayley triple.

Now, every positive hermitian Jordan triple gives rise to a \mathbb{Z}_2-graded real Lie algebra

\mathbf{k} = \mathbf{k}_0 \textstyle{\oplus} \mathbf{k}_1

Not a Lie superalgebra: a plain old-fashioned Lie algebra with a \mathbb{Z}_2-grading!

How does this work? We take the hermitian Jordan triple itself to be \mathbf{k}_1. The Lie algebra \mathbf{k}_0 consists of all linear maps from \mathbf{k}_1 to itself that are of this form:

x \mapsto [a,b,x] - [b,a,x]

for some a,b \in \mathbf{k}_1. These maps are called real inner derivations. They form a Lie algebra since the commutator of two such maps is another such map. With a bit more work we can define other operations making all of \mathbf{k} into a \mathbb{Z}_2-graded Lie algebra.

So, we get a big Lie algebra \mathbf{k}, and a Lie subalgebra \mathbf{k}_0 sitting inside it. From this we get two Lie groups: a big one K whose Lie algebra is \mathbf{k}, and a subgroup K_0 whose Lie algebra is \mathbf{k}_0.

The quotient is K/K_0 is a nice kind of manifold called a hermitian symmetric space. Conversely, any compact hermitian symmetric space give rise to a positive hermitian Jordan triple!

This geometric picture is revealing. The group K acts transitively as symmetries of our hermitian symmetric space, while the stabilizer of any point is isomorphic to K_0. Our original Jordan triple, \mathbf{k}_1, is then the tangent space of that point! So, K_0 acts on this Jordan triple. This action preserves the triple product, and we call K_0 the real inner automorphism group of our Jordan triple.

Here’s another great thing about the geometric picture: hermitian symmetric spaces were classified by Eli Cartan (who seems to have spent his life classifying things). As a result we also know the classification of positive hermitian Jordan triples. They come in four infinite series together with two exceptions. One is the bi-Cayley triple, and other is the Albert triple, which is the complexification of the exceptional Jordan algebra. The bi-Cayley triple is a subtriple of the Albert triple. It’s these two exceptions that are connected to the Standard Model. But we’ll start with the bi-Cayley triple.

The 3-graded Lie algebra coming from the bi-Cayley triple is the compact real form of \mathfrak{e}_6:

\mathfrak{e}_6 = \big[\mathfrak{so}(10) \textstyle{\oplus} \mathfrak{u}(1)\big] \textstyle{\oplus} \mathbb{O}_\mathbb{C}^2

The even part of this Lie algebra is in brackets. The corresponding hermitian symmetric space is called the bioctonionic plane (\mathbb{C}\otimes\mathbb{O})P^2. The even part of our 3-graded Lie algebra, \mathfrak{so}(10)\oplus \mathfrak{u}(1), generates the stabilizer of a point in the bioctonionic plane. The odd part, our friend \mathbb{O}_\mathbb{C}^2, is the tangent space of that point.

Here’s the first big surprise. The even part transforms as the adjoint representation of \mathrm{Spin}(10), while the odd part itself transforms as the 16-dimensional complex spinor representation of \mathrm{Spin}(10). Ignoring the extra \mathrm{U}(1) for a moment, this is exactly what we see in a \mathrm{SO}(10) grand unified theory: gauge bosons in the adjoint representation, and one generation of fermions in the 16-dimensional spinor representation.

So before we do anything, the bi-Cayley triple already smells like it contains the ingredients of an \mathrm{SO}(10) grand unified theory.

Tripotents

In a Jordan algebra the important elements are the idempotents, e^2 = e. In a Jordan triple W their role is played by tripotents: elements e with

[e,e,e] = e

A tripotent always lets us split W into three parts via something called its Peirce decomposition. The operator w \mapsto [e,e,w] has eigenvalues 0, 1/2, and 1, so W splits into the corresponding eigenspaces

W = W_0(e) \textstyle{\oplus} W_{1/2}(e) \textstyle{\oplus} W_1(e)

which are called the Peirce 0-space, Peirce 1/2-space and Peirce 1-space of e. A tripotent is called minimal when its Peirce 1-space is one-dimensional. Two tripotents e_1, e_2 are called colinear when each lies in the other’s Peirce 1/2-space.

I can’t resist explaining some of the quantum physics here. In a hermitian Jordan triple, the triple product [-,-,-] is linear in the first and last slot, but conjugate-linear in the middle slot. So, if you multiply a tripotent by a phase \alpha, you get a new tripotent:

[\alpha e, \alpha e, \alpha e] = \alpha \overline{\alpha} \alpha e = \alpha e

This should remind you of how when you multiply a unit vector in a Hilbert space by a phase, you get a new unit vector. In Jordan triple quantum mechanics, minimal tripotents take the place of these unit vectors. The hermitian symmetric space K/K_0 that I was talking about earlier is the same as the space of minimal tripotents mod phase! So, it generalizes the familiar space of ‘pure states’ in quantum mechanics: unit vectors mod phase.

But let’s get back to the Standard Model.

A chain of Jordan triples

From here on, the single fact driving everything is this: in any hermitian Jordan triple, any minimal tripotent’s Peirce 1/2-space is itself a hermitian Jordan triple!

If we run this starting from the bi-Cayley triple, we get this chain of hermitian Jordan triples, where each row’s 1/2-space is the next row’s triple:

Jordan triple Lie algebra \mathbf{k}_0 \oplus \mathbf{k}_1 (even part in brackets)
W = \mathbb{O}_\mathbb{C}^2 \mathfrak{e}_6 = [\mathfrak{so}(10) \oplus \mathfrak{u}(1)] \oplus \mathbb{O}_\mathbb{C}^2
W' = \mathfrak{a}_5(\mathbb{C}) \mathfrak{so}(10) = [\mathfrak{su}(5) \oplus \mathfrak{u}(1)] \oplus \mathfrak{a}_5(\mathbb{C})
W'' = \mathrm{M}_{3,2}(\mathbb{C}) \mathfrak{su}(5) = [\mathfrak{g}_{\mathrm{SM}}] \oplus \mathrm{M}_{3,2}(\mathbb{C})

Here \mathfrak{a}_5(\mathbb{C}) is the Jordan triple of antisymmetric 5\times 5 complex matrices, \mathrm{M}_{3,2}(\mathbb{C}) is the Jordan triple of 3\times 2 complex matrices, \mathfrak{g}_{\mathrm{SM}} = \mathfrak{su}(3)\oplus\mathfrak{su}(2)\oplus \mathfrak{u}(1), and

G_{\mathrm{SM}} = \mathrm{S}(\mathrm{U}(2) \times \mathrm{U}(3)) \cong (\mathrm{SU}(3)\times\mathrm{SU}(2)\times\mathrm{U}(1))/\mathbb{Z}_6

is the true Standard Model gauge group.

The gauge group from two tripotents

Start with the bi-Cayley triple. Choose two colinear minimal tripotents e_1, e_2. Descend the table twice:

• Start with W = \mathbb{O}_\mathbb{C}^2, which has real inner automorphism group (\mathrm{Spin}(10)\times\mathrm{U}(1))/\mathbb{Z}_4.

• Fix e_1. Its Peirce 1/2-space is W' = \mathfrak{a}_5(\mathbb{C}), with real inner automorphism group \mathrm{SU}(5)\times\mathrm{U}(1).

• Fix e_2 (colinear with e_1, so living in W'). Its Peirce 1/2-space in W' is W'' = \mathrm{M}_{3,2}(\mathbb{C}), with real inner automorphism group exactly G_{\mathrm{SM}}.

In other words, the subspace of the bi-Cayley triple colinear with both e_1 and e_2 is a Jordan triple whose real inner automorphism group is the Standard Model gauge group.

The choice of e_1 and e_2 also pins down how G_{\mathrm{SM}} sits inside the original group \mathrm{E}_6. At each we step take the subgroup that acts with determinant 1 and preserves the chosen tripotent up to a phase; this gives a chain of subgroups whose members are \mathrm{Spin}(10), \mathrm{U}(5), and G_{\mathrm{SM}}, so we get the embeddings

G_{\mathrm{SM}} \subset \mathrm{SU}(5) \subset \mathrm{Spin}(10)

In particle physics, this is the classic chain taking us from the so-called \mathrm{SO}(10) grand unified theory down to the \mathrm{SU}(5) grand unified theory down to the Standard Model. And it’s well known that restricting the 16-dimensional complex spinor representation of \mathrm{Spin}(10) along this chain gives precisely the Standard Model representation \rho_{\mathrm{SM}} on one generation of fermions! So we get one generation of Standard Model fermions this way.

The six particles types as Peirce spaces

We have gotten the representation of the Standard Model gauge group on one generation of fermions without any fuss. But it’s also fun to peer into the details, and see how the different kinds of fermions emerge.

For any tripotent e, we have projections P_0(e), P_{1/2}(e) and P_1(e) onto its three eigenspaces: its so-called Peirce projectors. Since we get the Standard Model structure using two minimal tripotents e_1 and e_2 in the bi-Cayley triple \mathbb{O}_{\mathbb{C}}^2, there are nine composites of two Peirce projectors we can apply to this triple. This is how we pick out the different kinds of fermions!

As a representation of the Standard Model Lie algebra

\mathfrak{g}_{\mathrm{SM}} = \mathfrak{su}(3) \textstyle{\oplus} \mathfrak{su}(2) \textstyle{\oplus} \mathfrak{u}(1)

any generation of Standard Model fermions transforms as the direct sum of six irreducible representations:

\rho_{\mathrm{SM}} = (3,2,\tfrac{1}{6}) \textstyle{\oplus} (\bar 3,1,\tfrac{1}{3}) \textstyle{\oplus} (\bar 3,1,-\tfrac{2}{3}) \textstyle{\oplus} (1,2,-\tfrac{1}{2}) \textstyle{\oplus} (1,1,1) \textstyle{\oplus} (1,1,0)

These correspond to the six types of left-handed fermion: q_L, \overline{d_R}, \overline{u_R}, \ell_L, \overline{e_R}, \overline{\nu_R}. Six irreducible pieces, six particle types.

It turns out these are exactly the six nonzero components of the Peirce decomposition of \mathbb{O}_\mathbb{C}^2 with respect to both e_1 and e_2. Those six match up one-to-one with the particle types:

Peirce projector representation of G_{\text{SM}} particle type
P_{1/2}(e_2) P_{1/2}(e_1) (3, 2, +1/6) q_L
P_{1/2}(e_2) P_0(e_1) (\overline{3}, 1, +1/3) \overline{d_R}
P_0(e_2) P_{1/2}(e_1) (\overline{3}, 1, −2/3) \overline{u_R}
P_0(e_2) P_0(e_1) (1, 2, −1/2) \ell_L
P_1(e_2) P_{1/2}(e_1) (1, 1, +1) \overline{e_R}
P_{1/2}(e_2) P_1(e_1) (1, 1, 0) \overline{\nu_R}

The remaining three combinations—P_1(e_2)P_1(e_1), P_1(e_2)P_0(e_1), and P_0(e_2)P_1(e_1)—all vanish, which is why we land on six pieces and not nine.

So the whole package—the gauge group G_{\mathrm{SM}}, the embedding G_{\mathrm{SM}} \subset \mathrm{Spin}(10), the representation \rho_{\mathrm{SM}}, and even the split of one generation into its six particle multiplets as distinct Peirce components—all comes out of the single object \mathbb{O}_\mathbb{C}^2 once you choose two colinear minimal tripotents.

And if you prefer to start one level up, with the Albert triple \mathfrak{h}_3(\mathbb{O}) \otimes \mathbb{C}, you get the same result by choosing three mutually colinear tripotents instead of two—but for that, read our paper!

August 13, 2026

Tim Gowers — What sort of maths are LLMs good at?

For the sake of anyone who might read this blog post in the distant future (a month from now, say), let me mention that I am writing it a few days after OpenAI announced that it had solved ten major problems in mathematics and theoretical computer science, including the first construction of a non-sofic group, and a proof that the multicolour Ramsey number R(3,3,...,3) (where there are k 3’s) grows superexponentially in k. The first was, to judge from various talks I have been to, one of the most important unsolved problems in group theory, and the second was a major open problem in Ramsey theory that I didn’t necessarily expect to see solved in my lifetime, though of course such expectations now have to be revised. The reason I want to be clear about the timing is that I shall be discussing the current capabilities of LLMs in the full expectation that those will continue to change rapidly. So it is likely that in not too long from now, if there is anything interesting in what I write, it will be interesting mainly as a record of what the situation looked like in early August 2026.

These results, and the other eight on the list, are extraordinarily impressive, but it still doesn’t seem to be the case that LLMs are better than all humans at all aspects of mathematics. If they were, then their big speed advantage over us would mean that there would be much more of a flood of results. So it is natural to wonder about what kinds of problems LLMs are good at, and about where there is still room for improvement. I don’t pretend to have a good answer to this question, where a good answer would be a crisp classification that would fit the current examples well, but it is an interesting exercise to try to rule out some bad answers, and to try to identify potential answers that aren’t obviously contradicted by the evidence.

Are LLMs particularly good at finding counterexamples?

A first remark here is that LLMs are not just good at finding counterexamples: they can find proofs of difficult statements as well. However, it is notable that the most famous problems they have solved have almost all been with counterexamples rather than proofs. That is true of the two problems mentioned above, and also of the Jacobian conjecture and the unit distance conjecture.

If one wants to theorize that LLMs are particularly good at finding counterexamples, then there are two things it would be good to do to make the theory more convincing. The first may sound unproblematic: it is to decide when solving a problem counts as finding a counterexample. Once that is sorted out, the second is to come up with a potential explanation of why LLMs would be particularly well suited to solving problems of that particular kind.

What does it mean to find a counterexample?

Why am I suggesting that it is not completely obvious what it means to find a counterexample? Surely, one might suggest, all it means is that you have a statement of the form “Every object of such and such a type has such and such a property,” and you exhibit an object of the given type that does not have the given property.

However, this doesn’t always work. Consider a famous result of Vinogradov, which states that every sufficiently large positive integer is a sum of three primes. The negation of this statement is (or is equivalent to) the statement that for every positive integer N there exists an integer n\geq N such that n is not a sum of three primes. In other words, it states that every positive integer N has a certain property. Seen in this light, Vinogradov found an example of a positive integer N that does not have the given property. Do we want to say that Vinogradov found a counterexample? Clearly not — the result should obviously be classified as a theorem and not a counterexample.

Thus, we cannot just naively say that LLMs are particularly good at negating universally quantified statements: there has to be something about the nature of the universal quantification. With the three-primes example, it is clear that Vinogradov did not think, “How am I going to find N with this property?” Rather, what he thought would have been more like, “I’ve got an integer n that is very large. How am I going to show that it is a sum of three primes?” In other words, all his focus would have been on the universally quantified n, with the existentially quantified N being a sort of afterthought once the details of the proof have been worked out.

In general, many interesting results, when they are stated formally, begin with an alternation of two or three (or more) quantifiers. The question then becomes to determine which is the first “interesting” quantified variable in some sense. Here’s another example to illustrate the point, from the theory of finite-dimensional normed spaces. I’ll give a few mathematical details for those curious, but if you don’t care about those, then you can skip the next three paragraphs and should get the gist of what I am saying about this example.

Let X and Y be two n-dimensional normed spaces and let T be a linear map from X to Y. We say that T is a C–isomorphism if there exists \lambda>0 such that \lambda\|x\|\leq\|Tx\|\leq C\lambda\|x\| for every x\in X. By rescaling we can always take \lambda to be 1, in which case we have that \|x\|\leq\|Tx\|\leq C\|x\| for every x\in X. If C=1, then this tells us that T is an isometry. In general, the Banach-Mazur distance d(X,Y) between X and Y is defined to be the smallest C such that there exists a C-isomorphism from X to Y. It is easy to see that the logarithm of the Banach-Mazur distance is a metric on the set of isometry classes of n-dimensional normed spaces. A less easy fact, but still not too hard, is that the resulting metric space is compact: in fact, it is known as the Banach-Mazur compactum.

It is natural to wonder what the diameter of the Banach-Mazur compactum is, and here things get interesting. A result of Fritz John states that every n-dimensional space X has distance at most \sqrt n from \ell_2^n. (The idea of the proof is as follows: pick inside the unit ball of X an n-dimensional ellipsoid of maximal volume; that is the unit ball of a normed space Y that is isometric to \ell_2^n; it can be shown that the identity map is a \sqrt n-isomorphism between X and Y.) From Fritz John’s theorem and the (multiplicative) triangle inequality, it follows that d(X,Y)\leq n for any two n-dimensional normed spaces. That is, the diameter of the Banach-Mazur compactum is at most n. But might it be substantially less than that?

An indication that the answer is not obvious comes from looking at the spaces \ell_1^n and \ell_\infty^n. The identity map between these two spaces is an n-isomorphism, but one can do much better by mapping the standard basis vectors not to themselves but to vertices of the unit cube, with the vertices chosen to be as orthogonal as possible. In particular, if there exists an n\times n Hadamard matrix, then the corresponding linear map is a \sqrt n-isomorphism. One can push this observation and deduce that for any p,q\in[1,\infty] the Banach-Mazur distance between \ell_p^n and \ell_q^n is O(\sqrt n). It is also easy to show that d(\ell_1^n,\ell_2^n)=\sqrt n, so \ell_p-spaces hardly improve on the easy lower bound, and do not improve on it at all in dimensions n for which an n\times n Hadamard matrix exists.

In 1981, Gluskin famously solved the problem by determining the correct asymptotics for the diameter of the Banach-Mazur compactum. Informally, what he showed was that the diameter is within a constant of the upper bound that follows immediately from Fritz John’s theorem. If we make the quantification explicit, then the statement we end up with is

\exists c>0\ \forall n\ \exists X,Y\in K_n\ d(X,Y)\geq cn,

where I have written K_n for the set of all n-dimensional normed spaces. (If you want to argue that it is not a set, then let me specify in addition that the underlying vector space is \mathbb R^n.) In words, there is a positive constant c such that for every positive integer n there are n-dimensional normed spaces X and Y such that the Banach-Mazur distance between X and Y is at least cn.

I can’t continue without very briefly describing the beautiful and highly influential idea Gluskin had for solving this problem. He took X and Y to be normed spaces whose unit balls were random symmetric convex sets defined as follows: take the standard basis vectors and a handful of other random unit vectors, as well as the negatives of all these vectors, and take the convex hull. Gluskin then showed that if two normed spaces are chosen from this distribution, then with high probability their Banach-Mazur distance is at least cn.

But back to the main point, which is that the logical form of the above statement is very similar to the logical form of Vinogradov’s theorem, which is

\exists N\ \forall n\geq N\ \exists p_1,p_2,p_3\in P\ \ p_1+p_2+p_3=n

where I have written P for the set of primes. And yet, Vinogradov’s result is unquestionably a theorem, while Gluskin’s result is unquestionably a counterexample, or at least an example.

What is the important difference between the two statements? It seems to be that in Vinogradov’s three-primes theorem the number n plays a more essential role in the statement that is to be proved about the various quantified variables. In Vinogradov’s theorem, that statement is n=p_1+p_2+p_3, whereas for Gluskin’s theorem the statement to be proved is

\dim X = \dim Y = n and d(X,Y)\geq cn,

which we can write equivalently as

\dim X = \dim Y = n and d(X,Y)\geq c\dim X.

In the case of Vinogradov’s theorem, the whole challenge is to get those three primes to add up to n, whereas for Gluskin it is not remotely challenging to get the dimensions of X and Y to equal n: the challenge is to get X and Y to be very far from each other, relative to their common dimension.

There is a further complication to bear in mind here, which is that via the process known as Skolemization, a universally quantified statement of the form \forall x\in X\ \exists y\in Y\ \ P(x,y) can be converted into an existentially quantifed statement \exists f:X\to Y\ \forall x\in X\ \ P(x,f(x)). (For this to be an equivalence one needs the axiom of choice, but it is certainly a sufficient condition.) This is not just a piece of logical trickery, but it often reflects quite accurately how we think about some problems. For instance, it is more natural to think of Gluskin’s example as a recipe for constructing (or at least proving the existence of) a pair of suitable normed spaces for any given dimension n, or in other words to construct a suitable function from \mathbb N to pairs of normed spaces by giving its value at each n, than it is to think of it as a statement that says that every positive integer n has a certain complicated property.

Yet another complication is that some universally quantified statements follow naturally from existentially quantified statements, or may even be equivalent to them. For example, the theorem that a 2-dimensional torus is not homeomorphic to a 2-dimensional sphere is a universally quantified statement (every map from the torus to the sphere fails to be a homeomorphism), but the natural way to prove it is to prove the existential statement that there is an invariant that distinguishes the two spaces. For an example of where a universal statement is equivalent to an existential statement, consider a statement of the form that a vector x\in\mathbb R^n does not belong to the convex hull of a certain compact set A. The statement that no convex combination of elements of A is equal to x is equivalent to the existence of a linear functional \phi:\mathbb R^n\to\mathbb R and a \lambda\in\mathbb R such that \phi(x)>\lambda and \phi(a)\leq\lambda for every a\in A. In both these cases it feels natural to regard the result as a theorem that is proved via an existential statement, perhaps because it is the theorem that is ultimately what interests us. But using “what interests us” as a criterion to determine what counts as a counterexample seems a little vague, and is a difficult criterion to use if we want to explain convincingly why AI should be good at finding counterexamples.

A more general argument against the notion that there is something about existential statements that is particularly suited to AI is that the need to establish existential statements pervades almost all of mathematical research, regardless of the nature of the headline result being aimed for. For example, if I want to prove a statement by induction, I may well look for a strengthening of the statement that serves better as an inductive hypothesis. Or if I want to prove that every object of type T with property P also has property Q, then I may well look for a property R that follows from P and can be used to prove Q. These are more metamathematical existence problems, but the distinction can be somewhat blurred, and more importantly, when trying to prove a statement S, it is often the case that the main question in our minds is less, “Why is S true?” and more, “What could a proof of S be like?” To give an example, I feel I understand pretty well why Goldbach’s conjecture is true — a highly plausible probabilistic model of the primes implies it and agrees closely with computational data — but if I were making a serious attempt to prove it, that understanding, which many mathematicians have had for a century or so, would be of limited help. Rather, my main task would be to try to find proof techniques that were powerful enough to make those heuristic ideas rigorous.

What is the difference between an example and a counterexample?

Logically, every statement of the form \exists x\ P(x) is a counterexample to the universally quantified statement \forall x\ \neg P(x). However, we do not describe all existential statements as counterexamples. For example, if I were to say, “The \ell_p-spaces with 1\leq p<\infty are all separable, as is c_0, but \ell_\infty is not separable,” I would not describe the second part of that assertion as a counterexample to the claim that all Banach spaces are separable. Rather, I would present it as probably the most basic example of a non-separable space. The important point seems to be that there was no particular reason to think that all Banach spaces would be separable, and finding an example of a non-separable space is not very difficult.

I think the first point is more important here: we are more inclined to call an object a counterexample if the existence of that object disproves a statement that we had quite good reason to believe. It often happens that after repeated unsuccessful attempts to prove a statement, mathematicians begin to feel that it has no particular reason to be true, even if it seems to be hard to come up with a counterexample to it. In such a situation, if a counterexample is eventually found, it may have lost something of its “counter” feel. My impression is that the construction of a non-sofic group comes into this category. There have been several proposals in the literature for how one might construct such a group, and I don’t think there were many (or even any?) experts who strongly believed that all groups were sofic. So it feels more natural to say, “OpenAI came up with the first example of a non-sofic group” than to say, “OpenAI found a counterexample to the soficity conjecture” (despite the fact that that section of their paper is entitled “A counterexample to the soficity conjecture”).

Likewise, it seems to me that the new lower bound for multicolour Ramsey numbers is more of an example than a counterexample. I think quite a lot of people believed that the bound should be exponential, so for them it was a counterexample, but others, myself included, were more neutral about it. As a matter of fact, I have worked on the problem in the past (a long time ago) in an equivalent formulation, which asks how many triangle-free graphs on n vertices you need if you want their union to be the complete graph K_n. If you take bipartite graphs, then it’s easy to see that you need \log_2n of them, but that bound can be improved if instead you observe that a complete 5-partite graph can be written as a union of two triangle-free subgraphs, and therefore it is possible to write the complete graph as a union of 2\log_5n triangle-free graphs. It is then tempting to try to do better, with triangle-free graphs that are less dense but that make up for it with unbounded chromatic number — a necessary condition if one wishes to use a sublogarithmic number of graphs, which is equivalent to showing a superexponential lower bound for R(3,3,\dots,3). All this is to say that when I worked on the problem, my efforts were concentrated on what turned out to be the right direction, so for me OpenAI found an example of what I (weakly) expected, rather than a counterexample.

Where does this leave us?

I would like to find a coherent explanation of the conjunction of the following facts.

  1. The most notable mathematical results proved by LLMs have tended to be ones that we would classify as examples or counterexamples, where counterexamples are, broadly speaking, existence statements that disprove statements that we expected to be true.
  2. Many statements can be formulated as existence statements when we would usually think of them as universal statements, and vice versa, so what we consider to be an example depends on the mathematical context of a statement as well as its logical form.
  3. LLMs are pretty good at proving universal statements as well: it’s just that the strongest statements they have proved that we would think of as theorems have mainly not been at the level of the strongest statements that we would think of as counterexamples.

Given these facts, it seems likely that what LLMs are good at is something else, which happens to have as a consequence that they are good at the kind of existence problem that we would normally classify as asking to find a non-trivial example.

Let us consider two things that we can be confident that LLMs are good at. One of them is knowing a lot of mathematics: if a problem can be solved by means of a relatively standard argument, it is highly likely that an LLM will be able to find and use that argument. The other is the ability that an LLM has simply by virtue of being a computer: it can work at huge speed (compared with humans at least) and can therefore afford to make a large number of unsuccessful attempts at a problem before it finds a solution.

Without even looking at what LLMs have actually managed to solve, one might guess that these two features would lead to their having a somewhat different style from human mathematicians. Very roughly, LLMs would have the edge when there is more of a probabilistic element to the proof-finding process: they would be good at problems for which the best method is to try a lot of ideas, not necessarily particularly novel, until at some point you get lucky. Humans on the other hand would be better (for the moment) at finding more “surprising” and “conceptual” arguments, where the appropriate method is to dig deeper and deeper into a problem until the solution reveals itself. (It is hard to say exactly what this means, but I hope that any experienced researcher reading this will know what I am talking about.)

This raises two questions: does the guess above correspond at all to the reality that we are observing, and is there any reason to suppose that what I have tentatively described as the “LLM style” of doing mathematics would lead naturally to LLMs discovering several counterexamples (or just examples) to long-standing conjectures, even if that was by no means all they could do?

I don’t pretend to have a scientific answer to either question, but the reactions of experts to several of the remarkable solutions that ChatGPT has found do lend some support to the idea that LLMs work in more of a try-lots-of-things-till-you-get-lucky way. People often seem to react by saying something like, “Initially I was amazed that the problem had been solved, but on closer inspection I realized that the approach was actually not all that novel, and one that with the right small hint a suitably expert human could have found quite easily.”

For the second question — whether the LLM style is well suited to finding (counter)examples — I think matters are less clear, because there are many ways of searching for a counterexample, and some of them fit better than others the style I have described. Here are a few general methods. (I don’t claim that the list is exhaustive.)

  1. Look for an off-the-shelf example. Here one has a stock of fairly standard examples and one simply tries them out one after another to see whether any of them fails to satisfy the given statement. For example, Ryan O’Donnell ends his wonderful book on the analysis of Boolean functions with some tips, one of which is, “If you have a conjecture about Boolean functions, test it on dictators, majority, parity, tribes (and maybe recursive majority of 3). If it’s true for these functions, it’s probably true.”
  2. Build an example from basic examples and standard construction methods. For an algebraic problem, for instance, one might start with some standard examples, but then take products or quotients or limits.
  3. Make heavy use of metavariables. The word “metavariable” comes from computer science, and in particular from automatic theorem proving, and refers to the practice that in mathematics would correspond to writing, “where x is to be chosen later,” (in which case x is the metavariable). In a paper we usually do this only in fairly simple situations such as when we need to choose a number \epsilon>0 that is small enough for later arguments to work. But when we search for an example of an object x that satisfies some property Q (which may well be a conjunction of simpler properties Q_1,\dots,Q_k), it is often not a good strategy to specify x completely and only then to check whether it satisfies Q. Instead, it can be more fruitful to do almost the opposite: we start by saying virtually nothing about x and simply launch into proving that it satisfies Q. In the course of doing so, we find that we need x to satisfy a property P_1. If we are lucky we can describe in a nice way a very general class of objects x that satisfy P_1. For instance, we may be able to find a parametrized class: we identify some function f and show that f(y) satisfies P_1 for every y of a certain type. The problem is then reduced to finding y such that $Q(f(y))$ holds, which is a more specific version of the original problem. There may be many iterations of this process, or a mixture of this process and other processes, before an example is eventually found.
  4. Try to prove the opposite. If one wishes to find x such that Q(x), it can be surprisingly helpful to start by attempting to prove the statement \forall x\ \neg Q(x). The reason this can be helpful is that using our standard methods of attempting to prove something, we may end up identifying a key lemma that would suffice: that is, we may find an intermediate property R that implies \neg Q in a non-trivial way and thus reduce the problem \forall x\ \neg Q(x) to \forall x\ R(x). Turning things round again, it may well then be that finding a counterexample to R is easier than finding a counterexample to \neg Q (that is, an example that satisfies Q). Of course, there is no guarantee that a counterexample to R will be an example of Q, but sometimes we are lucky and it is. More often, we can use the idea of the previous method, noting that it is at least a necessary condition of an example of Q that it should not be an example of R, so one can try to describe a general class of objects that fail R and in that way reduce the problem.
  5. Successive approximation. Sometimes, when we are searching for an example of x such that Q(x), we write down a moderately plausible guess x_0 not because we think it has a chance of working (if we did, then we would be using the first strategy), but because we hope that if x_0 does not satisfy Q, then we will be able to diagnose what went wrong and specify a new guess x_1 that does not have that defect. Again, this strategy can either be iterated or combined with one or more of the other strategies.
  6. Just-do-it proofs. Sometimes we need x to satisfy infinitely many properties Q_1,Q_2,\dots, each of which is, individually, quite easy to satisfy. In such situations, we often “build” x inductively bit by bit, ensuring at the ith stage of the process that however the building process continues, x will satisfy Q_i.
  7. Pick a random example. Often it is very hard to give an explicit example of an x that satisfies Q, but there is a natural probability distribution for which one can show that if one chooses x randomly from that distribution, then with high probability (or at least non-zero probability) it will satisfy Q.
  8. Pick a generic example. In more infinite contexts, it may again be quite hard to give an explicit example of an x that satisfies Q, but one may be able to show that the set of x that fail Q is or measure zero, or is a meagre set, or is small in some other way.

There is no particular reason to suppose that LLMs would be equally good at each of the methods above. So perhaps what we are observing is not quite that LLMs have a particular ability to find examples, but more that they are particularly good at finding examples (and proofs) in a certain way. Looking at the above techniques, one might imagine that they would be very well suited to checking off-the-shelf examples, finding just-do-it proofs (since that is a rather standard method with lots of instances in their training data), using the probabilistic method (unless, as often happens, significant new ideas are needed to show that the probabilities work out), and picking generic examples. The other three methods described above — use of metavariables, trying to prove the opposite, and using successive approximation — require more of an ability to judge whether the approach one is taking is likely to be fruitful. Here it seems at least possible that humans will sometimes have an advantage, but the conditions that a problem would need to satisfy are quite stringent. One would need an example to be one that lies at a leaf of a very large search tree — too large to be searched for by a combination of moderate mathematical ability and brute force — but that can be found by a mathematician with a sufficiently good nose for when they are making progress that they can prune the search tree very substantially.

Why wouldn’t LLMs also have that “nose”? I don’t rule out that “nose” is an emergent property of the way LLMs are trained, and that within a year or two they will have it to the same extent that we have it. But for now, in my interactions with ChatGPT, I do have a distinct impression that they haven’t got there quite yet. When I discuss an open problem with 5.6 Pro, I am often presented with approaches that sound promising until I think about them carefully, and then seem quite a lot less promising. And they will also often end a response by saying, “I have not managed to answer the question you asked, but have managed to reduce it to the following much narrower and more precise question,” which sounds very promising until it has happened five times without any obvious progress having been made. It isn’t completely obvious how they will get better at this, since their training data will not be full of examples of fruitful and less fruitful directions to pursue when trying to solve problems: all they will typically see is tidied up proofs that hide the thought processes of their discoverers. Of course, human mathematicians also don’t get to learn much about how to do research from the experience of other mathematicians, and yet we somehow manage to pick it up. But the situation is a little different for us, in that a lot of what we learn is by doing rather than emulating.

Another reason it is not obvious that “nose” is a property that emerges naturally when LLMs are scaled up is that if LLMs make heavy use of their broad knowledge and can afford to do a lot more brute-force search than humans can, then they will lack the incentive that humans have to prune the search tree ruthlessly. It could conceivably be that their successes so far are achieved using methods that for a human would be considered extremely inefficient, but that because of their superior speed and knowledge, the combinatorial explosion these methods will lead to has not yet become apparent.

It would be very interesting to try to test this experimentally, but it is also difficult, because if an LLM has what looks like the kind of idea that could only be the result of “deep thought” about a problem, we can never be sure that it has actually carried out that deep thought, as opposed to finding a model argument already in the literature, or in other words exploiting the deep thought of a human mathematician. It would probably be easier (but still not easy) to test it by using models that are less powerful than the latest ones and that have been to some extent shielded from the mathematical literature: one could give them a carefully designed suite of problems and see whether the ones that the LLMs solve have particular characteristics.

It may seem as though I am desperately clinging to the hope that humans will continue to be able to make meaningful contributions to mathematical discovery for a while yet, but while I do indeed hope that, I am not making any assertions of the form “LLMs will never be able to do X”. I think it is likely that they will, and given the pace of progress over the last three years it will probably happen quite soon. But I do think that there may be a hurdle for LLMs to clear and it seems at least possible that it won’t be cleared as straightforwardly as some of the previous hurdles.

In that connection, it would also be interesting to see whether a different reward structure leads to LLMs being able to solve different kinds of problems. For example, if during training an LLM (or machine-learning system of some other kind) is not just rewarded if it ends up with a solution, but also penalized if it explores too many dead ends or if it “cheats” by getting the answer from the literature, perhaps it would be incentivized to go about the research process in a more human way and thereby achieve better results for classes of problems where it is yet to make a big impact.

If the hurdle is cleared, either by pure scaling up or by some more thoughtful method, it will be quite difficult to know when that has happened, since, as just mentioned, an idea that seems very original and surprising may just be lurking somewhere in an LLM’s training data. But I would be confident that it had been cleared if an LLM were to come up with a proof that was as surprising to me as the solution of the cap-set problem was in 2016: the previous best known bounds were completely eclipsed, the method was utterly different from anything I had thought about trying, and afterwards there was a flurry of activity as people came to understand what this wonderful new technique was capable of.

Conclusion

I wasn’t quite sure where I would end up when I started this post, and now that I’ve got to the end, I feel that my main conclusions are not particularly new or surprising, but I hope that the route to them is of some interest. The main points I have made are the following.

  1. “Finding an example” is in practice not the same thing as proving a statement that begins with an existential quantifier.
  2. If it is true that current models are particularly good at finding examples, that is probably not because they have a particular affinity for existential statements, but more because the proof-discovery methods that are appropriate for finding certain kinds of examples play to the obvious strengths of LLMs: wide knowledge and the ability to explore many paths of the search tree that humans would judge to have a low probability of success.
  3. It seems likely that LLMs will carry on improving very quickly. However, if, contrary to expectations (mine at least), there turns out to be some residual class of problems (or other mathematical activities) for which humans continue to have the edge for a while, it is likely that those will be problems for which the mysterious human ability to prune the proof-discovery search tree is particularly advantageous: that is to say, problems where the search tree is deep and has a large amount of branching, so that without rigorous pruning a search is not feasible even for a computer.
  4. A good sign that LLMs have reached human level for a much wider class of problems will be if they start proving theorems using methods that, like much of the very best human mathematics, are new and surprising but that with hindsight come to seem beautiful and natural. They should also be methods that are difficult to stumble on by accident. It is hard to say precisely what would count as such a proof, but I think we’ll recognise it when we see it.

July 29, 2026

Secret Blogging Seminar — An experiment with AI-assisted writing

As in David’s most recent post, there’s been a lot in the news about finding proofs and counterexamples with AI. Last weekend, I decided to try an experiment with writing using AI. I learned a lot, and wanted to quickly discuss the experiment and my thoughts on it here. Lots of people are certainly already doing this, but I haven’t seen many people talking about it.

The starting point is that Victor Ostrik and I started a project back in 2017, generalizing a result of Kuperberg about quantum G2, from generic q to q a root of unity. Namely, we showed that for q a root of unity outside of a specific finite list, the Karoubi completion of the G2 spider category is equivalent to the category of tilting modules of the Lusztig form of the quantum group G2. At some point during those 9 years, we did a little bit of writing, and at some point I gave a talk on it, but otherwise we did very little writing. This was not for mathematical reasons, but rather for executive function reasons on my end, the global pandemic, and both of us becoming directors of graduate study. This suggested an interesting challenge: could I use LLMs (specifically ChatGPT 5.6 Sol work mode mostly at “very high” intensity, via IU’s “Edu” subscription) to write this paper that was essentially mathematically complete, but almost entirely unwritten, and how quickly could this be done. To some extent this was a free experiment, because realistically I don’t think we’d have ever finished the paper at this point, and so it’s not replacing a bespoke paper that could have existed.

After spending a decent chunk of the time from Saturday until now on it, I now have a draft that I’m pretty happy with. I want to emphasize although mathematically this is Victor and my joint work, and although Victor has allowed me to make this post, he has not signed off on the accuracy and all errors at this point should be blamed entirely on me. Also my work is supported under NSF DMS grant 2000093 and Simons Foundation grant MPS-TSM-00007608.

Ok, here’s what I did:

  1. First, I asked if Sol could one-shot the main theorem. The answer was yes, though for a somewhat simple reason: Bodish-Wu write “It is possible to adapt the approach from [1], which itself is based on [7], to prove that the Karoubi envelope of [the G2 web category] is equivalent to the category of tilting modules as long as $[2], [3] \neq 0$.” That is to say, Elijah already proved the same result for C2, and a similar argument will work for G2. So the robot supplied the similar argument. I asked it to write that argument up, and then to check it over for good references and to read it like a referee would and make edits. This took around 30 minutes. Here’s the resulting file.
  2. Second, I uploaded my talk slides (and the tiny file already written, which was mostly useless), and asked Sol to give a proof of the main results following the slides. Again I asked it to edit it. This took around 30 minutes. Here’s the resulting file.
  3. Then I looked at the files. As mathematical exposition, I consider both to be garbage.
  4. Then I spent several days giving feedback attempting to improve the second file based on my talk. At no point did I edit the source directly. Most of this was in what I would call the style of a (low executive function, see above) PhD advisor. That is, I would kinda skim the file, get annoyed about something, and tell it to fix it. While it was fixing the paper, I would skim some more to try to find something else that annoyed me. This was a long process! It took three days, nearly 100 prompts, 10-15 hours of reasoning, plus another 10-15 hours of non-reasoning computer time. This used nearly an entire week of my generous budget, and Sol estimates that this would cost around $100 (within a factor of 2) at metered rates. Eventually I got to a version of the paper that I’m pretty happy with. Here’s the resulting file.

I thought I’d distill some thoughts and some questions from the process, I’m of course very curious for your thoughts on the matter.

Comments:

  1. This was much faster than I could have written the paper myself, though slower than I thought it would be. I think the final product is comparable in quality to a typical math paper of mine. On the other hand, I think that compared to my fastest writing collaborators it was not orders of magnitude faster, and the quality is not close to the output of the best mathematical expositors. AI at this point is much worse at writing paper than finding counterexamples to conjectures.
  2. In this case, I was not very worried about errors, because I already had thought through the whole argument and was highly confident that it would work (modulo getting the exactly correct list of exceptions). Nonetheless, I felt like Sol did not make errors more frequently (or of a worse character) than I would expect of myself or a collaborator. Most errors were stuff like “Oh, forgot to check whether this theorem actually works at all roots of unity.” This is typical of my experience with 5.6, which is dramatically better at doing math accurately than previous ChatGPT models.
  3. In this case the vast majority of the ideas were already present from Victor and my work. In particular, the goal was not just to write a proof, but to write our specific proof. Nonetheless, I do think the model contributed mathematically in one key way: in my original sketch I always worked over each q individually, and the model preferred to work integrally, and this resulted in some very nice simplifications in Section 4.1. If and when we turn this into a real preprint, I will include a brief discussion of the intellectual contribution from the model.
  4. I was surprised when I printed out and read a near-final draft, that this feels to me like a paper I wrote. That is the voice is not different enough from what I would write with a human collaborator to feel like it’s not in large part mine.
  5. The experience is disconcertingly similar to advising a PhD student on a paper. That said, a PhD student would need less handholding on their second paper, but an LLM won’t really learn.
  6. I was surprised about how important “prompt engineering” remains, and I think that if I were to write another paper this way I would be able to write it faster and better. The key points are that the model is lazy and easily distracted (both properties I find highly relatable!). It’s lazy in the sense that if you ask it to do a lot of work all at once it will take shortcuts and not do a good job. At one point I had to be like “no, go look at exactly how I made TikZ diagrams, now make all your diagrams actually good like that.” It’s easily distractible in that if you’re not clear about the scope of your question and the document is long, it will start spending crazy amounts of time doing who knows what. Like it wrote the whole first draft in 20 minutes, but then when the paper was 50 pages long, I asked it to switch the order of two paragraphs and it took an hour. Make clear requests and not too many requests at once. Form a plan first and then implement the plan. Be specific about whether it should be editing the document, and if so in which sections. For simple tasks, medium intensity is better than very high.
  7. Starting again from sketch, I’d try to follow Terry Tao’s advice for writing and start with an outline and gradually flesh it out, rather than trying to start with a one-shot paper and then editing.

Questions:

  1. To what extent is this final paper adding any value to the original talk? Especially considering that readers themselves could use an AI model to flesh out points in the talk that they didn’t understand? Maybe we should just be focusing on talk-length digests and formal checking, rather than traditional papers?
  2. What should we do with this paper? I don’t want to make someone hand-referee it, because it doesn’t seem fair when it wasn’t hand-written. Probably we will put it on the arxiv once we’ve human-checked it fully and Victor has signed off on it, so that other people can use the results if they need to.
  3. Given the speed-up, when does it still make sense for me to write papers by hand? (Relevant here that I’m a very slow writer and don’t really enjoy it, the way I enjoy say preparing and giving a talk.)
  4. What does this mean for PhD advising? Many PhD students need a similar amount of guidance to what I gave the model in this project. But you can now remove the student from the loop (either intentionally, with the advisor just writing using LLM assistance rather than having students, or unintentionally, with the student just feeding all the suggestions to an LLM and reporting back to the advisor).
  5. Have any of you done better with AI-assisted paper writing? My points 6 and 7 above sounds like something where someone is going to say “blah, blah, scaffolding, blah, blah, multi-agent…”

What a strange world to live in…

July 26, 2026

Tim Gowers — Thoughts about the Leiden Declaration

Last September I went to a workshop at the Lorentz Centre in Leiden to discuss mathematics and AI with historians, philosophers, computer scientists, AI researchers, and mathematicians of several different flavours (though there was a surprising preponderance of algebraic geometers). The whole event was extremely stimulating, with some talks but also a lot of time set aside for discussion. One of the concrete outcomes of the workshop was the Leiden Declaration, which has now been signed by over 3000 people. Given that I was part of the workshop, it might seem a bit strange that I am not one of the signatories of the resulting declaration. The reason is not so much that I disagree with it in any concrete way, but more that in several places it makes confident assertions and recommendations that I feel somewhat uncertain about. So instead I prefer to try to articulate my views about the issues raised by the declaration and put them in this blog post. Before I do that, I would like to make clear that I am very glad that the Leiden Declaration exists and I think that it has done a lot of good in focusing people’s minds on the issues that AI is forcing the mathematical community to grapple with, which are more acute now than they were last September.

Let me begin by quoting a passage from the declaration that sets out “what we take to be characteristic values of mathematical research that we have a joint interest in preserving”.

  1. There are many reasons to pursue mathematical research, ranging from intellectual curiosity to a desire to solve practical and societal problems. Underlying much of mathematics is the activity of proof. Mathematical proofs are regarded as conferring the highest degree of certainty to their conclusions, as well as imparting understanding of why their conclusions are true. These characteristics of proof support the scientific integrity of mathematics.
  2. Results are attributable to specific authors who take credit for their discovery and assume responsibility for their correctness. These principles ground the merit-based standards to which we aspire in mathematical research.
  3. Mathematical arguments are regarded as transparent and subject to independent verification. They may be extremely long or difficult, but in principle no proprietary knowledge or equipment should be required to understand them.
  4. Mathematicians share a concern for proper evaluation of mathematical work relative to shared standards of depth, difficulty, and significance.
  5. Mathematics produces not only a body of results, but also understanding, clarity, and judgment among the communities of mathematicians who have shaped them, often in the context of their own autonomously guided research. This expert knowledge is essential, both to effectively use mathematics, and to continue to articulate new and significant research questions. A key source of strength of the discipline has long been the autonomous shaping of the direction of research and the methods used to pursue it.

The first thing I would say about these values is that they are undoubtedly values that are widely held by mathematicians, including, with some qualifications, me. The main qualification I have concerns point 4: I find the notion of “proper evaluation” somewhat problematic, given that different mathematicians can have very different judgments without either of them being clearly wrong, especially when it comes to the significance of a piece of mathematics. Also, these judgments are used for purposes such as the acceptance of papers in journals, hiring and promotion decisions, the awarding of prizes, and so on, that are part of a system that copiously rewards a few people — I myself have hugely benefited from it — but doesn’t necessarily adequately reward a lot of people who are doing less visible work that is essential to keeping the whole enterprise going.

But the more important point is whether these values are ones that we should fight for in the future, as the Leiden Declaration suggests. I find that clearer for some of them than others. For example, it seems to me that the importance of rigorous proof will be even greater in an AI age than it was before — if the output of AI is not underpinned by rigorous proof, then the kinds of difficulties one already hears about with certain areas of human mathematics (see for example many talks by Kevin Buzzard arguing for the value of formalization) would be hugely magnified. But what about the attribution of results to specific authors, who take both credit and responsibility for them? Suppose that at some point in the future AI becomes more autonomous, reading the literature and solving many problems that it finds. Suppose also that its solutions are autoformalized, so there is no serious doubt about their correctness. In such a situation, there would be nothing for a human to take credit for or responsibility for. Does that mean that we should declare such results undesirable and threatening to mathematical values?

Of course, something could well be missing in such a situation: perhaps the proofs would be badly written and hard to follow, which would mean that they lacked something we all very much value. So let me extend the thought experiment slightly. What if by that stage one could take one of these outputs and ask an LLM to explain the ideas, and what if LLMs did a very good job at that? That is not particularly hypothetical, since they are often pretty good at this job already, but I am imagining a world in which they are much better than they are now, as they will presumably become.

So now we would have a world in which a lot of problems had been solved, we were sure that the solutions were correct, and we had an LLM ready to explain those solutions in as much or as little detail as we wanted. Is that a future we should resist, and if so, why?

One obvious reason is that it would take a huge part of the fun out of the subject. It is extremely satisfying to struggle with a mathematical problem for months or even years and eventually solve it. But I worry about that argument, because it seems to be saying that we should resist doing mathematics the easy way because a tiny fraction of the world’s population gets huge pleasure from taking orders of magnitude longer to do it. That is not to say that I wouldn’t be sad that a way of life that has sustained me for the last forty years was not available any more — of course I would. I just find it hard to use it as a reason to argue that we should try to preserve the “ownership structure” of mathematical results. If we arrive at a world where mathematical theorems are no longer associated with mathematicians, maybe that won’t be any more problematic than the fact that stars aren’t named after astronomers and most aren’t named at all. I’m not necessarily in a hurry for that world to exist, but maybe once the transition had happened, people would be OK with it.

The third value I share in an uncomplicated way, and I have already discussed the fourth. The fifth value is one that I hold very strongly, though I’m not so keen on the idea of experts consciously “shaping the direction of research”, something that I see as happening more organically. Obviously there are some notable examples of mathematicians who have created wonderful programmes of research, but even there I would like to credit other mathematicians with understanding what is wonderful about those programmes and contributing to them enthusiastically as a result, rather than being told what direction to pursue and meekly doing so (which is probably not what the declaration is actually trying to suggest, but it has a slight flavour of that for me).

But that’s a minor quibble when set against my main worry about the effect of AI on mathematics, which is the possible destruction of mathematical culture. There is at the moment an extraordinary body of knowledge and expertise that exists not just in the mathematical literature but in the heads of mathematicians all round the world. Imagine if AI didn’t exist and a pandemic broke out that for some reason wiped out all mathematicians and nobody else. All the literature would still be there, but nobody would have the faintest idea what to do with it. To revive a mathematical tradition under those circumstances would be extremely difficult and take decades. Now imagine a slight variant of that, where AI does exist and because of it people are no longer motivated to put in the years of effort it takes to reach the level of expertise that a typical research mathematician has now. After a decade or two, we might arrive at a situation where the mathematical literature has, in some form, been vastly expanded, but there is no corresponding community of human experts who have a shared understanding of parts of it. Almost all of mathematics would be like the areas that we have more or less forgotten about today, areas that exist in papers written many decades ago that nobody reads any more. (I won’t name any such area because I don’t want accidentally to suggest an area that many people still love and work on.)

This, it seems to me, is a possibility that we should try very hard to resist, but I agree with many other commentators who say that in order to resist it, we will need to give less priority to some of our current values — and I would include ownership of mathematical results in that list — and more to others. For example, if Person A gets an LLM to one-shot a solution of an important open problem (which is formalized, possibly automatically, so there is no doubt about its correctness) but Person B makes the effort to digest the solution and explain it in a way that other mathematicians can understand and learn from, then I think we will want Person B to get the lion’s share of the credit. The credit would be of a slightly different from what it is now, which could be described as admiration for somebody’s talent, insight, speed (I mean here the purely factual statement that speed is often admired — I would prefer that to be less the case) and hard work. It would be more like the gratitude that one feels already for somebody who writes a beautiful textbook that makes a whole area of mathematics coherent and accessible.

Maybe that is what the “research mathematicians” of the future should do: make a selection from a vast sea of AI-generated mathematics and write a book about it in such a way that other mathematicians can read the book and feel the kind of enrichment that we feel when we get to grips with an area of mathematics.

At this point I have to admit that there’s a pessimistic side of me that asks the following general question whenever anyone says anything about what the role for humans might be in the future: why do you think that AI wouldn’t be able to do it? For example, with the suggestion I’ve just made, what reason is there to suppose that ChatGPT 8.2 wouldn’t be able to have a short interaction with you about your mathematical tastes and background and then write the ideal textbook just for you? Humans are likely to be better at this kind of curating for a little while yet, but is it a fundamentally human ability that AI could never hope to emulate?

In a world where AI wrote bespoke textbooks (or more likely, just taught people in some more direct way), something would be lost that feels important: mathematics as a collective endeavour. If we all just learnt cool bits of maths for our own private satisfaction, we would miss the considerable pleasure that comes from discussing mathematics with others, though even that could in principle be restored by a benign LLM that deliberately taught many people the same cool bits of the subject, though an LLM that could do that sort of social engineering would raise all sorts of safety issues.

Let me now turn to the section of the declaration about potential threats. I’ll put my comments on each one in square brackets.

  1. Current automated techniques can produce plausible but unreliable (or even incorrect) arguments which are difficult to distinguish from correct mathematical proofs. This applies not only to informal arguments, but also to formalizations, where the difficulty lies in the translation between computer-encoded and human presentations of concepts. These fast-moving developments put our present system of review under increasing pressure, jeopardizing our ability to implement traditional standards for the correctness, transparency, and independent verifiability of proof. [This feels like less of a problem now than it did last September, partly because the best LLMs hallucinate a lot less than before, and partly because autoformalization is improving all the time — I have just used harmonic.fun’s Aristotle system to formalize a complicated paper in Lean and I didn’t need to know any Lean to do it.]
  2. Technologies that draw extensively on the published mathematical commons undermine the traditional system of attribution. Models trained on published works frequently return outputs that do not properly cite the human works they synthesize. Many current models are also built on data obtained by systematically exploiting licenses and access arrangements that were not made with artificial intelligence in mind, or indeed by simply violating copyright protections. [This is a problem at the moment, when ownership of results is important, and I am very much in favour of people making an effort to give appropriate credit for mathematical ideas that AI may have used. However, in the longer term, as I have already discussed, I think this ownership structure will break down and the issue will become less important. It also seems possible that LLMs will become better at revealing their sources.]
  3. Technologies which affect the way in which mathematics is practiced may disturb the current system of incentives. The use of artificial intelligence — and thus also the sort of problems which it can address — may become incentivized for its own sake, disrupting our mechanisms for hiring, funding, and recognition. This disadvantages researchers who do not have access to the technologies or decision-making related to them, or who are unwilling to use technologies controlled by organizations whose values they do not share. [These seem to me to be genuine problems. I think there is simply no point in hoping that our current system of incentives will not be disturbed — it obviously will. I am not necessarily too worried if our mechanisms for hiring, funding and recognition are disrupted, as I don’t find those mechanisms unproblematic as they are, but disadvantaging researchers who do not have access to good LLMs is something I certainly think we should worry about.]
  4. Proper evaluation is endangered if results are communicated through informal channels such as press releases or blog posts, often without any research paper or other disclosure of information necessary for scientific evaluation. This practice seeks publicity for new results on market timelines before the accepted processes of community evaluation in mathematics can take place. In many cases this leads to simplifications in reporting, such as overemphasizing the significance of automated tools and undervaluing the prior human contributions which have made those tools possible. Such oversimplification risks influencing public opinion in a way that not only damages perceptions of mathematics, but also misleadingly uses specific mathematical tasks as metrics for the general reasoning capacities of commercial products. [I think this can be a problem, but I think it is not as serious a problem as some of the others, since when results get overhyped, there seems to be no shortage of people publicly (and rightly) pointing that out.]
  5. These developments put the autonomy of mathematics under threat. The increasing involvement of technology companies in mathematical research raises the risk that research questions may come to be prioritized because of their amenability to automated mathematics, rather than expert judgment of their deeper significance. Indeed, broader understanding of the field may be permanently lost in the process of automation. With university budgets under pressure, this reshaping also changes professional incentives in a manner which encourages the collaboration of researchers with technology companies on asymmetric terms. If left unchecked, these trends go beyond threatening researchers’ autonomy, affecting the scope and depth of mathematical research itself. [I think this could be a problem, but it also seems to me that mathematicians have a lot of power here. For instance, if a technology company were to produce a lot of research that mathematicians did not find all that interesting or important, I don’t think they would be able to use their financial and other resources to persuade us to change our minds. Rather, what seems to happen is that mathematicians say, “Yes that does X but it doesn’t do Y,” and the tech companies then feel challenged to do Y.]

There follow eleven recommendations for individual mathematicians. I agree with almost all of them. The one that I’m not so sure about, for reasons I’ve basically already gone into, is this.

Affirm the humanity of authorship. Credit and responsibility continue to belong to humans within the mathematical community and should not be given to automated systems. Artificial intelligence may obscure, but does not replace, the collective human labor behind a result.

I’m not sure what that really means. For example, should we affirm the humanity of authorship in the case of the solution to the unit-distance problem? Some humans did a wonderful job of explaining the proof that OpenAI’s model came up with, and the model made use of some highly non-trivial mathematics produced by humans, but the solution itself has not been credited to any human, and nor should it be in my view.

Under recommendations for mathematical organizations and not-for-profit research funders I again agree with several of them but have my doubts about some. An interesting case is the following.

Protect the rights of authors. Automated mathematics presents new challenges to the rights of authors, and societies should be proactive in the development of sample licensing agreements to protect these rights. In particular, material should not be used as training data without consent, and publishing agreements should allow authors to opt-out [sic] of the use of their work in this way.

This recommendation seems to belong to a world in which journal articles are the main means of dissemination of mathematics. But that has long since ceased to be the case: almost all dissemination now takes place via arXiv preprints, with journals limited to providing a little extra mark of prestige. Once an article is on arXiv, it is on the internet and one can hardly ask for it not to be used as training data. So this recommendation, if it applies at all, will apply to a tiny fraction of articles that are published without first appearing on arXiv. More generally, what right of an author is being compromised when an article is used as training data? We don’t object if human mathematicians use our articles to help train themselves to become better mathematicians — indeed, we will typically be delighted that somebody else thought our articles worthy of their attention. So the objection to a machine doing the same would have to be that for some reason one did not want machines to get better at mathematics in a similar way. I can imagine grounds for such a wish: perhaps somebody is worried about the threat that LLMs pose to traditional mathematical practice, or perhaps they worry that mathematical ability of LLMs will transfer to much more dangerous reasoning ability. But there’s a more complicated discussion to be had here than one might think from reading the recommendation.

The next recommendation is this.

Insist on appropriate publication outlets. Demand that mathematical results continue to be published in peer-reviewed venues such as journals, proceedings, and books. Informal mechanisms such as press releases or blog posts can provide a valuable supporting role, but they cannot replace peer-review or community scrutiny.

For reasons that I’ve gone into many times, I am not too fond of the current publication system, so I can’t get behind this recommendation. Indeed, if the current system becomes unsustainable because of a flood of AI-generated and AI-aided content, I would regard that as a beneficial consequence of AI. However, that doesn’t mean that I would advocate a total free-for-all. I’ve already said that one of my worries is that if mathematical content is not sufficiently organized, then the traditions that we all value could die. I just think that what we will want to do to preserve those traditions is likely to be a lot more innovative than clinging on to the peer-reviewed journal system.

I have highlighted in this post the parts of the declaration that I have doubts about, either because I disagree with them or, more typically, because I sort of half agree with them but want to add many qualifications. That may make the post come across as rather negative, but that is not my intention. The parts I disagree with are in the minority, and I think it is important that a declaration such as this should be made. I should also make clear that my views are evolving all the time, largely because the speed of progress of LLMs has taken me by surprise, but also as a result of conversations I have had or opinions that other mathematicians have expressed online.

I’ll end with two further clarifications. The first is that it may seem as though I am taking it for granted that LLMs will soon be better than humans at all aspects of mathematical problem solving, and maybe also problem posing, theory building, formulation of definitions, etc. I do think all that will happen at some point, but whereas some people say that it will obviously happen within the next two to three years, I would say that it might happen as soon as that, but I don’t rule out that we’ll get lucky and find that we can do interesting AI-assisted maths for quite a bit longer than that before AI doesn’t need us any more.

The second is that I think I have acquired a reputation as somebody who celebrates what is going on. But if, for example, I post on Twitter saying that such-and-such an AI solution is a remarkable development, the word “remarkable” is meant to indicate no more nor less than that I found it very surprising. My feelings about the possibility of AI solving all sorts of problems that interest me are much more mixed. I’ve had the experience twice now of seeing GPT 5.6 Pro one-shot a solution to a problem that I very much liked and had thought about hard (in both cases with much younger collaborators, who, with my approval, were the ones who prompted the LLM). It felt very strange and not particularly pleasant to have the rug pulled out from under my feet like that. On the other hand, I was quite pleased to see the problems solved. It’s actually a similar feeling to the one I have had many times when a problem I am fond of and have thought about gets solved by another human mathematician.

Another factor for me is that I have invested a lot of thought into automatic theorem proving of a more traditional kind. One of my main motivations for that was the hope that the work I put into it would extend the state of the art, measured by which problems a computer can solve. That ship has sailed now, and that saddens me. I still think that there is value in the work that I and my group are doing, but it has become a tougher sell.

So I personally have already found AI quite disruptive, and this is just the beginning. I would have preferred the developments to happen at a slower pace. But I don’t see any practical way to slow them down, so the best we can do is probably to face up to the changes that are being thrust upon us and do what we can to maximize the benefits and minimize the damage. The Leiden Declaration may not be perfect, but it makes an important and positive contribution to that effort.

July 25, 2026

Clifford Johnson — On top of the Mountain again

Just in case you’re up for a short talk at the top of Mount Wilson followed by an evening of observing through the historic telescopes on Saturday 25th July… this might be for you! Go to Mount Wilson Observatory’s website for more. –cvj

The post On top of the Mountain again appeared first on Asymptotia.

July 24, 2026

Peter Rohde Introducing Sigfried’s Blog

My new secondary blog featuring conversations with AI, inventing new things, exploring hypotheticals, letting creativity flow freely.

Some highlights:

  • Satellite constellations with topologically distributed apertures.
  • A clockless architecture for classical topological computing.
  • Post-quantum cryptography using the \mathbb{Z}_2^n \rtimes S_n algebra.
  • Efficient homomorphic computing using reversible classical circuits.
  • A silent speech interface using microwave Doppler imaging.
  • Cognitive search acceleration.
  • Consensual thought guidance.
  • Subliminal audio modulation & human guidance systems.
  • Microwave imaging using WiFi and 5G for medical applications.
  • Thought tomography.
  • The quantum bluff hypothesis.

https://sigfriedschattenjaeger.wordpress.com

July 20, 2026

Secret Blogging Seminar — The new counterexample to the Jacobian conjecture

As many of you have probably heard already, yesterday morning, Levent Alpöge tweeted that Fable had found a counterexample to the Jacobian Conjecture. Specifically, let

a=(1+xy)3z+y2(1+xy)(4+3xy),b=y+3x(1+xy)2z+3xy2(4+3xy),c=2x−3x2y−x3z,\begin{align*} a&=&(1+xy)^3z+y^2(1+xy)(4+3xy),\\ b&=&y+3x(1+xy)^2z+3xy^2(4+3xy),\\ c&=&2x-3x^2y-x^3z, \end{align*}

Then the Jacobian of (a,b,c) is easily checked to be -2. However, the map (a,b,c) is generically three to one, not bijective.

I’m sure many of you are playing with these polynomials to see what you can figure out about them. This is a place for us to share our observations. I’ll post a few minor observations of my own soon.

First, a basic but intriguing observation from Mathoverflow user “dorky”: The polynomials a, b and c are homogeneous with respect to the grading where \deg(x) = -1, \deg(y) = 1 and \deg(z)=2; their degrees are \deg(a) = 2, \deg(b) = 1 and \deg(c) = -1. I’m not sure what to make of this, but it surely matters.


Some computations by me: If you eliminate any two of the variables (x,y,z), you get a cubic relation in the remaining variable. Here they are

−2c+(4−3bc)x+(16a−b2−18abc+b3c+27a2c2)x3(−18ab+b3+27a2c)+18ay−3by2+2y3(really long)+8z3\begin{matrix} -2 c+(4 – 3 b c) x + (16 a – b^2 – 18 a b c + b^3 c + 27 a^2 c^2) x^3 \\ (-18 a b + b^3 + 27 a^2 c)+18 ay-3 b y^2+ 2y^3 \\ (\text{really long}) + 8 z^3 \\ \end{matrix}

I’m leaving out the “really long”, because it is really long and I suspect we don’t care about the details. Put

Δ=16a−b2−18abc+b3c+27a2c2\Delta= 16 a – b^2 – 18 a b c + b^3 c + 27 a^2 c^2 ,

the leading coefficient of the x cubic. Then the discriminants of the three cubics are \Delta p^2, \Delta q^2, \Delta r^2 where

pamp;=amp;8−9bc+27ac2qamp;=amp;bramp;=amp;(really long)\begin{align*} p &amp;=&amp; 8 – 9 b c + 27 a c^2 \\ q &amp;=&amp; b \\ r &amp;=&amp; (\text{really long}) \\ \end{align*}

The polynomials (p,q,r) have no common zeroes. Roughly speaking, our map should have special behavior over the loci \Delta=0, p=0, q=0 and r=0. The fact that $p$, $q$ and $r$ each appear cubed means that the variables x, y and z should have three fold branching over the loci p=0, q=0 and r=0 (respectively).

I’m having trouble visualizing what happens over \Delta=0 — since the leading coefficient of the x cubic drops out, the map is 2 to 1 rather than 3 to 1 over this point. But, at the same time, the y and z cubics have a multiple root at the points of \Delta=0. Does anyone see how to visualize this?

Any other insights?